Prometheus Operator, a tale about container mon...
Sponsored
·
 Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→
Ship Features Fearlessly
Turn features on and off without deploys. Used by thousands of Ruby developers.
→

Share
Embed
Prometheus Operator, a tale about container monitoring at iFood (volume I)
In this presentation, I'll talk about the use of Prometheus as the main monitoring technology for kubernetes (but not only k8s) at iFood.
The main purpose is to show what went right and what were the pitfalls in adopting this new way of monitoring apps and infrastructure.

drequena
April 21, 2020
Transcript
93 slides
-
Prometheus Operator A tale about container monitoring at iFood Volume
I by: Daniel Requena -
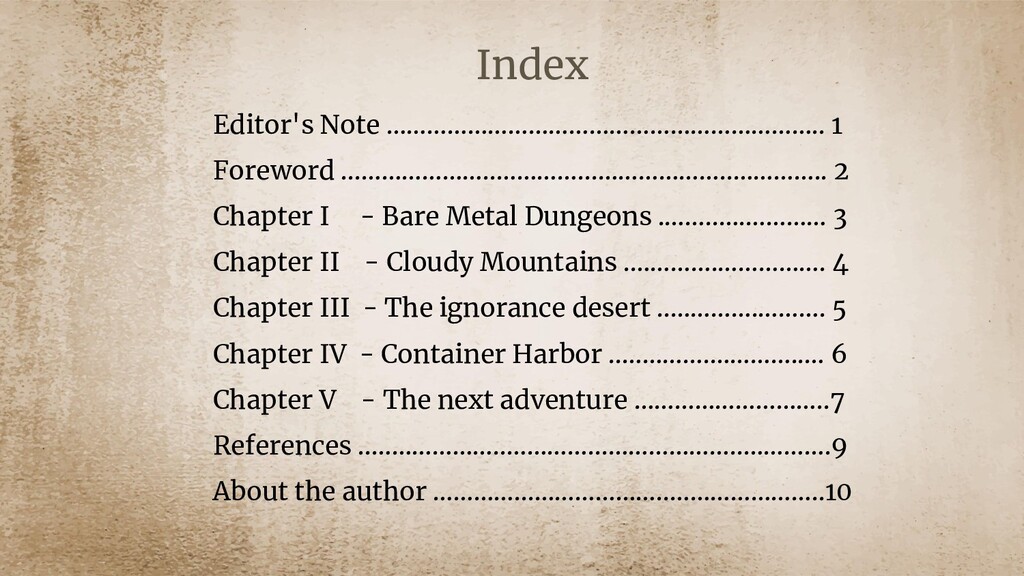
Index Editor's Note ……………………………………………………….. 1 Foreword ...………………..…………...………………..………….. 2 Chapter I
- Bare Metal Dungeons .……..….………… 3 Chapter II - Cloudy Mountains .………….……………. 4 Chapter III - The ignorance desert ..………….………. 5 Chapter IV - Container Harbor ..………….…………..… 6 Chapter V - The next adventure ………………………..7 References ..………………..…………...………………..………….9 About the author …………...………………..…………………..10 -
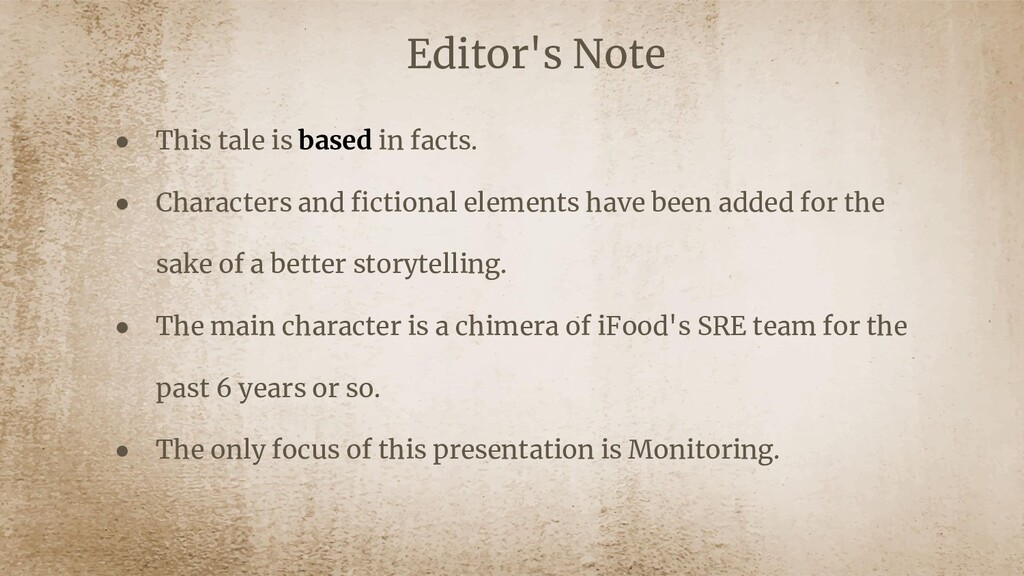
Editor's Note • This tale is based in facts. •
Characters and fictional elements have been added for the sake of a better storytelling. • The main character is a chimera of iFood's SRE team for the past 6 years or so. • The only focus of this presentation is Monitoring. -
Chapter I - Bare Metal Dungeons Class: Human Race :
Warrior Level: 10 XP : 2 years ------------- Int : ##### Str : ######## Dex : ### STA : # Tools: . Linux (int) . Networking (int) . Bash (int) . Pyrhon (bgn) . Zabbix (bgn) -
Chapter I - Bare Metal Dungeons Hello fellow Linus! I'm
ScrumMaster, the Bard! Are you looking for a great Monitoring adventure? I heard that beyond the dark forest, there is a site called Bare Metal Dungeons. A place full of big challenges: Racks Servers, VMs, switches, etc... A big reward in eXPerience is promised to the hero who answer to the call. Are you interested? Scrum Master, the Bard Linus, the Sysadmin -
Chapter I - Bare Metal Dungeons Hello my good friend!
A fare adventure you are proposing to me. I shall accept this challenge rightway! To the Bare Metal Dungeons I SAY! Accept my LinkedIn profile as a form of gratitude. Thanks for the opportunity, I hope to see you soon. Good Bye! Scrum Master, the Bard Linus, the Sysadmin -
Chapter I - Bare Metal Dungeons The Bare Metal Dungeons
landscape • Physical servers • Manual provisioned VMs • Network devices • Databases • Web Servers • Monolithic app • Few users -
Chapter I - Bare Metal Dungeons The Bare Metal Dungeons
landscape • Weapon of choice: Zabbix ◦ Basic templates ◦ Custom Templates ◦ Bash scripts ◦ Python integrations ◦ E-mail alerts ◦ ... -
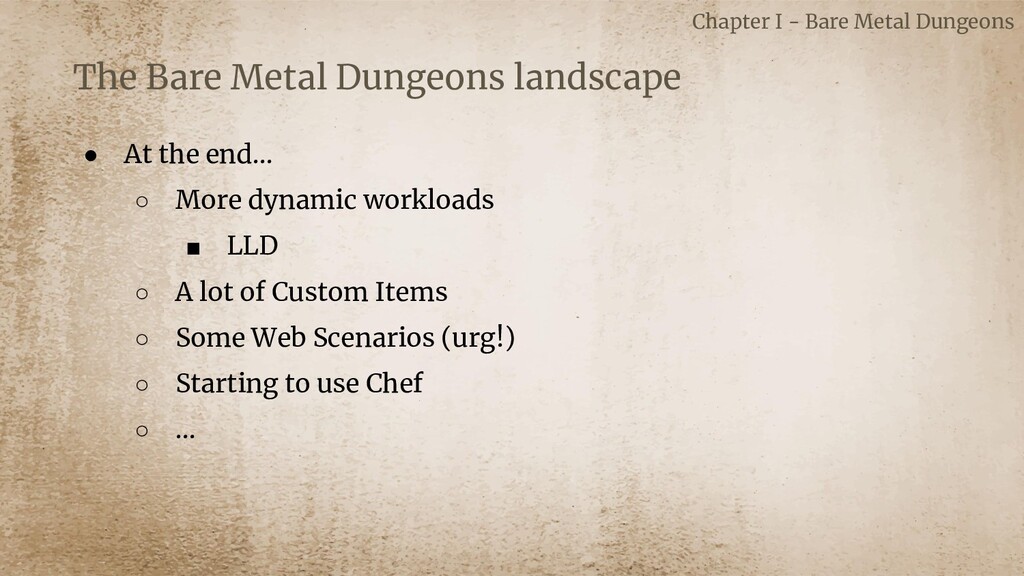
Chapter I - Bare Metal Dungeons The Bare Metal Dungeons
landscape • At the end... ◦ More dynamic workloads ▪ LLD ◦ A lot of Custom Items ◦ Some Web Scenarios (urg!) ◦ Starting to use Chef ◦ ... -
Chapter I - Bare Metal Dungeons Class: Human Race :
Warrior Level: 15 XP : 4 years ------------- Int : ###### Str : ########## Dex : #### STA : ##### Tools: .Linux (adv) .Networking (int) .Bash (adv) .Pyrhon (int) .Zabbix (int) .Chef (bgn) .AWS (bgn) -
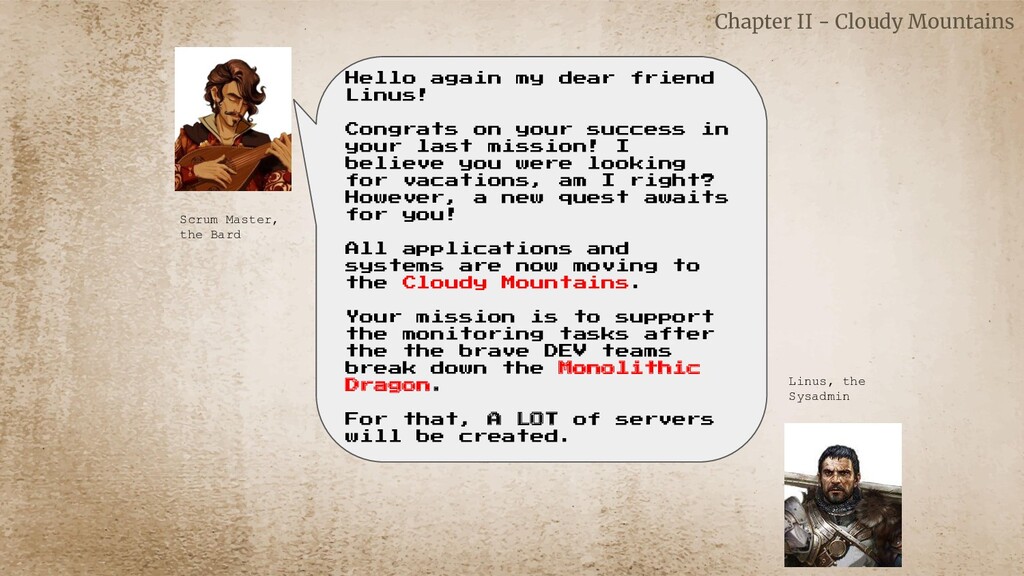
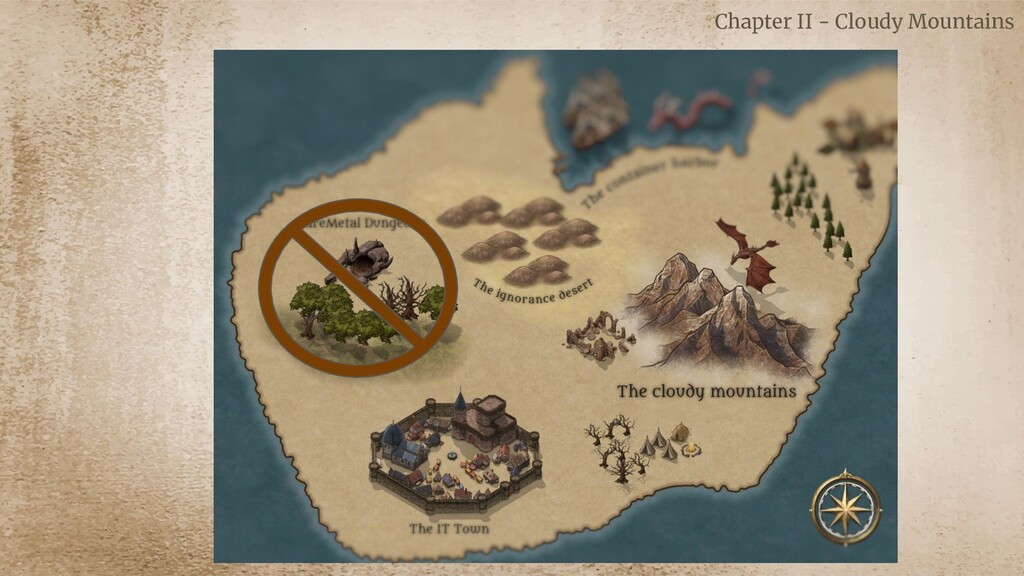
Chapter II - Cloudy Mountains Hello again my dear friend
Linus! Congrats on your success in your last mission! I believe you were looking for vacations, am I right? However, a new quest awaits for you! All applications and systems are now moving to the Cloudy Mountains. Your mission is to support the monitoring tasks after the the brave DEV teams break down the Monolithic Dragon. For that, A LOT of servers will be created. Scrum Master, the Bard Linus, the Sysadmin -
Chapter II - Cloudy Mountains Greetings my under occupied friend!
A new quest you say! I must accept rightway again. So, the Monolithic Dragon shall be broken down, right? And you said something about the creation of a lot of servers too. Tell me, my slacker friend, are you talking about how many servers? 70? Scrum Master, the Bard Linus, the Sysadmin -
Chapter II - Cloudy Mountains A little more. Scrum Master,
the Bard Linus, the Sysadmin -
Chapter II - Cloudy Mountains 140 servers? Scrum Master, the
Bard Linus, the Sysadmin -
Chapter II - Cloudy Mountains A little more. Scrum Master,
the Bard Linus, the Sysadmin -
Chapter II - Cloudy Mountains Oh wow! More than 140?
Are we talking about 400 servers? Scrum Master, the Bard Linus, the Sysadmin -
Chapter II - Cloudy Mountains There will be at least
1000 servers. Many dynamically created by ASGs and others created on AWS painel with no previous notice. Ow! And you shall monitor all kinds of AWS componentes too. Scrum Master, the Bard Linus, the Sysadmin -
Chapter II - Cloudy Mountains You know what? I'm starting
to reconsider our friendship dude. Scrum Master, the Bard Linus, the Sysadmin -
Chapter II - Cloudy Mountains Cloudy Mountains landscape • Migrate
to Cloud: "Lift and shift". ◦ Monolith at large scales ◦ ASGs ◦ HTTP routing ◦ Big database • Zabbix was still the only weapon of choice. ◦ Dynamically registering hosts ◦ Monitoring only infrastructure -
Chapter II - Cloudy Mountains Cloudy Mountains landscape • The
slow killing of the Monolithic Dragon. ◦ More instances (asg) ◦ SQS/SNS ◦ More databases - ro/rw (asg) ◦ Loadbalancers ◦ Buckets ◦ DynamoDB tables ◦ Lambdas ◦ Elastic Cache systems -
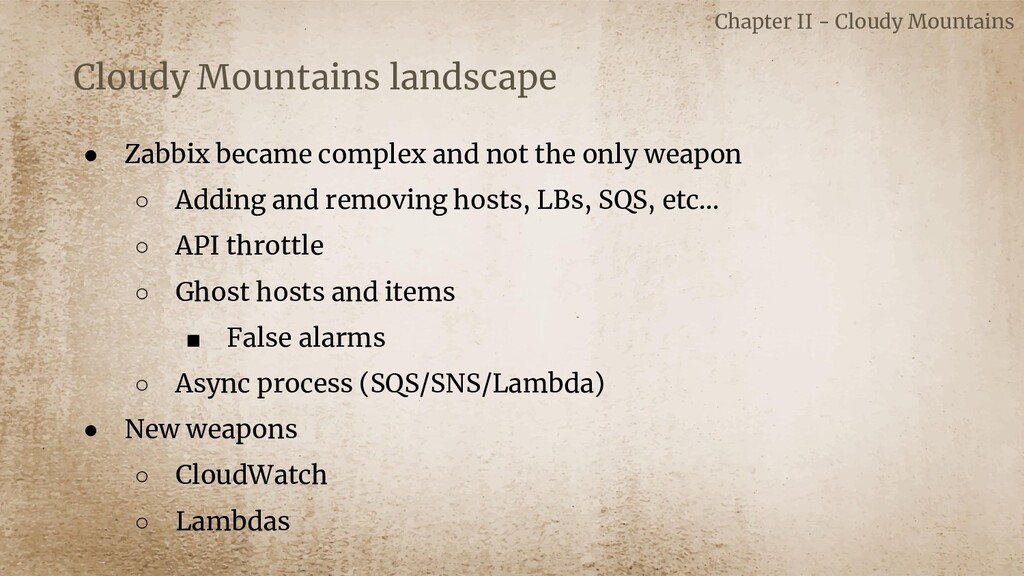
Chapter II - Cloudy Mountains Cloudy Mountains landscape • Zabbix
became complex and not the only weapon ◦ Adding and removing hosts, LBs, SQS, etc... ◦ API throttle ◦ Ghost hosts and items ▪ False alarms ◦ Async process (SQS/SNS/Lambda) • New weapons ◦ CloudWatch ◦ Lambdas -
Chapter II - Cloudy Mountains Class: Human Race : Warrior
Level: 19 XP : 6 years ------------- Int : ######## Str : ############ Dex : ###### STA : ####### Tools: .Linux (adv) .Networking (int) .Bash (adv) .Pyrhon (int) .Zabbix (int) .Chef (adv) .AWS (adv) .Terraform (adv) -
Chapter III - The ignorance desert Linus! My old friend!
Long time we don't see… You know! I was wondering... Scrum Master, the Bard Linus, the Sysadmin -
Oh now WHAT?! Tell me WHAT THE F*CK are you
put me into now! Scrum Master, the Bard Linus, the Sysadmin Chapter III - The ignorance desert -
WOW! so aggressive.Calm down. Have you heard about the Kubernetes
feaver? Apparently it is the NEW silver bullet to all problems. All apps are now moving to Kubernetes and no previous monitoring solutions are good to it. Your quest is to monitor Kubernetes itself and also all apps inside it. You must go fast to the container harbor before the ships starts to departure. Scrum Master, the Bard Linus, the Sysadmin Chapter III - The ignorance desert -
IIRC, containers can be created and destroyed in seconds! No
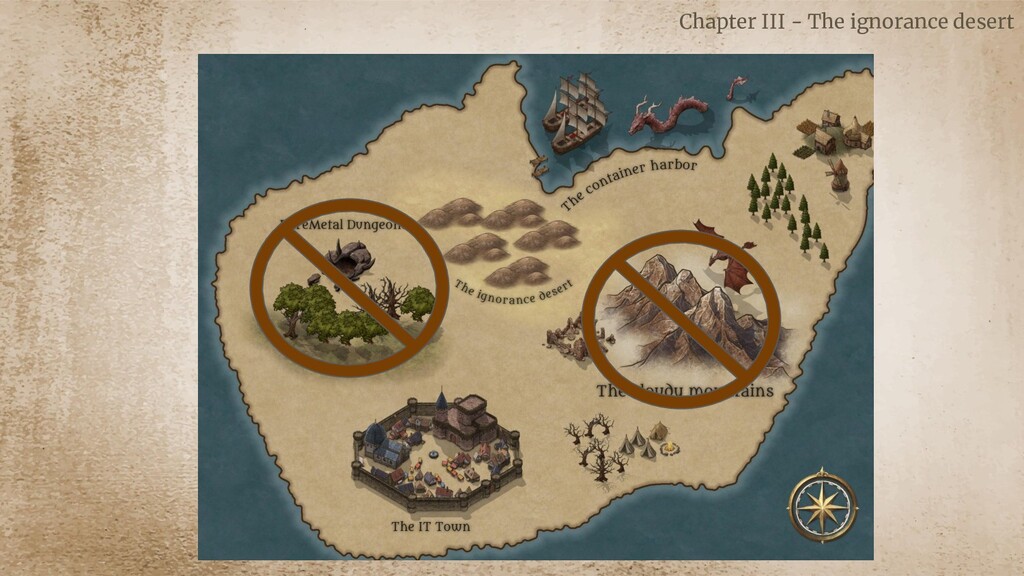
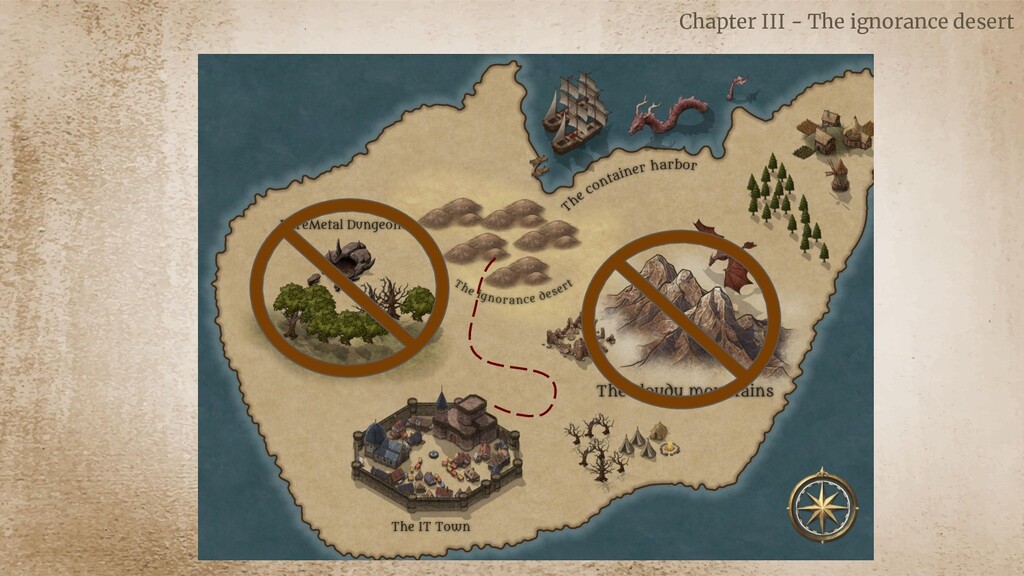
tool that I'm aware of can handle that kind of elastic workload! I must wander through the desert of ignorance in order to find a suitable tool for this situation. Wish me luck! And the next time we see each other, just don't talk to me anymore. Scrum Master, the Bard Linus, the Sysadmin Chapter III - The ignorance desert -
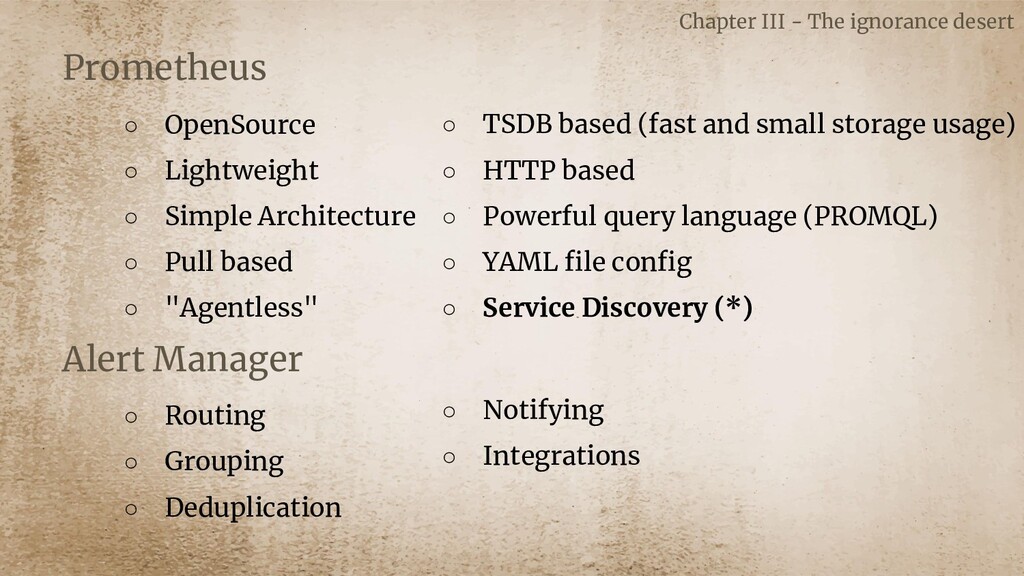
Prometheus ◦ OpenSource ◦ Lightweight ◦ Simple Architecture ◦ Pull
based ◦ "Agentless" Alert Manager ◦ Routing ◦ Grouping ◦ Deduplication Chapter III - The ignorance desert ◦ TSDB based (fast and small storage usage) ◦ HTTP based ◦ Powerful query language (PROMQL) ◦ YAML file config ◦ Service Discovery (*) ◦ Notifying ◦ Integrations -
Prometheus tsdb APP kube_deployment_spec_replicas{deployment="coredns",endpoint="http",instance="100.108.141.184:8080",jo b="kube-state-metrics",namespace="kube-system",pod="prometheus-operator-kube-state-metrics-78fb6c979- nxrlc",service="prometheus-operator-kube-state-metrics"} 2 Prometheus tsdb APP
exporter GET /metrics GET /metrics Get metrics from app somehow. Reply in Prometheus metrics standard Chapter III - The ignorance desert -
Prometheus tsdb APP Alert Manager Rules: avg(metric) > 10 label:
critical Condition Error! Solved! #Alerts GET metrics metric = 11 Store Check Result route: receiver: slack-general group_by: - job routes: - receiver: slack-integration match: severity: critical continue: true Chapter III - The ignorance desert -
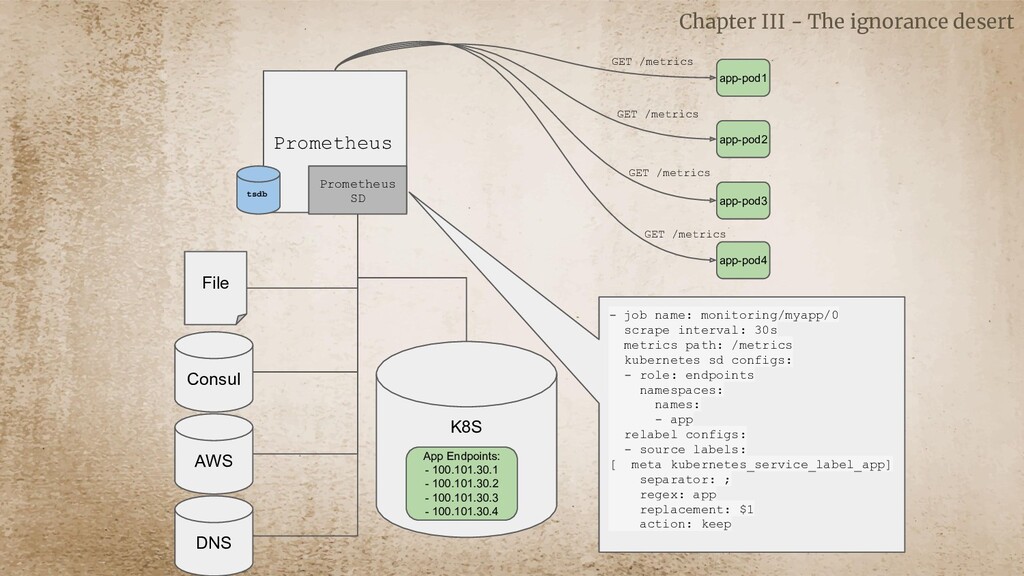
Consul K8S File Prometheus Prometheus SD - job_name: monitoring/myapp/0 scrape_interval:
30s metrics_path: /metrics kubernetes_sd_configs: - role: endpoints namespaces: names: - app relabel_configs: - source_labels: [__meta_kubernetes_service_label_app] separator: ; regex: app replacement: $1 action: keep tsdb AWS DNS App Endpoints: - 100.101.30.1 - 100.101.30.2 - 100.101.30.3 - 100.101.30.4 app-pod1 app-pod2 app-pod3 app-pod4 GET /metrics GET /metrics GET /metrics GET /metrics Chapter III - The ignorance desert -
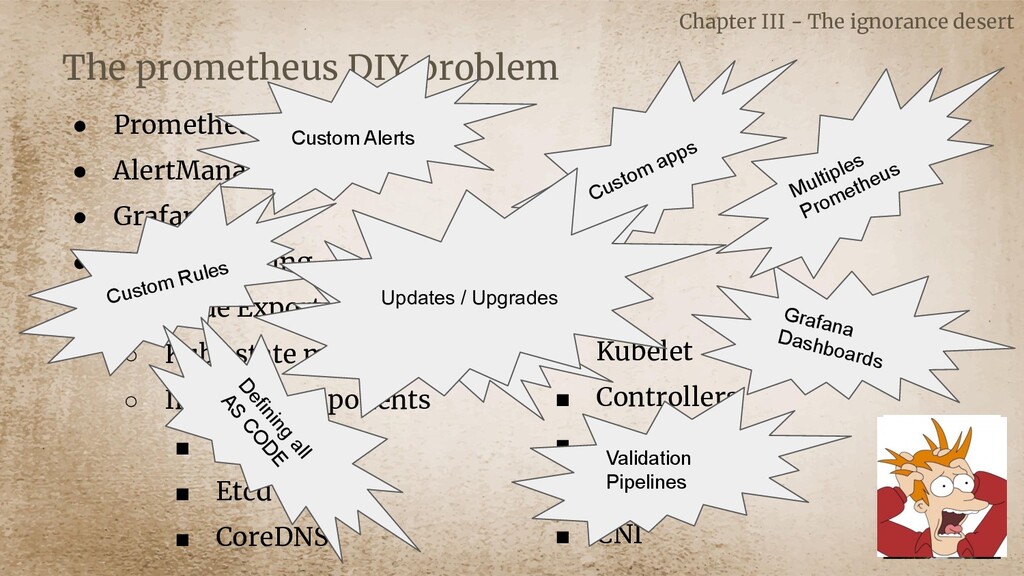
Chapter III - The ignorance desert The prometheus DIY problem
• Prometheus • AlertManager • Grafana • K8s monitoring ◦ Node Exporter ◦ Kube state metrics ◦ Internal components ▪ API server ▪ Etcd ▪ CoreDNS Custom apps Grafana Dashboards Custom Alerts Multiples Prometheus ▪ Kubelet ▪ Controllers ▪ Schedulers ▪ KubeProxy ▪ CNI Custom Rules AlertManager Cluster Defining all AS CO DE Validation Pipelines Updates / Upgrades -
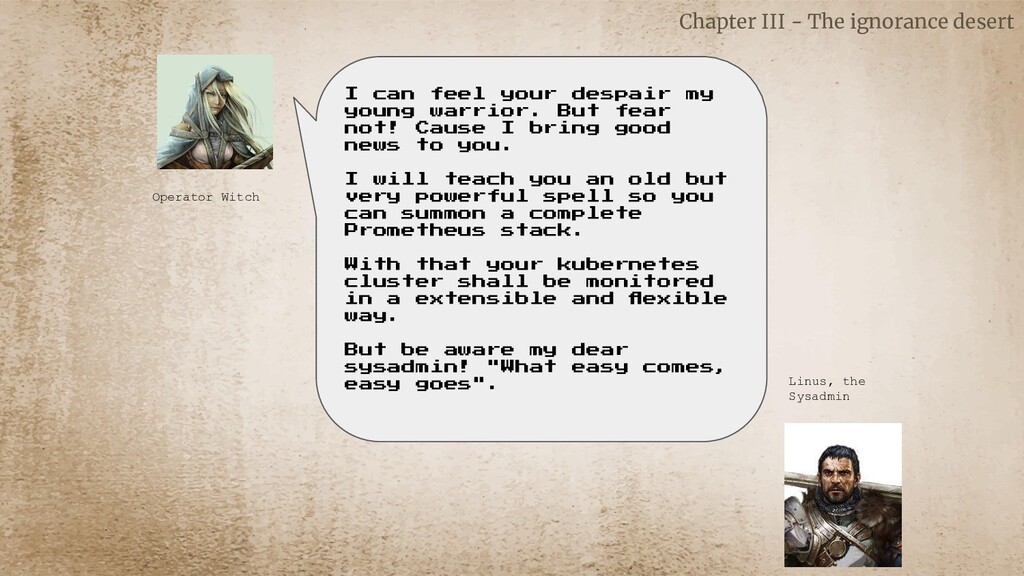
Chapter III - The ignorance desert Operator Witch Linus, the
Sysadmin I can feel your despair my young warrior. But fear not! Cause I bring good news to you. I will teach you an old but very powerful spell so you can summon a complete Prometheus stack. With that your kubernetes cluster shall be monitored in a extensible and flexible way. But be aware my dear sysadmin! "What easy comes, easy goes". -
Prometheus Operator ? An operator is a pattern in which
a software or even a platform is configured, provisioned and managed using Kubernetes objects (usually CRDs). That pattern gives flexibility and a single "language" for kubernetes users and administrators to use. Operators are normally composed by custom controllers that handle defined CRDs and take actions against it, converging the managed software state to the desired state just like a standard k8s object. ◦ Operators examples: ▪ Jenkins, Mongo, Mysql, Cassandra, Spark and many more... Chapter III - The ignorance desert -
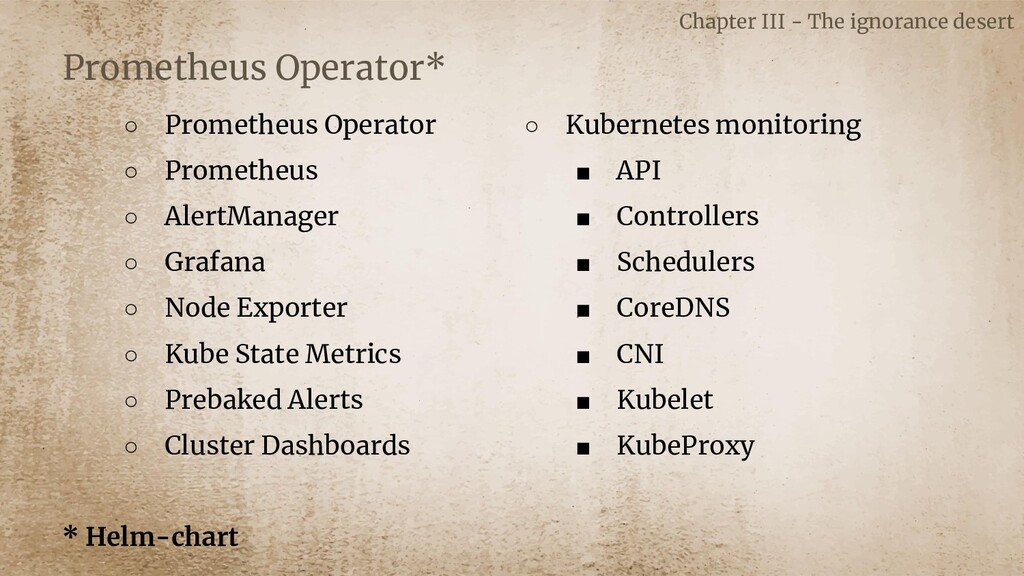
Prometheus Operator* ◦ Prometheus Operator ◦ Prometheus ◦ AlertManager ◦
Grafana ◦ Node Exporter ◦ Kube State Metrics ◦ Prebaked Alerts ◦ Cluster Dashboards * Helm-chart Chapter III - The ignorance desert ◦ Kubernetes monitoring ▪ API ▪ Controllers ▪ Schedulers ▪ CoreDNS ▪ CNI ▪ Kubelet ▪ KubeProxy -
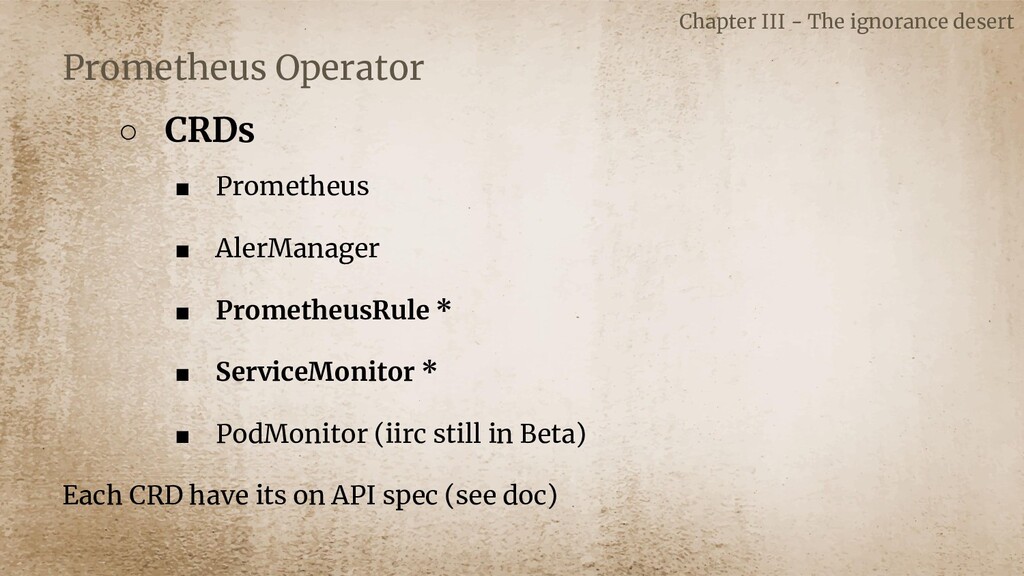
Prometheus Operator ◦ CRDs ▪ Prometheus ▪ AlerManager ▪ PrometheusRule
* ▪ ServiceMonitor * ▪ PodMonitor (iirc still in Beta) Each CRD have its on API spec (see doc) Chapter III - The ignorance desert -
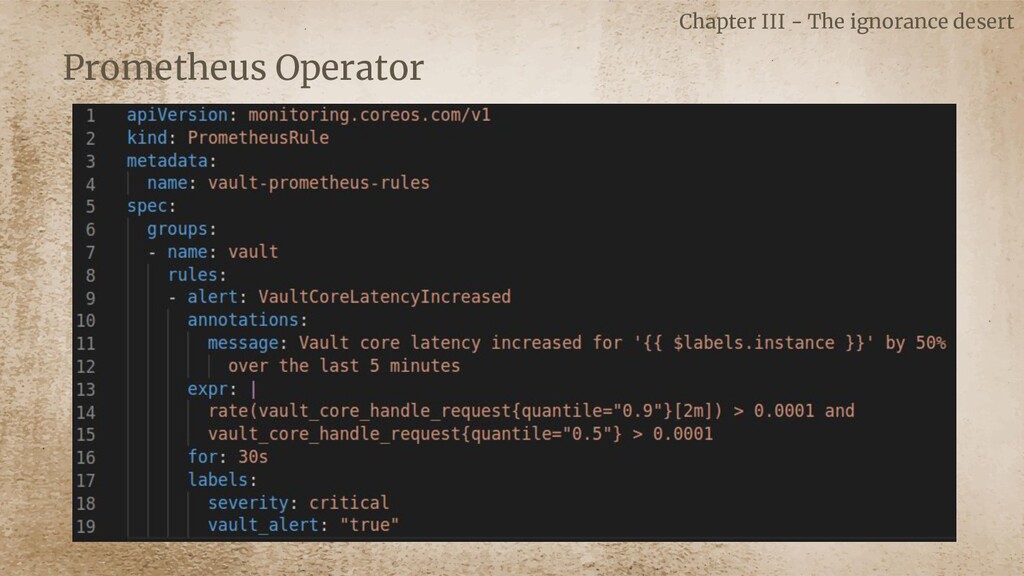
Prometheus Operator PrometheusRule and ServiceMonitor CRDs - Brings flexibility to
monitor and alerting on any application (or exporter) that can expose metrics using Prometheus standard, without the SD syntax hell and the operational burden to validate, merge and reload daemons. Chapter III - The ignorance desert -
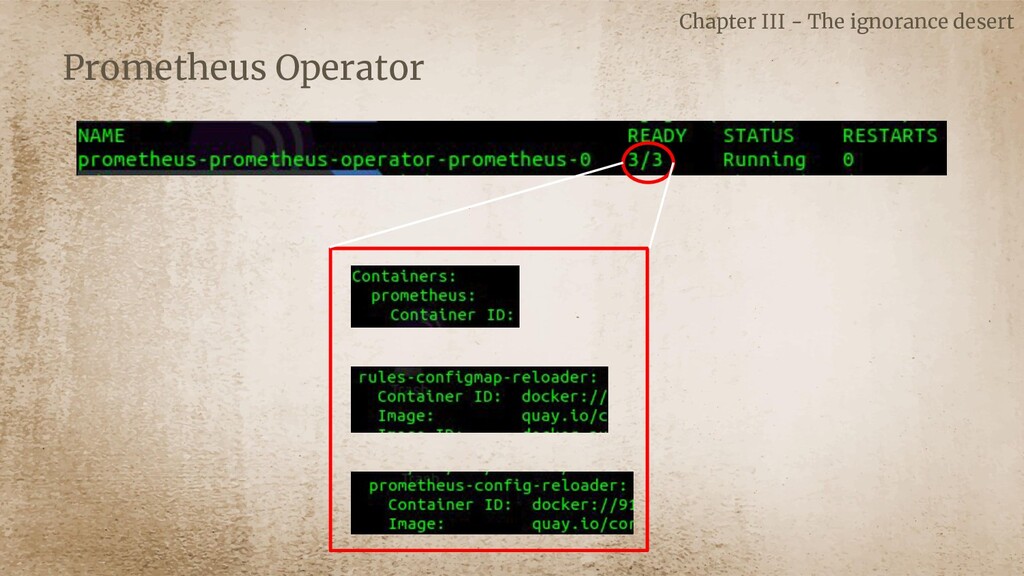
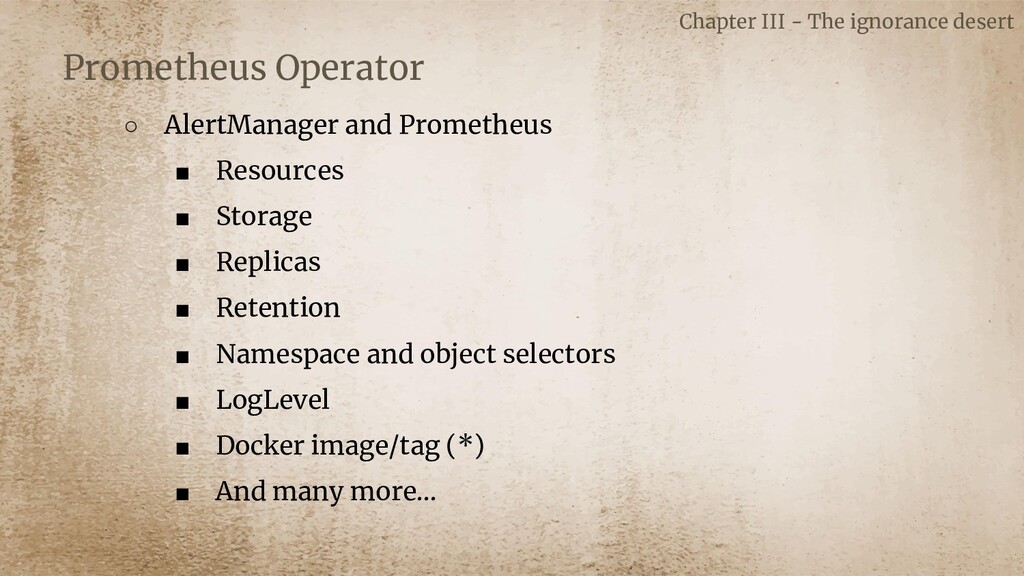
Prometheus Operator ◦ AlertManager and Prometheus ▪ Resources ▪ Storage
▪ Replicas ▪ Retention ▪ Namespace and object selectors ▪ LogLevel ▪ Docker image/tag (*) ▪ And many more... Chapter III - The ignorance desert -
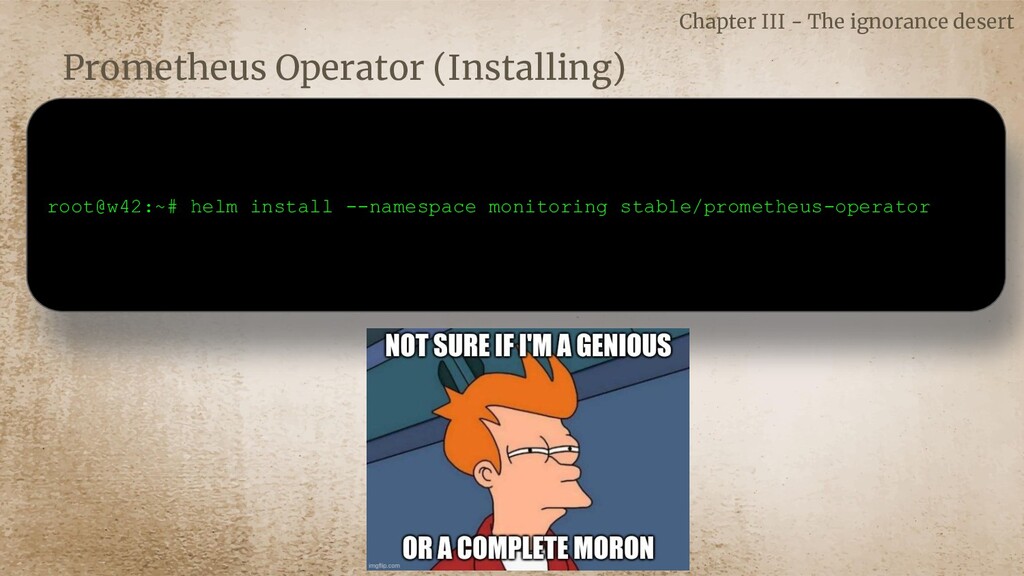
Chapter III - The ignorance desert root@w42:~# helm install --namespace
monitoring stable/prometheus-operator Prometheus Operator (Installing) -
Chapter III - The ignorance desert Operator Witch Linus, the
Sysadmin Oh! so wonderful! An eternal debt to you I have milady! I didn't quite understand your last verse, I must admit. But since the stack is all set, who cares? I must go now! thank you very much! -
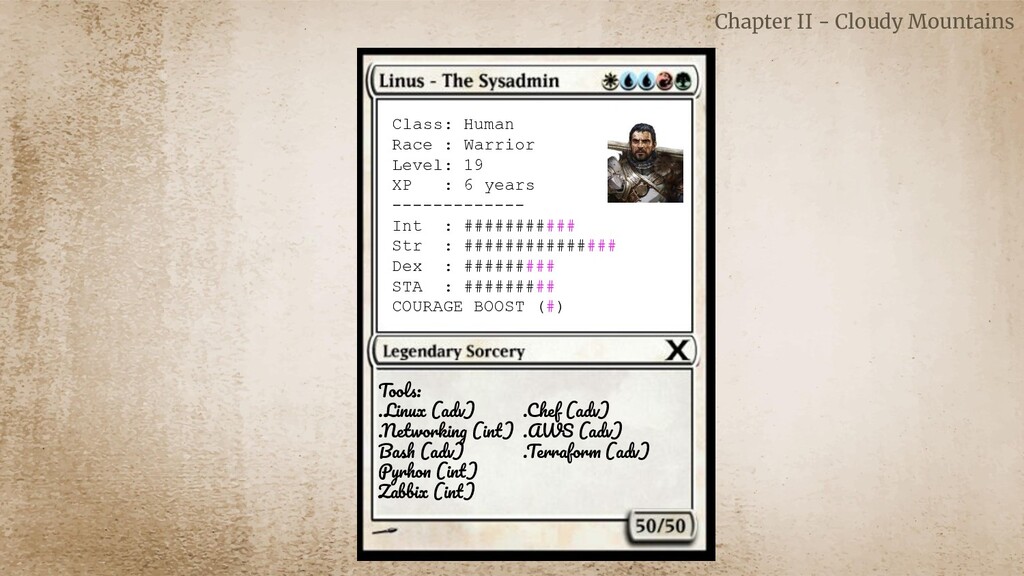
Chapter II - Cloudy Mountains Class: Human Race : Warrior
Level: 19 XP : 6 years ------------- Int : ########### Str : ############### Dex : ######### STA : ######### COURAGE BOOST (#) Tools: .Linux (adv) .Networking (int) Bash (adv) Pyrhon (int) Zabbix (int) .Chef (adv) .AWS (adv) .Terraform (adv) -
Container Harbor landscape ◦ Dozens of kubernetes clusters (kops) ◦
Prometheus Operator (helm) ▪ Prometheus and Alertmanager • Exposed by Ingress (web interfaces) • 45 days of retention • 500m CPU / 4G RAM ▪ Slack as AlertManager Receiver • Custom message templates ▪ Grafana and Dashboards with Prometheus as DataSource ◦ Jenkins as CI/CD system for apps Chapter IV - Container Harbor -
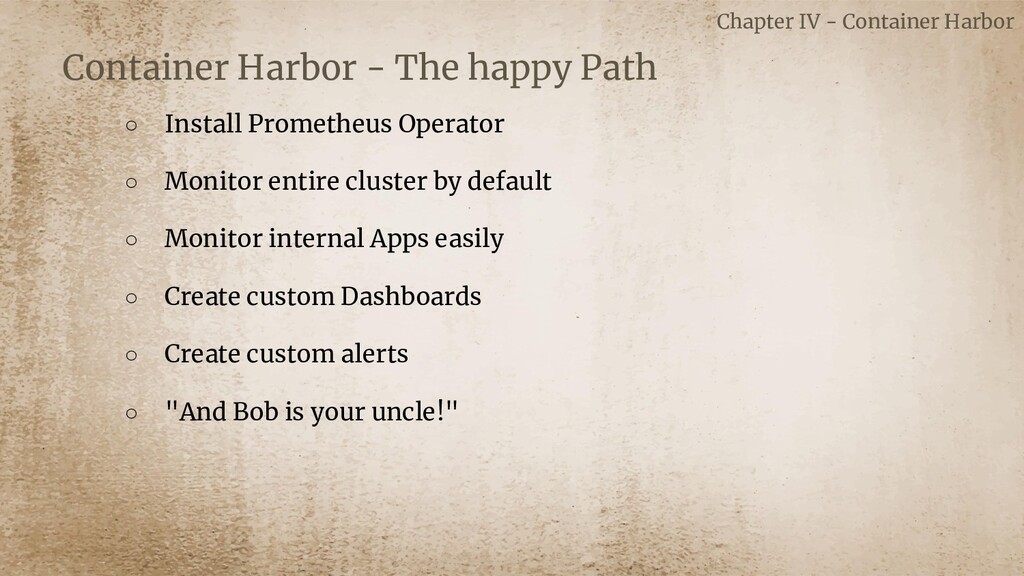
Container Harbor - The happy Path ◦ Install Prometheus Operator
◦ Monitor entire cluster by default ◦ Monitor internal Apps easily ◦ Create custom Dashboards ◦ Create custom alerts ◦ "And Bob is your uncle!" Chapter IV - Container Harbor -
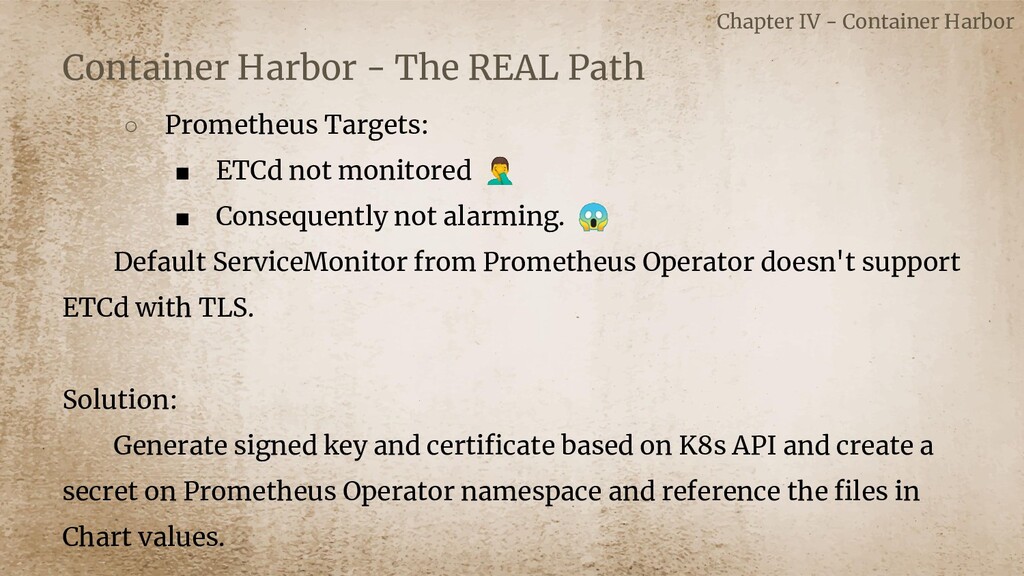
Container Harbor - The REAL Path ◦ Prometheus Targets: ▪
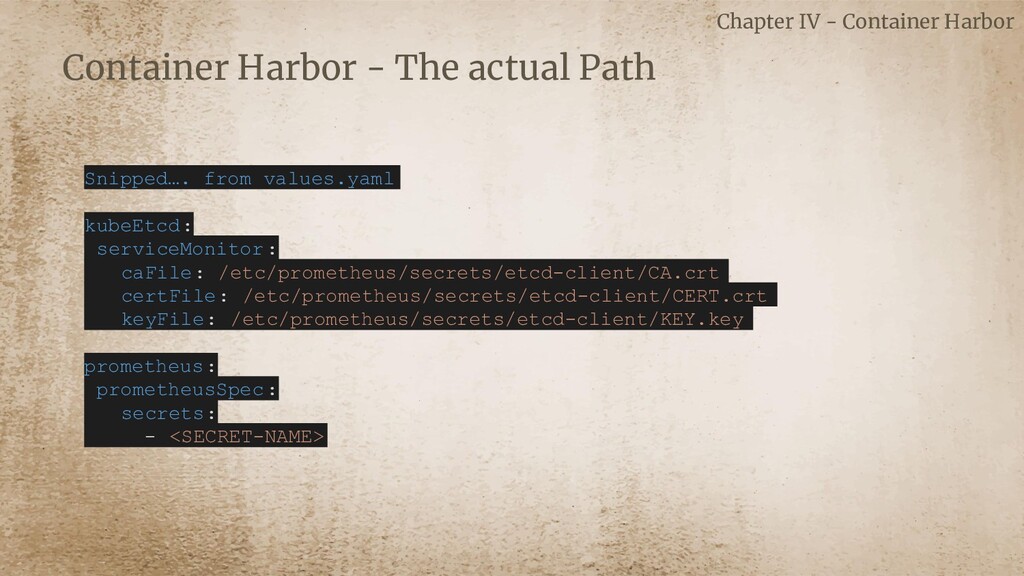
ETCd not monitored ♂ ▪ Consequently not alarming. Default ServiceMonitor from Prometheus Operator doesn't support ETCd with TLS. Solution: Generate signed key and certificate based on K8s API and create a secret on Prometheus Operator namespace and reference the files in Chart values. Chapter IV - Container Harbor -
Container Harbor - The actual Path Chapter IV - Container
Harbor Snipped…. from values.yaml kubeEtcd: serviceMonitor : caFile: /etc/prometheus/secrets/etcd-client/CA.crt certFile: /etc/prometheus/secrets/etcd-client/CERT.crt keyFile: /etc/prometheus/secrets/etcd-client/KEY.key prometheus: prometheusSpec : secrets: - <SECRET-NAME> -
Container Harbor - The actual Path ◦ Prometheus Targets: ▪
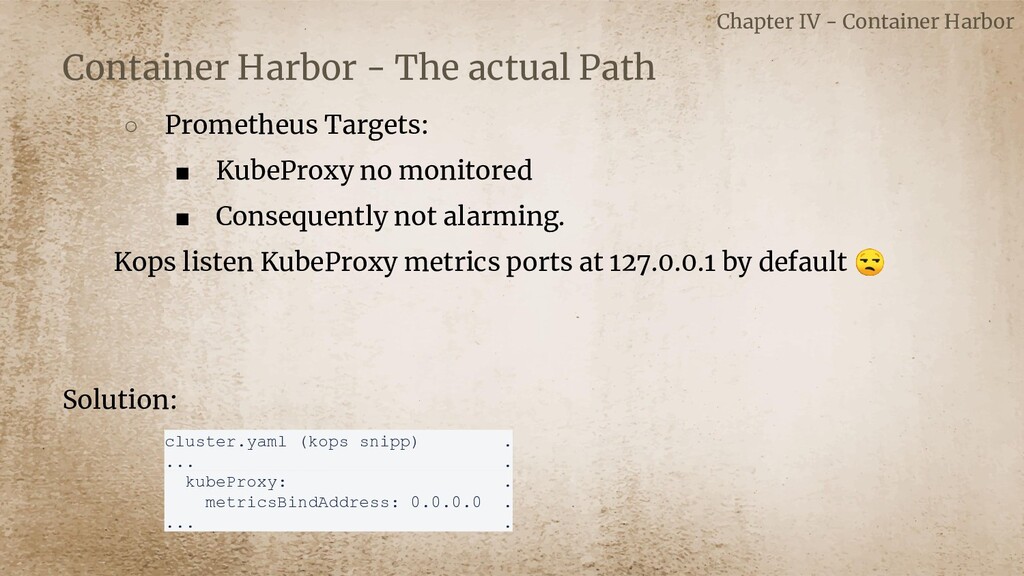
KubeProxy no monitored ▪ Consequently not alarming. Kops listen KubeProxy metrics ports at 127.0.0.1 by default Solution: cluster.yaml (kops snipp) . ... . kubeProxy: . metricsBindAddress: 0.0.0.0 . ... . Chapter IV - Container Harbor -
Container Harbor - The actual Path ◦ Prometheus and AlertManager
▪ Both doesn't have Auth method to the Web-UI ▪ Especially important to AlertManager ⚠ Solution: Use a Auth solution over Ingress Layer. - ldap-proxy (helm installed) Grafana supports .toml file in order to auth on Ldap ❤ Chapter IV - Container Harbor -
Container Harbor - The actual Path ◦ Default Alarms uncalibrated.
◦ Too many firings ▪ ex: Pods CPU Throttling ◦ "wrong" classifications. ▪ ex: Pods restarting too many times (Warning level) Solution: Full Alarms check up. Rebuild YAML file using jsonnet (good luck with that ) Substitute original alarms (service-monitors) with our calibrated ones. Chapter IV - Container Harbor -
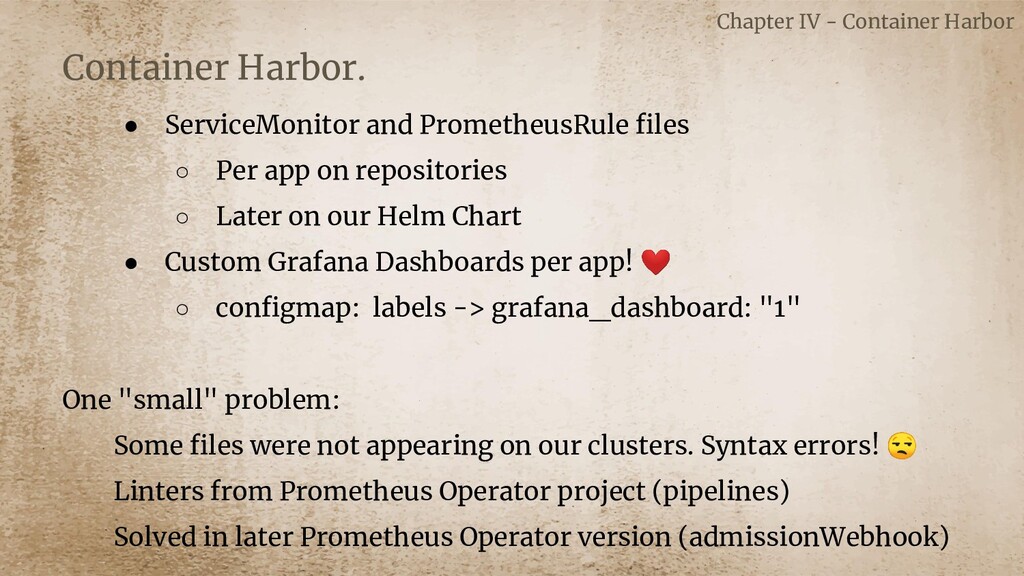
Container Harbor. • ServiceMonitor and PrometheusRule files ◦ Per app
on repositories ◦ Later on our Helm Chart • Custom Grafana Dashboards per app! ❤ ◦ configmap: labels -> grafana_dashboard: "1" One "small" problem: Some files were not appearing on our clusters. Syntax errors! Linters from Prometheus Operator project (pipelines) Solved in later Prometheus Operator version (admissionWebhook) Chapter IV - Container Harbor -
Container Harbor. Prometheus metrics became a thing! • Lots of
apps starting to expose them. • Why not to expose them on ec2 apps? ◦ Where store them? ◦ Solution: EC2 SD based on labels: - PrometheusScrape: true Chapter IV - Container Harbor -
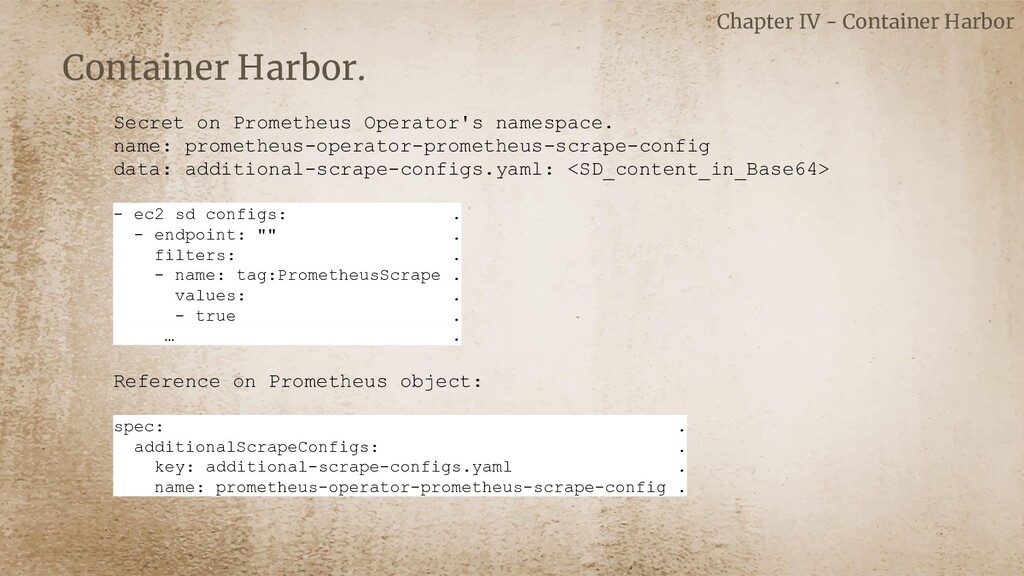
Container Harbor. Secret on Prometheus Operator's namespace. name: prometheus-operator-prometheus-scrape-config data:
additional-scrape-configs.yaml: <SD_content_in_Base64> - ec2_sd_configs: . - endpoint: "" . filters: . - name: tag:PrometheusScrape . values: . - true . … . Reference on Prometheus object: spec: . additionalScrapeConfigs: . key: additional-scrape-configs.yaml . name: prometheus-operator-prometheus-scrape-config . Chapter IV - Container Harbor -
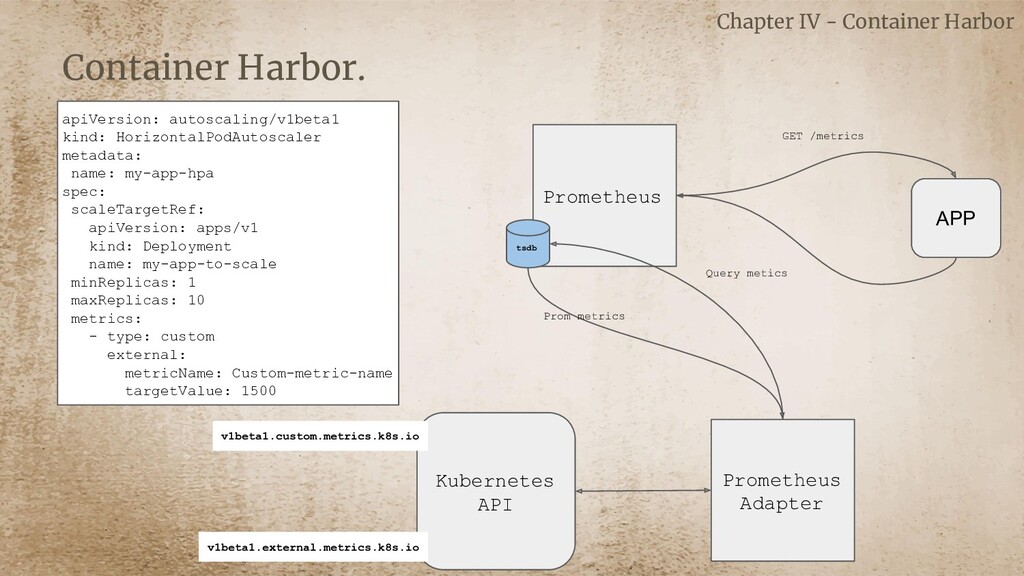
Container Harbor. Custom apps metrics, let's scale by it! Solution:
Prometheus Adapter. (helm) kubectl get APIService v1beta1.metrics.k8s.io ... NAME SERVICE AVAILABLE ... v1beta1.metrics.k8s.io kube-system/metrics-server True ... v1beta1.custom.metrics.k8s.io kube-system/prometheus-adapter True v1beta1.external.metrics.k8s.io kube-system/prometheus-adapter True Chapter IV - Container Harbor -
Container Harbor. apiVersion: autoscaling/v1beta1 kind: HorizontalPodAutoscaler metadata: name: my-app-hpa spec:
scaleTargetRef: apiVersion: apps/v1 kind: Deployment name: my-app-to-scale minReplicas: 1 maxReplicas: 10 metrics: - type: custom external: metricName: Custom-metric-name targetValue: 1500 Chapter IV - Container Harbor Prometheus tsdb APP GET /metrics Prometheus Adapter Query metics Prom metrics Kubernetes API v1beta1.custom.metrics.k8s.io v1beta1.external.metrics.k8s.io -
Container Harbor. Scaling by external metrics, an example: • Scaling
by number of messages in SQS • Tiamat ◦ Collect queue stats and stores at prometheus. ◦ Labels defines queue IDs ◦ Plans to support ▪ Kafka topics ▪ ... Chapter IV - Container Harbor -
Container Harbor. apiVersion: autoscaling/v1beta1 kind: HorizontalPodAutoscaler metadata: name: my-app-hpa spec:
scaleTargetRef: apiVersion: apps/v1 kind: Deployment name: my-app-to-scale minReplicas: 1 maxReplicas: 10 metrics: - type: custom external: metricName: My_queue_size targetValue: 1500 Chapter IV - Container Harbor Prometheus tsdb GET /metrics Prometheus Adapter Query metics Prom metrics Kubernetes API v1beta1.external.metrics.k8s.io Tiamat My_queue_size: 2300 -
Container Harbor. • Many metrics (k8s and ec2 apps) •
Lots! lots! of Grafanas (datasource -> k8s prometheus) • Gigantic queries! Chapter IV - Container Harbor -
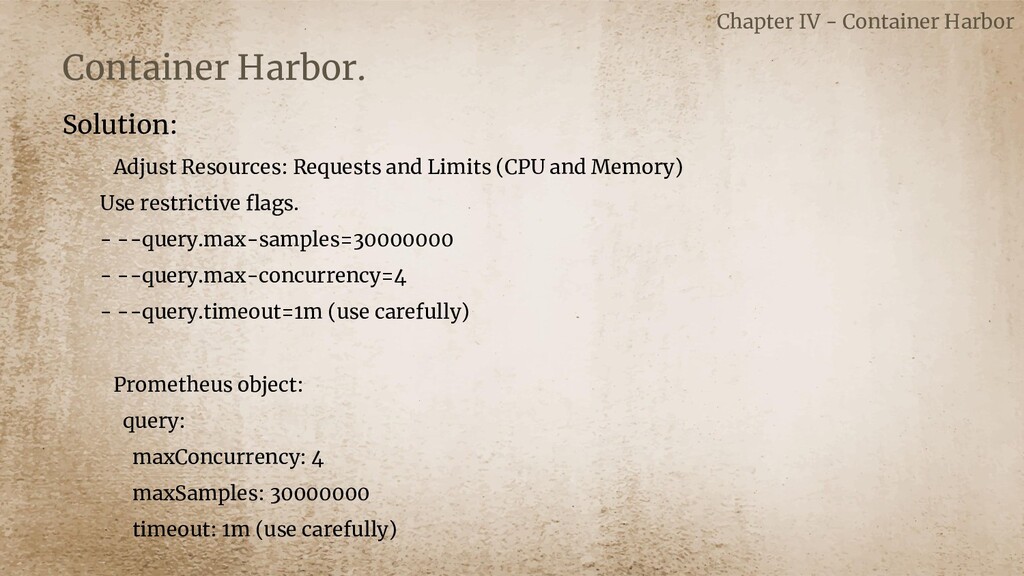
Container Harbor. Solution: Adjust Resources: Requests and Limits (CPU and
Memory) Use restrictive flags. - --query.max-samples=30000000 - --query.max-concurrency=4 - --query.timeout=1m (use carefully) Prometheus object: query: maxConcurrency: 4 maxSamples: 30000000 timeout: 1m (use carefully) Chapter IV - Container Harbor -
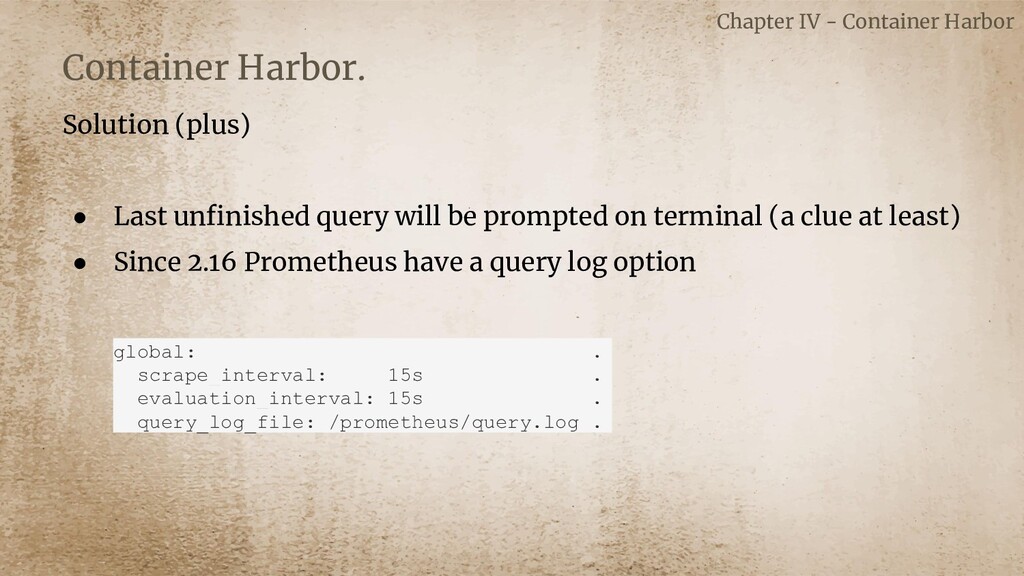
Container Harbor. Solution (plus) • Last unfinished query will be
prompted on terminal (a clue at least) • Since 2.16 Prometheus have a query log option global: . scrape_interval: 15s . evaluation_interval: 15s . query_log_file: /prometheus/query.log . Chapter IV - Container Harbor -
Container Harbor. • Scraped Metrics can also go wrong. •
Really wrong! • Like knockout wrong Chapter IV - Container Harbor -
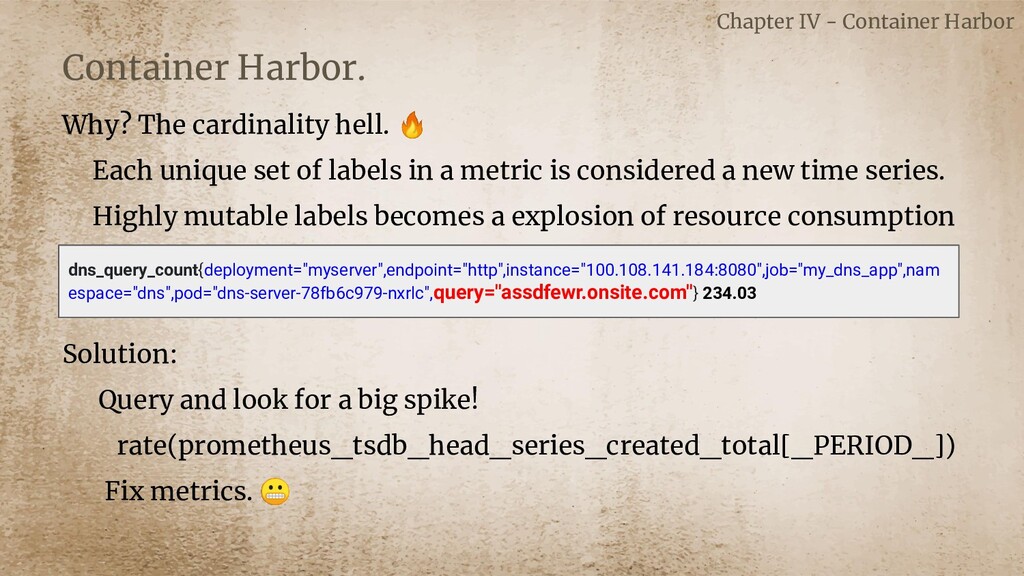
Container Harbor. Why? The cardinality hell. Each unique set of
labels in a metric is considered a new time series. Highly mutable labels becomes a explosion of resource consumption Solution: Query and look for a big spike! rate(prometheus_tsdb_head_series_created_total[_PERIOD_]) Fix metrics. Chapter IV - Container Harbor dns_query_count{deployment="myserver",endpoint="http",instance="100.108.141.184:8080",job="my_dns_app",nam espace="dns",pod="dns-server-78fb6c979-nxrlc",query="assdfewr.onsite.com"} 234.03 -
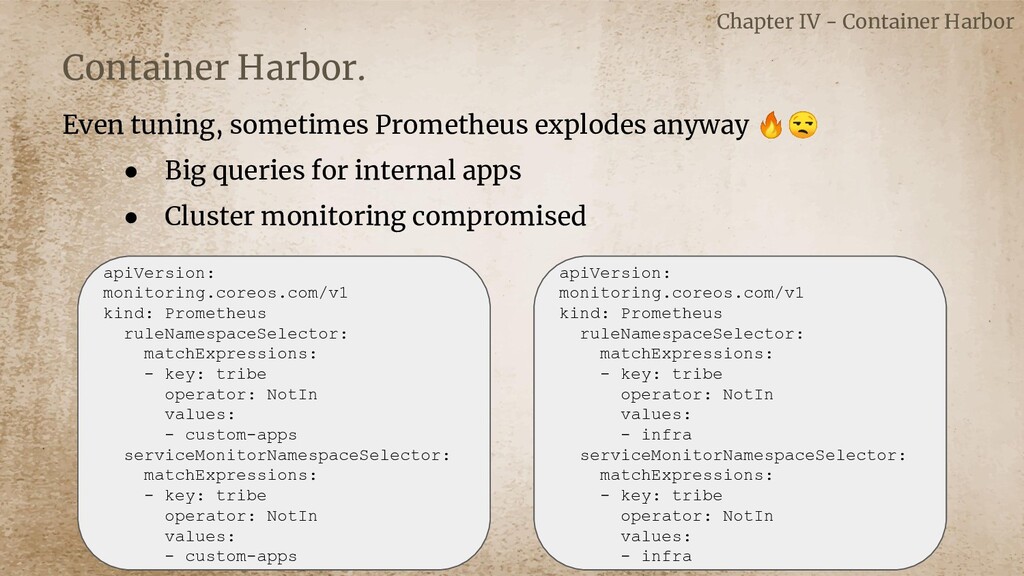
Container Harbor. Even tuning, sometimes Prometheus explodes anyway • Big
queries for internal apps • Cluster monitoring compromised Chapter IV - Container Harbor apiVersion: monitoring.coreos.com/v1 kind: Prometheus ruleNamespaceSelector: matchExpressions: - key: tribe operator: NotIn values: - infra serviceMonitorNamespaceSelector: matchExpressions: - key: tribe operator: NotIn values: - infra apiVersion: monitoring.coreos.com/v1 kind: Prometheus ruleNamespaceSelector: matchExpressions: - key: tribe operator: NotIn values: - custom-apps serviceMonitorNamespaceSelector: matchExpressions: - key: tribe operator: NotIn values: - custom-apps -
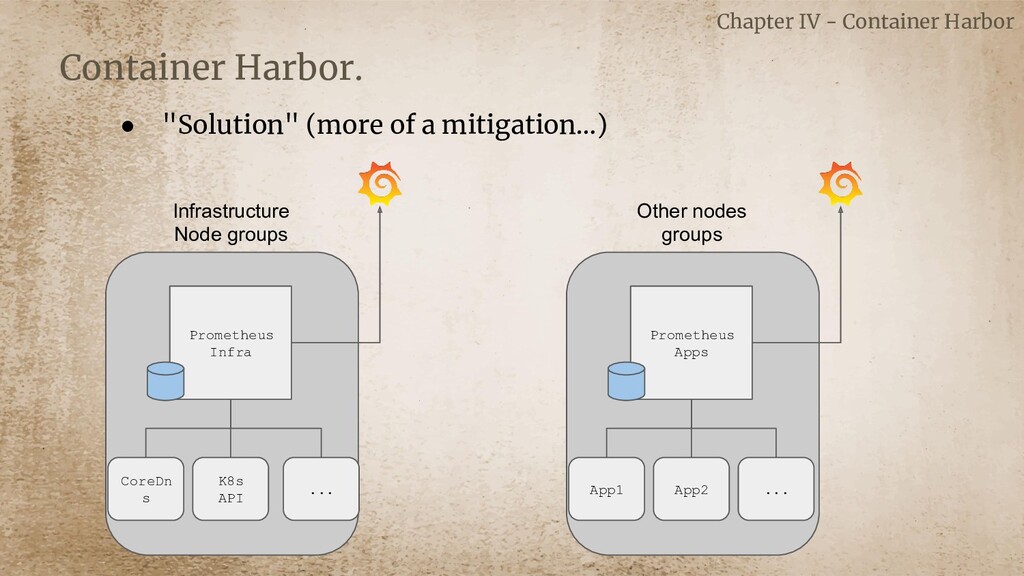
Container Harbor. • "Solution" (more of a mitigation…) Chapter IV
- Container Harbor Prometheus Infra K8s API CoreDn s Infrastructure Node groups Prometheus Apps App2 App1 Other nodes groups ... ... -
Container Harbor. AlertManager • Responsible to route alerts • Single
point of failure • By default just 1 replica. • Capable to create HA cluster. Solution: (super easy) AlertManager object (CRD) Replicas: 3 Chapter IV - Container Harbor -
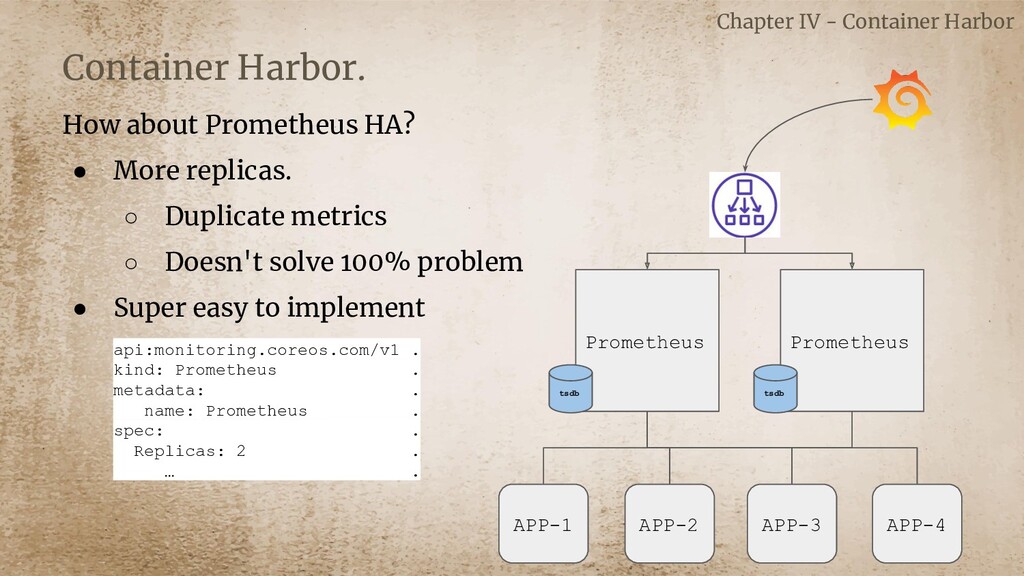
Container Harbor. How about Prometheus HA? • Prometheus does not
create clusters Chapter IV - Container Harbor Prometheus tsdb APP-4 APP-3 APP-2 APP-1 -
Container Harbor. How about Prometheus HA? • More replicas. ◦
Duplicate metrics ◦ Doesn't solve 100% problem • Super easy to implement api:monitoring.coreos.com/v1 . kind: Prometheus . metadata: . name: Prometheus . spec: . Replicas: 2 . … . Chapter IV - Container Harbor Prometheus tsdb APP-4 APP-3 APP-2 APP-1 Prometheus tsdb -
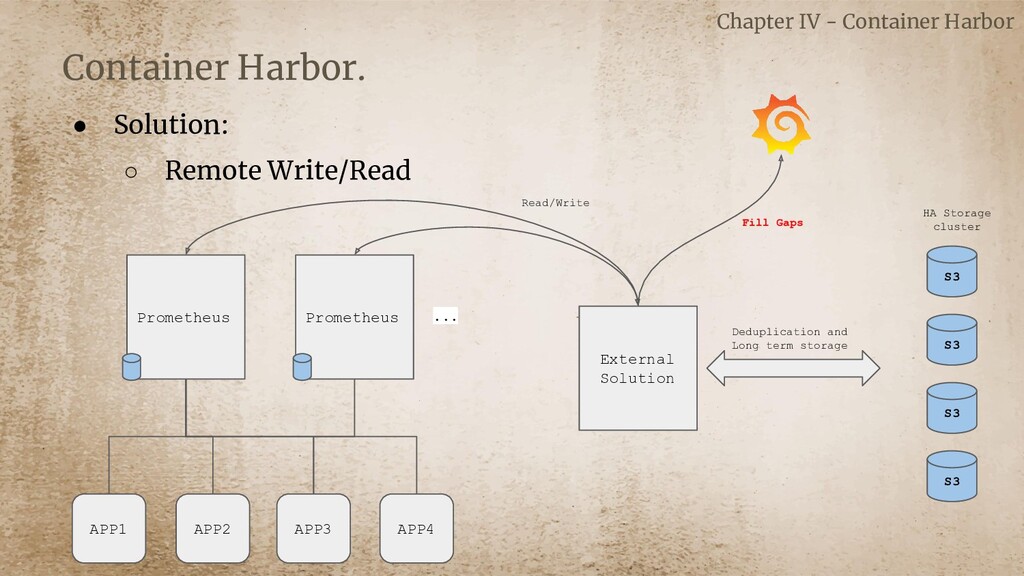
Container Harbor. • Solution: ◦ Remote Write/Read Chapter IV -
Container Harbor S3 External Solution Read/Write Deduplication and Long term storage S3 S3 S3 HA Storage cluster Fill Gaps Prometheus APP4 APP3 APP2 APP1 Prometheus ... -
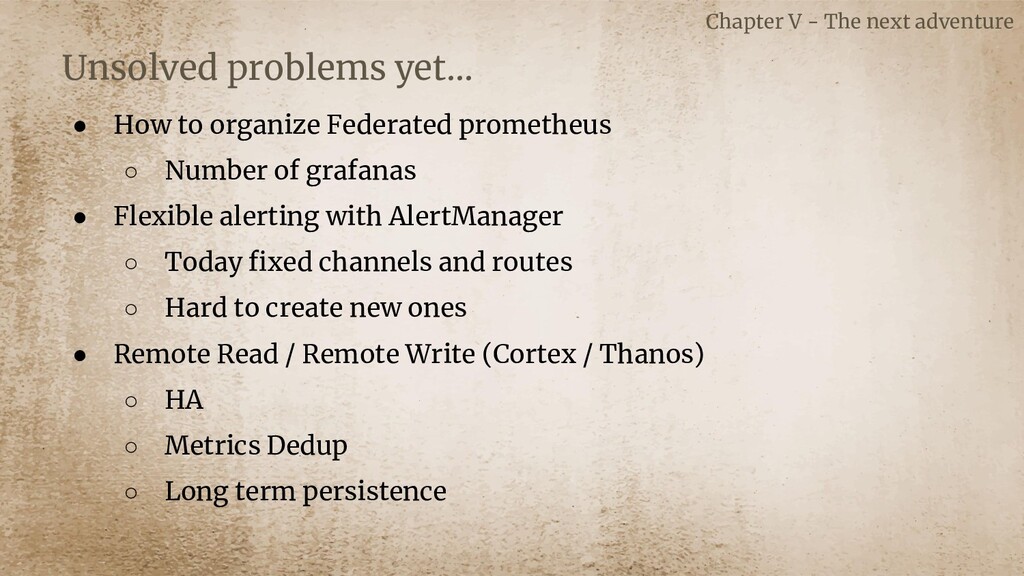
Unsolved problems yet... • How to organize Federated prometheus ◦
Number of grafanas • Flexible alerting with AlertManager ◦ Today fixed channels and routes ◦ Hard to create new ones • Remote Read / Remote Write (Cortex / Thanos) ◦ HA ◦ Metrics Dedup ◦ Long term persistence Chapter V - The next adventure -
References • https://prometheus.io/ • https://github.com/coreos/prometheus-operator • https://github.com/helm/charts/tree/master/stable/prometheus-operator • https://www.youtube.com/watch?v=pRmnh8lgjsU •
https://kubernetes.io/docs/concepts/extend-kubernetes/operator/ • https://coreos.com/blog/introducing-operators.html • https://operatorhub.io/ • https://github.com/tiagoapimenta/nginx-ldap-auth • https://github.com/hugobcar/tiamat • https://github.com/helm/charts/tree/master/stable/grafana • https://github.com/DirectXMan12/k8s-prometheus-adapter • https://cortexmetrics.io/ • https://www.youtube.com/watch?v=b_pEevMAC3I
 drequena
 wind111
 kamadamakoto
 daitak
 yuutosi
 munakata
 smt7174
 silmin_
 ivry_presentationmaterials
 grimoh
 rist
 sansantech
 ydah
 tammyeverts
 tanoku
 dugsong
 palkan
 addyosmani
 ryanjones
 sabderemane
 morganepeng
 codingconduct
 lauravandoore
 schlessera
 cassininazir