Share
Embed
SELECT ALL THE THINGS - Cascading Lingual, ANSI SQL for Apache Hadoop
Slide deck of a talk I gave about Cascading and Lingual at the TU Berlin.
André Kelpe
January 13, 2014
Transcript
26 slides
-
SELECT ALL THE THINGS! Cascading Lingual ANSI SQL for Apache
Hadoop TU-Berlin, January 13th 2014 André Kelpe concurrentinc.com -
Speaker André Kelpe Software Engineer at Concurrent The company behind
Cascading and Lingual concurrentinc.com / @concurrent [email protected] @fs111 -
Agenda Cascading and Lingual Lingual: design goals Lingual: features Demo:
Lingual in action Q&A -
Cascading terminology Taps are sources and sinks for data Schemes
represent the format of the data Pipes are connecting Taps -
Cascading terminology Tuples flow through Pipes Fields describe the Tuples
Operations are executed on Tuples in TupleStreams Flows get scheduled and executed -
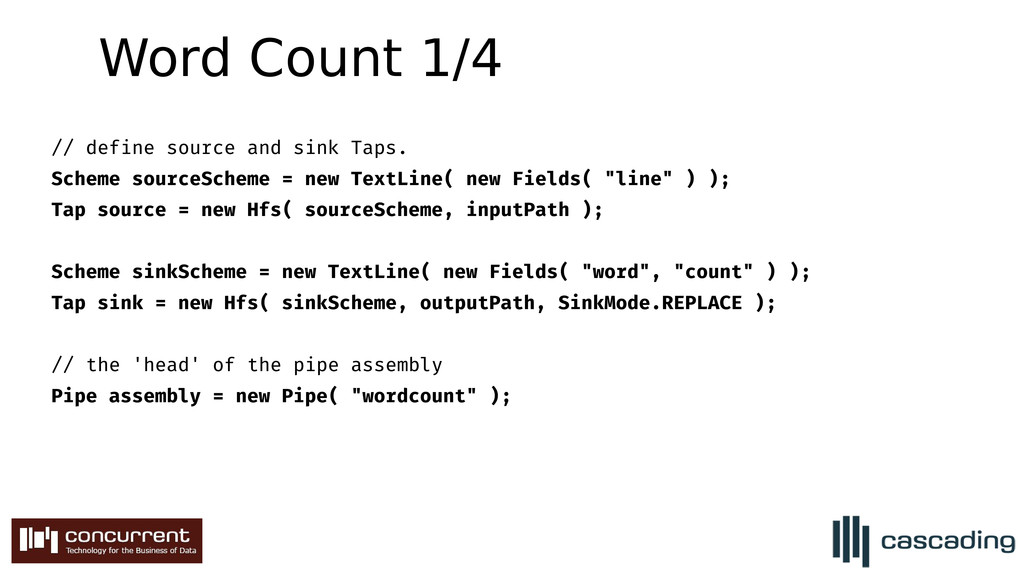
Word Count 1/4 // define source and sink Taps. Scheme
sourceScheme = new TextLine( new Fields( "line" ) ); Tap source = new Hfs( sourceScheme, inputPath ); Scheme sinkScheme = new TextLine( new Fields( "word", "count" ) ); Tap sink = new Hfs( sinkScheme, outputPath, SinkMode.REPLACE ); // the 'head' of the pipe assembly Pipe assembly = new Pipe( "wordcount" ); -
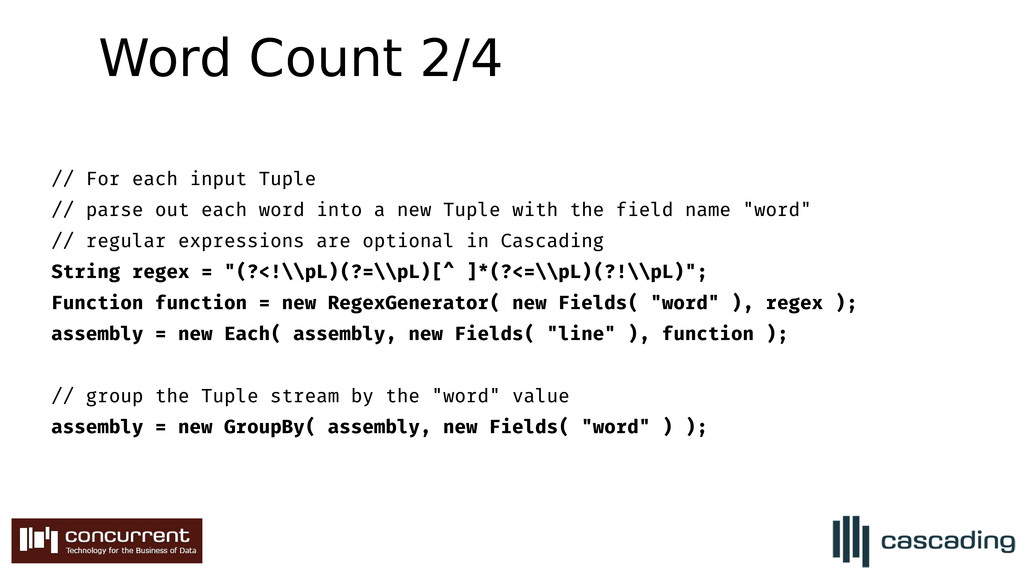
Word Count 2/4 // For each input Tuple // parse
out each word into a new Tuple with the field name "word" // regular expressions are optional in Cascading String regex = "(?<!\\pL)(?=\\pL)[^ ]*(?<=\\pL)(?!\\pL)"; Function function = new RegexGenerator( new Fields( "word" ), regex ); assembly = new Each( assembly, new Fields( "line" ), function ); // group the Tuple stream by the "word" value assembly = new GroupBy( assembly, new Fields( "word" ) ); -
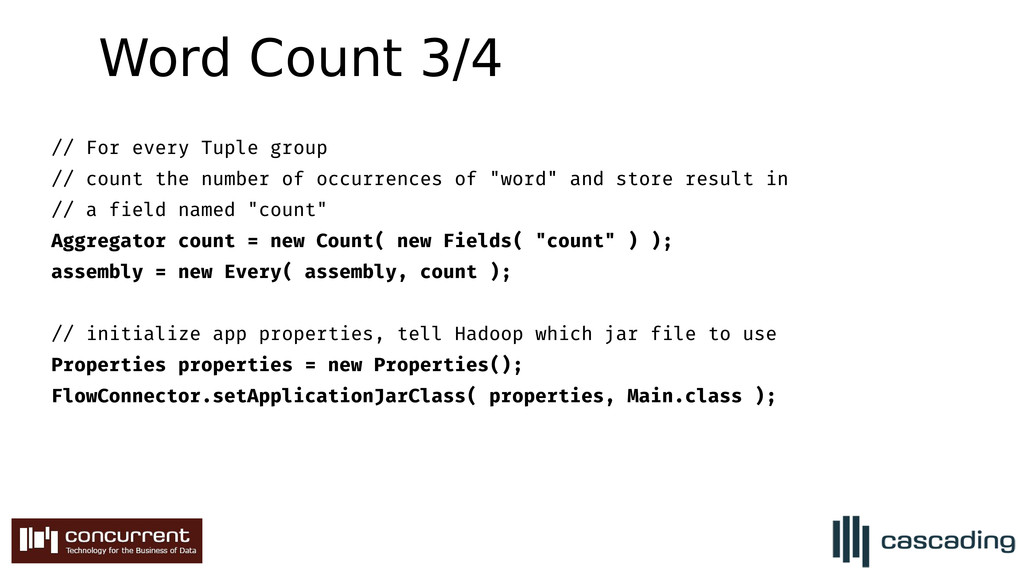
// For every Tuple group // count the number of
occurrences of "word" and store result in // a field named "count" Aggregator count = new Count( new Fields( "count" ) ); assembly = new Every( assembly, count ); // initialize app properties, tell Hadoop which jar file to use Properties properties = new Properties(); FlowConnector.setApplicationJarClass( properties, Main.class ); Word Count 3/4 -
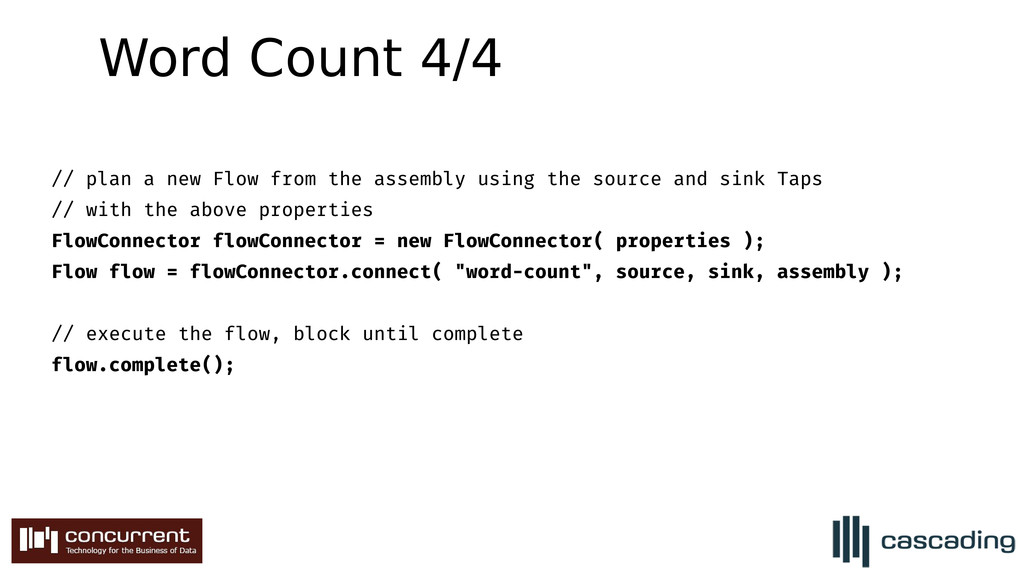
// plan a new Flow from the assembly using the
source and sink Taps // with the above properties FlowConnector flowConnector = new FlowConnector( properties ); Flow flow = flowConnector.connect( "word-count", source, sink, assembly ); // execute the flow, block until complete flow.complete(); Word Count 4/4 -
Scalding Scala DSL on top of Cascading Developed by twitter
https://github.com/twitter/scalding/ -
Cascalog Clojure DSL on top of Cascading Inspired by datalog
https://github.com/nathanmarz/cascalog -
Lingual – design goals 1/3 Immediate Data Access SQL access
via Shell or JDBC driver -
Lingual – design goals 2/3 Simplify SQL Migration move SQL
workflows on your Hadoop Cluster via Cascading flows or JDBC driver -
Lingual – design goals 3/3 Simplify System & Data Integration
Read and write from hdfs, jdbc, memcached, HBase, redshift... -
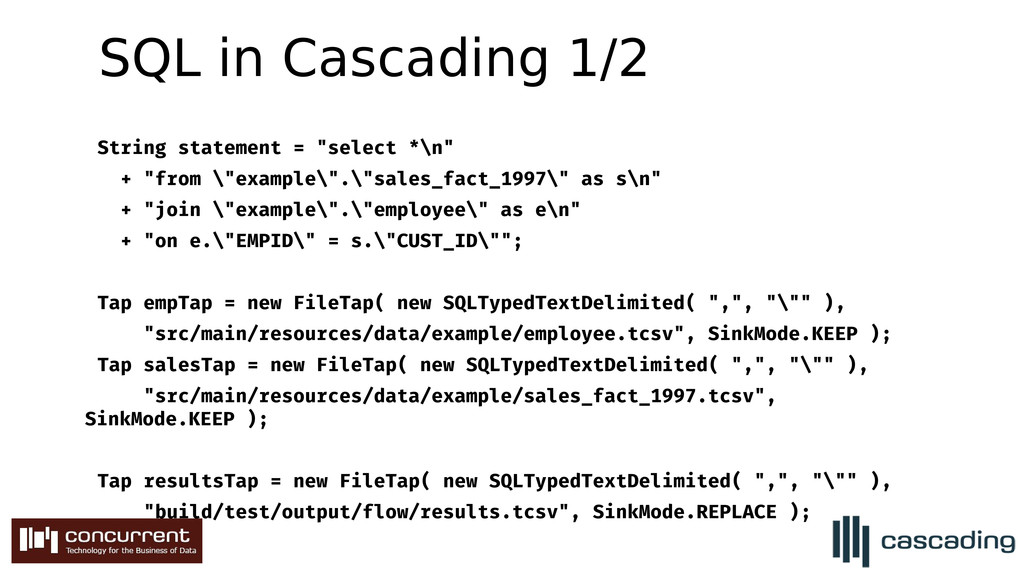
SQL in Cascading 1/2 String statement = "select *\n" +
"from \"example\".\"sales_fact_1997\" as s\n" + "join \"example\".\"employee\" as e\n" + "on e.\"EMPID\" = s.\"CUST_ID\""; Tap empTap = new FileTap( new SQLTypedTextDelimited( ",", "\"" ), "src/main/resources/data/example/employee.tcsv", SinkMode.KEEP ); Tap salesTap = new FileTap( new SQLTypedTextDelimited( ",", "\"" ), "src/main/resources/data/example/sales_fact_1997.tcsv", SinkMode.KEEP ); Tap resultsTap = new FileTap( new SQLTypedTextDelimited( ",", "\"" ), "build/test/output/flow/results.tcsv", SinkMode.REPLACE ); -
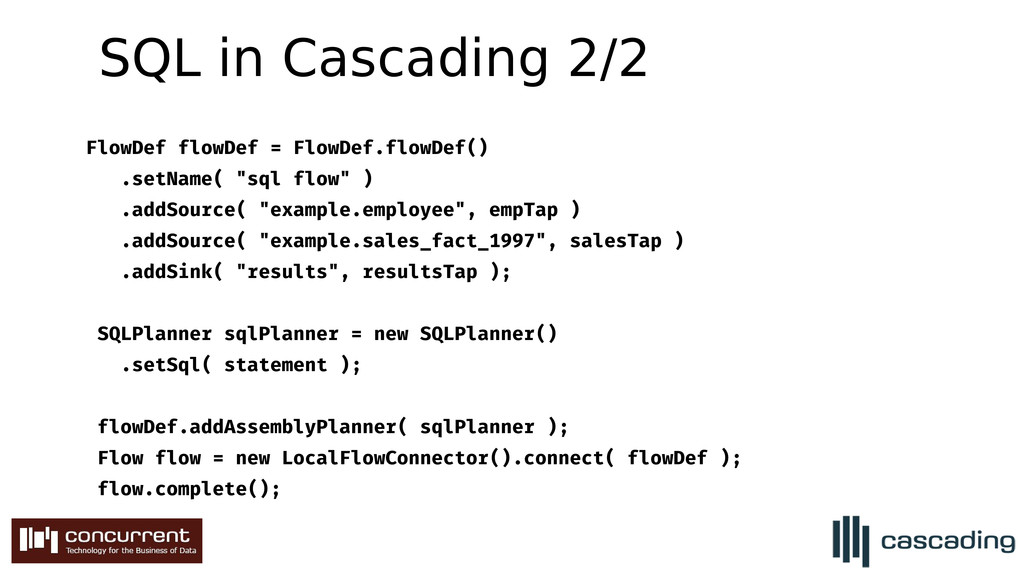
SQL in Cascading 2/2 FlowDef flowDef = FlowDef.flowDef() .setName( "sql
flow" ) .addSource( "example.employee", empTap ) .addSource( "example.sales_fact_1997", salesTap ) .addSink( "results", resultsTap ); SQLPlanner sqlPlanner = new SQLPlanner() .setSql( statement ); flowDef.addAssemblyPlanner( sqlPlanner ); Flow flow = new LocalFlowConnector().connect( flowDef ); flow.complete(); -
Link collection http://www.cascading.org/lingual/ http://www.cascading.org/ http://docs.cascading.org/lingual/1.0/ https://github.com/Cascading/ http://concurrentinc.com https://groups.google.com/forum/#!forum/lingual-user https://groups.google.com/forum/#!forum/cascading-user http://docs.cascading.org/impatient/
https://github.com/Cascading/vagrant-cascading-hadoop-cluster