Share
Embed
The Cascading (big) data application framework
A talk about Cascading given at the Hadoop User Group France in Paris in November 2014
André Kelpe
November 25, 2014
Transcript
21 slides
-
The Cascading (big) data application framework André Kelpe | HUG
France | Paris | 25. November 2014 -
Who am I? André Kelpe Senior Software Engineer at Concurrent
company behind Cascading, Lingual and Driven http://concurrentinc.com / @concurrent [email protected] / @fs111 -
http://cascading.org Apache licensed Java framework for writing data oriented applications
production ready, stable and battle proven (soundcloud, twitter, etsy, climate corp + many more) -
Cascading goals developer productivity focus on business problems, not distributed
systems knowledge useful abstractions over underlying „fabrics“ -
Cascading goals Testability & robustness production quality applications rather than
a collection of scripts (hooks into the core for experts) -
Cascading terminology Taps are sources and sinks for data Schemes
represent the format of the data Pipes are connecting Taps -
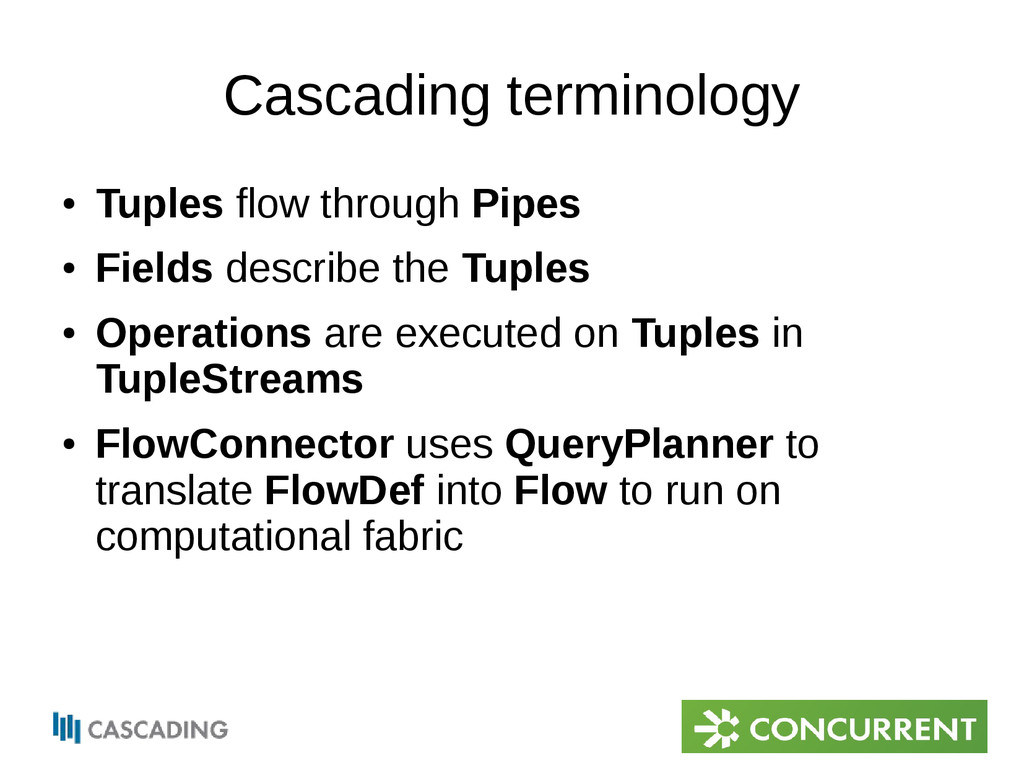
Cascading terminology • Tuples flow through Pipes • Fields describe
the Tuples • Operations are executed on Tuples in TupleStreams • FlowConnector uses QueryPlanner to translate FlowDef into Flow to run on computational fabric -
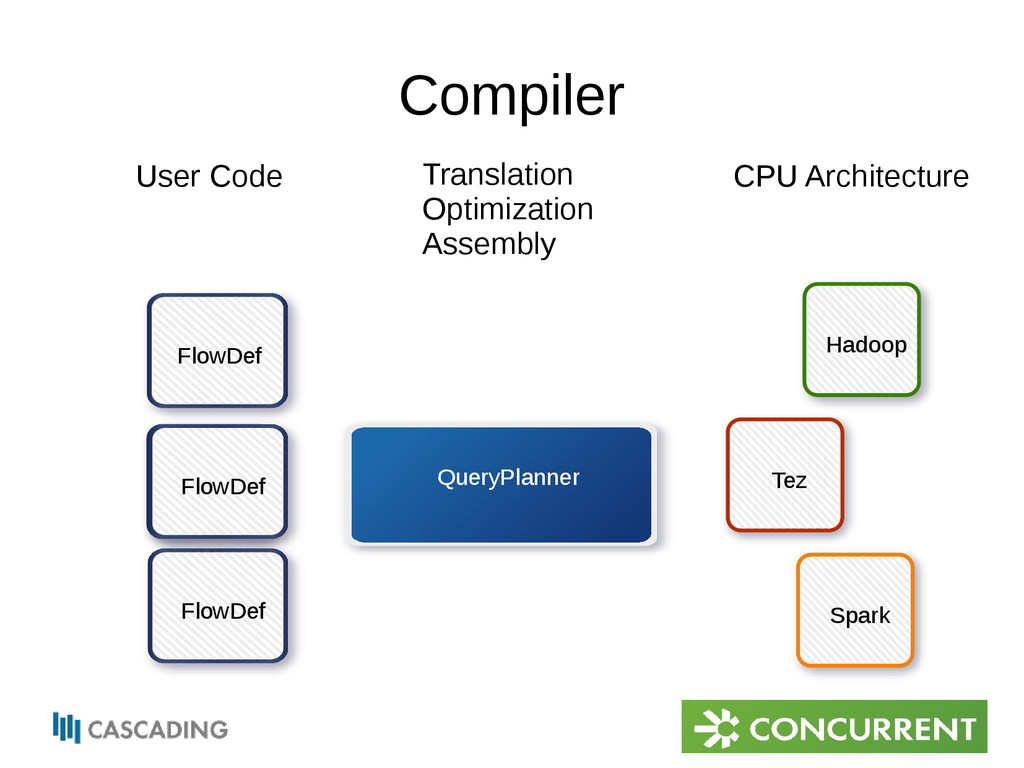
Compiler QueryPlanner FlowDef FlowDef FlowDef Hadoop Tez FlowDef Spark User
Code Translation Optimization Assembly CPU Architecture -
User-APIs • Fluid - A Fluent API for Cascading –
Targeted at application writers – https://github.com/Cascading/fluid • „Raw“ Cascading API – Targeted for library writers, code generators, integration layers – https://github.com/Cascading/cascading -
Counting words // configuration String docPath = args[ 0 ];
String wcPath = args[ 1 ]; Properties properties = new Properties(); AppProps.setApplicationJarClass( properties, Main.class ); FlowConnector flowConnector = new Hadoop2MR1FlowConnector( properties ); // create source and sink taps Tap docTap = new Hfs( new TextDelimited( true, "\t" ), docPath ); Tap wcTap = new Hfs( new TextDelimited( true, "\t" ), wcPath ); ... -
Counting words (cont.) // specify a regex operation to split
the "document" text lines into a token stream Fields token = new Fields( "token" ); Fields text = new Fields( "text" ); RegexSplitGenerator splitter = new RegexSplitGenerator( token, "[ \\[\\]\\(\\),.]" ); // only returns "token" Pipe docPipe = new Each( "token", text, splitter, Fields.RESULTS ); // determine the word counts Pipe wcPipe = new Pipe( "wc", docPipe ); wcPipe = new GroupBy( wcPipe, token ); wcPipe = new Every( wcPipe, Fields.ALL, new Count(), Fields.ALL ); ... -
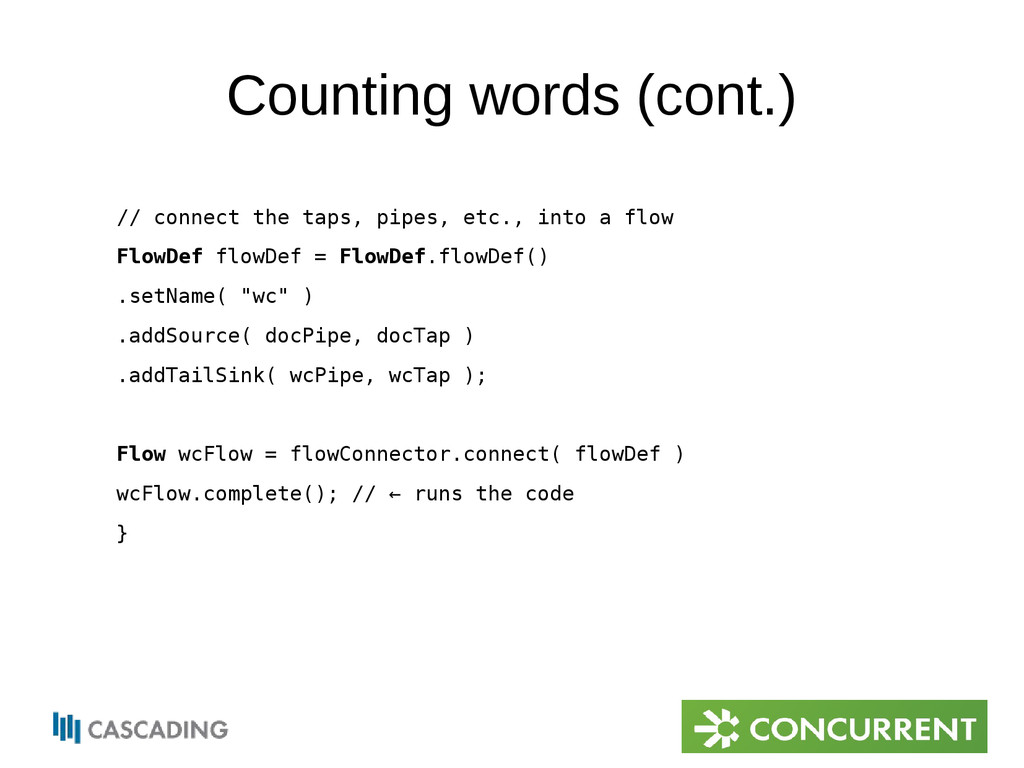
// connect the taps, pipes, etc., into a flow FlowDef
flowDef = FlowDef.flowDef() .setName( "wc" ) .addSource( docPipe, docTap ) .addTailSink( wcPipe, wcTap ); Flow wcFlow = flowConnector.connect( flowDef ) wcFlow.complete(); // ← runs the code } Counting words (cont.) -
• Operations – Function – Filter – Regex/Scripts – Boolean
operators – Count/Limit/Last/First – Scripts – Unique – Asserts – Min/Max – … • Splices – GroupBy – CoGroup – HashJoin – Merge A full toolbox • Joins Left, right, outer, inner, mixed... -
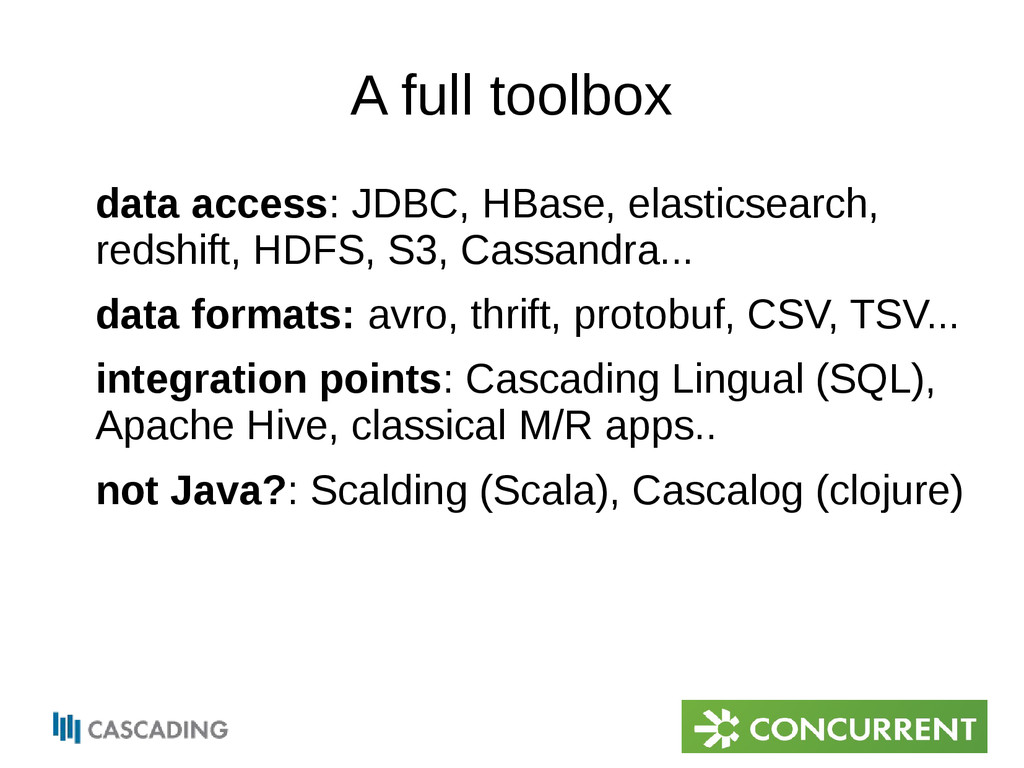
A full toolbox data access: JDBC, HBase, elasticsearch, redshift, HDFS,
S3, Cassandra... data formats: avro, thrift, protobuf, CSV, TSV... integration points: Cascading Lingual (SQL), Apache Hive, classical M/R apps.. not Java?: Scalding (Scala), Cascalog (clojure) -
Status quo • Cascading 2.6 – Production release • Hadoop
2.x • Hadoop 1.x • Local mode • Cascading 3.0 – public wip builds • Tez • Hadoop 2.x • Hadoop 1.x • Local mode • Others (Spark...)