SAMOA: A Platform for Mining Big Data Streams

Share
Embed
SAMOA: A Platform for Mining Big Data Streams
RAMSS '13: 2nd International Workshop on Real-Time Analysis and Mining of Social Streams, @WWW, Rio De Janeiro.

Gianmarco De Francisci Morales
May 14, 2013
Transcript
54 slides
-
SAMOA A Platform for Mining Big Data Streams Gianmarco De
Francisci Morales Yahoo! Research Barcelona [email protected] RGB color version - for online/web use 3D Y-Bang Logo 1 -
Web Mining Yahoo! Research Barcelona 3 RGB color version -
for online/web use 3D Y-Bang Logo -
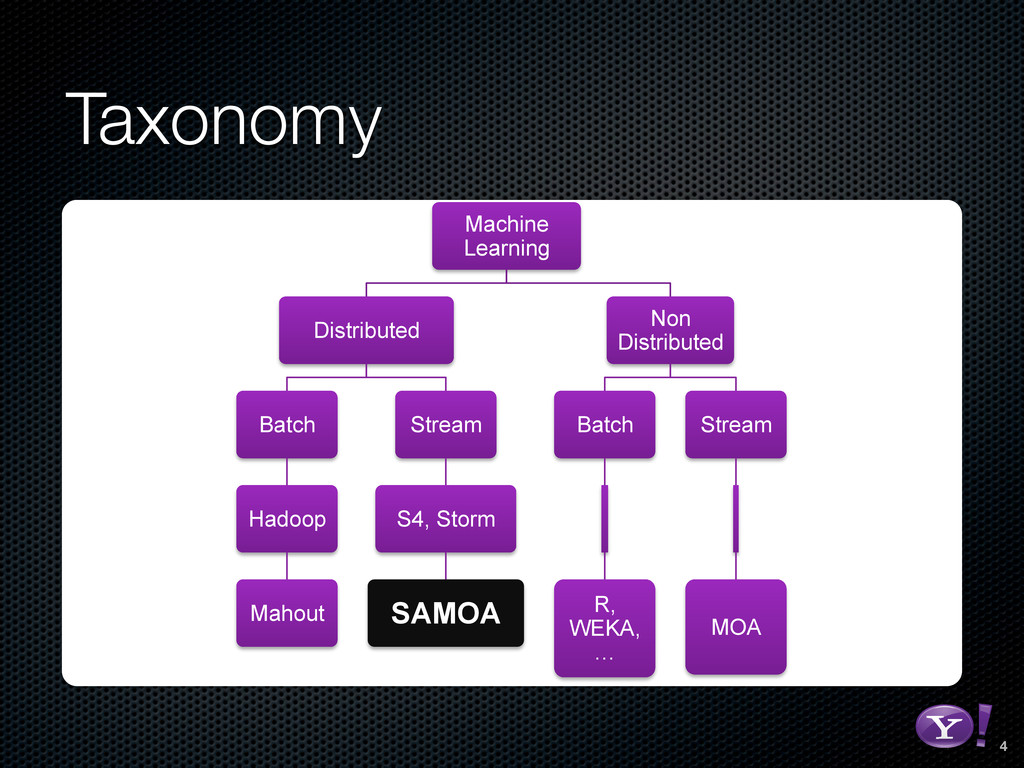
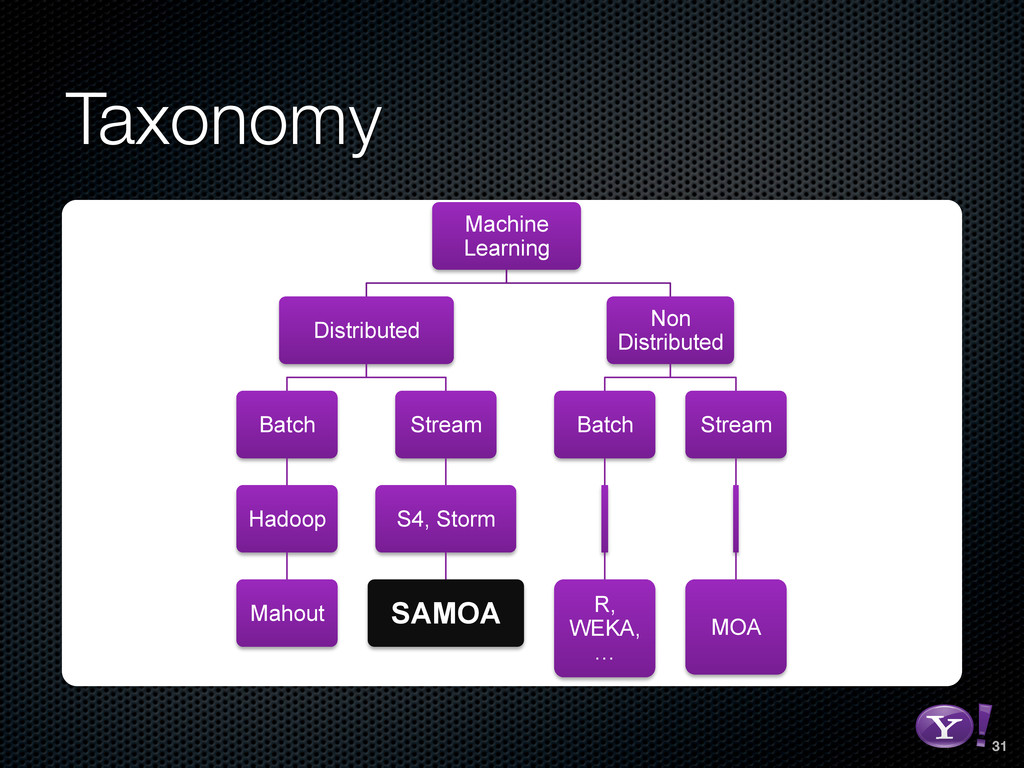
Taxonomy Machine Learning Distributed Batch Hadoop Mahout Stream S4, Storm
SAMOA Non Distributed Batch R, WEKA, … Stream MOA 4 RGB color version - for online/web use 3D Y-Bang Logo -
Agenda Stream processing engine retrospective MapReduce for stream processing SAMOA
Motivation Challenges 5 RGB color version - for online/web use 3D Y-Bang Logo -
Streaming Sequence is potentially infinite High amount of data, high
speed of arrival Change over time (concept drift) Approximation algorithms (small error with high probability) Single pass, one data item at a time Sublinear space and time per data item 6 RGB color version - for online/web use 3D Y-Bang Logo -
Big Data Volume + Velocity (+ Variety) Too large for
single commodity server main memory Too fast for single commodity server CPU A solution should be: Distributed Scalable 7 RGB color version - for online/web use 3D Y-Bang Logo -
In the beginning… …it was the Database 8 RGB color
version - for online/web use 3D Y-Bang Logo -
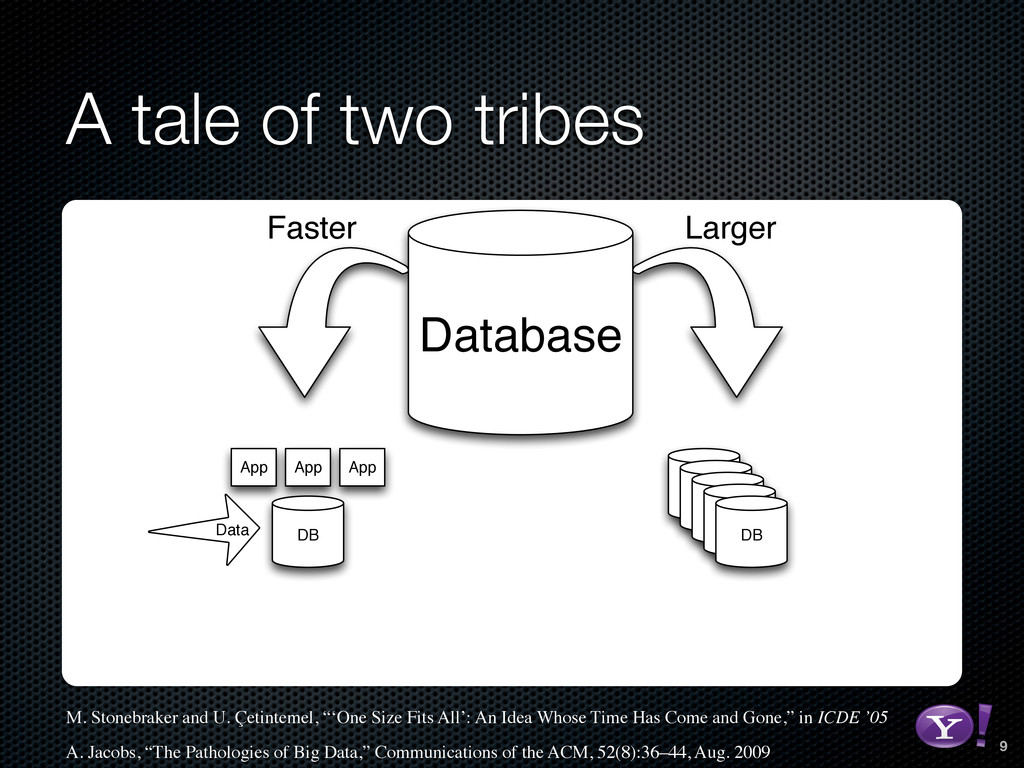
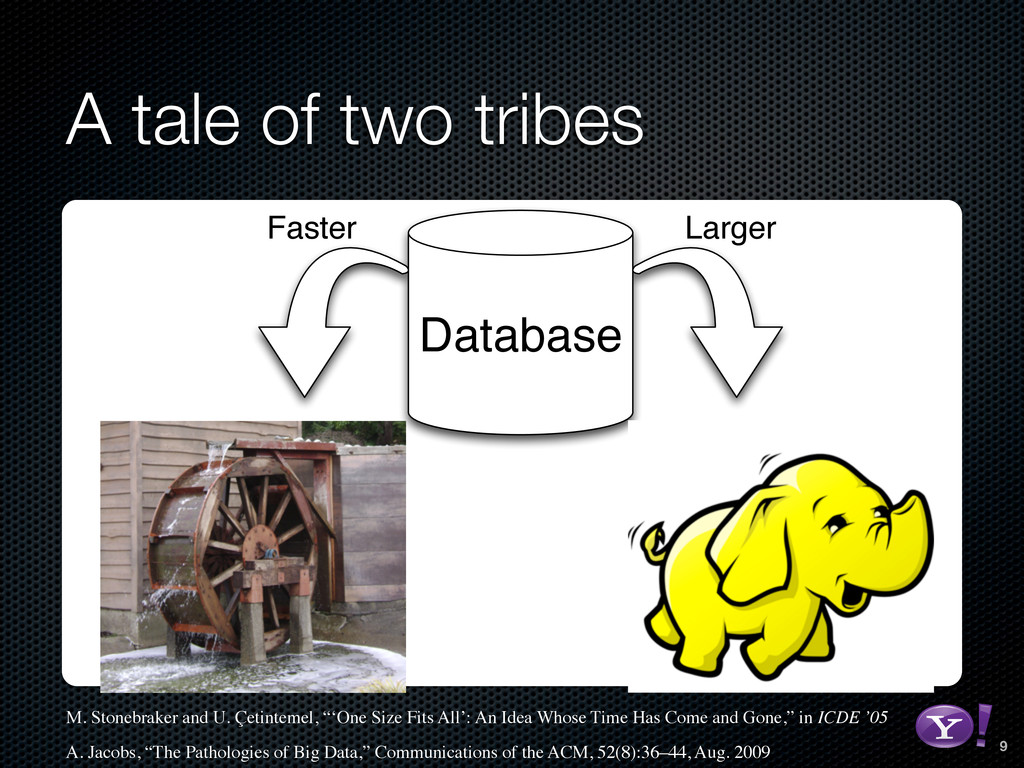
A tale of two tribes DB DB DB DB DB
DB Data App App App Faster Larger Database M. Stonebraker and U. Çetintemel, “‘One Size Fits All’: An Idea Whose Time Has Come and Gone,” in ICDE ’05 A. Jacobs, “The Pathologies of Big Data,” Communications of the ACM, 52(8):36–44, Aug. 2009 9 RGB color version - for online/web use 3D Y-Bang Logo -
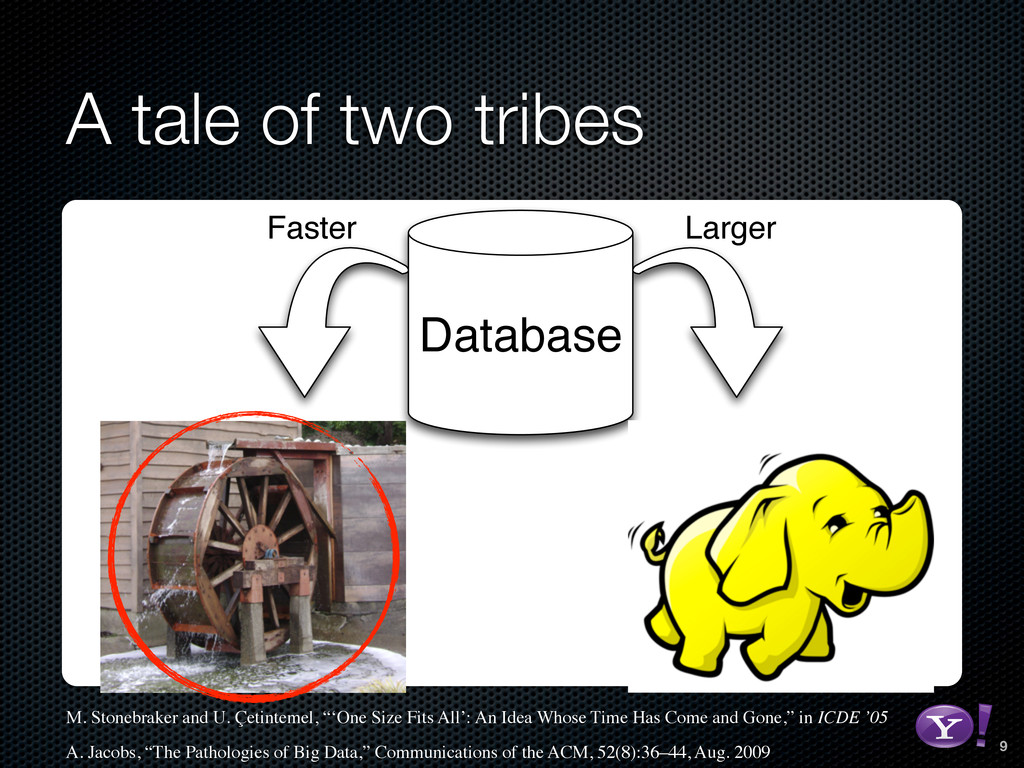
A tale of two tribes DB DB DB DB DB
DB Data App App App Faster Larger Database M. Stonebraker and U. Çetintemel, “‘One Size Fits All’: An Idea Whose Time Has Come and Gone,” in ICDE ’05 A. Jacobs, “The Pathologies of Big Data,” Communications of the ACM, 52(8):36–44, Aug. 2009 9 RGB color version - for online/web use 3D Y-Bang Logo -
A tale of two tribes DB DB DB DB DB
DB Data App App App Faster Larger Database M. Stonebraker and U. Çetintemel, “‘One Size Fits All’: An Idea Whose Time Has Come and Gone,” in ICDE ’05 A. Jacobs, “The Pathologies of Big Data,” Communications of the ACM, 52(8):36–44, Aug. 2009 9 RGB color version - for online/web use 3D Y-Bang Logo -
A tale of two tribes DB DB DB DB DB
DB Data App App App Faster Larger Database M. Stonebraker and U. Çetintemel, “‘One Size Fits All’: An Idea Whose Time Has Come and Gone,” in ICDE ’05 A. Jacobs, “The Pathologies of Big Data,” Communications of the ACM, 52(8):36–44, Aug. 2009 9 RGB color version - for online/web use 3D Y-Bang Logo -
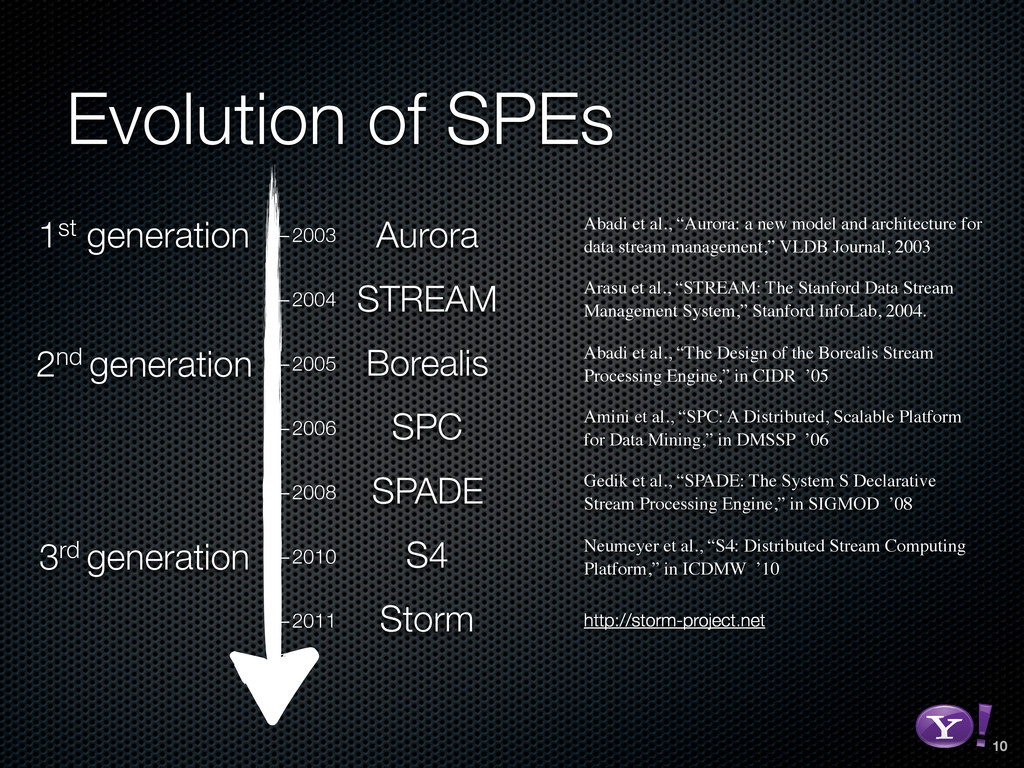
Evolution of SPEs 10 —2003 —2004 —2005 —2006 —2008 —2010
—2011 Aurora STREAM Borealis SPC SPADE Storm S4 1st generation 2nd generation 3rd generation Abadi et al., “Aurora: a new model and architecture for data stream management,” VLDB Journal, 2003 Arasu et al., “STREAM: The Stanford Data Stream Management System,” Stanford InfoLab, 2004. Abadi et al., “The Design of the Borealis Stream Processing Engine,” in CIDR ’05 Amini et al., “SPC: A Distributed, Scalable Platform for Data Mining,” in DMSSP ’06 Gedik et al., “SPADE: The System S Declarative Stream Processing Engine,” in SIGMOD ’08 Neumeyer et al., “S4: Distributed Stream Computing Platform,” in ICDMW ’10 http://storm-project.net RGB color version - for online/web use 3D Y-Bang Logo -
S4 & Storm Top-k word count example 11 RGB color
version - for online/web use 3D Y-Bang Logo -
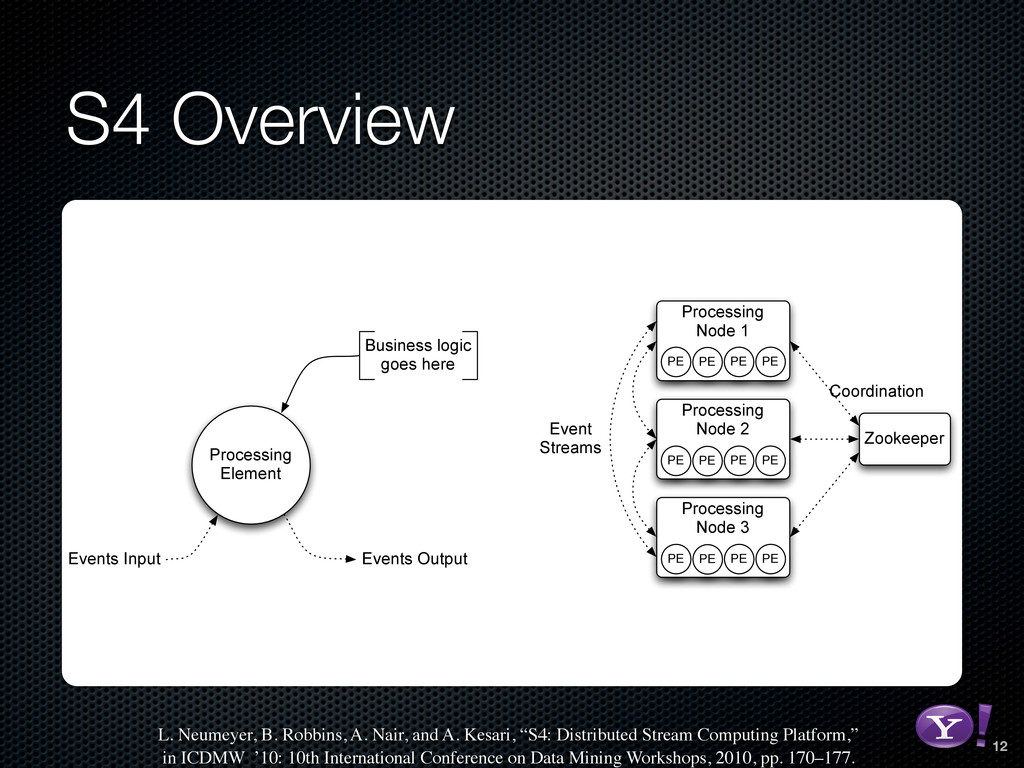
S4 Overview Processing Element Zookeeper Event Streams Coordination Events Input
Events Output Business logic goes here Processing Node 1 PE PE PE PE Processing Node 2 PE PE PE PE Processing Node 3 PE PE PE PE 12 RGB color version - for online/web use 3D Y-Bang Logo L. Neumeyer, B. Robbins, A. Nair, and A. Kesari, “S4: Distributed Stream Computing Platform,” in ICDMW ’10: 10th International Conference on Data Mining Workshops, 2010, pp. 170–177. -
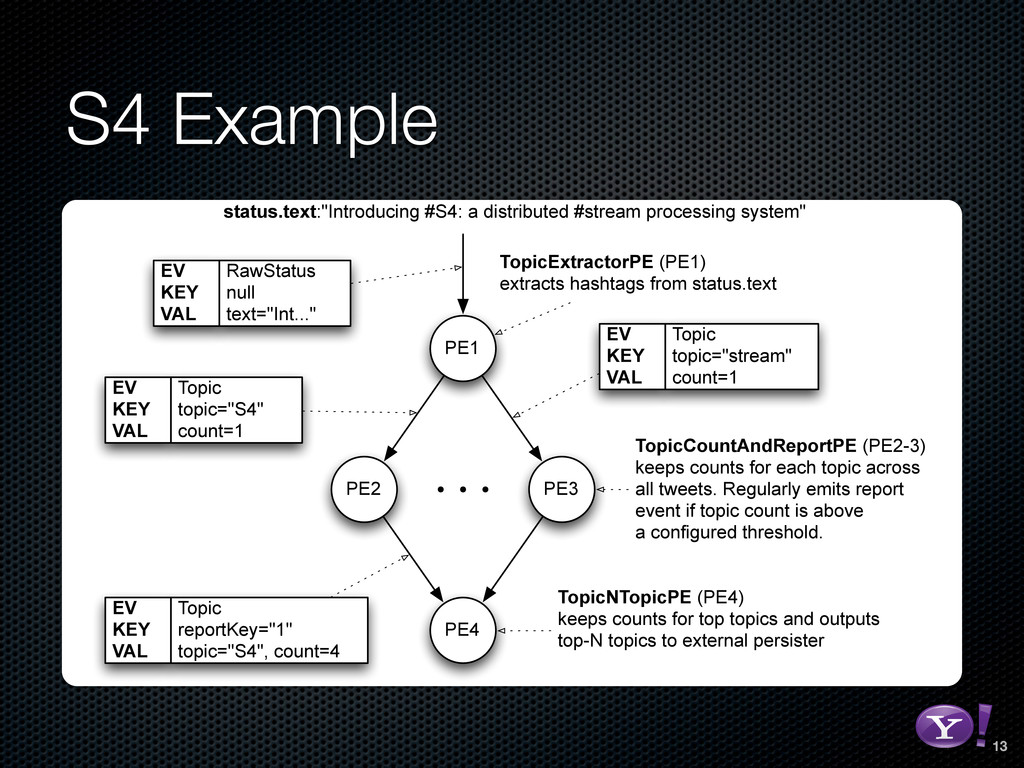
S4 Example status.text:"Introducing #S4: a distributed #stream processing system" PE1
PE2 PE3 PE4 RawStatus null text="Int..." EV KEY VAL Topic topic="S4" count=1 EV KEY VAL Topic topic="stream" count=1 EV KEY VAL Topic reportKey="1" topic="S4", count=4 EV KEY VAL TopicExtractorPE (PE1) extracts hashtags from status.text TopicCountAndReportPE (PE2-3) keeps counts for each topic across all tweets. Regularly emits report event if topic count is above a configured threshold. TopicNTopicPE (PE4) keeps counts for top topics and outputs top-N topics to external persister 13 RGB color version - for online/web use 3D Y-Bang Logo -
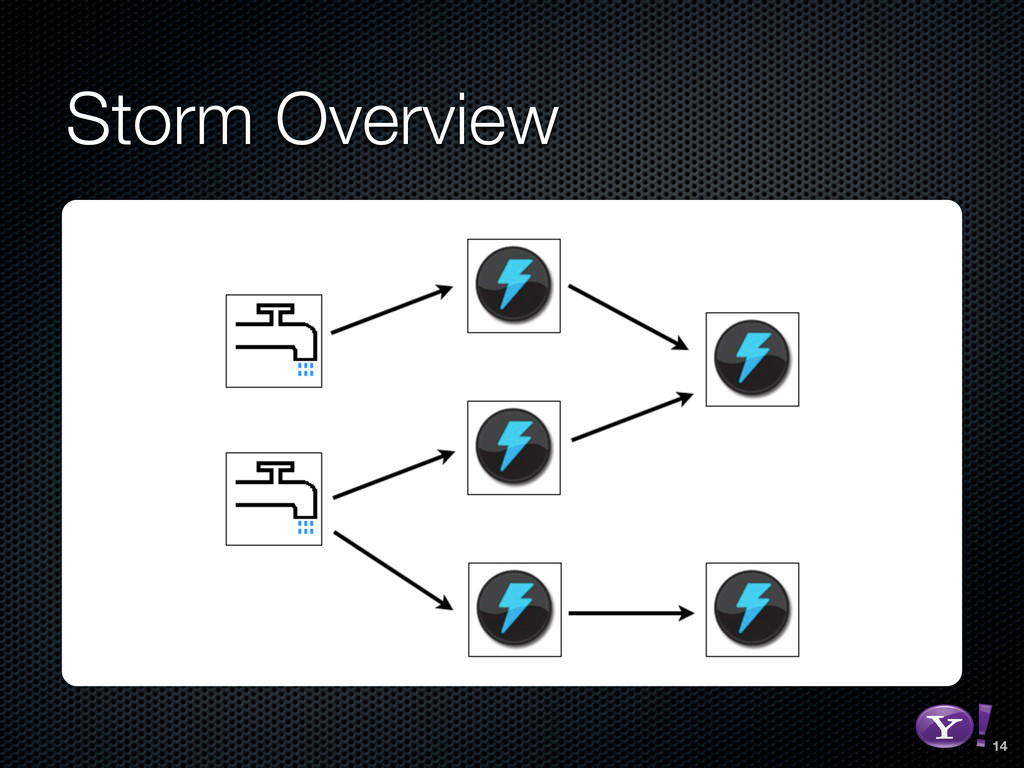
Storm Overview 14 RGB color version - for online/web use
3D Y-Bang Logo -
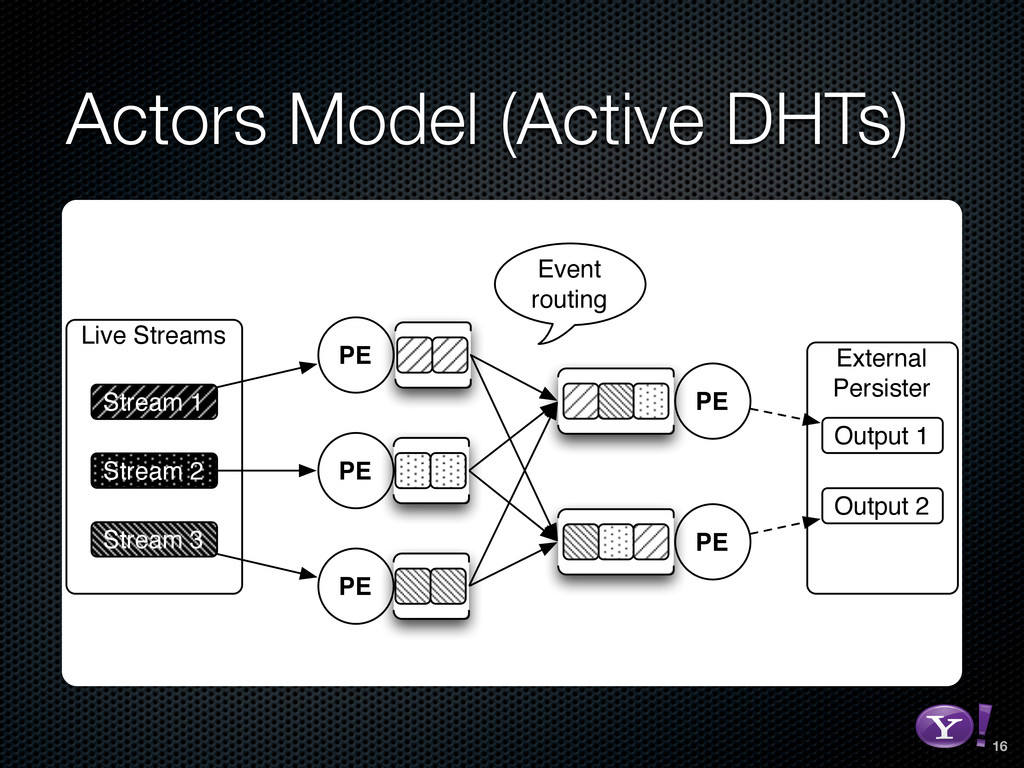
Actors Model (Active DHTs) Live Streams Stream 1 Stream 2
Stream 3 PE PE PE PE PE External Persister Output 1 Output 2 Event routing 16 RGB color version - for online/web use 3D Y-Bang Logo -
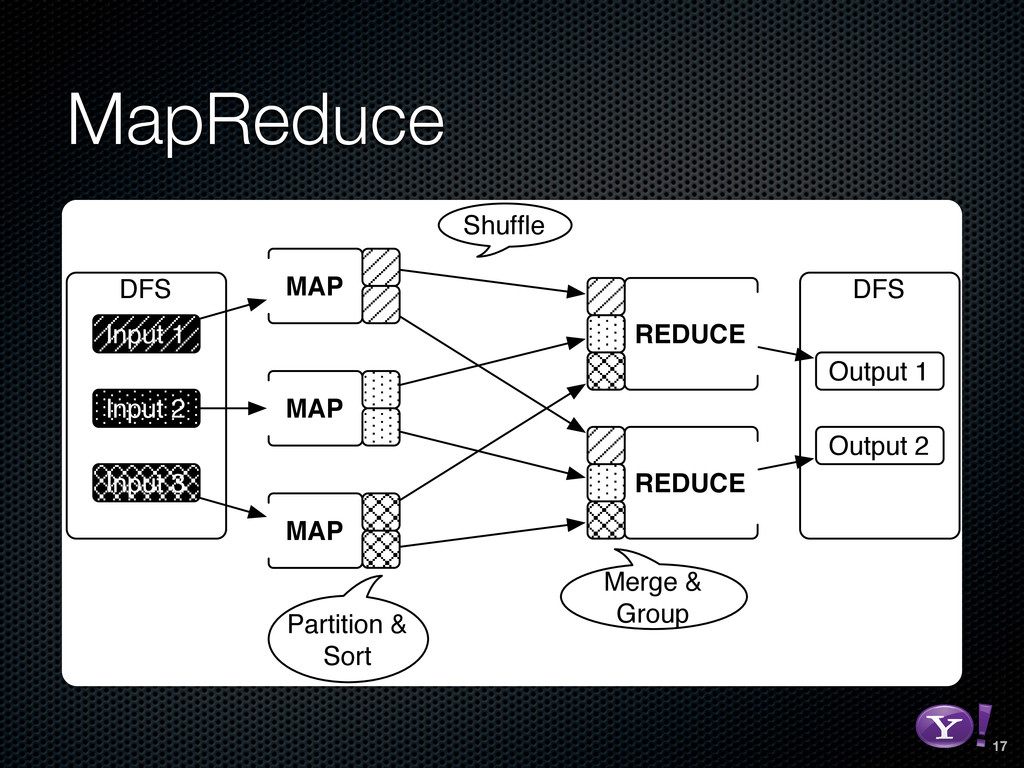
MapReduce DFS Input 1 Input 2 Input 3 MAP MAP
MAP REDUCE REDUCE DFS Output 1 Output 2 Shuffle Merge & Group Partition & Sort 17 RGB color version - for online/web use 3D Y-Bang Logo -
Shoehorning “Mapreduce is Good Enough? If All You Have is
a Hammer, Throw Away Everything That’s Not a Nail!” [J. Lin, in Big Data, 1(1):28–37, 2013] Can we reuse the MapReduce programming model for stream mining? A review of online, streaming, and incremental computation on MapReduce 18 RGB color version - for online/web use 3D Y-Bang Logo -
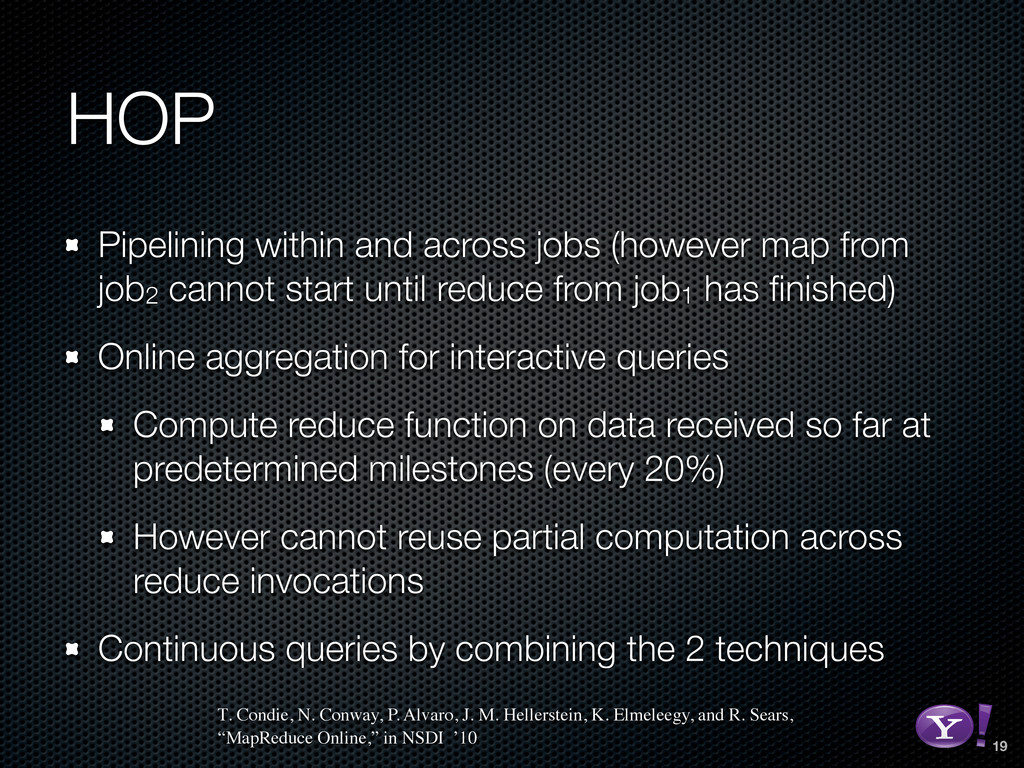
HOP Pipelining within and across jobs (however map from job2
cannot start until reduce from job1 has finished) Online aggregation for interactive queries Compute reduce function on data received so far at predetermined milestones (every 20%) However cannot reuse partial computation across reduce invocations Continuous queries by combining the 2 techniques 19 RGB color version - for online/web use 3D Y-Bang Logo T. Condie, N. Conway, P. Alvaro, J. M. Hellerstein, K. Elmeleegy, and R. Sears, “MapReduce Online,” in NSDI ’10 -
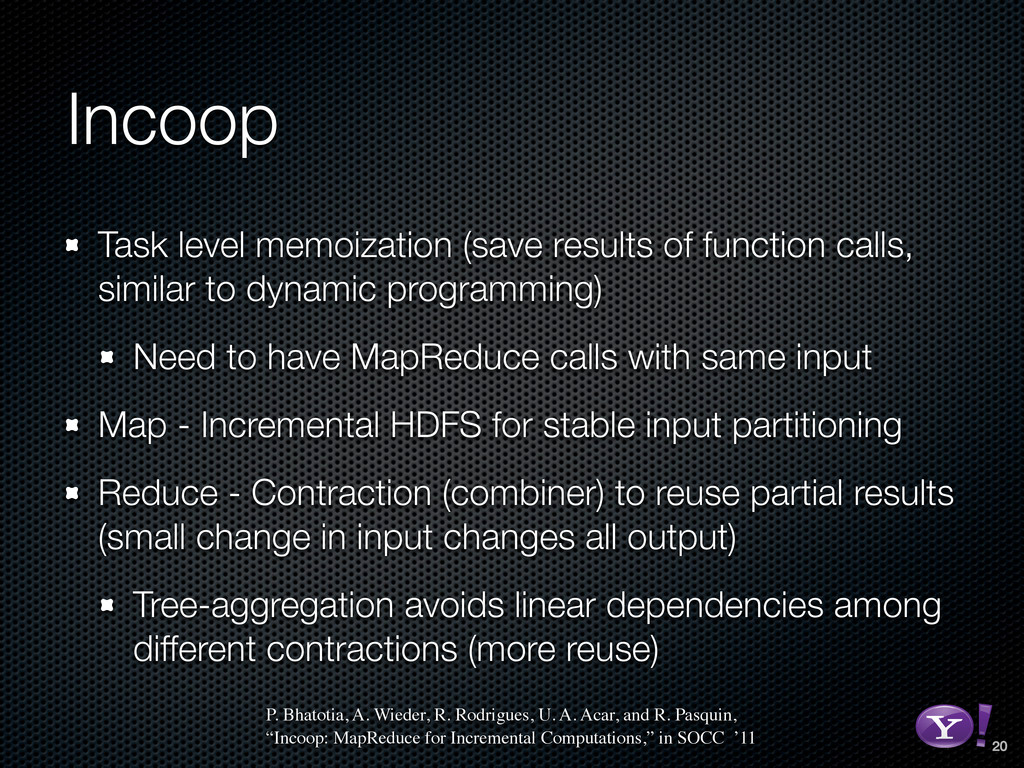
Incoop Task level memoization (save results of function calls, similar
to dynamic programming) Need to have MapReduce calls with same input Map - Incremental HDFS for stable input partitioning Reduce - Contraction (combiner) to reuse partial results (small change in input changes all output) Tree-aggregation avoids linear dependencies among different contractions (more reuse) 20 RGB color version - for online/web use 3D Y-Bang Logo P. Bhatotia, A. Wieder, R. Rodrigues, U. A. Acar, and R. Pasquin, “Incoop: MapReduce for Incremental Computations,” in SOCC ’11 -
StreamMapReduce Backward-compatible extension of MapReduce API Map = stateless function
Reduce Windowed = defined over a window (tumbling, sliding) Stateful = custom definition of state (time triggered) Actors model in disguise! 21 RGB color version - for online/web use 3D Y-Bang Logo A. Brito, A. Martin, T. Knauth, S. Creutz, D. Becker, S. Weigert, and C. Fetzer, “Scalable and Low-Latency Data Processing with Stream MapReduce,” in CloudCom ’11 -
Muppet MapUpdate = streaming version of MapReduce Map = stateless
function, Update = stateful function Slate = external memory for Update, keyed on events, lazily allocated, persisted in a KV storage Workflow is a DAG, nodes are MapUpdate functions, edges are event streams Actors model in disguise! 22 RGB color version - for online/web use 3D Y-Bang Logo W. Lam, L. Liu, S. Prasad, A. Rajaraman, Z. Vacheri, and A. Doan, “Muppet: MapReduce-Style Processing of Fast Data,” VLDB 5(12):1814–1825, 2012. -
MapReduce for streams? Can be done, but most approaches reinvent
the actors model 3rd gen SPEs are the natural choice Need to rethink algorithms :( Opportunities for new algorithms :) 23 RGB color version - for online/web use 3D Y-Bang Logo -
SAMOA Scalable Advanced Massive Online Analysis Albert Bifet Gianmarco De
Francisci Morales Nicolas Kourtellis Matthieu Morel Arinto Murdopo Antonio Severien 24 RGB color version - for online/web use 3D Y-Bang Logo -
Motivation Big Data + Streaming What is happening now? Use
feedback in real-time Update models faster: from weeks to seconds Adapt to changes, concept drift Resist adversarial interactions 25 RGB color version - for online/web use 3D Y-Bang Logo -
Importance$of$O • As$spam$trends$change retrain$the$model$with Importance Spam detection in comments on
Yahoo! News Trends change in time Need to retrain model with new data 26 RGB color version - for online/web use 3D Y-Bang Logo -
Is SAMOA useful for you? Only if you need to
deal with: Big fast data Evolving data (model updates) Concept drift: discriminative features or class distribution change Example: Twitter spam detection. Hashtags and their co-occurrences change dramatically and very fast over time 27 RGB color version - for online/web use 3D Y-Bang Logo -
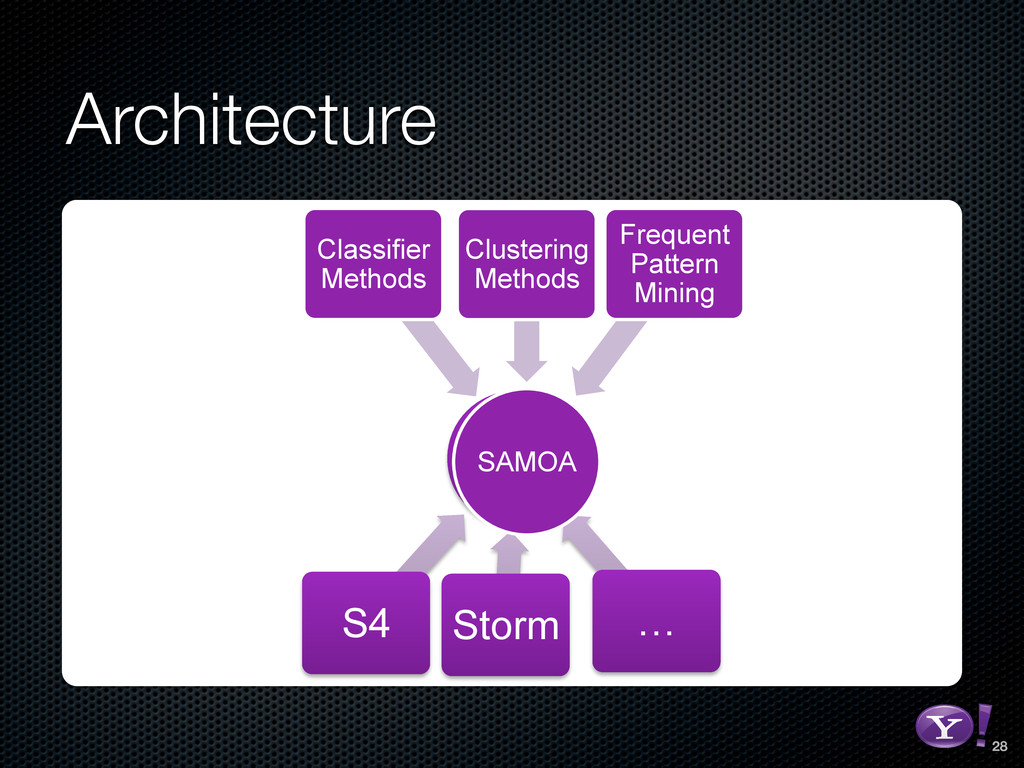
Architecture SAMOA S4 Storm … SAMOA Classifier Methods Clustering Methods
Frequent Pattern Mining 28 RGB color version - for online/web use 3D Y-Bang Logo -
Advantages Program once, run everywhere Reuse existing computational infrastructure Model
is always up to date No system downtime No complex backup/update procedures No need to choose update frequency 29 RGB color version - for online/web use 3D Y-Bang Logo -
What about Mahout? Think SAMOA = Mahout for streaming But
SAMOA… More than JBoA (just a bunch of algorithms) Provides a common platform Easy to port to new computing engines 30 RGB color version - for online/web use 3D Y-Bang Logo -
Taxonomy Machine Learning Distributed Batch Hadoop Mahout Stream S4, Storm
SAMOA Non Distributed Batch R, WEKA, … Stream MOA 31 RGB color version - for online/web use 3D Y-Bang Logo -
Short-Term Goals Parallel algorithms Hoeffding tree K-means-based clustering Gradient Boosted
Decision Trees Platforms: S4 & Storm First release in July 32 RGB color version - for online/web use 3D Y-Bang Logo -
Long-Term Goals Easy to integrate add-ons with packages (like R)
Most common algorithms implemented (like Mahout) Large community in industry & academia (like Hadoop) Become reference platform for big data stream mining (like Weka) Lively open-source project (Apache Incubator) 33 RGB color version - for online/web use 3D Y-Bang Logo -
Challenges Algorithmic Platform design Implementation 34 RGB color version -
for online/web use 3D Y-Bang Logo -
Algorithmic Case study: Hoeffding tree What kind of parallelism? Task
Data Horizontal Vertical 35 RGB color version - for online/web use 3D Y-Bang Logo -
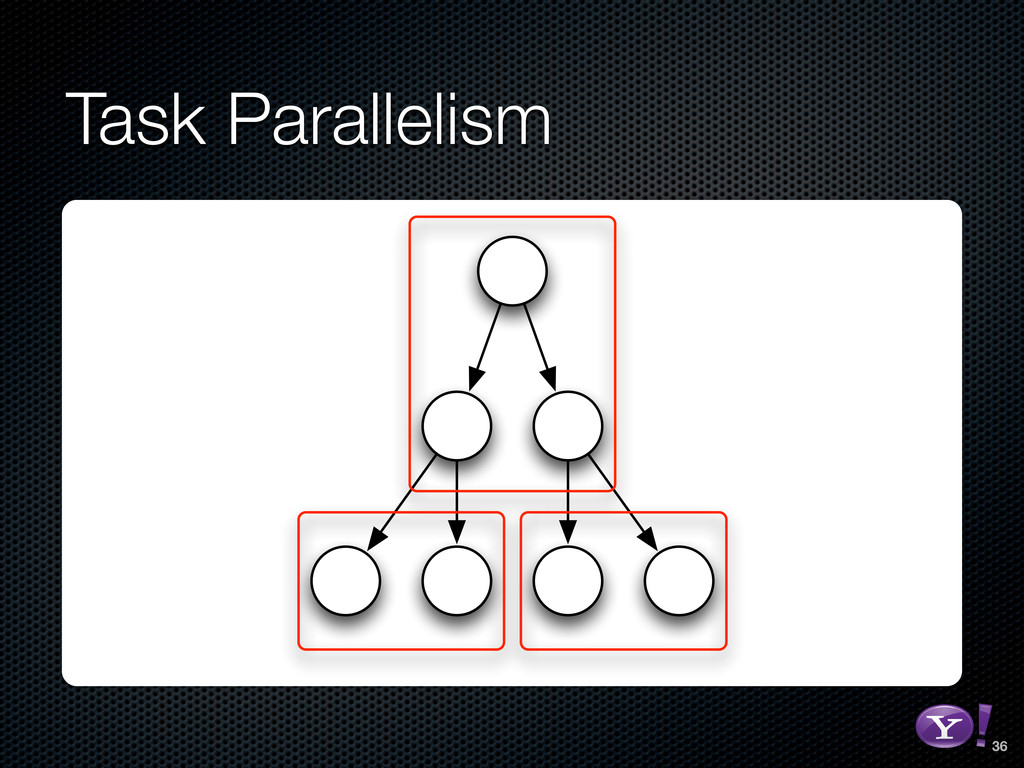
Task Parallelism 36 RGB color version - for online/web use
3D Y-Bang Logo -
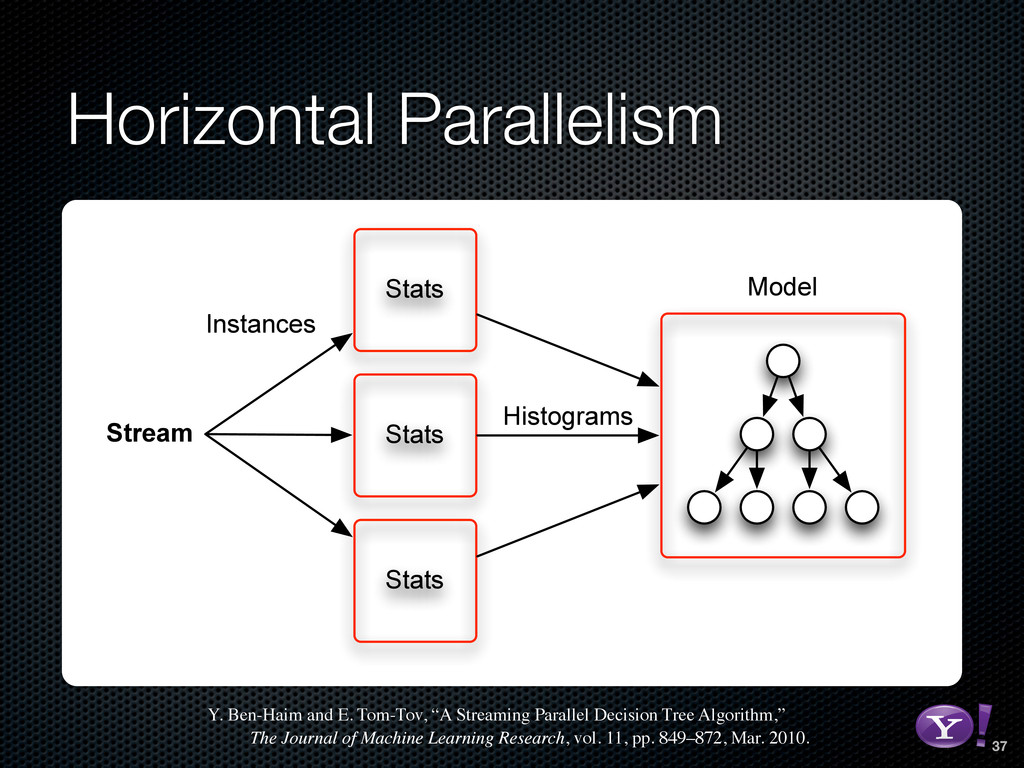
Horizontal Parallelism Stats Stats Stats Stream Histograms Model Instances Y.
Ben-Haim and E. Tom-Tov, “A Streaming Parallel Decision Tree Algorithm,” The Journal of Machine Learning Research, vol. 11, pp. 849–872, Mar. 2010. 37 RGB color version - for online/web use 3D Y-Bang Logo -
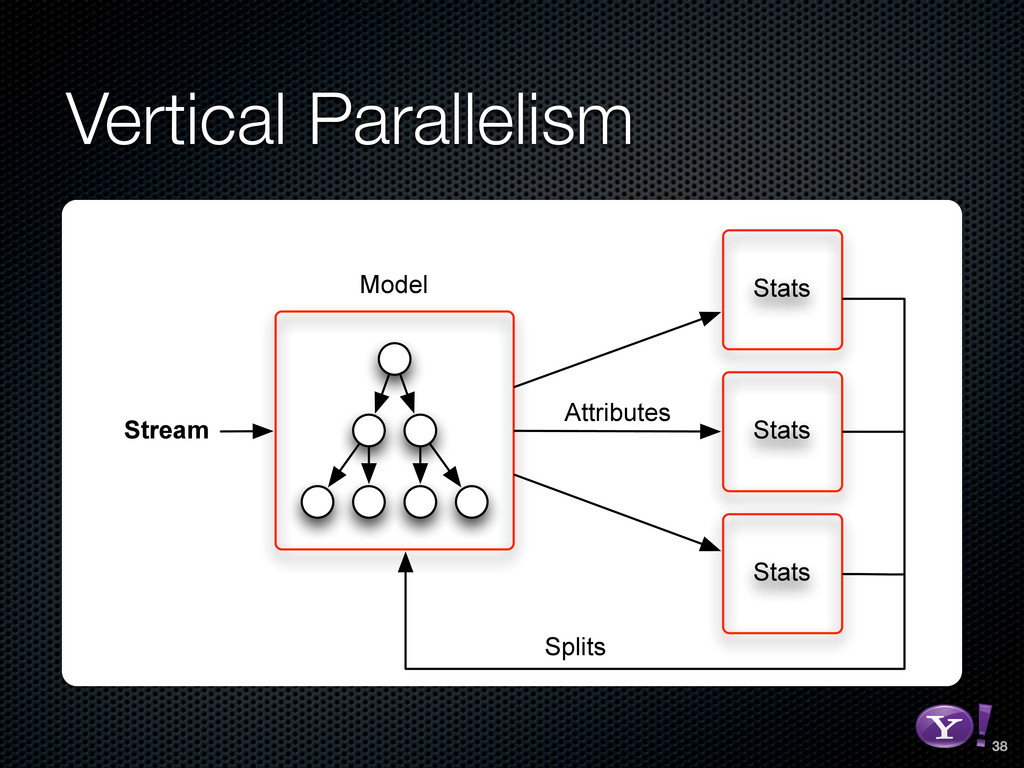
Vertical Parallelism Stats Stats Stats Stream Model Attributes Splits 38
RGB color version - for online/web use 3D Y-Bang Logo -
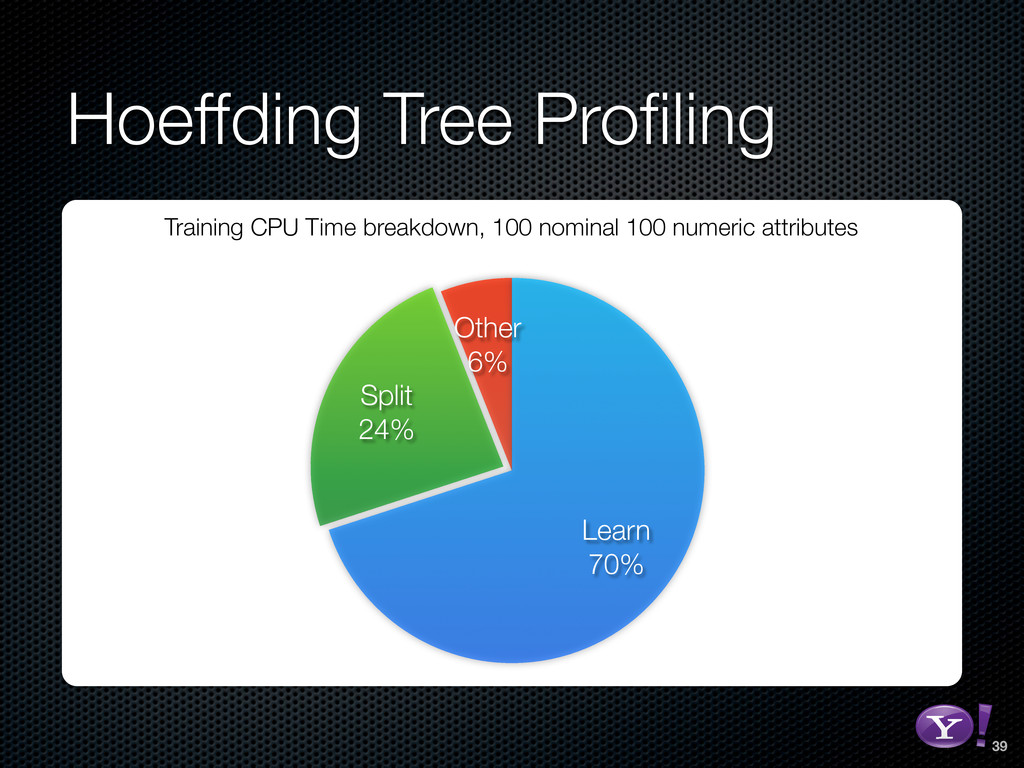
Other 6% Split 24% Learn 70% Training CPU Time breakdown,
100 nominal 100 numeric attributes Hoeffding Tree Profiling 39 RGB color version - for online/web use 3D Y-Bang Logo -
Vertical Parallelism High number of attributes (e.g., documents) results in
high level of parallelism Parallelism is observed immediately (compared to task parallelism) Localized failure handling and model updates (model is kept in one node) Less memory usage compared to horizontal partitioning (no model replication) 40 RGB color version - for online/web use 3D Y-Bang Logo -
Platform Design What is the right level of abstraction? Application
building Computation Communication 41 RGB color version - for online/web use 3D Y-Bang Logo -
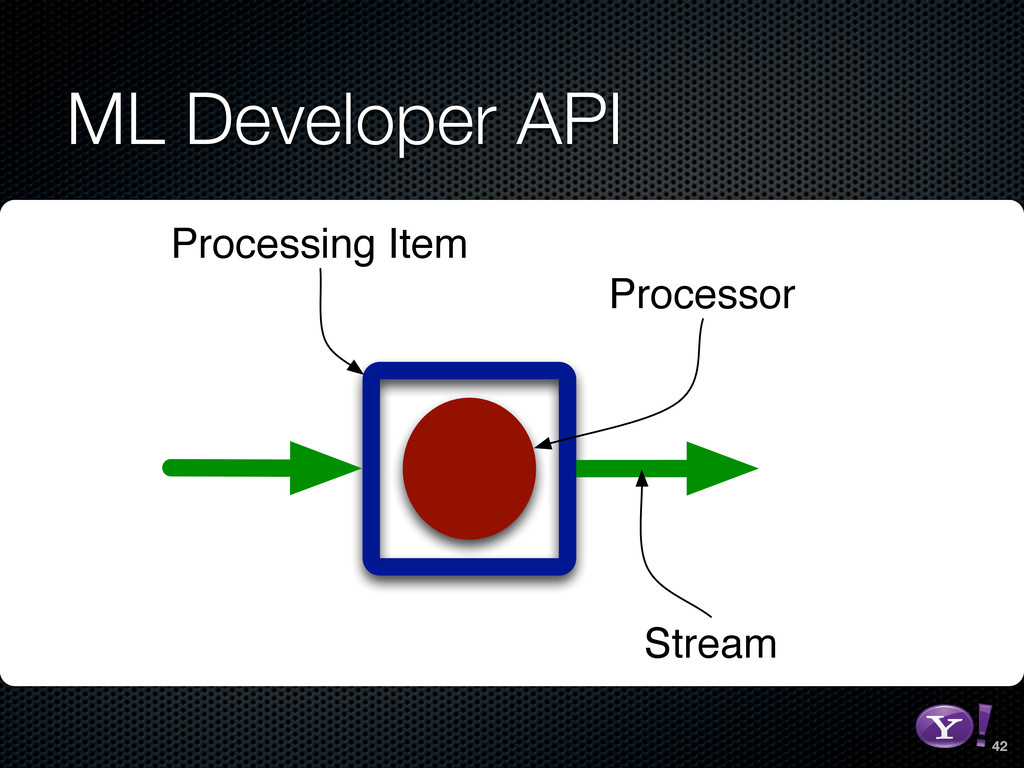
ML Developer API 42 RGB color version - for online/web
use 3D Y-Bang Logo Processing Item Processor Stream -
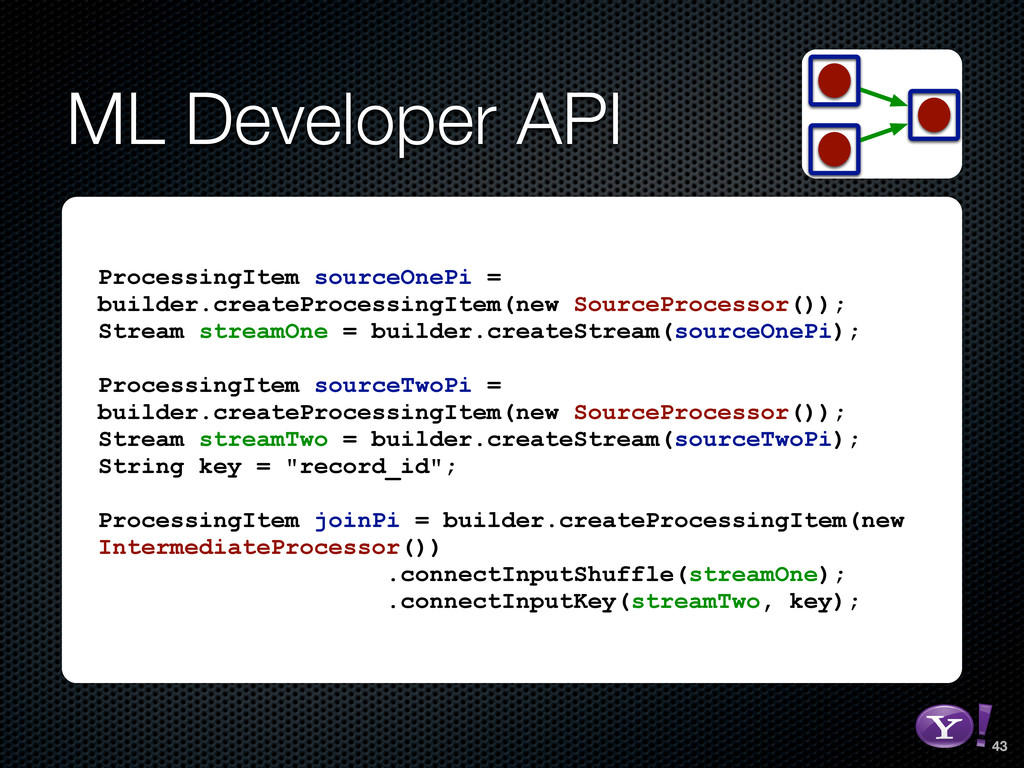
ML Developer API ProcessingItem sourceOnePi = builder.createProcessingItem(new SourceProcessor()); Stream streamOne
= builder.createStream(sourceOnePi); ProcessingItem sourceTwoPi = builder.createProcessingItem(new SourceProcessor()); Stream streamTwo = builder.createStream(sourceTwoPi); String key = "record_id"; ProcessingItem joinPi = builder.createProcessingItem(new IntermediateProcessor()) .connectInputShuffle(streamOne); .connectInputKey(streamTwo, key); 43 RGB color version - for online/web use 3D Y-Bang Logo -
Implementation How to hide platform differences? Deployment Runtime How to
isolate platform-related code? Build and release architecture 44 RGB color version - for online/web use 3D Y-Bang Logo -
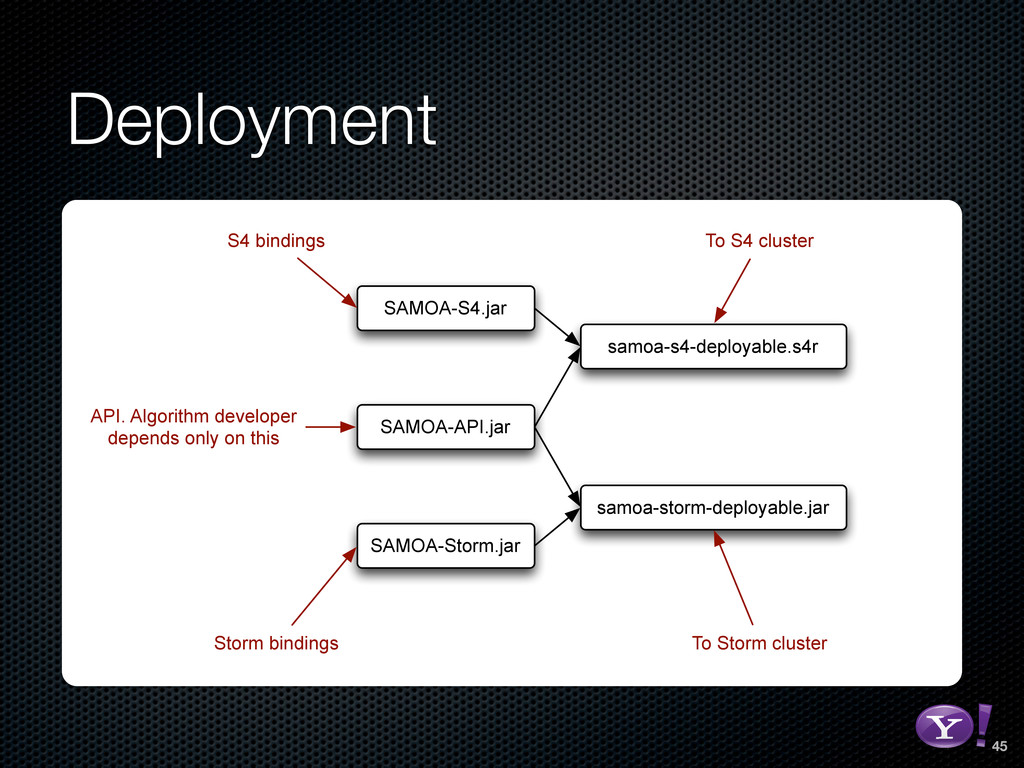
Deployment SAMOA-S4.jar SAMOA-API.jar SAMOA-Storm.jar samoa-storm-deployable.jar samoa-s4-deployable.s4r S4 bindings Storm bindings
API. Algorithm developer depends only on this To S4 cluster To Storm cluster 45 RGB color version - for online/web use 3D Y-Bang Logo -
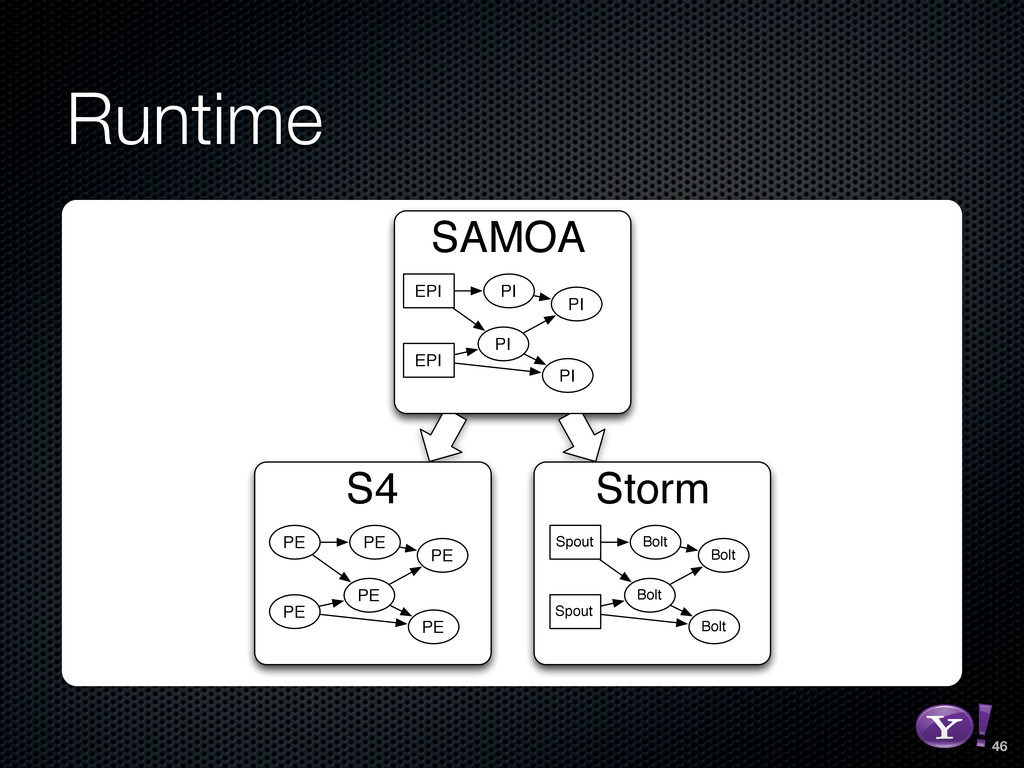
Runtime 46 RGB color version - for online/web use 3D
Y-Bang Logo SAMOA EPI EPI PI PI PI PI S4 PE PE PE PE PE PE Storm Spout Spout Bolt Bolt Bolt Bolt -
Conclusions SAMOA: A Platform for Mining Big Data Streams Runs
on existing distributed stream processing engines Parallel algorithms for machine learning on streams Pluggable architecture, flexible, extensible, open source Available soon! 47 RGB color version - for online/web use 3D Y-Bang Logo -
References [1] D. J. Abadi, D. Carney, U. Cetintemel, M.
Cherniack, C. Convey, S. Lee, M. Stonebraker, N. Tatbul, and S. Zdonik, “Aurora: a new model and architecture for data stream management,” VLDB Journal, vol. 12, no. 2, pp. 120–139, Aug. 2003. [2] A. Bifet, G. Holmes, R. Kirkby, and B. Pfahringer, “MOA: Massive Online Analysis,” The Journal of Machine Learning Research, vol. 11, pp. 1601–1604, 2010. [3] Gartner, “Gartner Says Solving ‘Big Data’ Challenge Involves More Than Just Managing Volumes of Data,” 2011. [Online]. Available: http://www.gartner.com/it/page.jsp?id=1731916. [4] B. Gedik, H. Andrade, K.-L. Wu, P. S. Yu, and M. Doo, “SPADE: The System S Declarative Stream Processing Engine,” in SIGMOD ’08: 34th International Conference on Management of Data, 2008, pp. 1123– 1134. [5] V. Kumar, H. Andrade, B. Gedik, and K.-L. Wu, “DEDUCE: At the Intersection of MapReduce and Stream Processing,” in EDBT ’10: 13th International Conference on Extending Database Technology, 2010, pp. 657– 662. [6] C. Olston, S. Seth, C. Tian, T. ZiCornell, X. Wang, G. Chiou, L. Chitnis, F. Liu, Y. Han, M. Larsson, A. Neumann, V. B. N. Rao, and V. Sankarasubramanian, “Nova: Continuous Pig/Hadoop Workflows,” in SIGMOD ’11: 37th International Conference on Management of Data, 2011, pp. 1081–1090. [7] L. Neumeyer, B. Robbins, A. Nair, and A. Kesari, “S4: Distributed Stream Computing Platform,” in ICDMW ’10: 10th International Conference on Data Mining Workshops, 2010, pp. 170–177. 49 -
[8] D. J. Abadi, Y. Ahmad, M. Balazinska, M. Cherniack,
J. Hwang, W. Lindner, A. S. Maskey, E. Rasin, E. Ryvkina, N. Tatbul, Y. Xing, and S. Zdonik, “The Design of the Borealis Stream Processing Engine,” in CIDR ’05: 1st Conference on Innovative Data Systems Research, 2005, pp. 277–289. [9] L. Amini, H. Andrade, R. Bhagwan, F. Eskesen, R. King, P. Selo, Y. Park, and C. Venkatramani, “SPC: A Distributed, Scalable Platform for Data Mining,” in DMSSP ’06: 4th international Workshop on Data Mining Standards, Services and Platforms, 2006, pp. 27–37. [10] A. Arasu, B. Babcock, S. Babu, J. Cieslewicz, M. Datar, K. Ito, R. Motwani, U. Srivastava, and J. Widom, “STREAM: The Stanford Data Stream Management System,” Stanford InfoLab, 2004. [11] P. Bhatotia, A. Wieder, R. Rodrigues, U. A. Acar, and R. Pasquin, “Incoop: MapReduce for Incremental Computations,” in SOCC ’11: 2nd ACM Symposium on Cloud Computing, 2011, pp. 1–14. [12] A. Brito, A. Martin, T. Knauth, S. Creutz, D. Becker, S. Weigert, and C. Fetzer, “Scalable and Low-Latency Data Processing with Stream MapReduce,” in CloudCom ’11: 3rd International Conference on Cloud Computing Technology and Science, 2011, pp. 48–58. [13] Y. Bu, B. Howe, M. Balazinska, and M. D. Ernst, “HaLoop: efficient iterative data processing on large clusters,” VLDB Endowment, vol. 3, no. 1–2, pp. 285–296, Sep. 2010. [14] T. Condie, N. Conway, P. Alvaro, J. M. Hellerstein, K. Elmeleegy, and R. Sears, “MapReduce Online,” in NSDI ’10: 7th Conference on Networked Systems Design and Implementation, 2010, p. 21. [15] J. Dean and S. Ghemawat, “MapReduce: Simplified Data processing on Large Clusters,” in OSDI ’04: 6th Symposium on Opearting Systems Design and Implementation, 2004, pp. 137–150. 50 References -
51 References [16] J. Feldman, S. Muthukrishnan, A. Sidiropoulos, C.
Stein, and Z. Svitkina, “On distributing symmetric streaming computations,” ACM Transactions on Algorithms, vol. 6, no. 4, pp. 1–19, 2010. [17] M. Hall, E. Frank, G. Holmes, B. Pfahringer, P. Reutemann, and I. H. Witten, “The WEKA data mining software,” SIGKDD Explorations, vol. 11, no. 1, p. 10, 2009. [18] J. Lin, “Mapreduce is Good Enough? If All You Have is a Hammer, Throw Away Everything That’s Not a Nail!,” Big Data, vol. 1, no. 1, pp. 28–37, Mar. 2013. [19] J. Rosen, N. Polyzotis, V. Borkar, Y. Bu, M. J. Carey, M. Weimer, T. Condie, and R. Ramakrishnan, “Iterative MapReduce for Large Scale Machine Learning,” Arxiv, Mar. 2013. [20] M. Zaharia, T. Das, H. Li, S. Shenker, and I. Stoica, “Discretized Streams: an Efficient and Fault-Tolerant Model for Stream Processing on Large Clusters,” in HotCloud ’12: 4th Conference on Hot Topics in Cloud Ccomputing, 2012, p. 10. [21] M. Stonebraker, U. Çetintemel, and S. Zdonik, “The 8 requirements of real-time stream processing,” ACM SIGMOD Record, vol. 34, no. 4, pp. 42–47, Dec. 2005. [22] W. Lam, L. Liu, S. Prasad, A. Rajaraman, Z. Vacheri, and A. Doan, “Muppet: MapReduce-Style Processing of Fast Data,” VLDB Endowment, vol. 5, no. 12, pp. 1814–1825, Aug. 2012.
 gdfm
 tattaka
 satai
 taniai
 ept
 sishi
 masao
 resolutionfoundation
 tosseto
 pman0214
 takehaya
 kzmssk
 ayatokanada
 jonyablonski
 bkeepers
 rocio
 brettharned
 thekraken
 malarkey
 reverentgeek
 bcantrill
 tamaranovitovic
 szymonslowik
 inesmontani
 shlominoach