Share
Embed
Transcript
85 slides
-
+Kazunori Sato @kazunori_279 Kaz Sato Staff Developer Advocate Data &
Analytics Google Cloud -
Agenda What is TPU? domain specific architecture for deep learning
TPU Pod HPC-powered scalable "All Reduce" distributed training Cloud TPU Programming with TensorFlow Estimator API and TensorBoard -
TPU public resources Cloud TPU Documentation Effective machine learning using
Cloud TPUs by Zak Stone (Google I/O '18 video) Training Performance: A user’s guide to converge faster by Brennan Saeta (TensorFlow Dev Summit 2018 video) In-Datacenter Performance Analysis of a Tensor Processing Unit by Norm Jouppi et al. (paper) An in-depth look at Google’s first Tensor Processing Unit by Kaz Sato, Cliff Young and David Patterson (blog post) The future of computing by John Hennessy (Google I/O '18 video) -
Based on SPECintCPU. Source: John Hennessy and David Patterson, Computer
Architecture: A Quantitative Approach, 6/e. 2018 End of the Line? 2X / 20 yrs (3%/yr) RISC 2X / 1.5 yrs (52%/yr) CISC 2X / 3.5 yrs (22%/yr) End of Dennard Scaling ⇒ Multicore 2X / 3.5 yrs (23%/yr) Am- dahl’s Law ⇒ 2X / 6 yrs (12%/yr) End of Growth of Single Program Speed? -
Example: hardware acceleration in BigQuery Why BQ's so fast? because:
hardware acceleration + MPP (massively parallel processing) -
TPU history: Designing a domain specific hardware for ML Early
discussion started in 2006 Production project started in 2013 (...after 15 months…) The first deployment in 2015 -
TPU v1 and v2 TPU v1 Launched in 2015 Inference
only TPU v2 Launched in 2017 Inference and training -
14 ASIC (28nm process) Clock: 700MHz Power consumption: 40W Size:
SATA disk drive slot Bus: PCIe Gen3 x16 (12.5GB/s sustained) TPU v1 Overview -
TPU v1: in production since 2015 Search Search ranking Speech
recognition Translate Text, graphic and speech translation Photos Photos search -
TPU v1 Performance comparison with Intel Haswell CPU and NVIDIA
K80 GPU Performance: 15 - 30x Performance per watt: 30 - 80x -
17 Domain specific architecture for Deep Learning Reduced precision Matrix
Processor Minimal and deterministic design Why TPU v1 was so successful? -
TPU v1 workloads in Google Type of network # of
network layers # of weights % of deployed MLP0 5 20M 61% MLP1 4 5M LSTM0 58 52M 29% LSTM1 56 34M CNN0 16 8M 5% CNN1 89 100M as of June 2016 -
Reducing precision max min ↓ -3.4E+38 +3.4E+38 ↑ 32 bit
float 8 bit int Common practice: Inference: 8 bit int quantization Training: 16 bit fp truncation -
22 DType • DT_QINT8 • DT_QINT32 • DT_QUINT8 Quantize/Dequantize •
tf.quantize_v2 • tf.dequantize Operations • matmul • Conv/Pool • Activation Quantization in TensorFlow -
Quantized = 25x more multipliers Tesla K80: 2,496 x 32
bit FP multipliers TPU v1: 65,536 x 8 bit Integer multipliers -
How CPU and GPU work CPU GPU (NVIDIA P100: 3,584
CUDA Cores) -
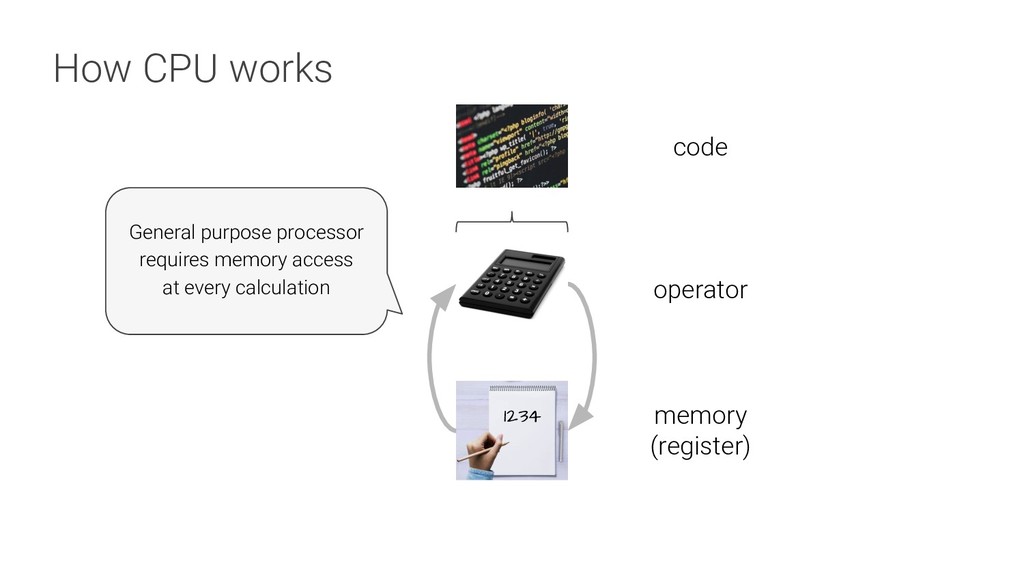
1234 How CPU works code operator memory (register) General purpose
processor requires memory access at every calculation -
How TPU works 1234 1234 Specialized for matrix operations with
significantly less memory access More operators with smaller footprint and less power -
The core of TPU: Systolic Array Large hard-wired matrix calculation
without memory access -
TPU v1: a matrix processor for neural network prediction Matrix
Multiplier Unit (MXU) • 65,536 x 8-bit multiply-and-add Unified Buffer • 24MB SRAM Activation Unit • Hardwired activation functions -
Matrix Multiply Unit (MXU): a BIG systolic array Up to
256K ops / cycle Up to 256M ops / instruction Operations per cycle CPU a few CPU (vector extension) tens GPU tens of thousands TPU hundreds of thousands, up to 256K -
TPU v1 Instruction Set and software stack Instruction Function Read_Host_Memory
Read data from memory Read_Weights Read weights from memory MatrixMultiply/ Convolve Multiply or Convolve, Accumulate the results Activate Apply activation functions Write_Host_Memory Write result to memory -
37 TPU v1: minimal design for neural network Control logic:
only 2% Removing all complexities: caching, branch prediction, OOO, multi-processing/threading, context switching etc Guaranteed latency: 7ms with high thruput -
2nd generation Tensor Processing Unit ASIC for NN calculation Training
& Inference 180 Tflops / Cloud TPU NVIDIA V100: 128 Tflops -
Confidential & Proprietary Vector Unit Scalar Unit Matrix Unit (MXU)
Matrix Unit (MXU) 8GB HBM 8GB HBM Vector Unit Scalar Unit TPU v2 processor layout -
Confidential & Proprietary Vector Unit Scalar Unit Matrix Unit (MXU)
Matrix Unit (MXU) 8GB HBM 8GB HBM Vector Unit Scalar Unit TPU v2 "Tensor Core" 2 cores per processor Matrix Unit Scalar Unit Vector Unit -
Confidential & Proprietary Vector Unit Scalar Unit Matrix Unit (MXU)
Matrix Unit (MXU) 8GB HBM Vector Unit Scalar Unit TPU v2 MXU Matrix Unit (MXU) 128 x 128 systolic array bfloat16 multiplies float32 accumulate 8GB HBM -
Floating Point Formats in TPU M M M M M
M M M M M M M M M M M M M M M M M M S E E E E E E E E Exponent: 8 bits Mantissa (Significand): 23 bits fp32: Single-precision IEEE Floating Point Format Range: ~1e−38 to ~3e38 S E E E E E M M M M M M M M M M Exponent: 5 bits Mantissa (Significand): 10 bits fp16: Half-precision IEEE Floating Point Format Range: ~5.96e−8 to 65504 Less bandwidth, Larger model, but shorter range -
M M M M M M M M M M
M M M M M M M M M M M M M S E E E E E E E E Exponent: 8 bits Mantissa (Significand): 23 bits fp32: Single-precision IEEE Floating Point Format Range: ~1e−38 to ~3e38 S E E E E E M M M M M M M M M M Exponent: 5 bits Mantissa (Significand): 10 bits fp16: Half-precision IEEE Floating Point Format Range: ~5.96e−8 to 65504 bfloat16: Brain Floating Point Format S E E E E E E E E Exponent: 8 bits Mantissa (Significand): 7 bits M M M M M M M Range: ~1e−38 to ~3e38 Supported by TPU Same range as fp32 Floating Point Formats in TPU -
Cloud TPU Performance AmoebaNet-D Final accuracy: 93% Training time: 7.5
Hrs Training cost: $49 #1 training cost on DAWNBench as of Apr 2018 -
Cloud TPU Performance Tuned ResNet-50 on Preemptible TPU Final accuracy:
93% Training cost: $7.5 1/10 of the #1 training cost by GPU on DAWNBench as of June 2018 -
Using Cloud TPUs instead of clusters of other accelerators has
allowed us to focus on building our models without being distracted by the need to manage the complexity of cluster communication patterns. “ Alfred Spector, CTO, Two Sigma Anantha Kancherla, Head of Software, Self-Driving Level 5, Lyft Since working with Google Cloud TPUs, we’ve been extremely impressed with their speed—what could normally take days can now take hours. -
HPC technology is the key for scalable ML eg NVIDIA
DGX-2: 16 x V100 at $400K, 2 PFLOPS -
TPU v2 Pod: Google's HPC cluster for ML 11.6 PFLOPS
with 64 Cloud TPUs -
Parameter Server v. All Reduce Parameter Server Model Replicas Data
Shards w’ = w - n Δ w w Δw Model Replicas Data Shards Δw Δw High speed interconnect PS with gRPC on TCP/IP by software on CPU → PS becomes the bottleneck, tedious distributed cluster mgmt All Reduce with 2-D toroidal mesh network by Google's HPC hardware → as easy as using a single node as scalable as supercomputers -
TPU v2 Pod performance ResNet-50 on TPU v2 half-pod Real
data: images/sec 77,392 Final accuracy: 93% Training time: 30 min #1 training time on DAWNBench -
TPU v2 Pod performance RankBrain: 132 h on 275 CPU
→ 9 h on 16 TPU Image model: 216 h → 22 h on 16 TPU WaveNet (Speech): generation at 20X real time -
Large-batch training: 8K images / batch on 32 TPUs hours
to 90 epochs top-1 validation accuracy 76% 25 min ResNet-50 training on ImageNet 10 hrs 52 min time -
Scalable training with TensorFlow Estimator GPU 1 GPU 2 Mean
Update Variable s Gradient s Loss Model Gradient s Loss Model Parameter Server Model Replicas Data Shards w’ = w - n Δ w w Δw Multi GPUs Distributed TensorFlow TPU -
Programming Cloud TPU: TPU Estimator estimator = tf.contrib.tpu.TPUEstimator( model_fn=model_fn, use_tpu=FLAGS.use_tpu,
train_batch_size=FLAGS.batch_size, eval_batch_size=FLAGS.batch_size, params={"data_dir": FLAGS.data_dir}, config=run_config) -
def model_fn(features, labels, mode, params): input_layer = tf.reshape(features, [-1, 28,
28, 1]) conv1 = tf.layers.conv2d(inputs=input_layer, ...) pool1 = tf.layers.max_pooling2d(inputs=conv1, pool_size=[2,2], strides=2) # ... loss = tf.losses.softmax_cross_entropy( onehot_labels=onehot_labels, logits=logits) optimizer = tf.train.GradientDescentOptimizer(learning_rate=0.01) train_op = optimizer.minimize(loss) return tf.estimator.EstimatorSpec(mode=mode, loss=loss, train_op=train_op) Sample Model with Layers & Estimators -
def model_fn(features, labels, mode, params): input_layer = tf.reshape(features, [-1, 28,
28, 1]) conv1 = tf.layers.conv2d(inputs=input_layer, ...) pool1 = tf.layers.max_pooling2d(inputs=conv1, pool_size=[2,2], strides=2) # ... loss = tf.losses.softmax_cross_entropy( onehot_labels=onehot_labels, logits=logits) optimizer = tf.train.GradientDescentOptimizer(learning_rate=0.01) optimizer = tpu_optimizer.CrossShardOptimizer(optimizer) train_op = optimizer.minimize(loss) return tpu_estimator.EstimatorSpec(mode=mode, loss=loss, train_op=train_op) Model with TPU Modifications No further change required for TPU Pod -
When to use Cloud TPU Use Cloud TPU when: Needs
tons of matrix operations Large model with large batch size Can run with TPU supported ops Don't use Cloud TPU when: Sparse, small, high-precision, or many branches Can't run with TPU supported ops Eg. large CNN such as ResNet -
Confidential & Proprietary Image Recognition & Object Detection Machine Translation
and Language Modeling Speech Recognition Model: ASR Transformer (LibriSpeech) Available reference models for Cloud TPUs Models: Machine translation Language modeling Sentiment analysis Question-answering (all Transformer-based) Image Generation Models: Image Transformer DCGAN Image Recognition: AmoebaNet-D ResNet-50/101/152/200 Inception v2/v3/v4 DenseNet Object Detection: RetinaNet Low-Resource Models: MobileNet SqueezeNet -
Cloud TPU FAQs (as of June 5, 2018) How do
you count Cloud TPUs? 1 Cloud TPU has 4 TPU processors and 8 cores. Total 64GB HBM and 180 TFLOPS. Can you use Cloud TPU for inference? Batch inference works on Cloud TPU. Online inference does not. TensorFlow Serving and ML Engine prediction does not work on Cloud TPU. Is Cloud TPU faster than GPU? Google hasn't published any comparison, but RiseML has a blog post comparing with NVIDIA V100. Any other way of using TPU than TPUEstimator? No. We strongly recommend to start with the reference models and then customise TPUEstimator. Does Colaboratory or Cloud Datalab support TPU? Stay tuned. Does Cloud ML Engine support TPU? Yes. Training with Cloud TPU is supported as beta. -
"Romit and I discovered some new TensorBoard profiling features that
analyze your ENTIRE TensorFlow pipeline including data ingestion and ETL to CPU, GPU, and TPU utilization and graph/operator optimization...These profiling tools are exactly what we've always from Spark-based ETL pipelines, but we've never seen them on the market - not at this level of system detail and optimization." https://www.meetup.com/Advanced-Spark-and-TensorFlow-Meetup/events/23 3979387/ -
Host-side analysis details Tips Stats Reading data from storage Preprocessing
the data Sending the data to device caching, prefetching parallel processing -
Summary What is TPU? domain specific architecture for deep learning
TPU Pod HPC-powered scalable "All Reduce" distributed training Cloud TPU Programming with TensorFlow Estimator API and TensorBoard