Share
Embed
[IROS2022] Scalable Fiducial Tag Localization on a 3D Prior Map Via Graph-Theoretic Global Tag-Map Registration
Scalable Fiducial Tag Localization on a 3D Prior Map Via Graph-Theoretic Global Tag-Map Registration
Kenji Koide, Shuji Oishi, Masashi Yokozuka, and Atsuhiko Banno
IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS2022)
koide3
June 28, 2024
Transcript
29 slides
-
Scalable Fiducial Tag Localization on a 3D Prior Map Via
Graph-Theoretic Global Tag-Map Registration Kenji Koide, Shuji Oishi, Masashi Yokozuka, and Atsuhiko Banno National Institute of Advanced Industrial Science and Technology (AIST), Japan -
Background • Map-based visual localization has been attracting much attention
• It is, however, sometimes necessary to rely on visual fiducial tags (aka visual markers) for initialization and fail-safe [Oishi, 2020] -
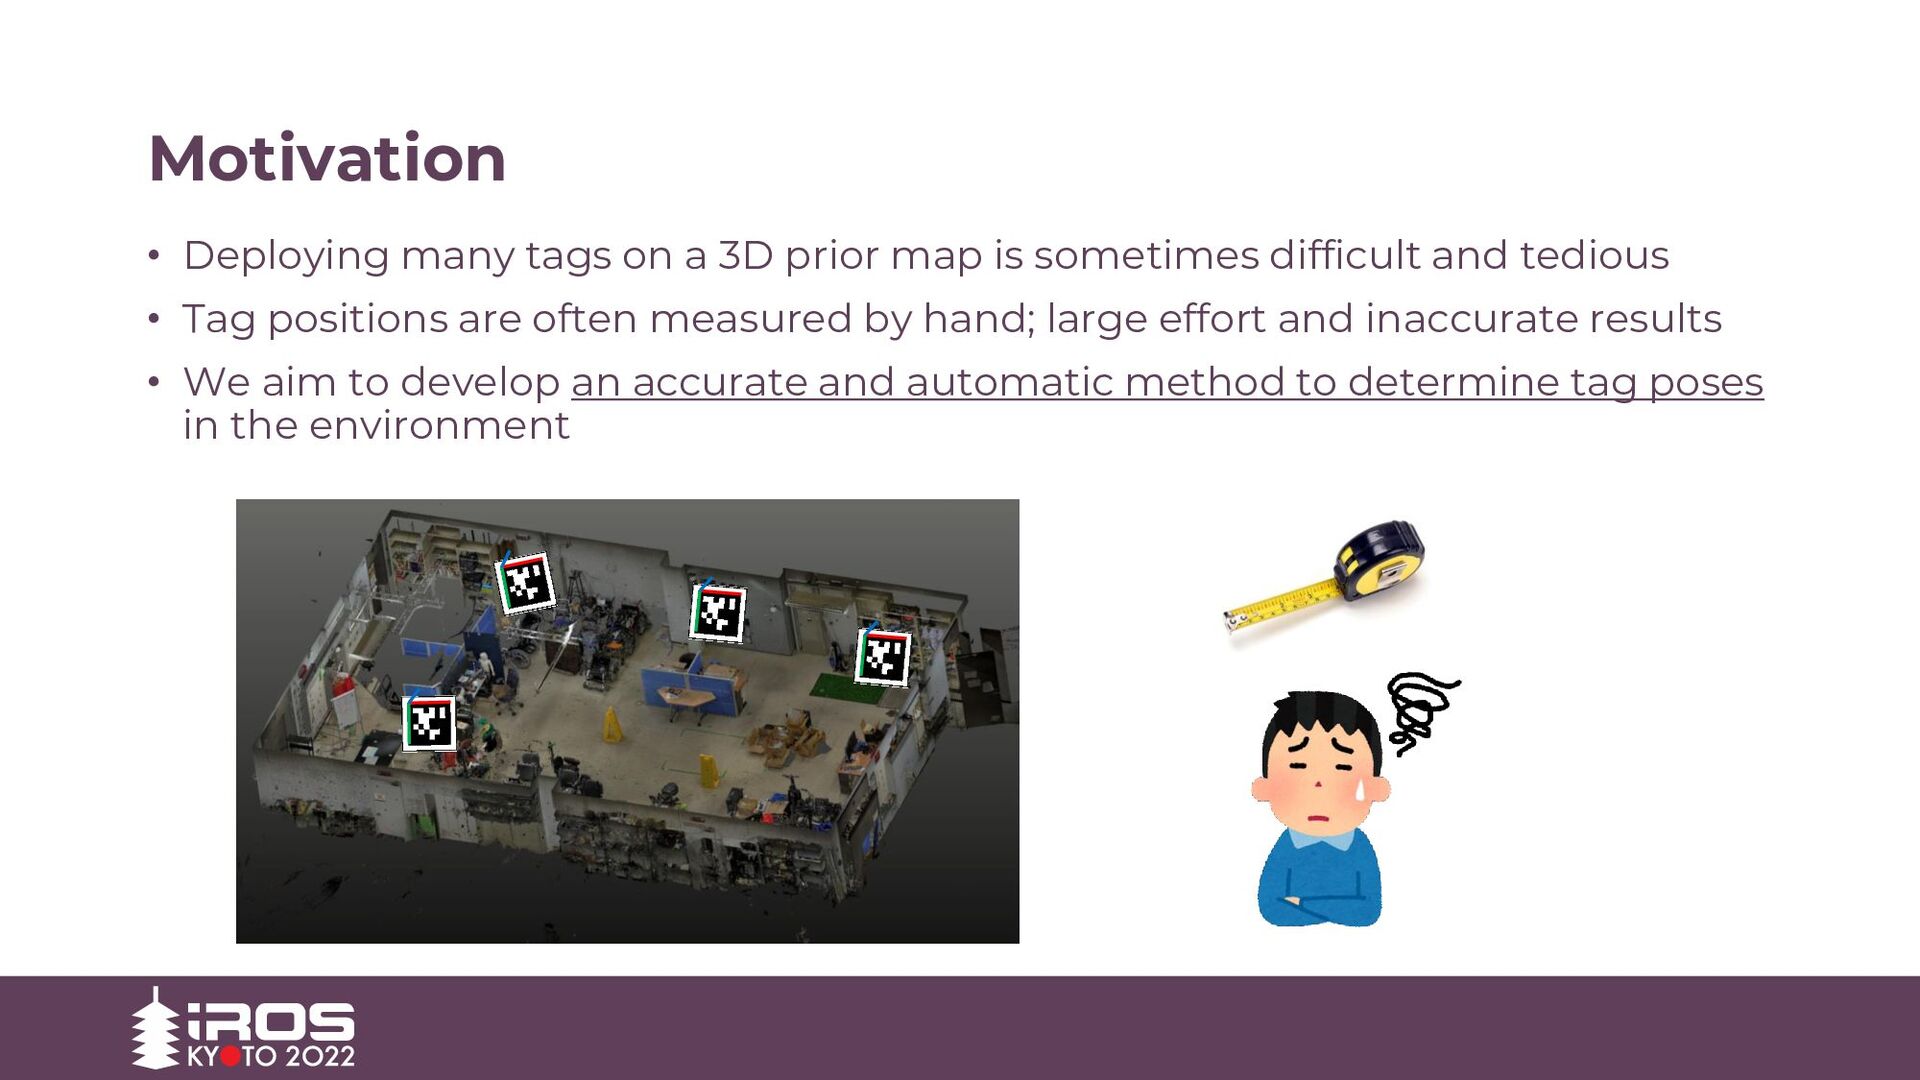
Motivation • Deploying many tags on a 3D prior map
is sometimes difficult and tedious • Tag positions are often measured by hand; large effort and inaccurate results • We aim to develop an accurate and automatic method to determine tag poses in the environment -
Proposed Method 1. VIO-based Tag-Relative-Pose Estimation We use an agile
camera to observe tags in the environment and estimate the relative poses between tags via landmark SLAM 2. Global Tag-Map Registration We then roughly align tags and a prior map by establishing tag-plane correspondences via graph-theoretic correspondence estimation 3. Estimation Refinement via Direct Camera-Map Alignment Tag and camera poses are refined by directly aligning agile camera images with the prior map and re-optimize all variables under all constraints -
Proposed Method 1. VIO-based Tag-Relative-Pose Estimation We use an agile
camera to observe tags in the environment and estimate the relative poses between tags via landmark SLAM 2. Global Tag-Map Registration We then roughly align tags and a prior map by establishing tag-plane correspondences via graph-theoretic correspondence estimation 3. Estimation Refinement via Direct Camera-Map Alignment Tag and camera poses are refined by directly aligning agile camera images with the prior map and re-optimize all variables under all constraints -
Proposed Method 1. VIO-based Tag-Relative-Pose Estimation We use an agile
camera to observe tags in the environment and estimate the relative poses between tags via landmark SLAM 2. Global Tag-Map Registration We then roughly align tags and a prior map by establishing tag-plane correspondences via graph-theoretic correspondence estimation 3. Estimation Refinement via Direct Camera-Map Alignment Tag and camera poses are refined by directly aligning agile camera images with the prior map and re-optimize all variables under all constraints -
Proposed Method 1. VIO-based Tag-Relative-Pose Estimation We use an agile
camera to observe tags in the environment and estimate the relative poses between tags via landmark SLAM 2. Global Tag-Map Registration We then roughly align tags and a prior map by establishing tag-plane correspondences via graph-theoretic correspondence estimation 3. Estimation Refinement via Direct Camera-Map Alignment Tag and camera poses are refined by directly aligning agile camera images with the prior map and re-optimize all variables under all constraints -
Proposed Method 1. VIO-based Tag-Relative-Pose Estimation We use an agile
camera to observe tags in the environment and estimate the relative poses between tags via landmark SLAM 2. Global Tag-Map Registration We then roughly align tags and a prior map by establishing tag-plane correspondences via graph-theoretic correspondence estimation 3. Estimation Refinement via Direct Camera-Map Alignment Tag and camera poses are refined by directly aligning agile camera images with the prior map and re-optimize all variables under all constraints -
VIO-based Tag-Relative-Pose Estimation • We use an agile camera and
observe each tag in the environment at least once • The tag poses in the VIO frame is estimated via landmark SLAM VIO (VINS-Mono) Tag detections (Apriltags) Pose graph optimization -
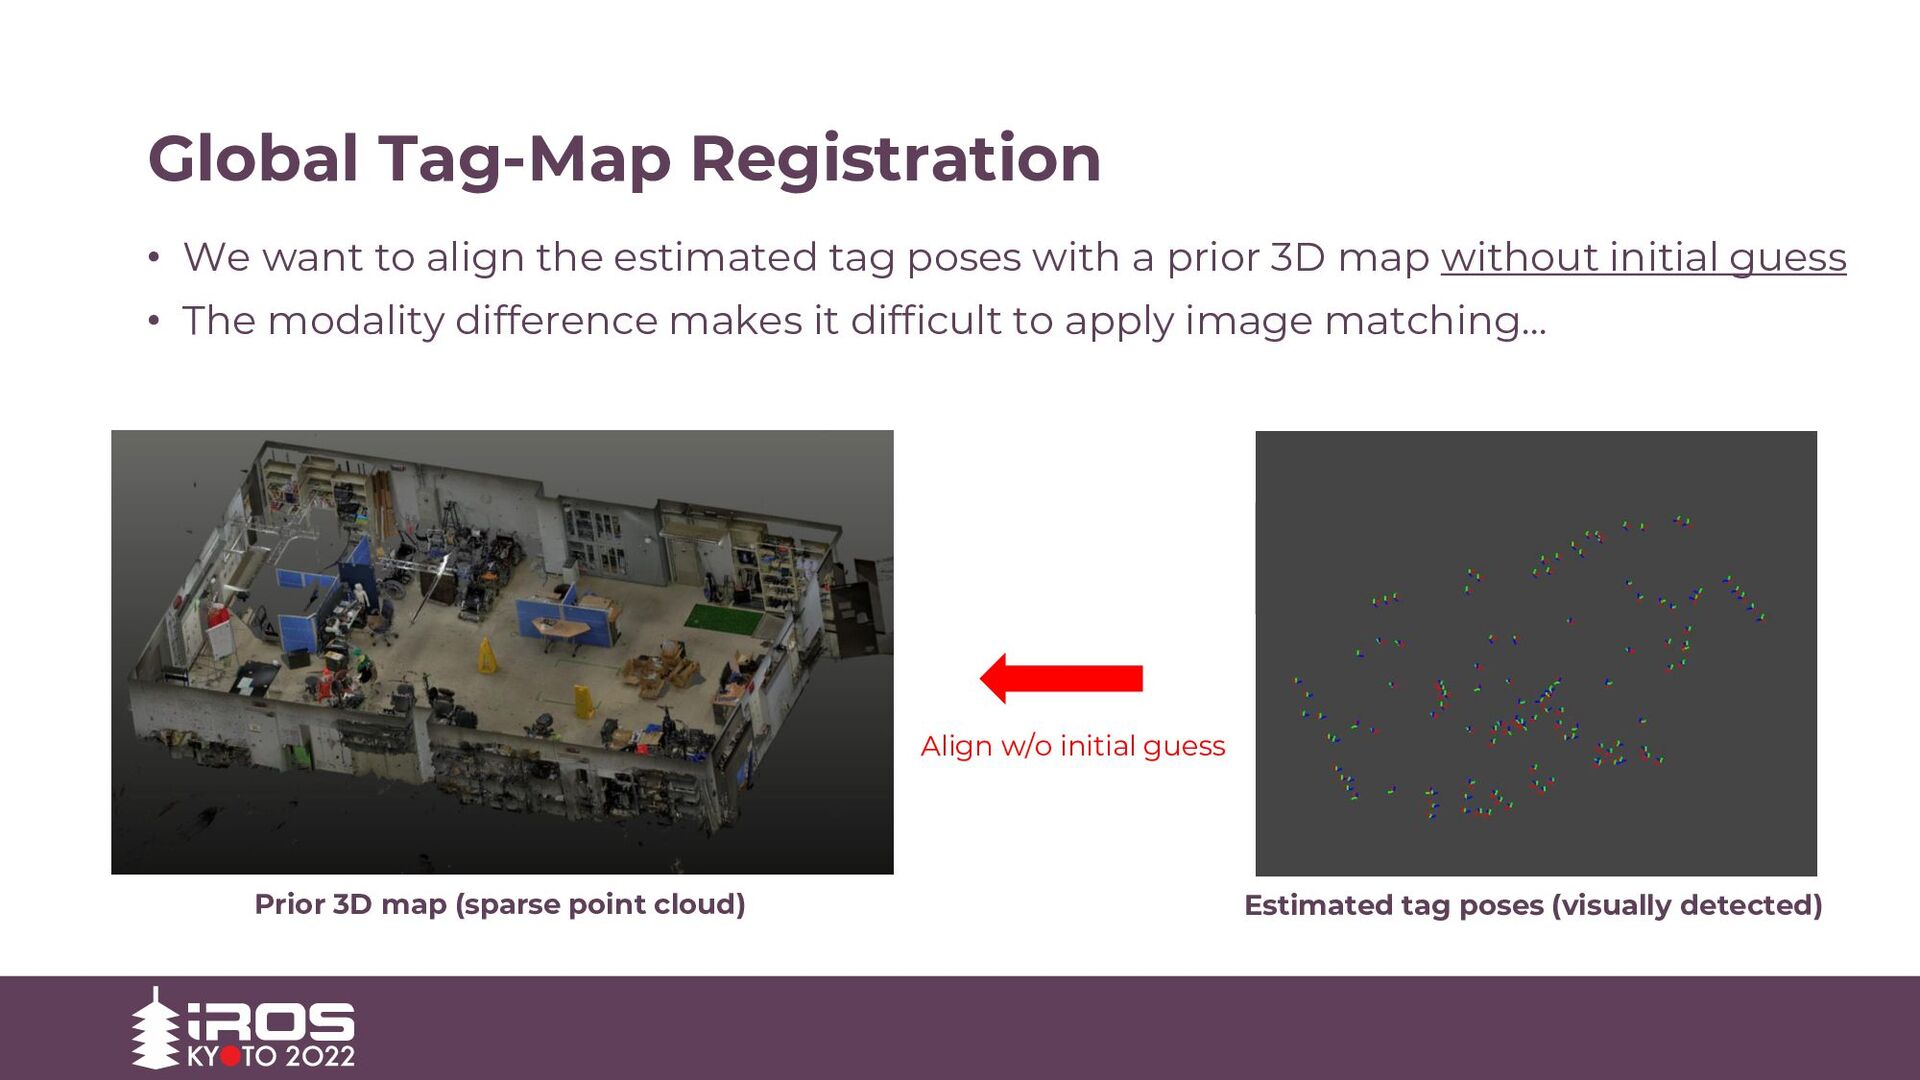
Global Tag-Map Registration • We want to align the estimated
tag poses with a prior 3D map without initial guess • The modality difference makes it difficult to apply image matching… Prior 3D map (sparse point cloud) Estimated tag poses (visually detected) Align w/o initial guess -
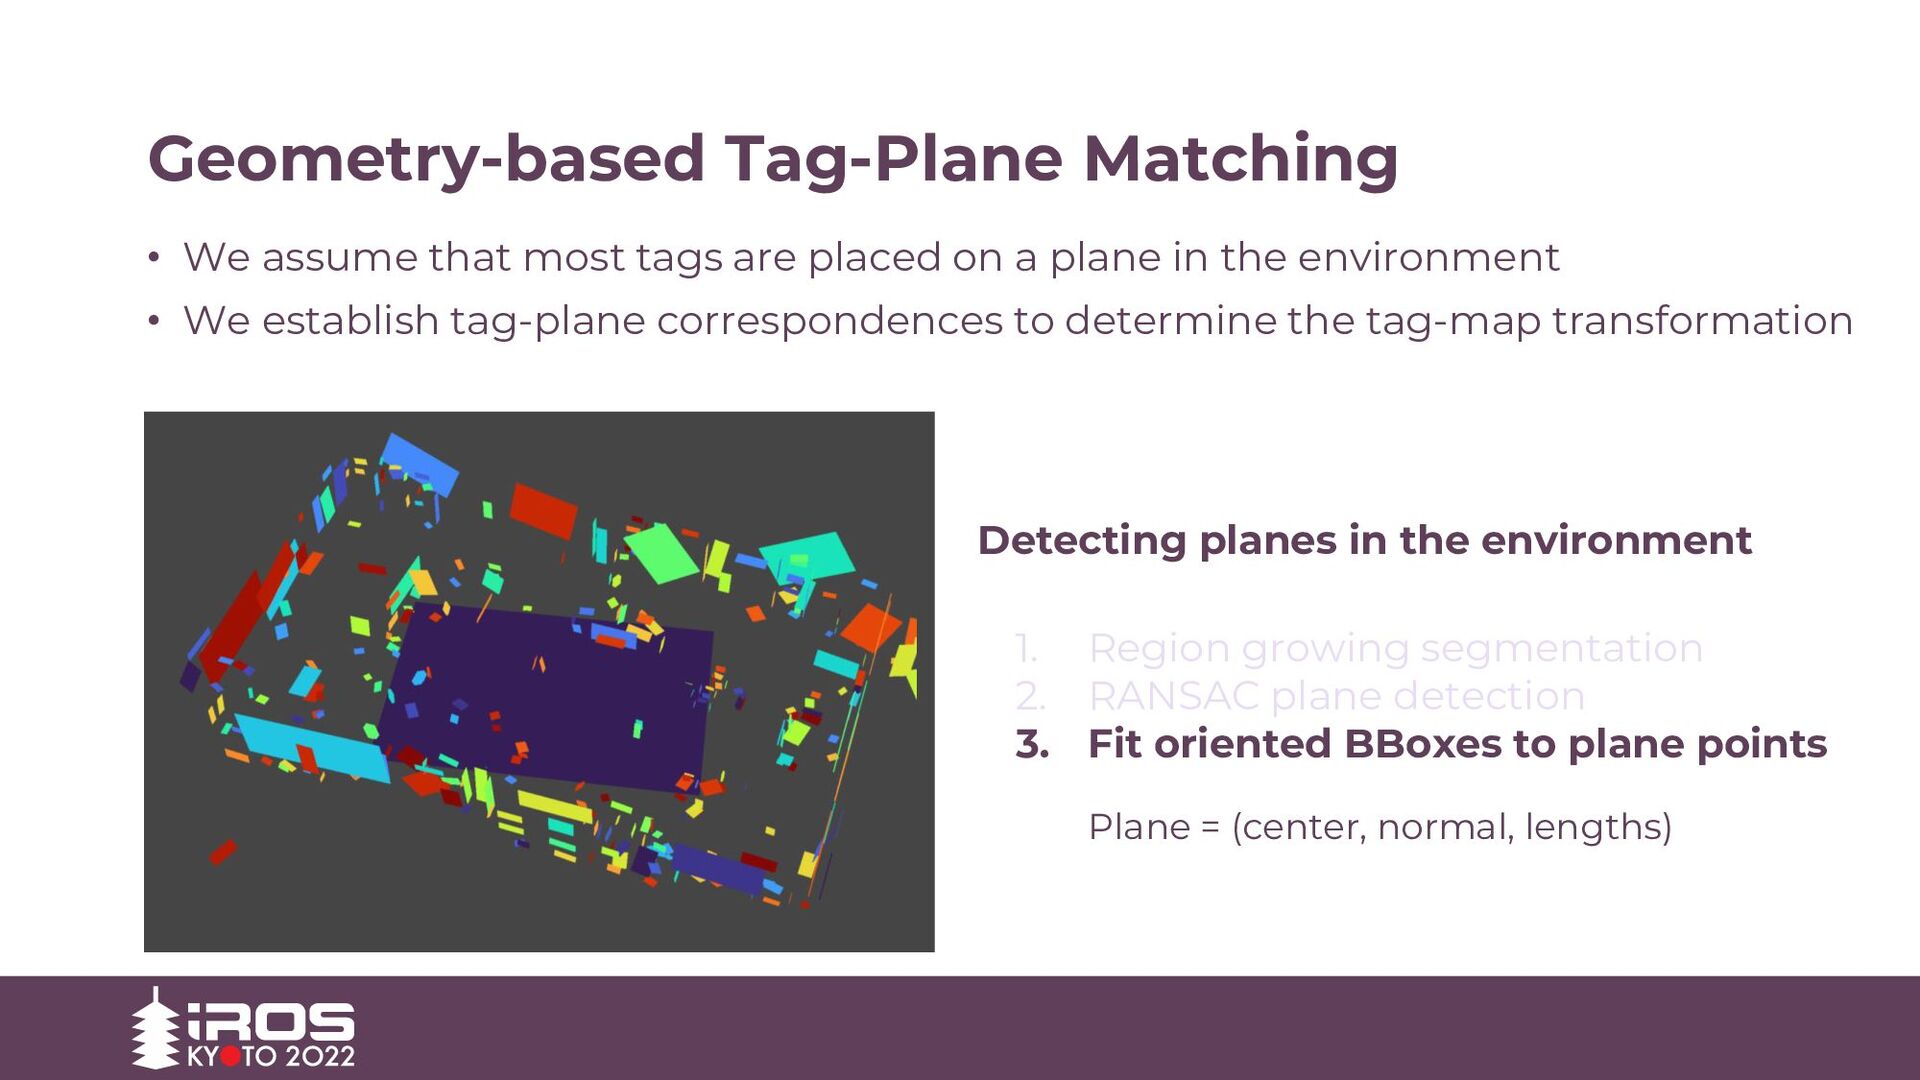
Geometry-based Tag-Plane Matching • We assume that most tags are
placed on a plane in the environment • We establish tag-plane correspondences to determine the tag-map transformation Detecting planes in the environment 1. Region growing segmentation 2. RANSAC plane detection 3. Fit oriented BBoxes to plane points -
Geometry-based Tag-Plane Matching • We assume that most tags are
placed on a plane in the environment • We establish tag-plane correspondences to determine the tag-map transformation Detecting planes in the environment 1. Region growing segmentation 2. RANSAC plane detection 3. Fit oriented BBoxes to plane points -
Geometry-based Tag-Plane Matching • We assume that most tags are
placed on a plane in the environment • We establish tag-plane correspondences to determine the tag-map transformation Detecting planes in the environment 1. Region growing segmentation 2. RANSAC plane detection 3. Fit oriented BBoxes to plane points -
Geometry-based Tag-Plane Matching • We assume that most tags are
placed on a plane in the environment • We establish tag-plane correspondences to determine the tag-map transformation Detecting planes in the environment 1. Region growing segmentation 2. RANSAC plane detection 3. Fit oriented BBoxes to plane points Plane = (center, normal, lengths) -
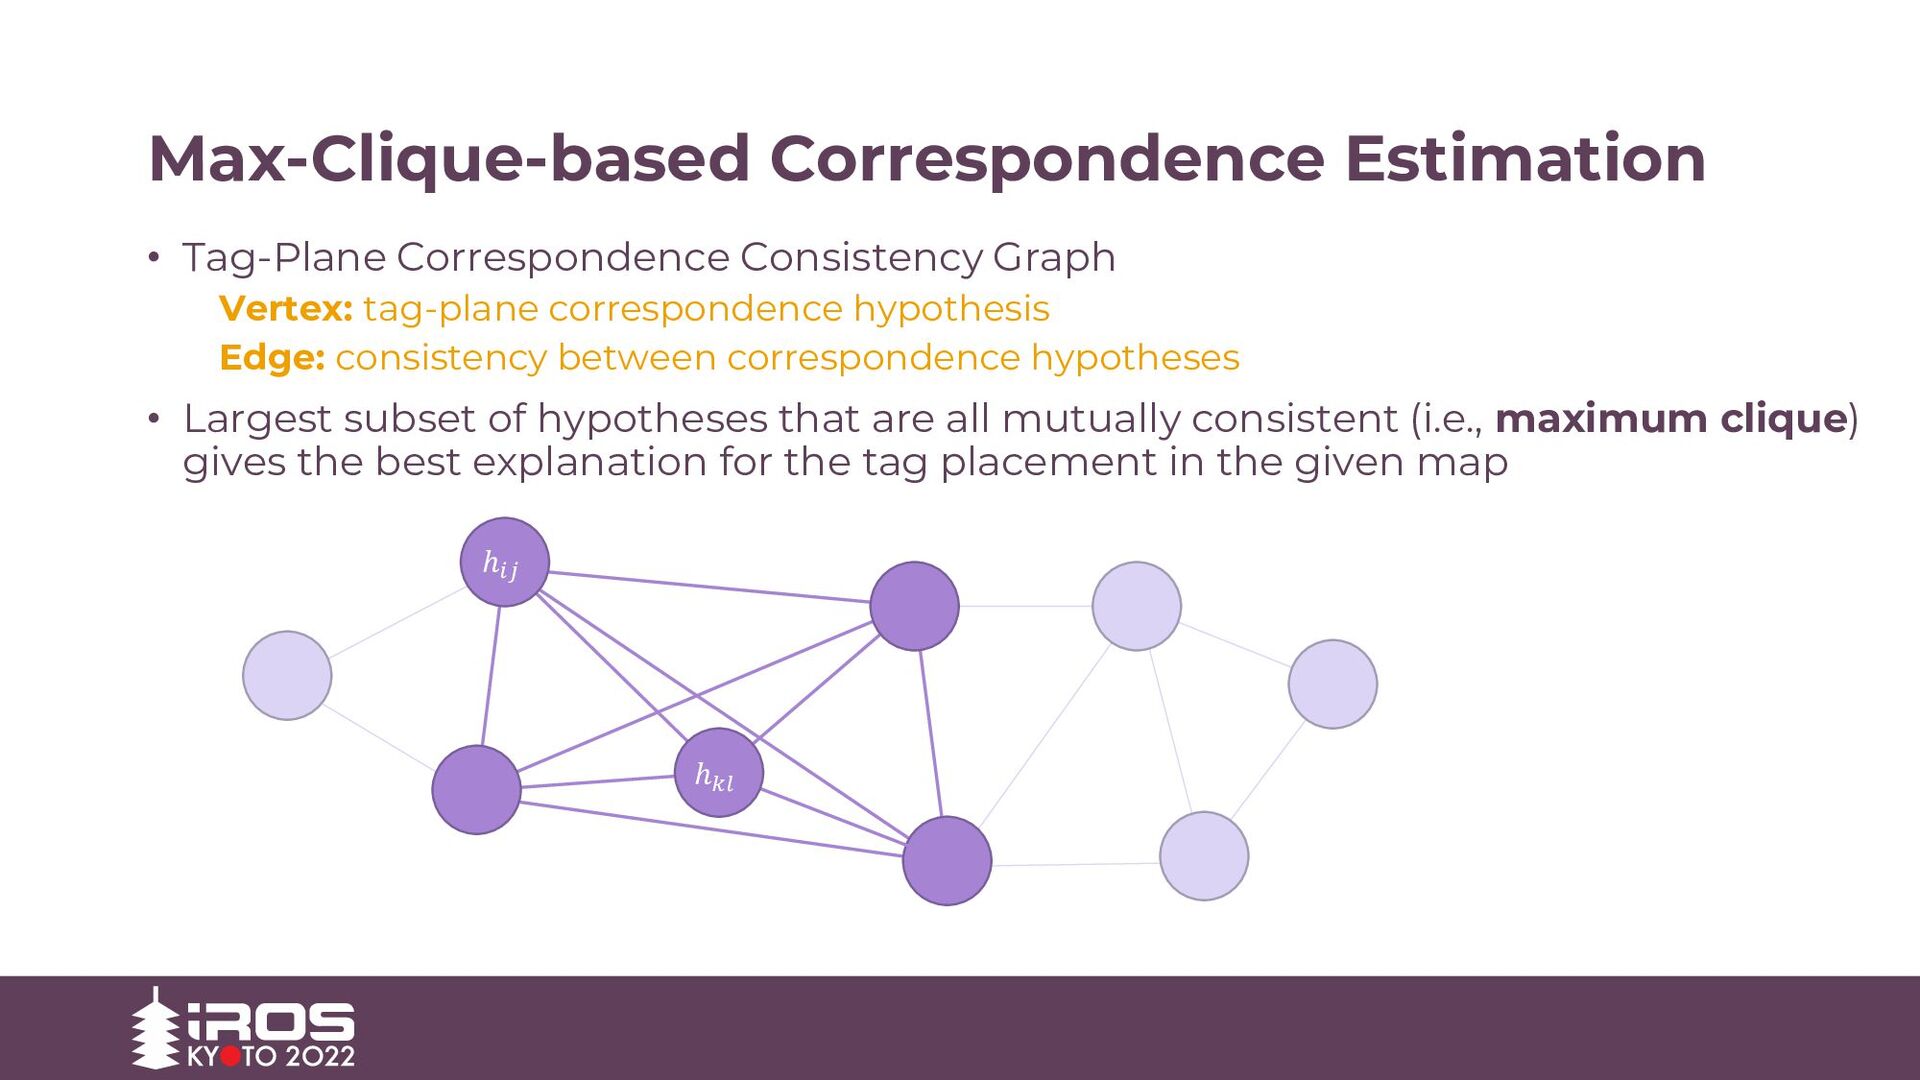
Max-Clique-based Correspondence Estimation • Tag-Plane Correspondence Consistency Graph Vertex: tag-plane
correspondence hypothesis Edge: consistency between correspondence hypotheses ℎ𝑖𝑗 does not contradict ℎ𝑘𝑙 (i.e., they are consistent) Tag i corresponds to plane j Tag k corresponds to plane l ℎ𝑖𝑗 ℎ𝑘𝑙 -
Max-Clique-based Correspondence Estimation • Tag-Plane Correspondence Consistency Graph Vertex: tag-plane
correspondence hypothesis Edge: consistency between correspondence hypotheses ℎ𝑖𝑗 ℎ𝑘𝑙 -
Max-Clique-based Correspondence Estimation • Tag-Plane Correspondence Consistency Graph Vertex: tag-plane
correspondence hypothesis Edge: consistency between correspondence hypotheses • Largest subset of hypotheses that are all mutually consistent (i.e., maximum clique) gives the best explanation for the tag placement in the given map ℎ𝑖𝑗 ℎ𝑘𝑙 -
Tag-Plane Correspondence Consistency • Consistency between tag-plane correspondence hypotheses is
determined based on geometric consistency check ℎ𝑖𝑗 ℎ𝑘𝑙 Tag i Tag k Plane j Plane l -
Tag-Plane Correspondence Consistency • Consistency between tag-plane correspondence hypotheses is
determined based on geometric consistency check • We align tag i and plane j and s.t. distance between tag k and plane l Plane j Plane l -
Tag-Plane Correspondence Consistency • Consistency between tag-plane correspondence hypotheses is
determined based on geometric consistency check • We align tag i and plane j and s.t. distance between tag k and plane l • If normal and translation errors between tag k and plane l are smaller than threshold, these hypotheses are mutually consistent Plane j Plane l Normal error Translation error -
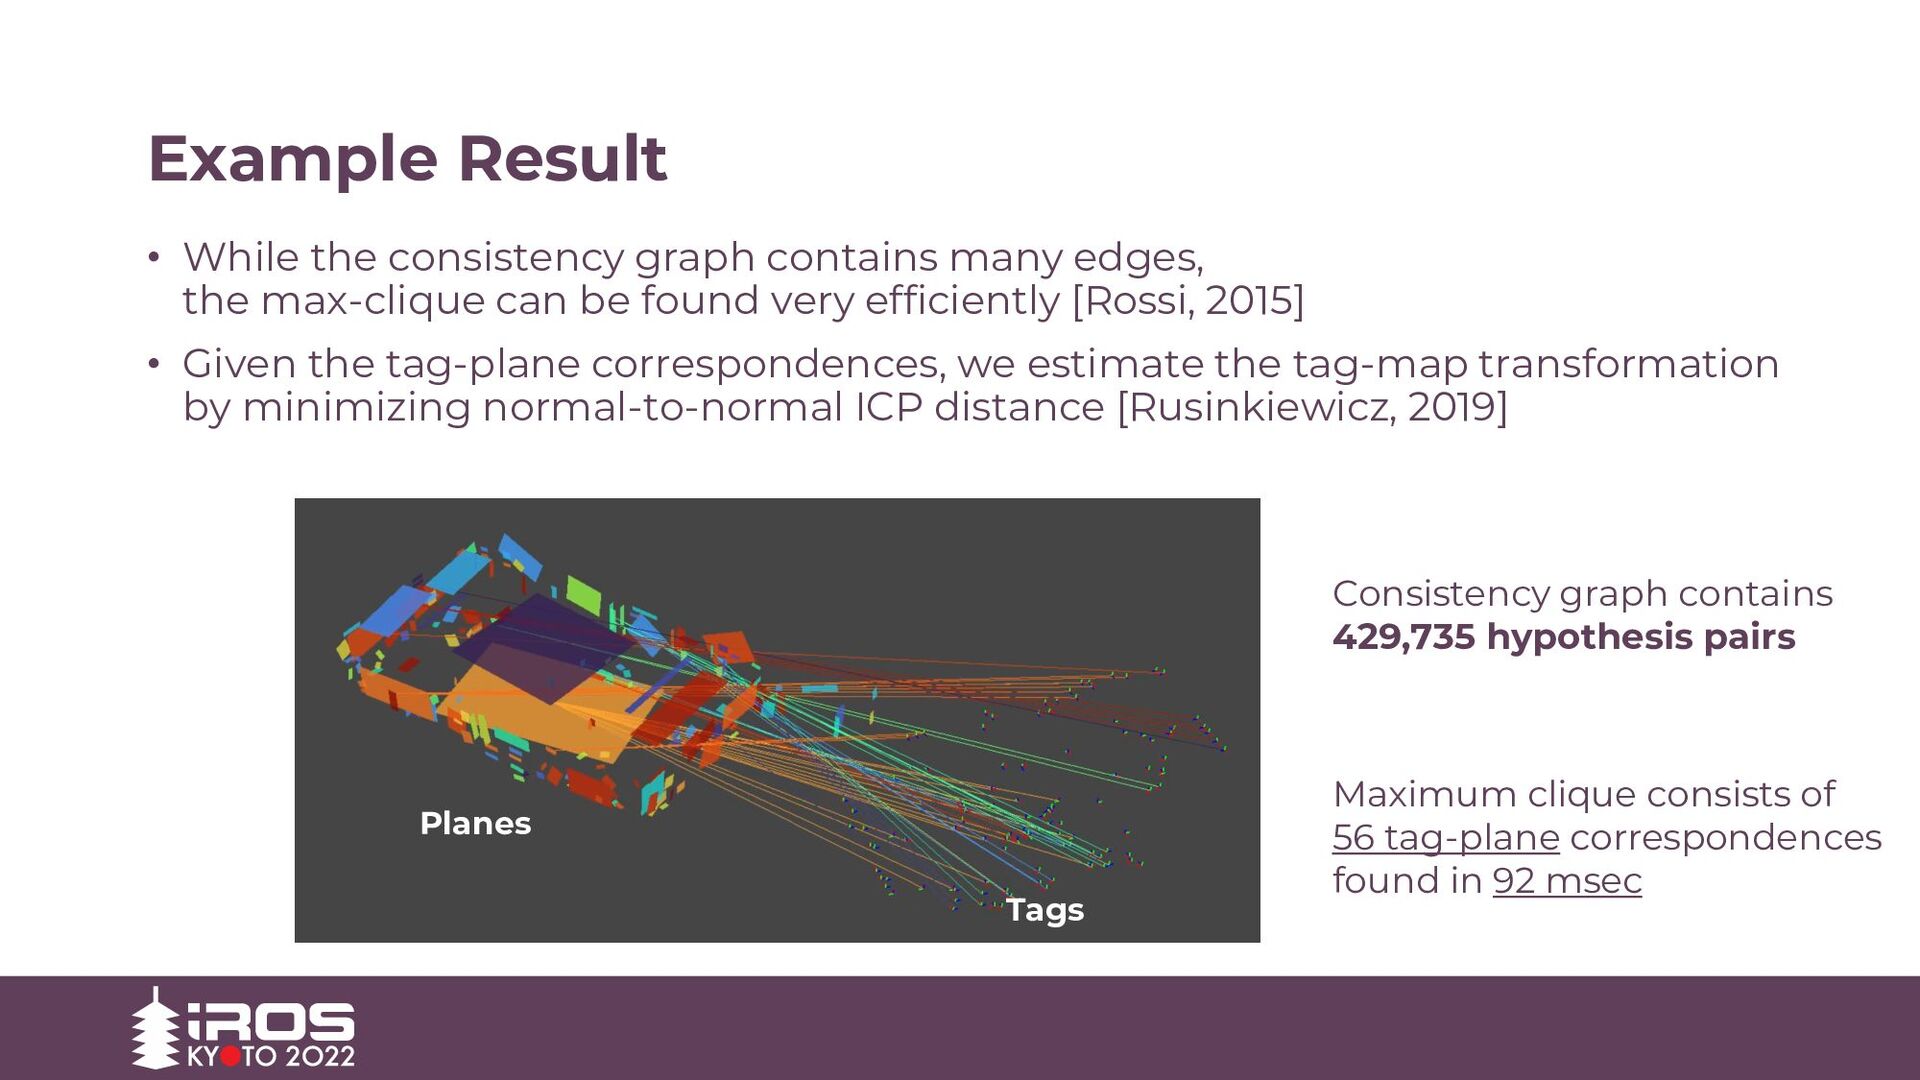
Example Result Planes Tags • While the consistency graph contains
many edges, the max-clique can be found very efficiently [Rossi, 2015] -
Example Result Planes Tags Consistency graph contains 429,735 hypothesis pairs
• While the consistency graph contains many edges, the max-clique can be found very efficiently [Rossi, 2015] -
Example Result Planes Tags Consistency graph contains 429,735 hypothesis pairs
Maximum clique consists of 56 tag-plane correspondences found in 92 msec • While the consistency graph contains many edges, the max-clique can be found very efficiently [Rossi, 2015] • Given the tag-plane correspondences, we estimate the tag-map transformation by minimizing normal-to-normal ICP distance [Rusinkiewicz, 2019] -
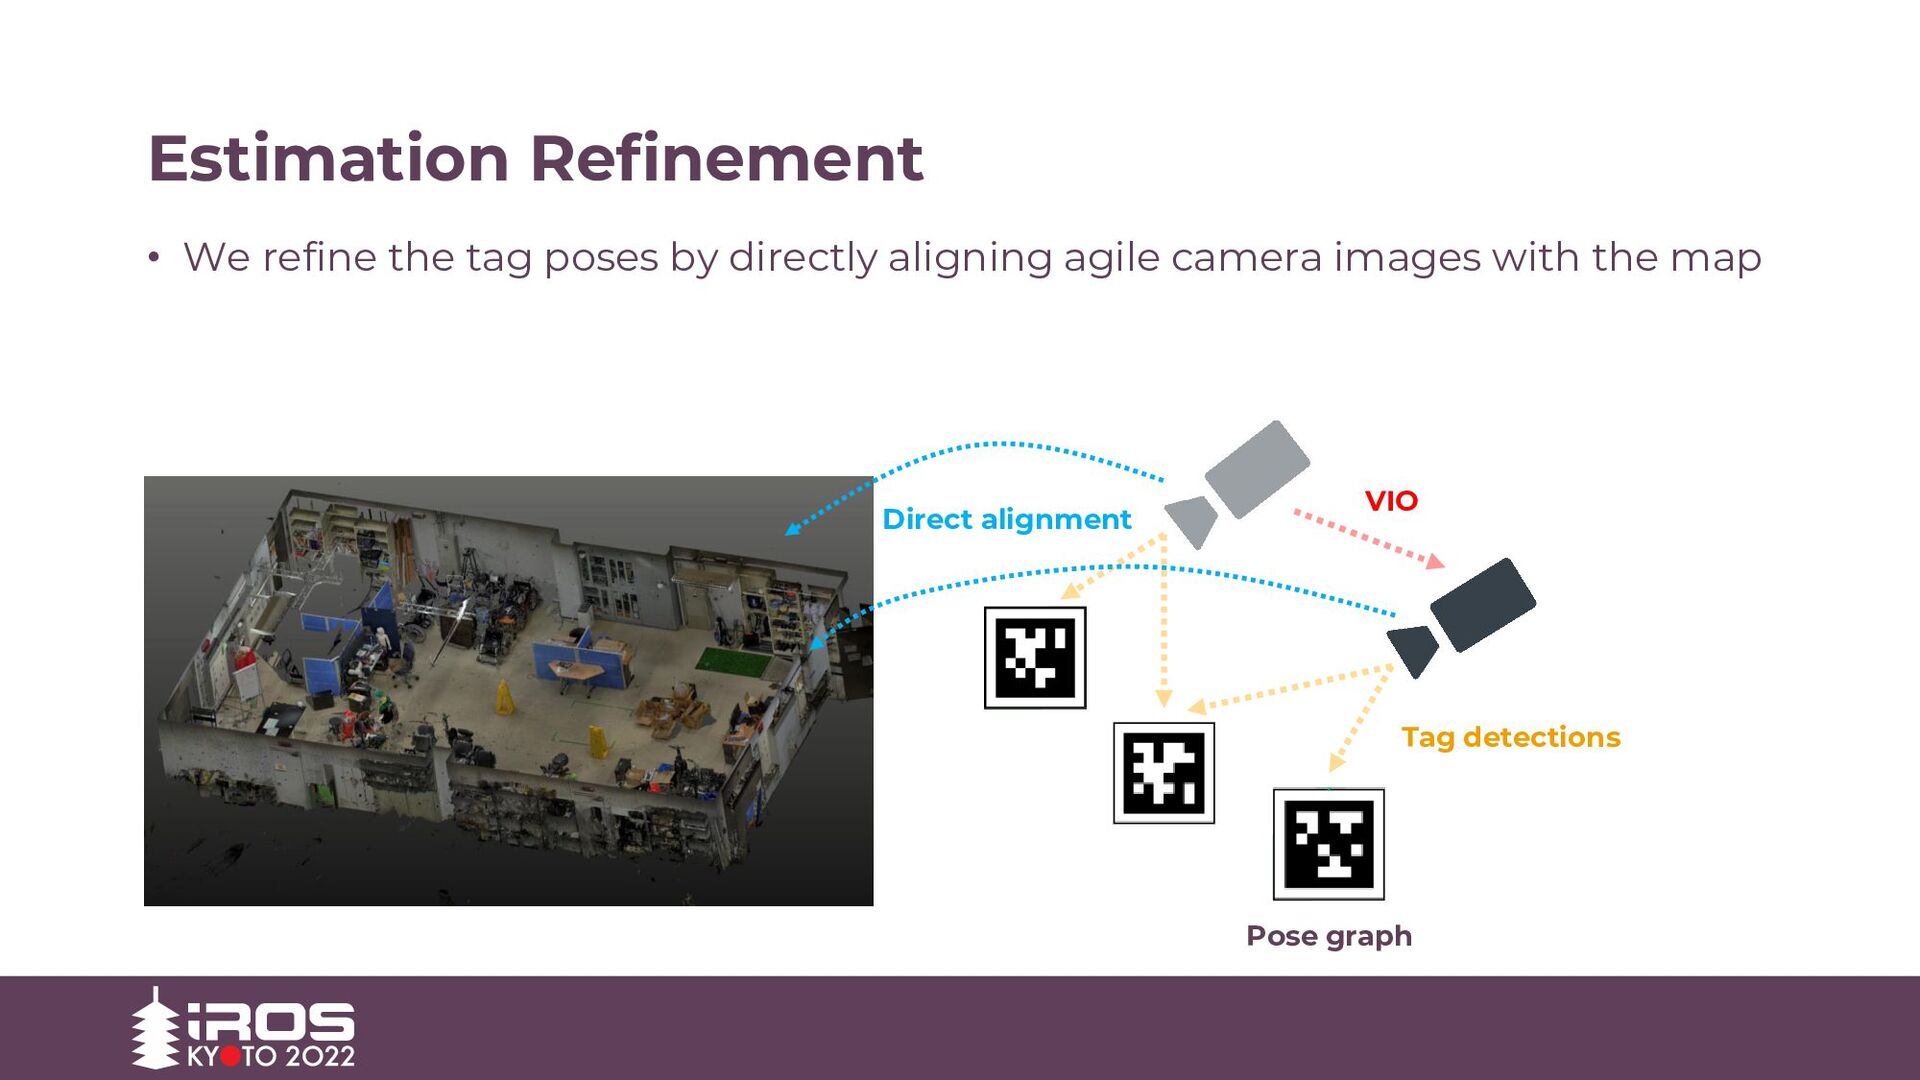
Estimation Refinement • We refine the tag poses by directly
aligning agile camera images with the map VIO Tag detections Pose graph Direct alignment -
Estimation Refinement • We refine the tag poses by directly
aligning agile camera images with the map • We use the normalized information distance (NID), a mutual information-based cross modal metric, to maximize the co-occurrence of pixel and map intensity values • Tag and camera poses are re-optimized under all the constraints Agile camera image Map rendered with optimized camera pose -
Evaluation in Simulation • The method is evaluated on the
Replica dataset [Savva, 2019] Global tag-map registration : 0.039m / 1.021° Tag localization accuracy : 98% success rate Baseline (FPFH+RANSAC/Teaser) : 26% and 70% Robustness to outlier tags -
Evaluation in Real Environment • 117 tags were placed in
the environment • Tag poses were estimated in 22 minutes (16 min for VIO recording, 6 min for post processing) • Average tag pose error: 0.019m and 2.382° Final estimation result -
Conclusion • An accurate and scalable method for fiducial tag
localization on a 3D prior environmental map is proposed • VIO-based tag relative pose estimation via landmark SLAM • Global tag-map registration based on tag-plane correspondence estimation via maximum clique finding • Estimation refinement via NID-based direct camera-map alignment • The proposed method could localize over 100 tags in 22 minutes • The average tag localization error was about 2 cm