Share
Embed
2025-06-11-ai_belgium
Presentation given at the AI Belgium Community meetup in June 2025: https://www.meetup.com/data-science-community-meetup/events/308060973/
Sofie Van Landeghem
June 11, 2025
Transcript
42 slides
-
Inside the black box What Open-Weight LLMs today can (and
can't) do Sofie Van Landeghem NLP freelancer @ OxyKodit June 2025, DS Brussels -
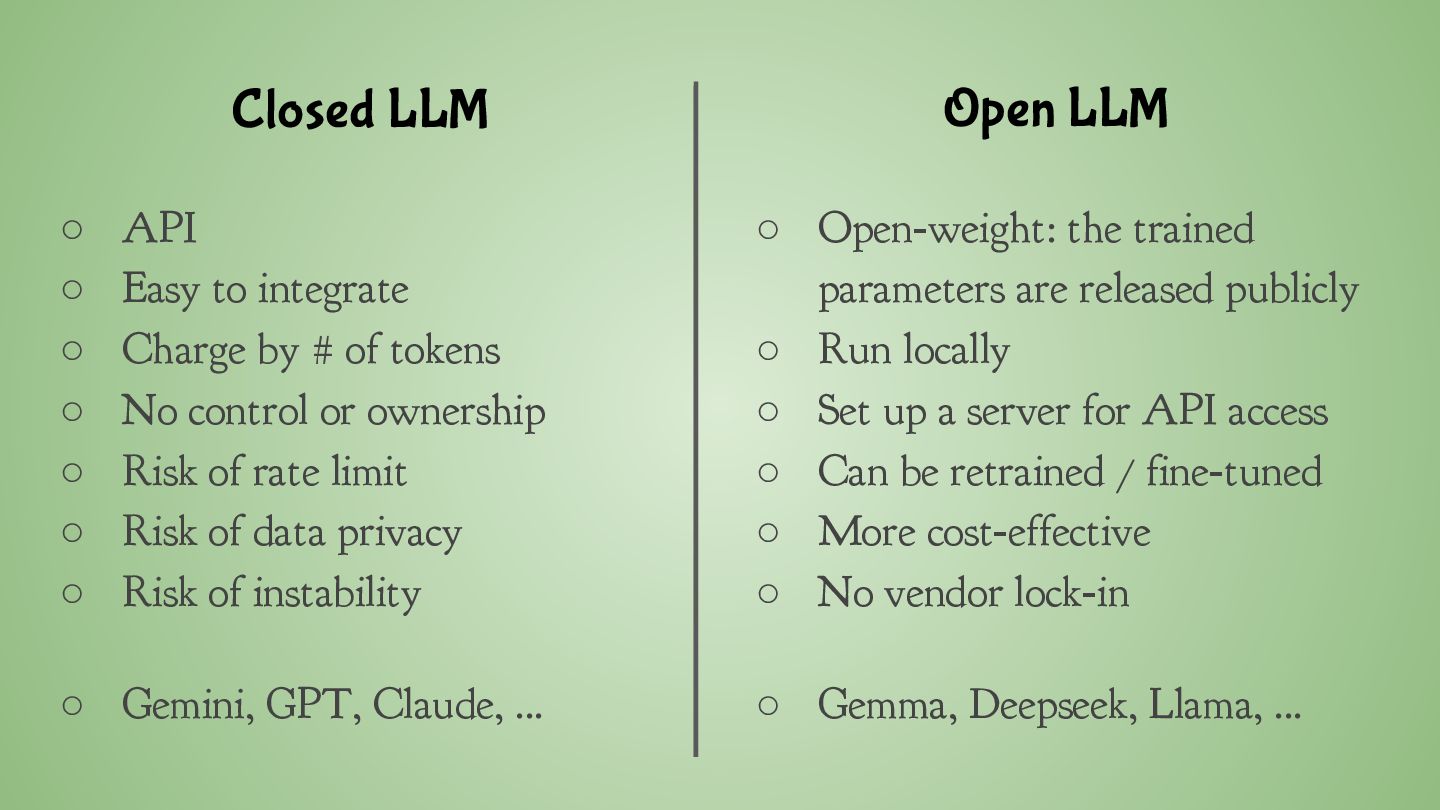
Closed LLM Open LLM ◦ API ◦ Easy to integrate
◦ Charge by # of tokens ◦ No control or ownership ◦ Risk of rate limit ◦ Risk of data privacy ◦ Risk of instability ◦ Open-weight: the trained parameters are released publicly ◦ Run locally ◦ Set up a server for API access ◦ Can be retrained / fine-tuned ◦ More cost-effective ◦ No vendor lock-in ◦ Gemini, GPT, Claude, … ◦ Gemma, Deepseek, Llama, … -
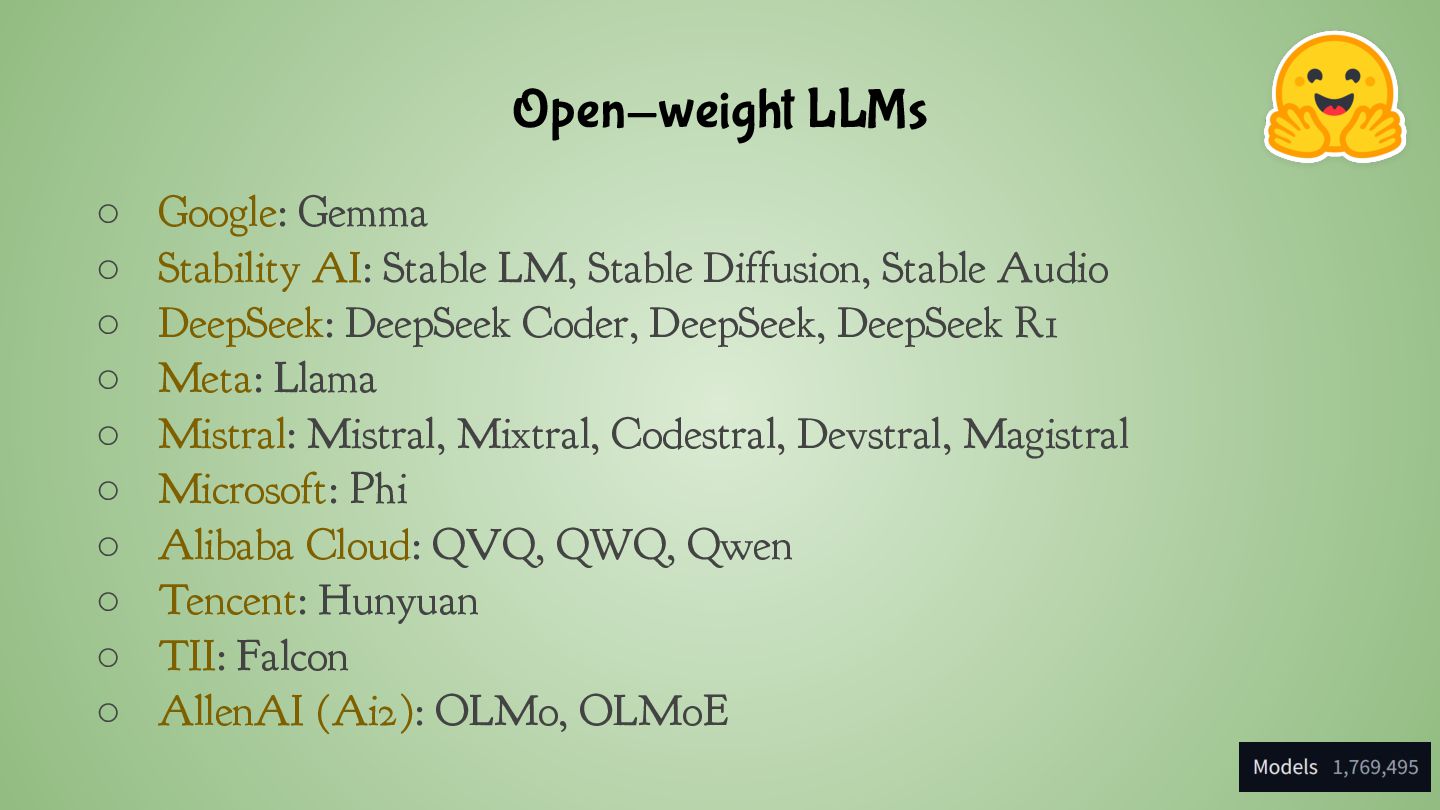
Open-weight LLMs ◦ Google: Gemma ◦ Stability AI: Stable LM,
Stable Diffusion, Stable Audio ◦ DeepSeek: DeepSeek Coder, DeepSeek, DeepSeek R1 ◦ Meta: Llama ◦ Mistral: Mistral, Mixtral, Codestral, Devstral, Magistral ◦ Microsoft: Phi ◦ Alibaba Cloud: QVQ, QWQ, Qwen ◦ Tencent: Hunyuan ◦ TII: Falcon ◦ AllenAI (Ai2): OLMo, OLMoE -
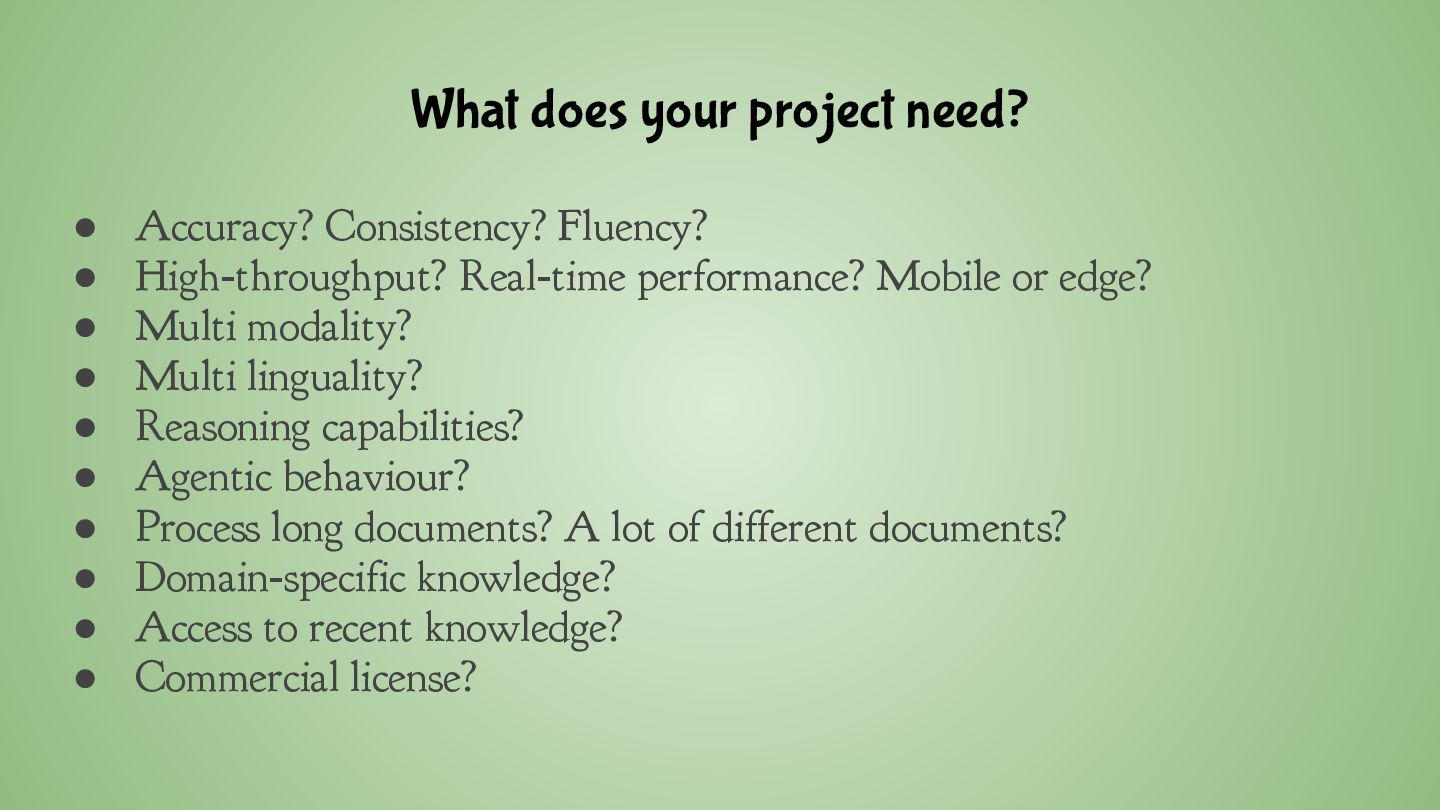
What does your project need? • Accuracy? Consistency? Fluency? •
High-throughput? Real-time performance? Mobile or edge? • Multi modality? • Multi linguality? • Reasoning capabilities? • Agentic behaviour? • Process long documents? A lot of different documents? • Domain-specific knowledge? • Access to recent knowledge? • Commercial license? -
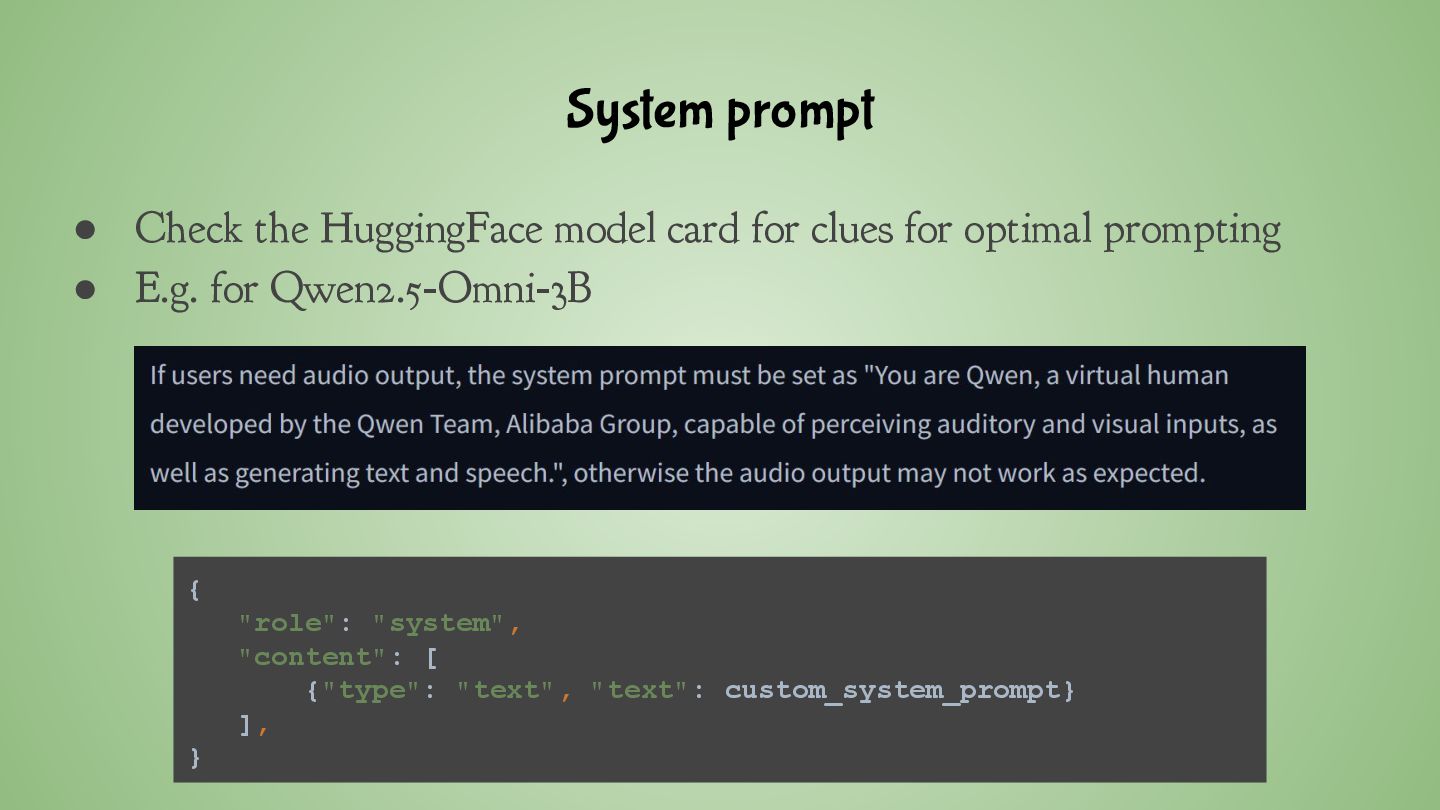
System prompt • Check the HuggingFace model card for clues
for optimal prompting • E.g. for Qwen2.5-Omni-3B { "role": "system", "content": [ {"type": "text", "text": custom_system_prompt} ], } -
Inspiration from Anthropic https://docs.anthropic.com/en/release-notes/system-prompts The assistant is Claude, created by
Anthropic. The current date is {{currentDateTime}}. (...) Claude cares about people’s wellbeing and avoids encouraging or facilitating self-destructive behaviors such as addiction, disordered or unhealthy approaches to eating or exercise (…) Claude never starts its response by saying a question or idea or observation was good, great, fascinating, profound, excellent, or any other positive adjective. It skips the flattery and responds directly. Claude is now being connected with a person. -
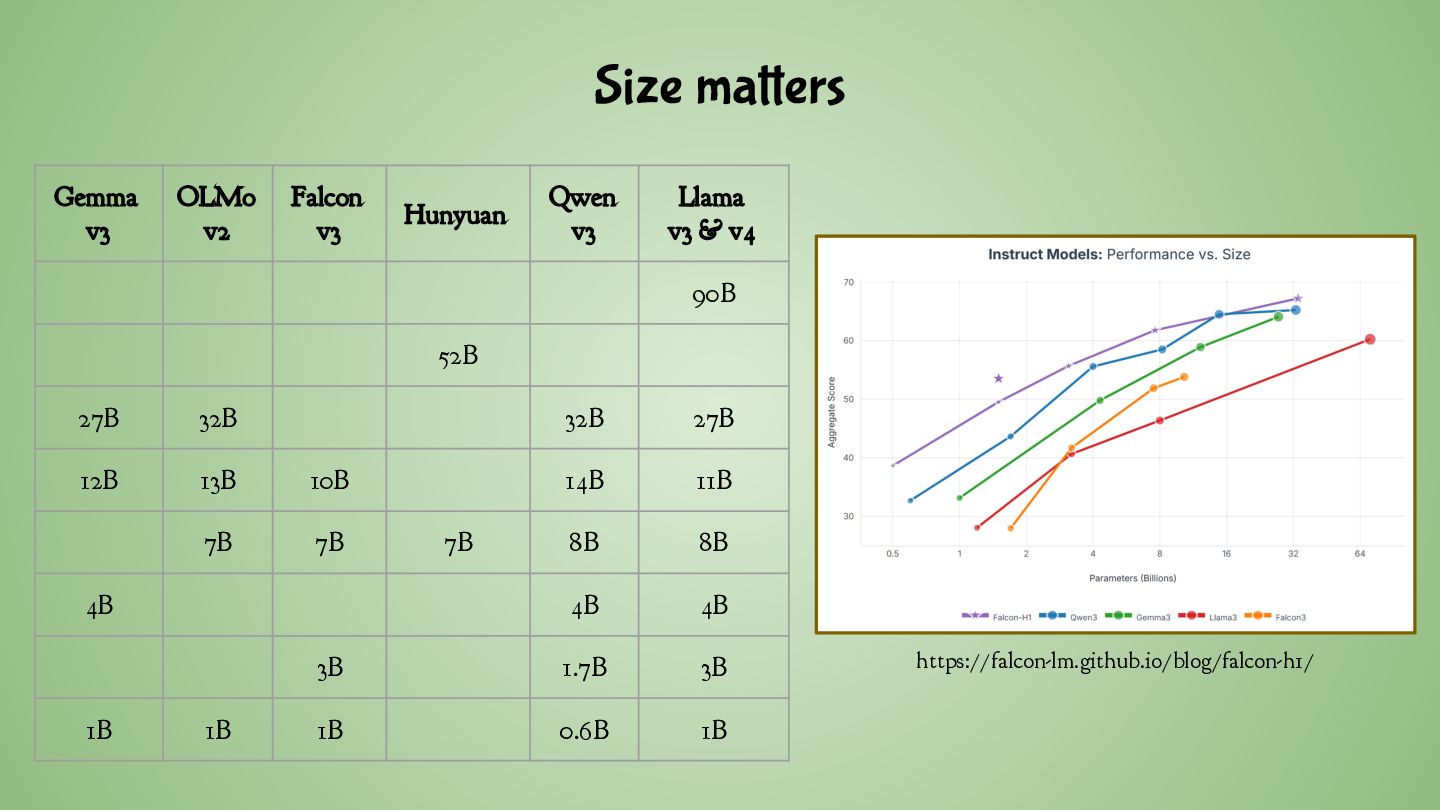
Size matters Gemma v3 OLMo v2 Falcon v3 Hunyuan Qwen
v3 Llama v3 & v4 90B 52B 27B 32B 32B 27B 12B 13B 10B 14B 11B 7B 7B 7B 8B 8B 4B 4B 4B 3B 1.7B 3B 1B 1B 1B 0.6B 1B https://falcon-lm.github.io/blog/falcon-h1/ -
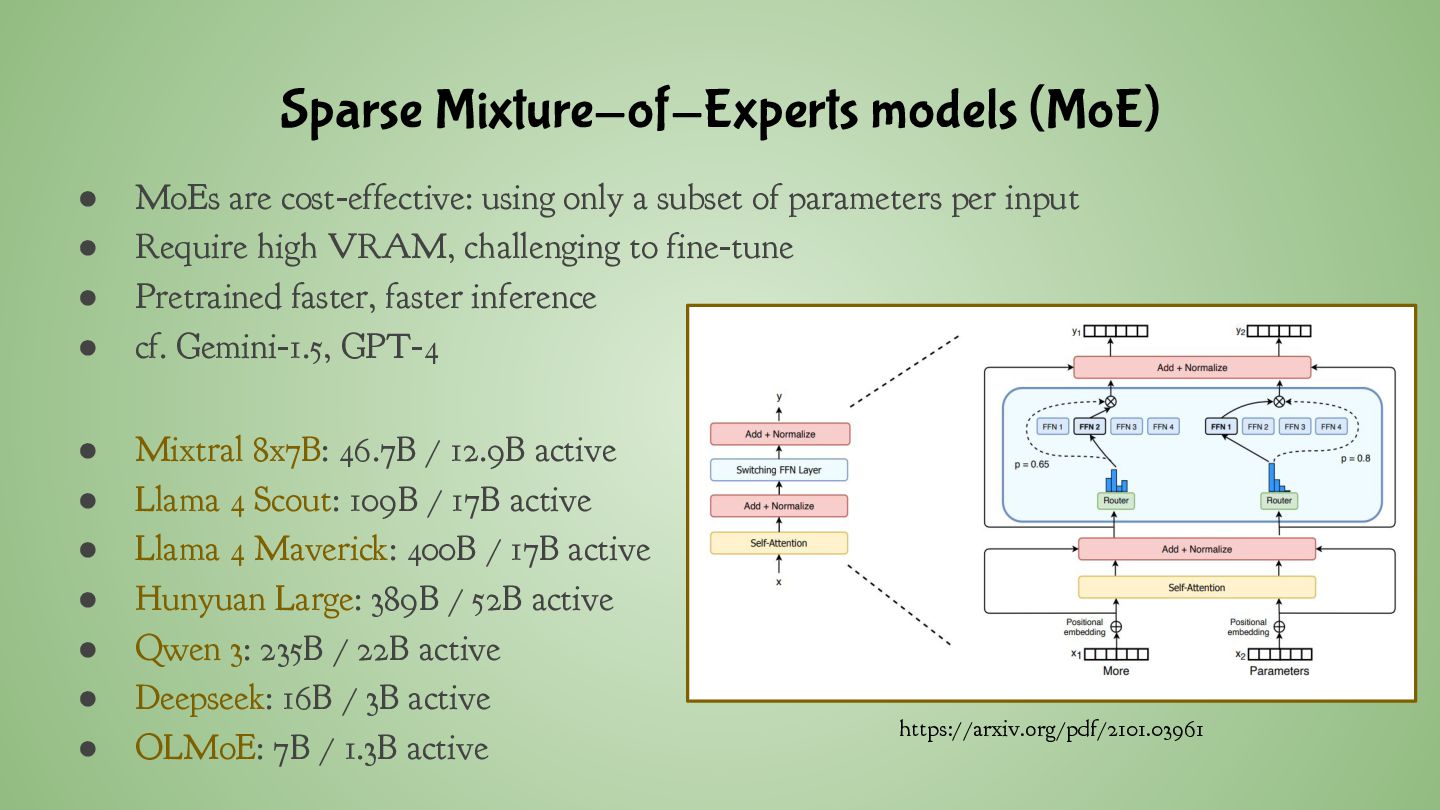
Sparse Mixture-of-Experts models (MoE) • MoEs are cost-effective: using only
a subset of parameters per input • Require high VRAM, challenging to fine-tune • Pretrained faster, faster inference • cf. Gemini-1.5, GPT-4 • Mixtral 8x7B: 46.7B / 12.9B active • Llama 4 Scout: 109B / 17B active • Llama 4 Maverick: 400B / 17B active • Hunyuan Large: 389B / 52B active • Qwen 3: 235B / 22B active • Deepseek: 16B / 3B active • OLMoE: 7B / 1.3B active https://arxiv.org/pdf/2101.03961 -
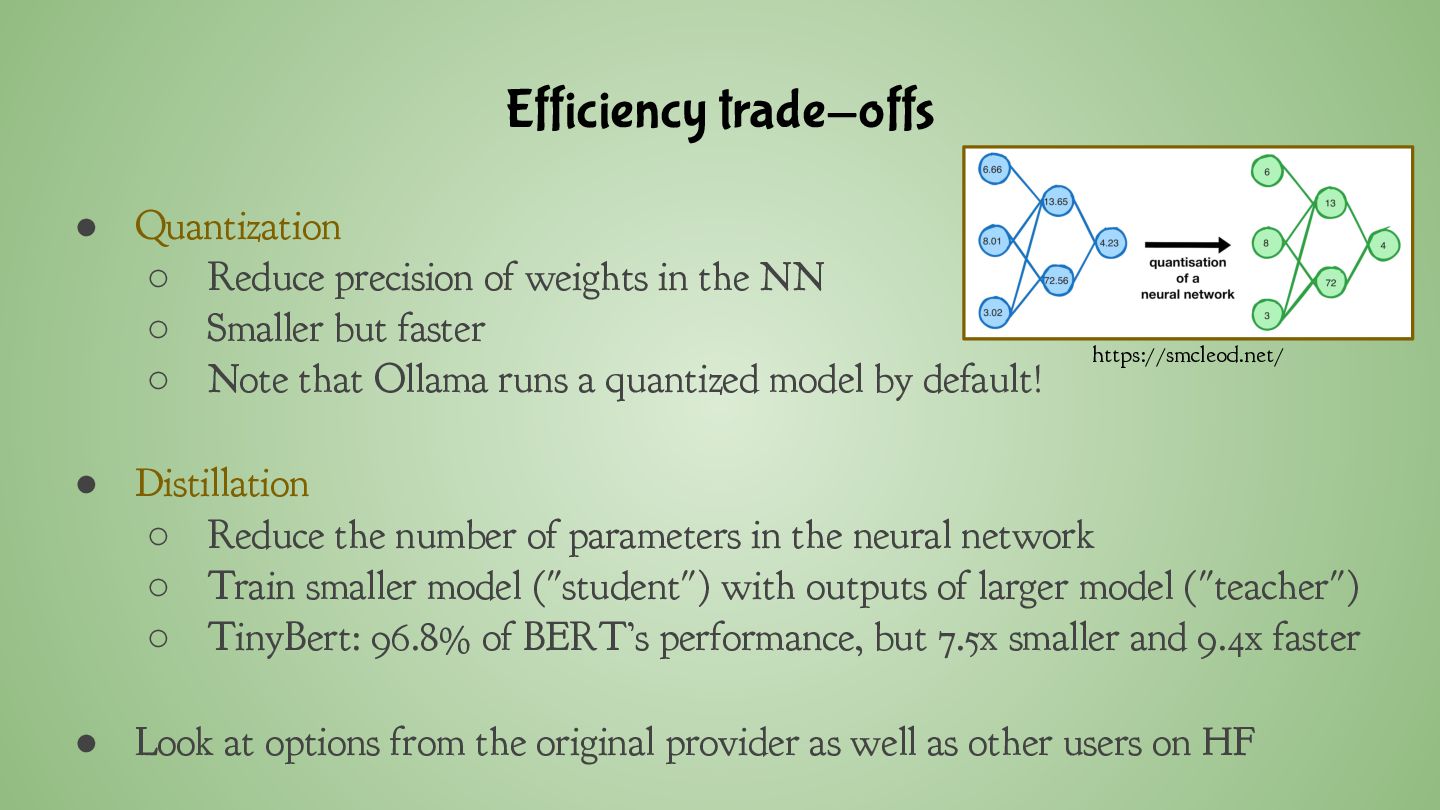
Efficiency trade-offs • Quantization ◦ Reduce precision of weights in
the NN ◦ Smaller but faster ◦ Note that Ollama runs a quantized model by default! • Distillation ◦ Reduce the number of parameters in the neural network ◦ Train smaller model ("student") with outputs of larger model ("teacher") ◦ TinyBert: 96.8% of BERT’s performance, but 7.5x smaller and 9.4x faster • Look at options from the original provider as well as other users on HF https://smcleod.net/ -
Mamba • State spaces instead of Attention • Use-cases for
Mamba ◦ Uses less memory ◦ More efficient for long sequences ◦ Summarization and chatting with long documents • Use-cases for Transformers ◦ Accurately capture complex relations ◦ Deep contextual understanding, code generation, Math • Mamba/Transformer hybrid architectures: ◦ Hunyuan Turbo S / T1 (also MoE) ◦ Falcon-H1 -
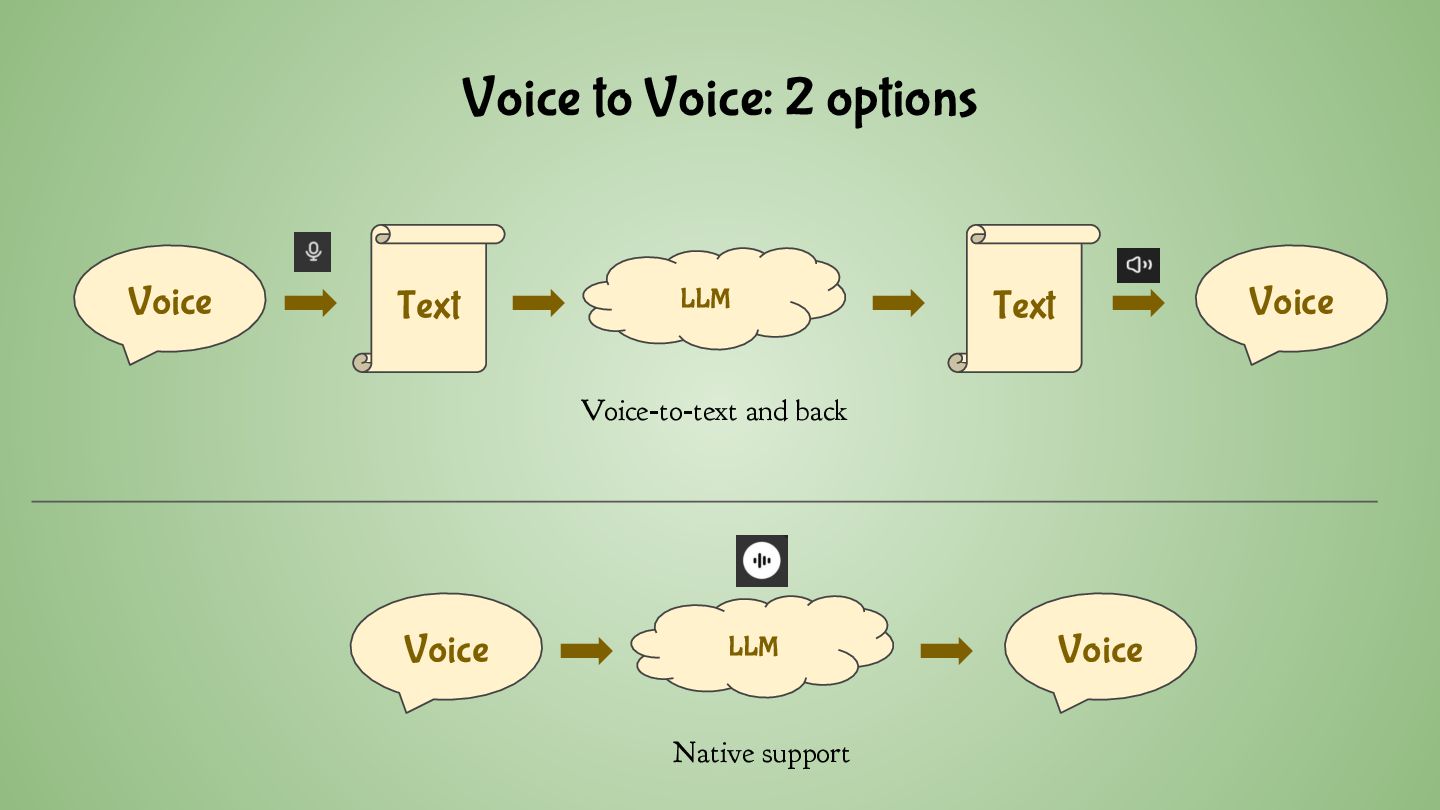
Voice to Voice: 2 options LLM Voice Text Text Voice
LLM Voice Voice Native support Voice-to-text and back -
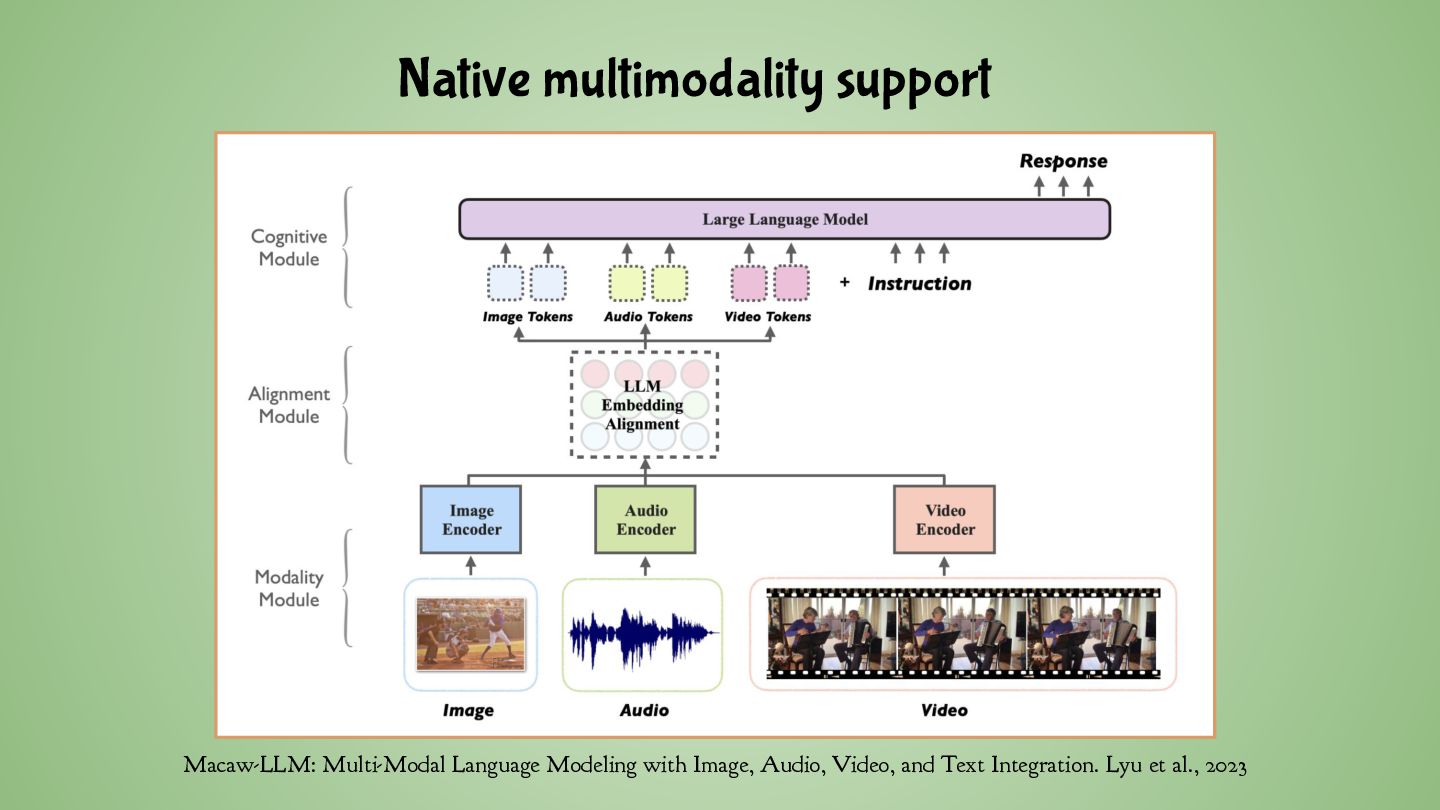
Native multimodality support Macaw-LLM: Multi-Modal Language Modeling with Image, Audio,
Video, and Text Integration. Lyu et al., 2023 -
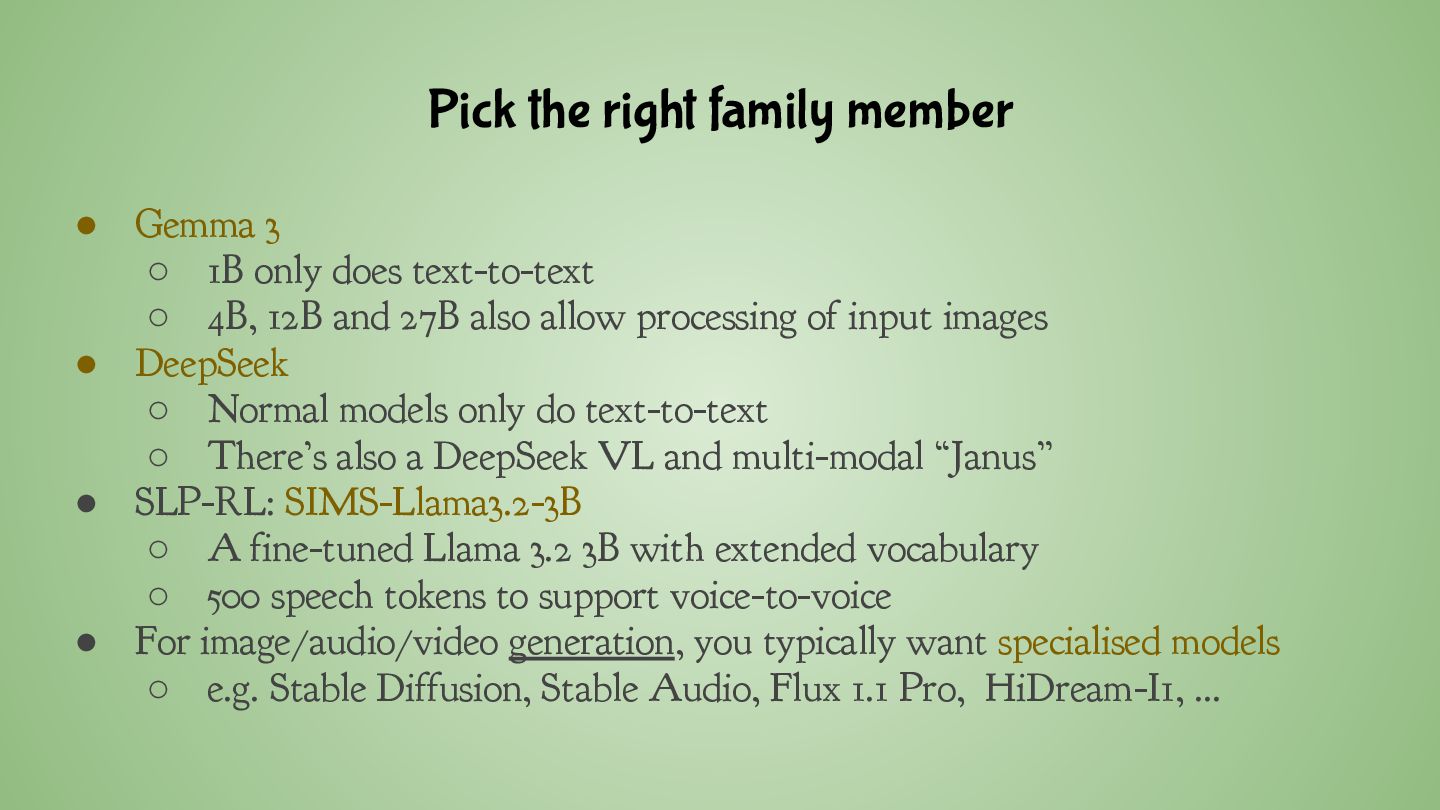
Pick the right family member • Gemma 3 ◦ 1B
only does text-to-text ◦ 4B, 12B and 27B also allow processing of input images • DeepSeek ◦ Normal models only do text-to-text ◦ There’s also a DeepSeek VL and multi-modal “Janus” • SLP-RL: SIMS-Llama3.2-3B ◦ A fine-tuned Llama 3.2 3B with extended vocabulary ◦ 500 speech tokens to support voice-to-voice • For image/audio/video generation, you typically want specialised models ◦ e.g. Stable Diffusion, Stable Audio, Flux 1.1 Pro, HiDream-I1, ... -
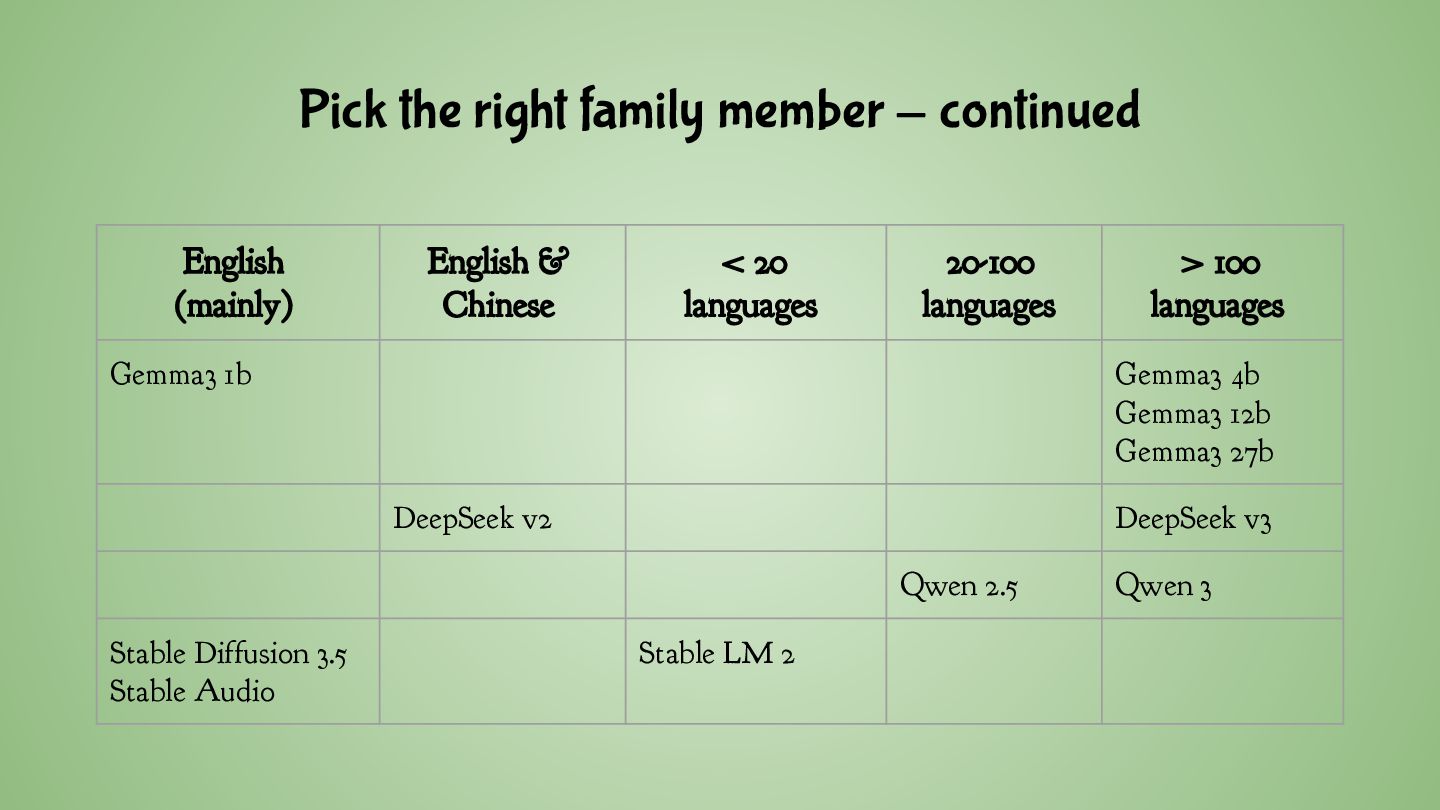
Pick the right family member - continued English (mainly) English
& Chinese < 20 languages 20-100 languages > 100 languages Gemma3 1b Gemma3 4b Gemma3 12b Gemma3 27b DeepSeek v2 DeepSeek v3 Qwen 2.5 Qwen 3 Stable Diffusion 3.5 Stable Audio Stable LM 2 -
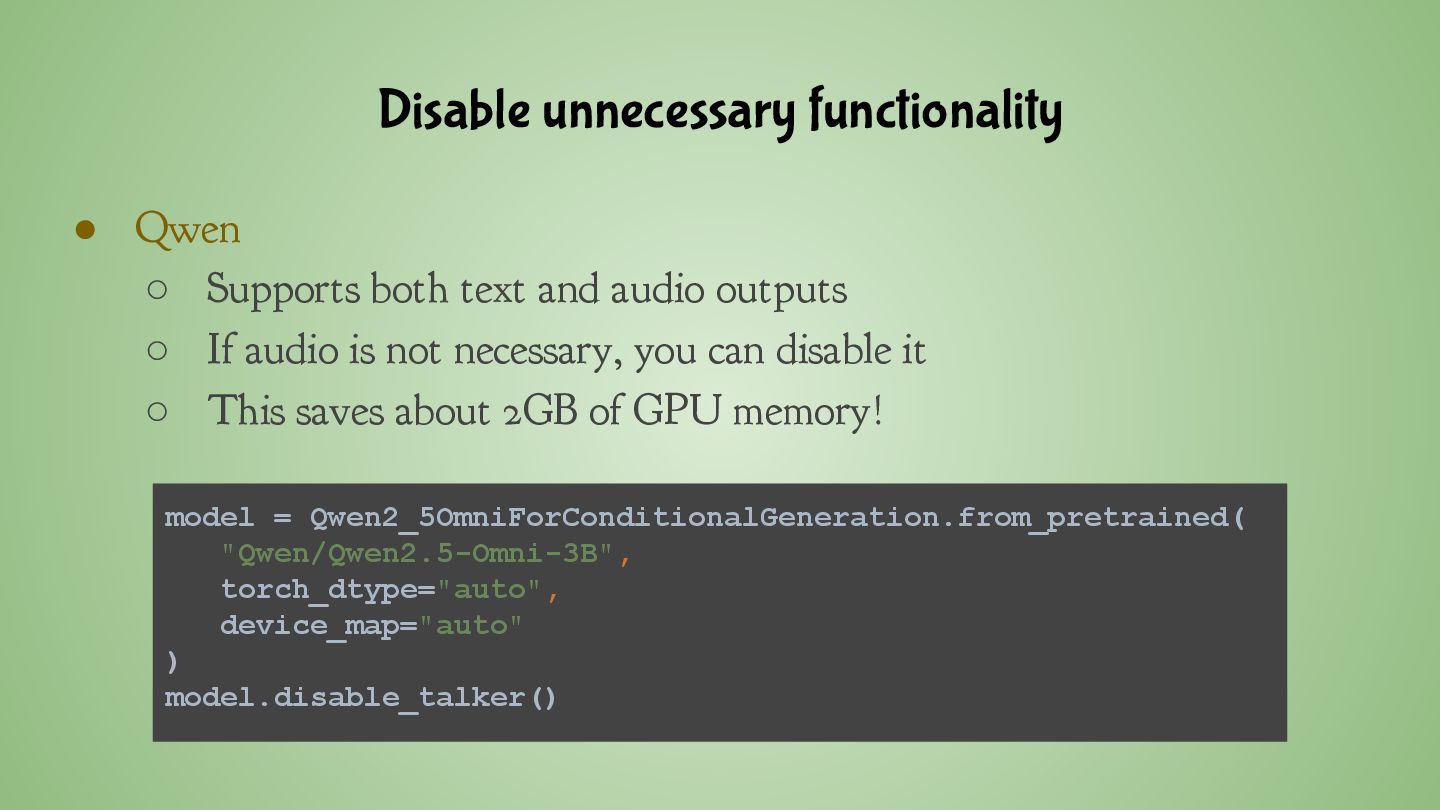
Disable unnecessary functionality • Qwen ◦ Supports both text and
audio outputs ◦ If audio is not necessary, you can disable it ◦ This saves about 2GB of GPU memory! model = Qwen2_5OmniForConditionalGeneration.from_pretrained( "Qwen/Qwen2.5-Omni-3B", torch_dtype="auto", device_map="auto" ) model.disable_talker() -
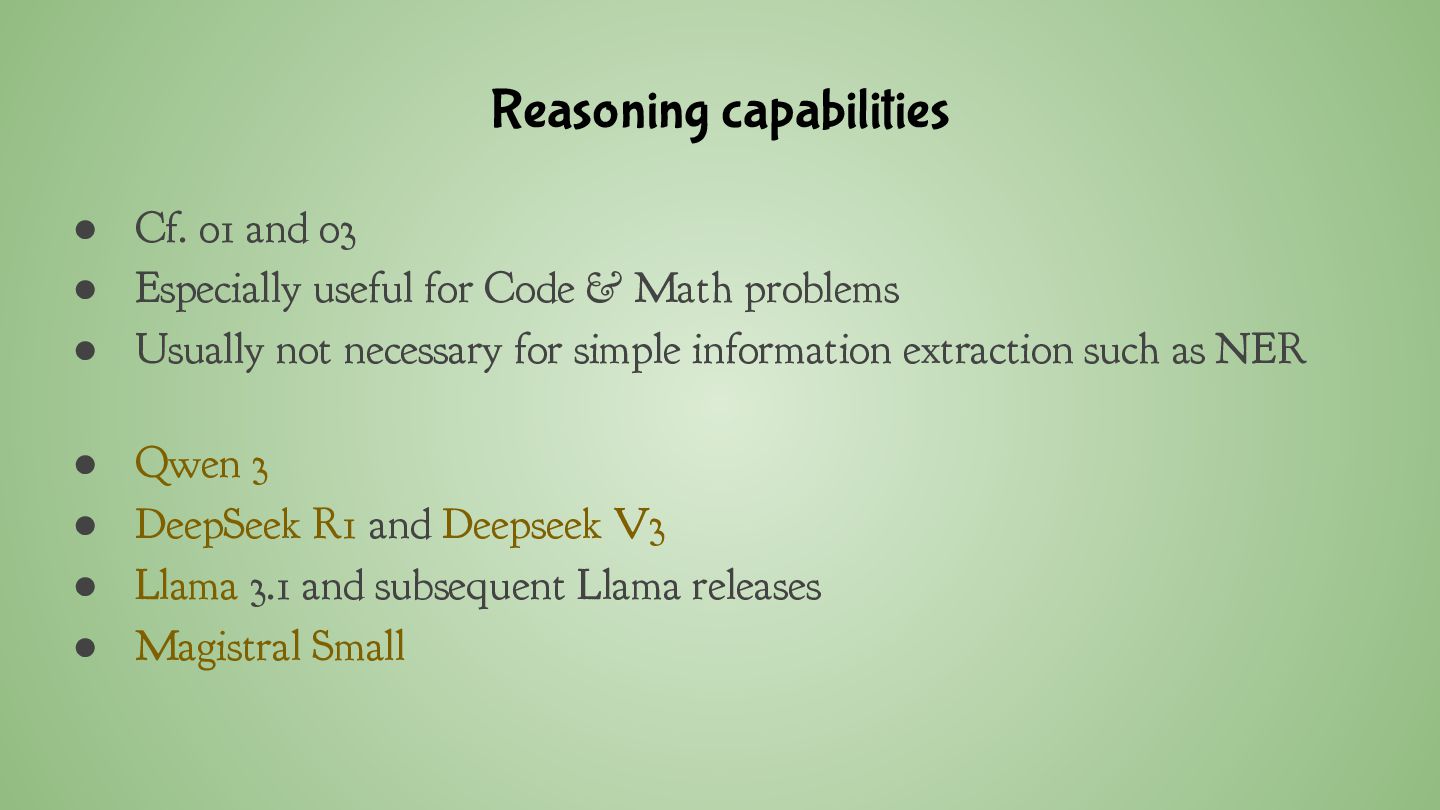
Reasoning capabilities • Cf. o1 and o3 • Especially useful
for Code & Math problems • Usually not necessary for simple information extraction such as NER • Qwen 3 • DeepSeek R1 and Deepseek V3 • Llama 3.1 and subsequent Llama releases • Magistral Small -
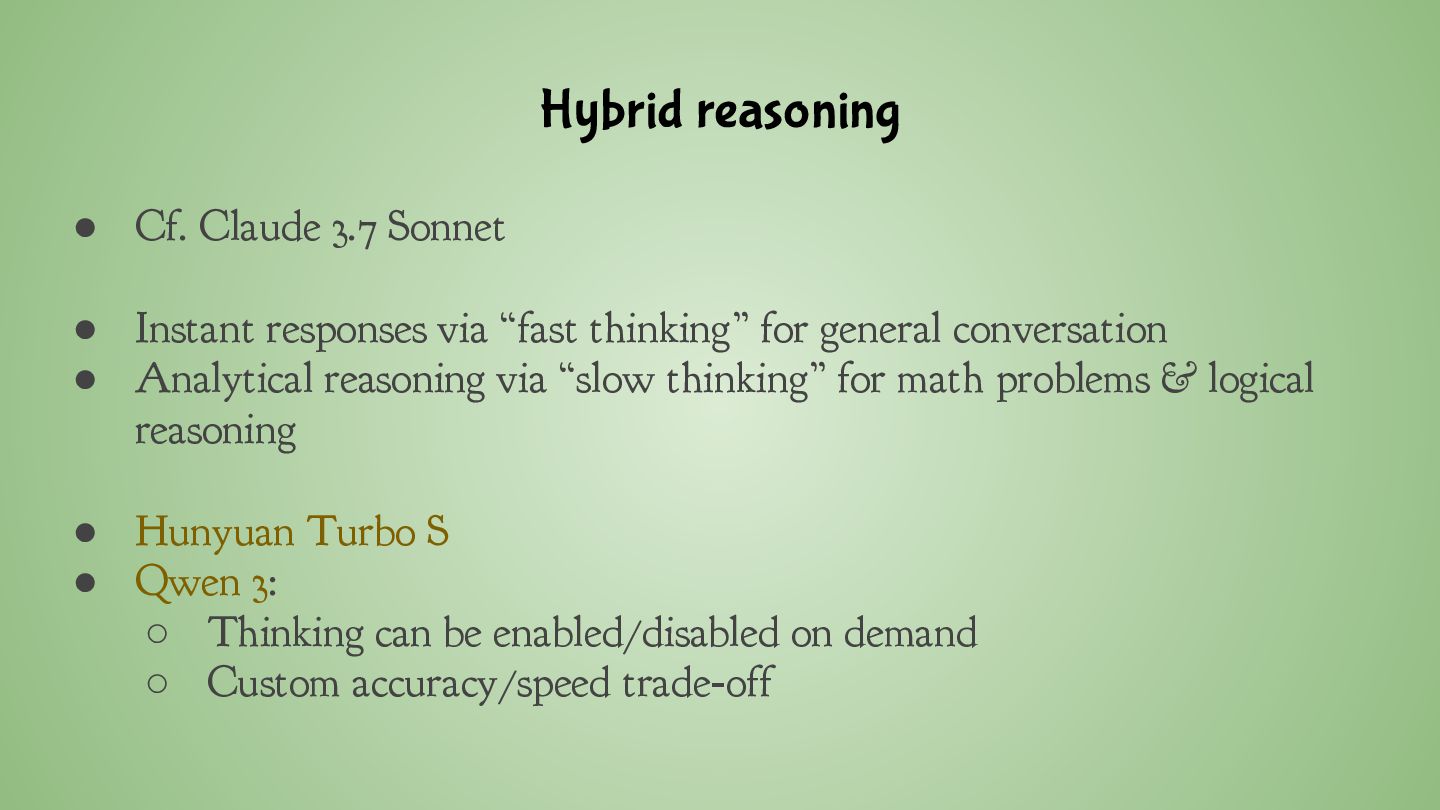
Hybrid reasoning • Cf. Claude 3.7 Sonnet • Instant responses
via “fast thinking” for general conversation • Analytical reasoning via “slow thinking” for math problems & logical reasoning • Hunyuan Turbo S • Qwen 3: ◦ Thinking can be enabled/disabled on demand ◦ Custom accuracy/speed trade-off -
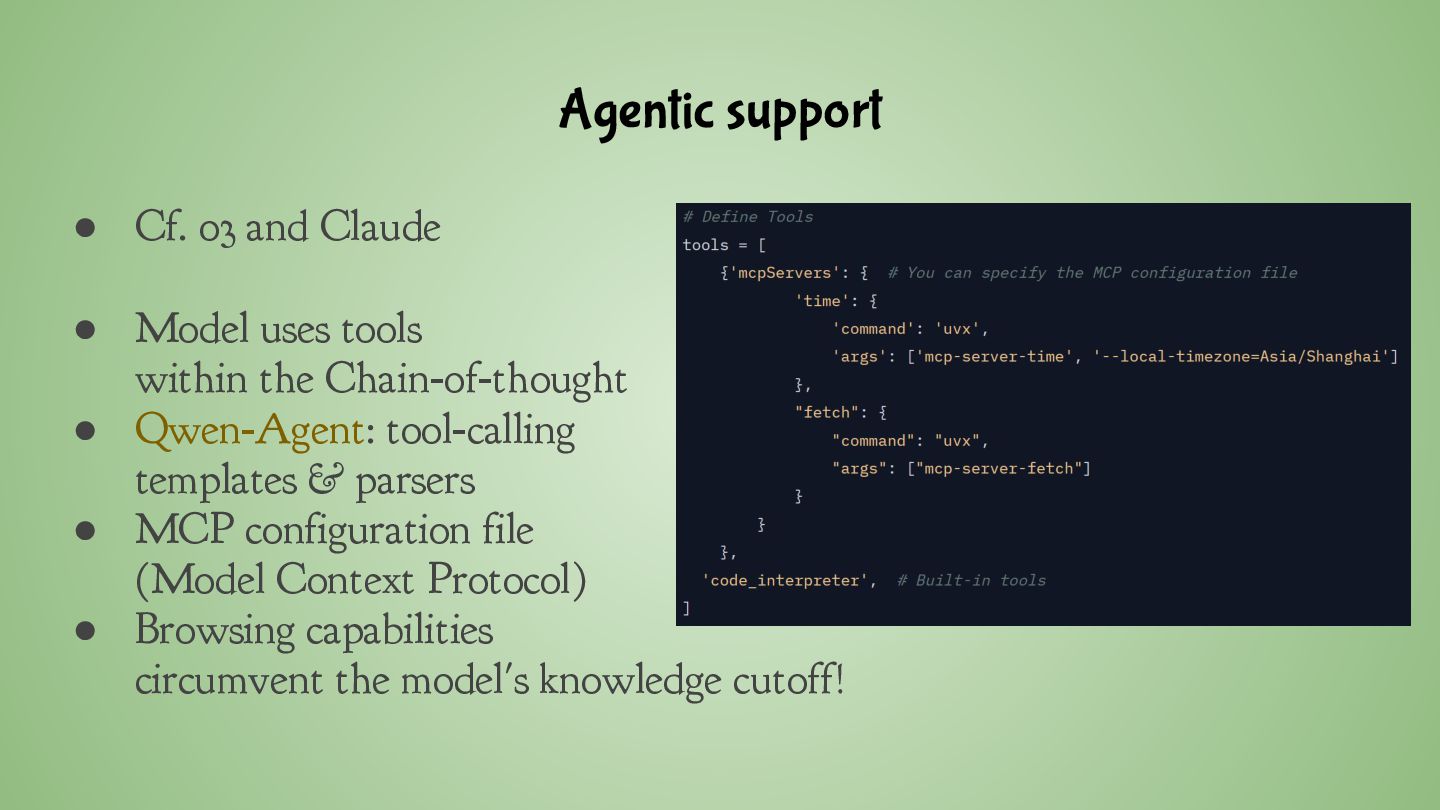
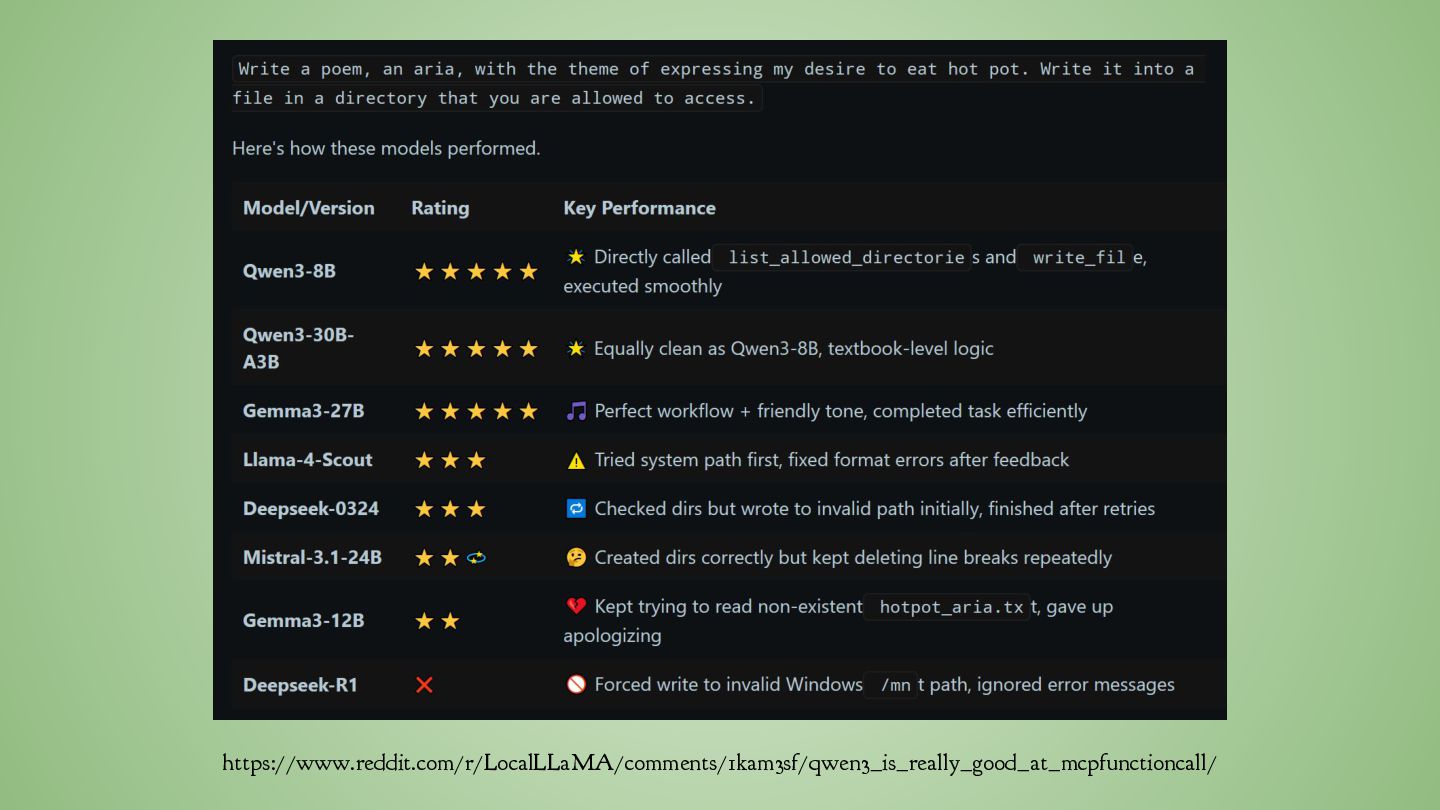
Agentic support • Cf. o3 and Claude • Model uses
tools within the Chain-of-thought • Qwen-Agent: tool-calling templates & parsers • MCP configuration file (Model Context Protocol) • Browsing capabilities circumvent the model's knowledge cutoff! -
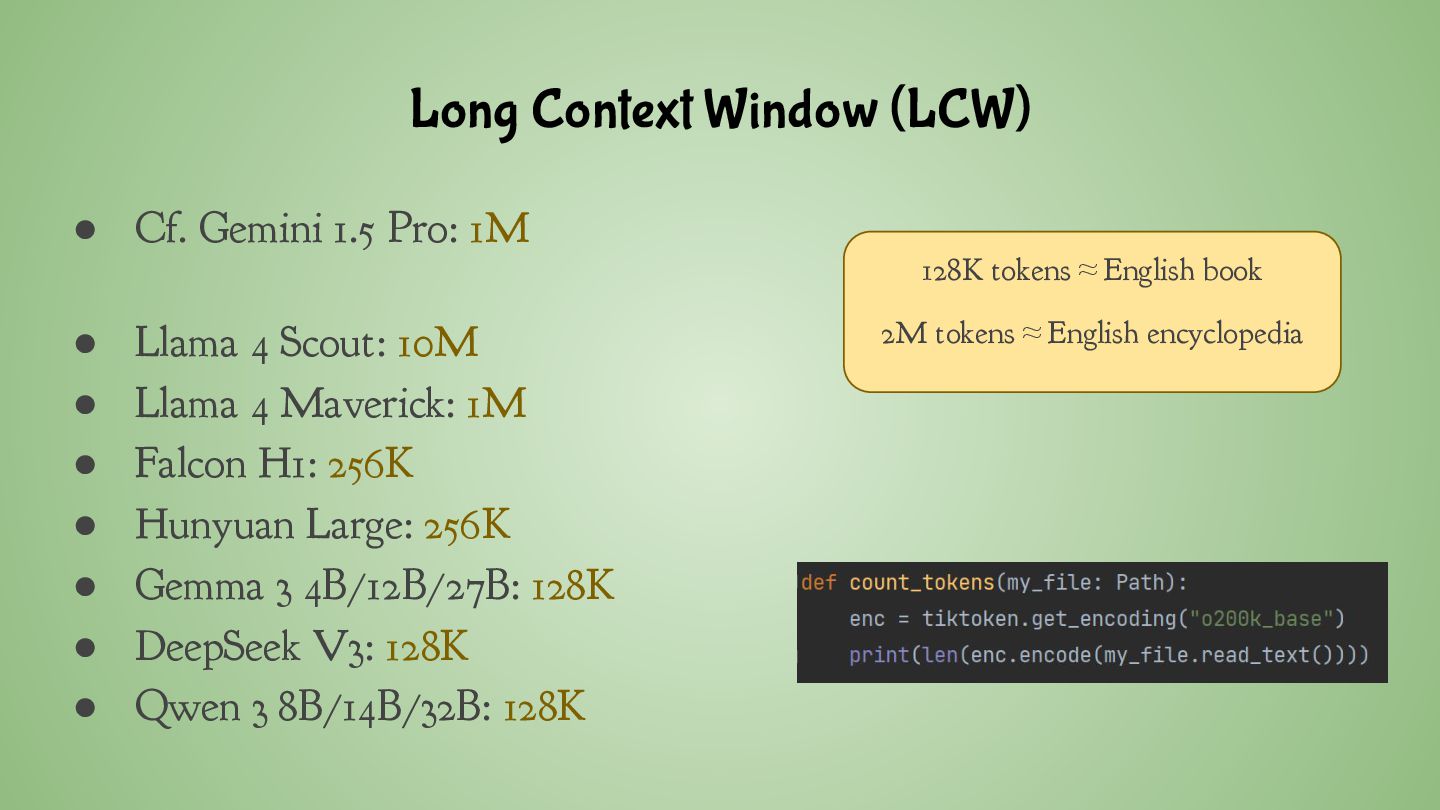
Long Context Window (LCW) • Cf. Gemini 1.5 Pro: 1M
• Llama 4 Scout: 10M • Llama 4 Maverick: 1M • Falcon H1: 256K • Hunyuan Large: 256K • Gemma 3 4B/12B/27B: 128K • DeepSeek V3: 128K • Qwen 3 8B/14B/32B: 128K 128K tokens ≈ English book 2M tokens ≈ English encyclopedia -
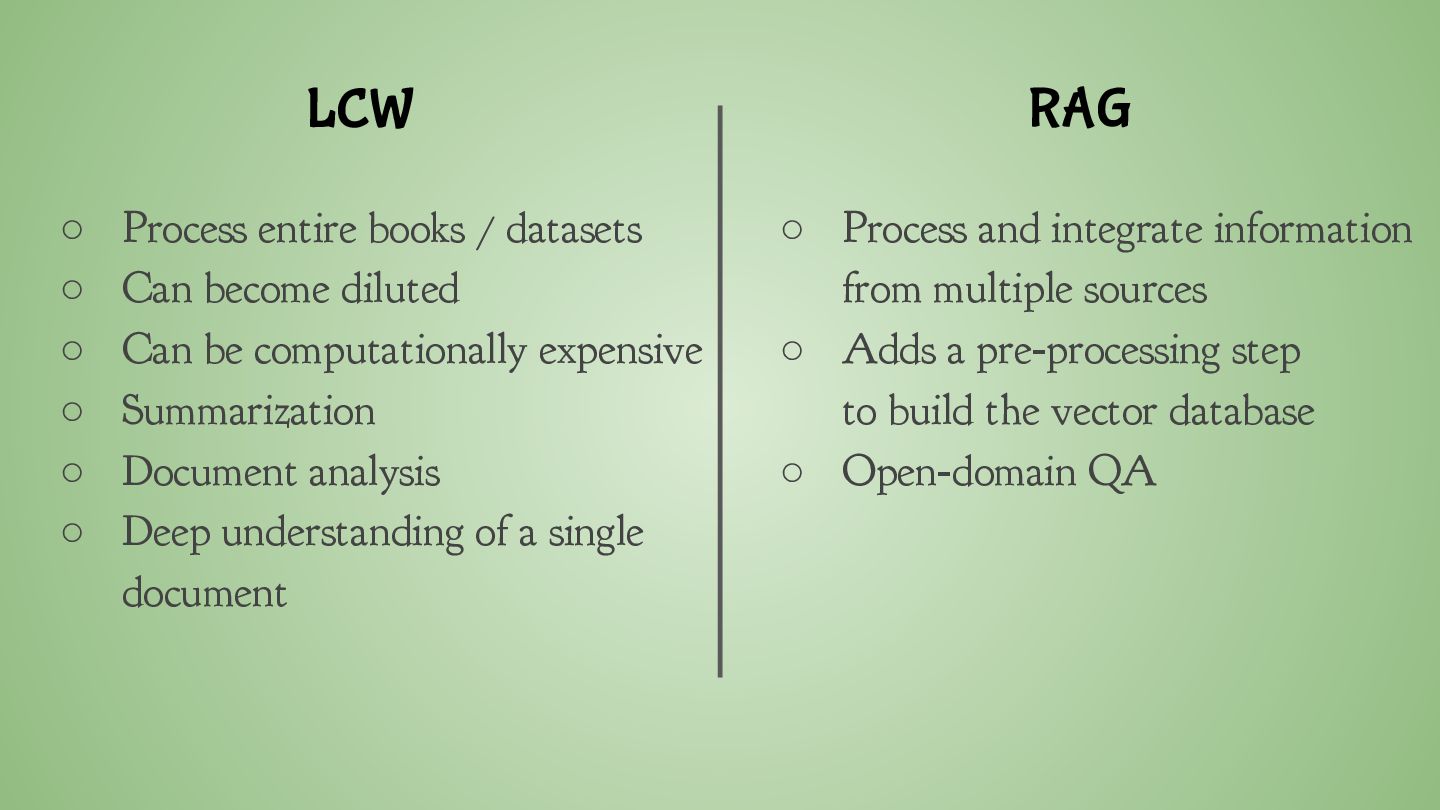
LCW RAG ◦ Process entire books / datasets ◦ Can
become diluted ◦ Can be computationally expensive ◦ Summarization ◦ Document analysis ◦ Deep understanding of a single document ◦ Process and integrate information from multiple sources ◦ Adds a pre-processing step to build the vector database ◦ Open-domain QA -
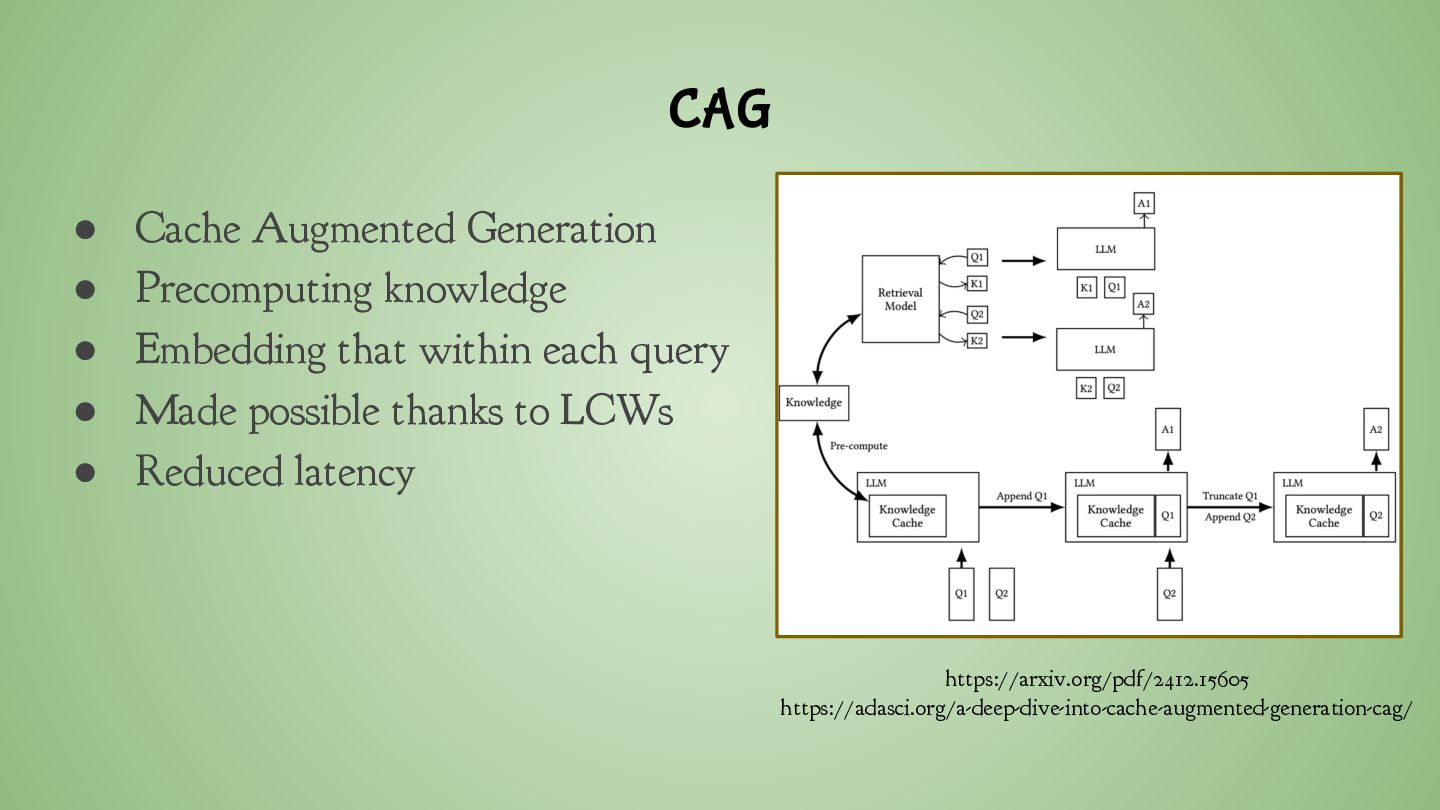
CAG • Cache Augmented Generation • Precomputing knowledge • Embedding
that within each query • Made possible thanks to LCWs • Reduced latency https://arxiv.org/pdf/2412.15605 https://adasci.org/a-deep-dive-into-cache-augmented-generation-cag/ -
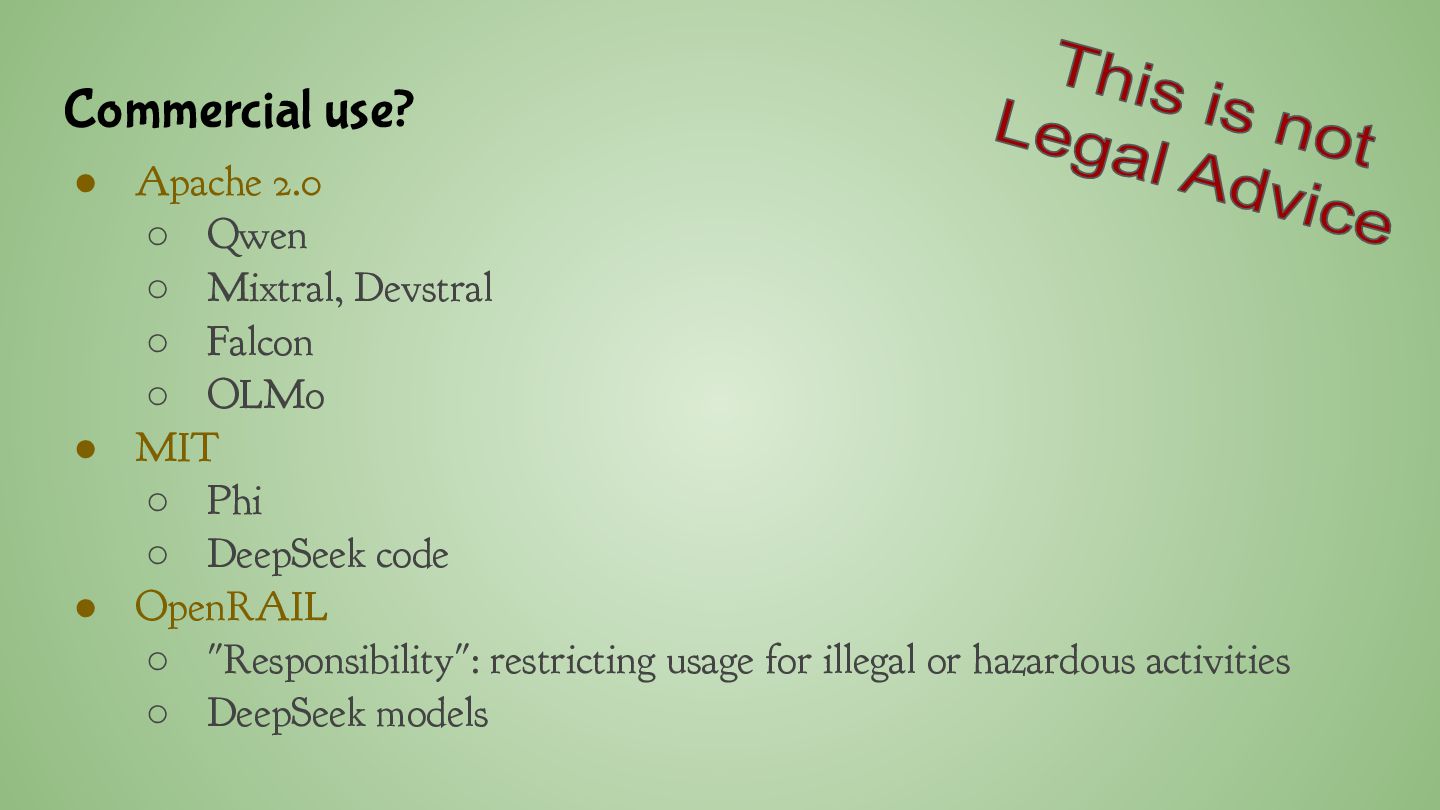
Commercial use? • Apache 2.0 ◦ Qwen ◦ Mixtral, Devstral
◦ Falcon ◦ OLMo • MIT ◦ Phi ◦ DeepSeek code • OpenRAIL ◦ "Responsibility": restricting usage for illegal or hazardous activities ◦ DeepSeek models -
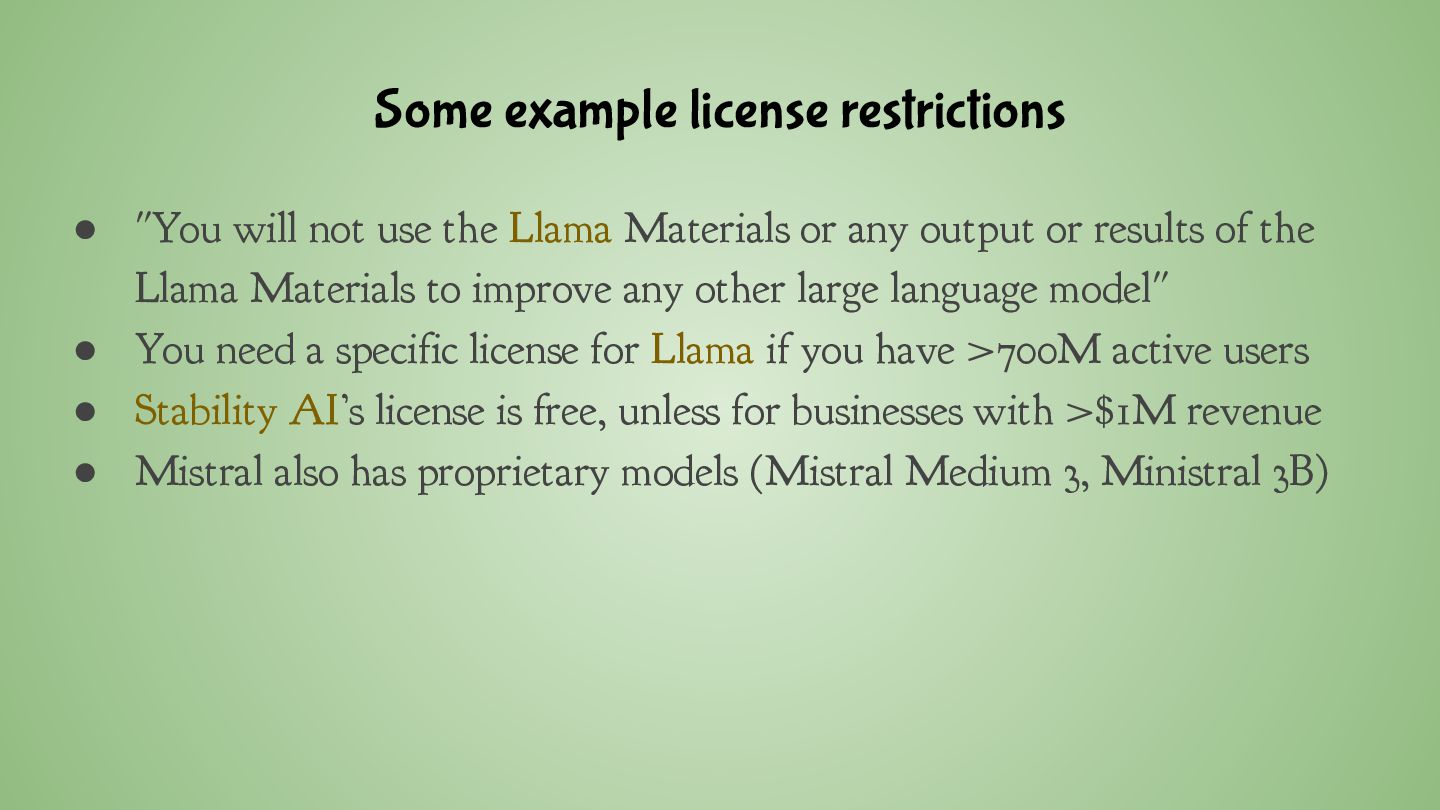
Some example license restrictions • "You will not use the
Llama Materials or any output or results of the Llama Materials to improve any other large language model" • You need a specific license for Llama if you have >700M active users • Stability AI’s license is free, unless for businesses with >$1M revenue • Mistral also has proprietary models (Mistral Medium 3, Ministral 3B) -
Data license ?! • It is not always clear what
kind of data has been trained on • Example: StableLM Base Alpha ◦ Published under a commercial license ◦ Partially fine-tuned on data prohibiting commercial usage • This is especially problematic with image generation models • As a commercial user, are you at risk? • Do you want to be better safe than sorry? -
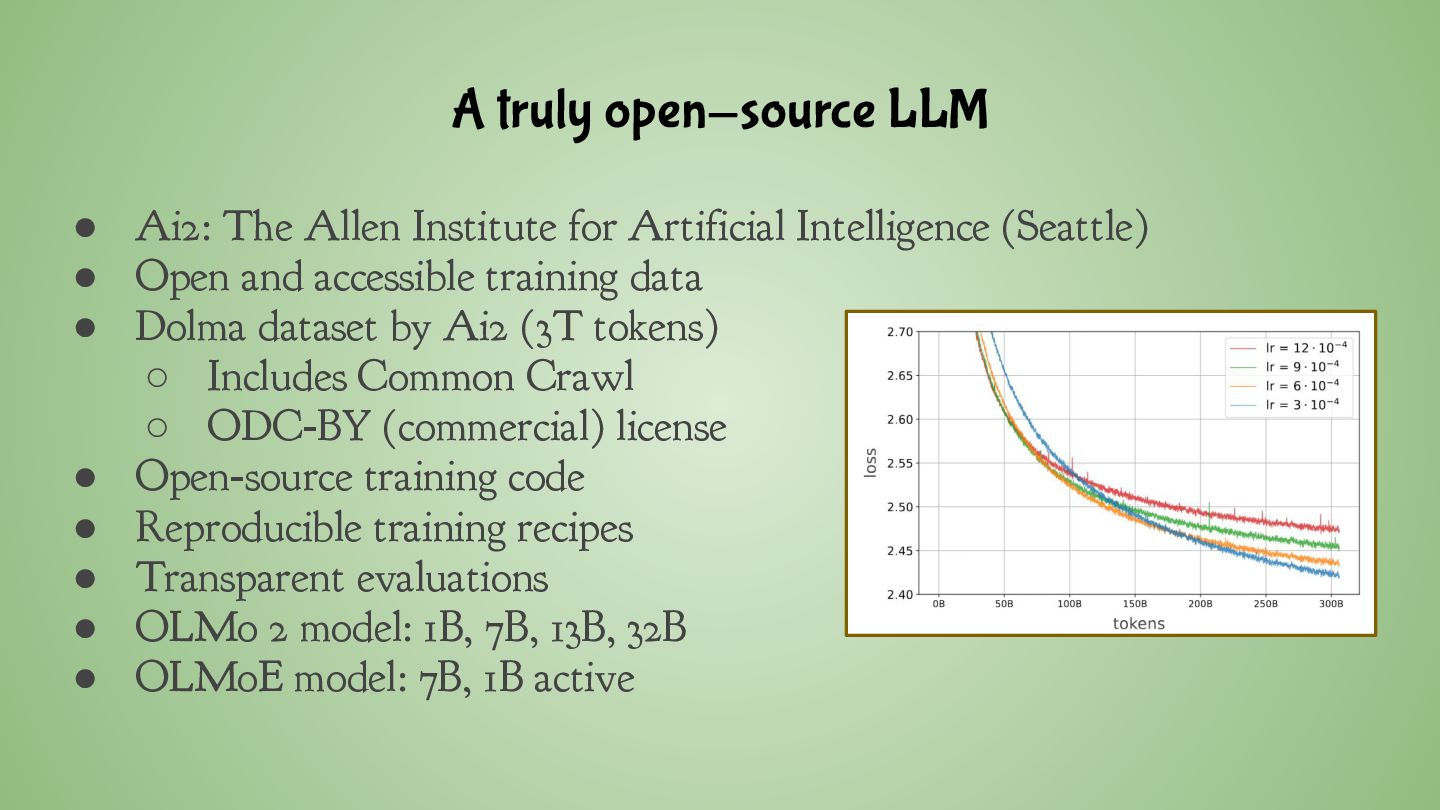
A truly open-source LLM • Ai2: The Allen Institute for
Artificial Intelligence (Seattle) • Open and accessible training data • Dolma dataset by Ai2 (3T tokens) ◦ Includes Common Crawl ◦ ODC-BY (commercial) license • Open-source training code • Reproducible training recipes • Transparent evaluations • OLMo 2 model: 1B, 7B, 13B, 32B • OLMoE model: 7B, 1B active -
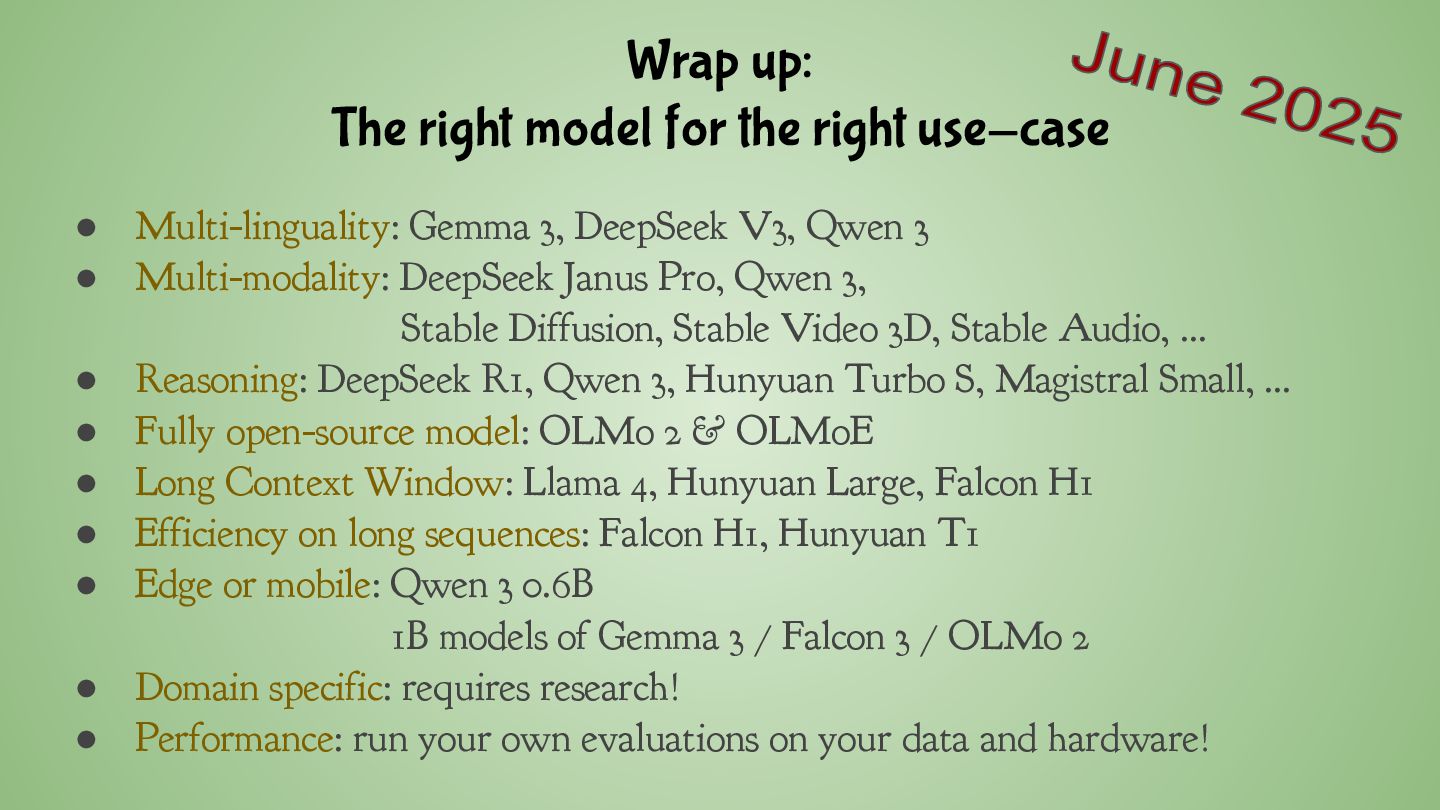
Wrap up: The right model for the right use-case •
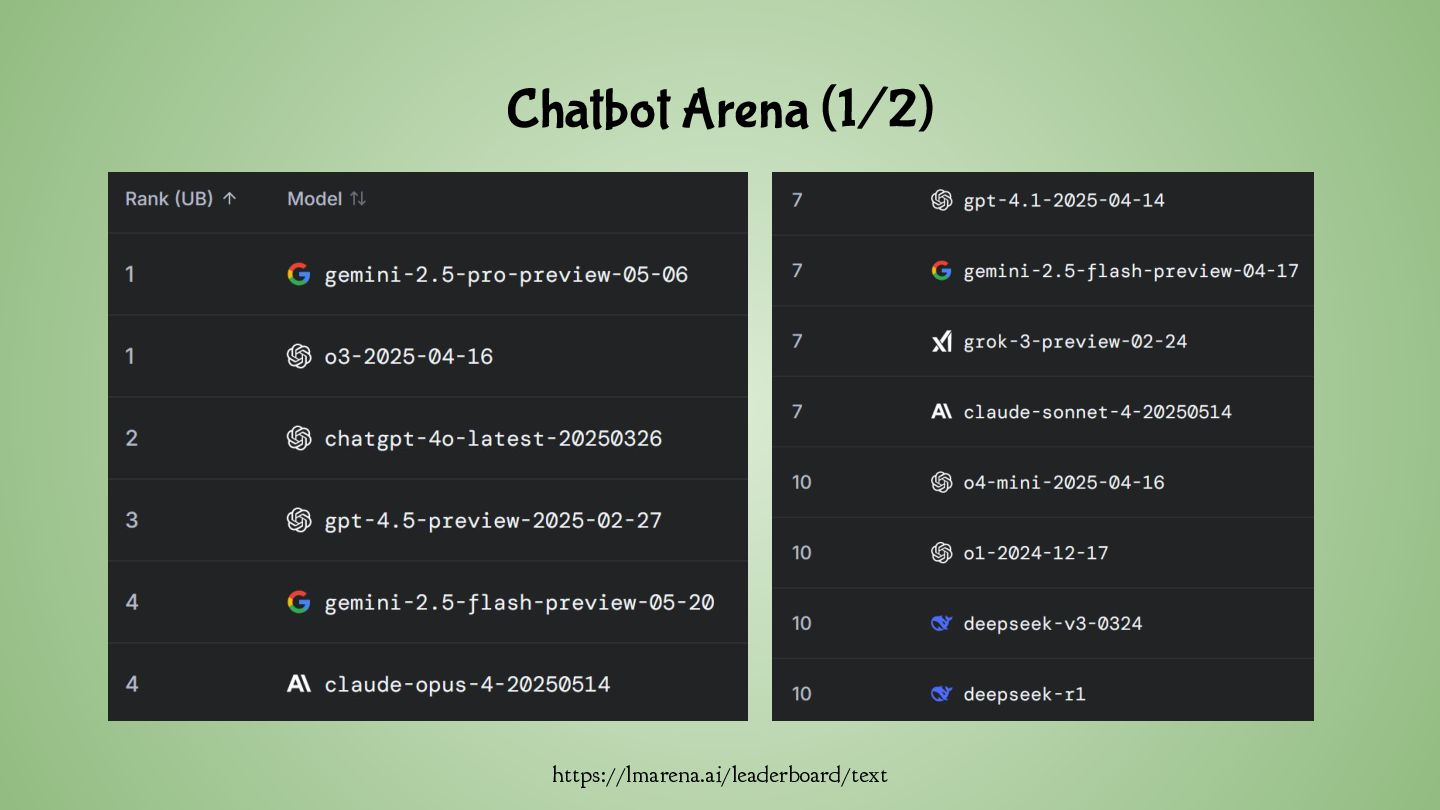
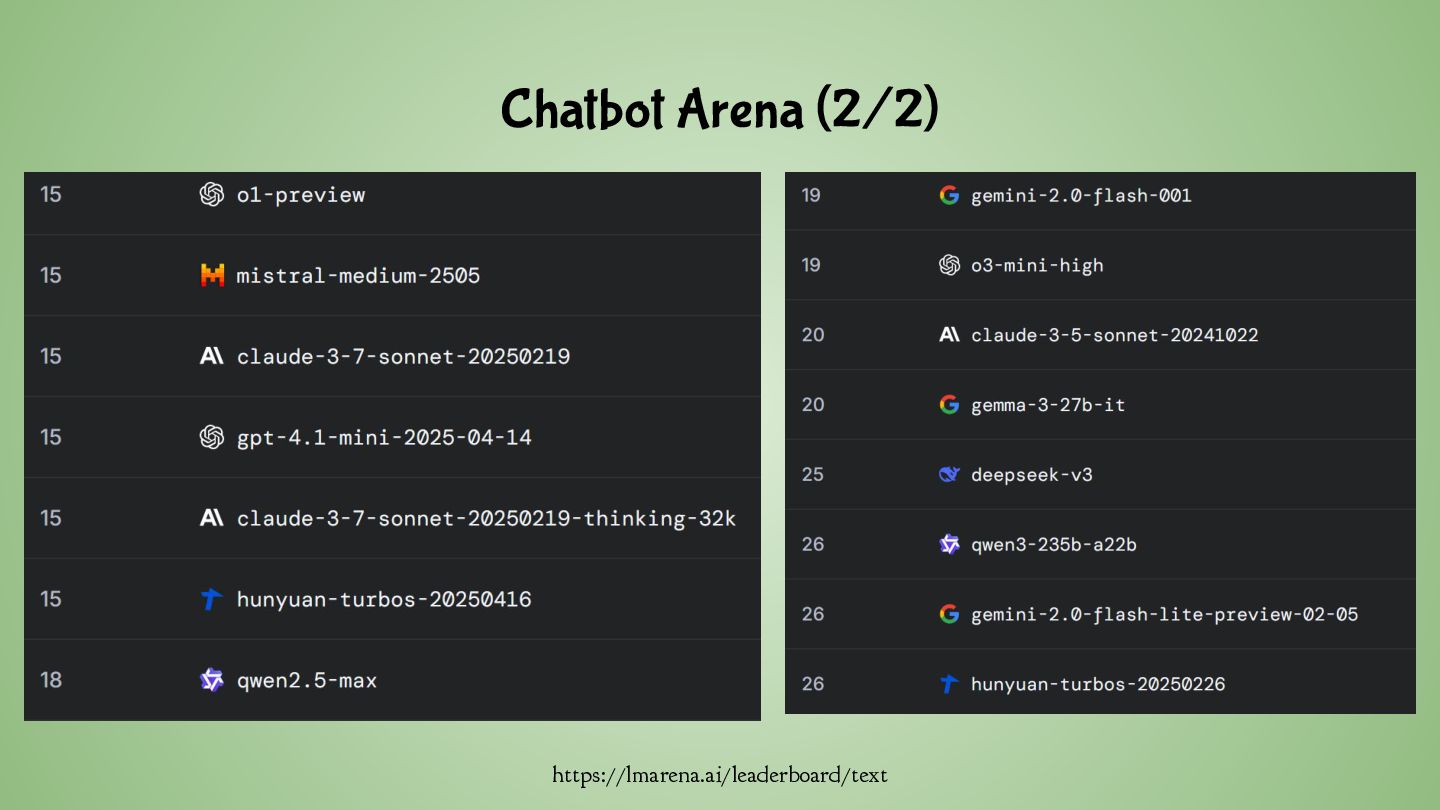
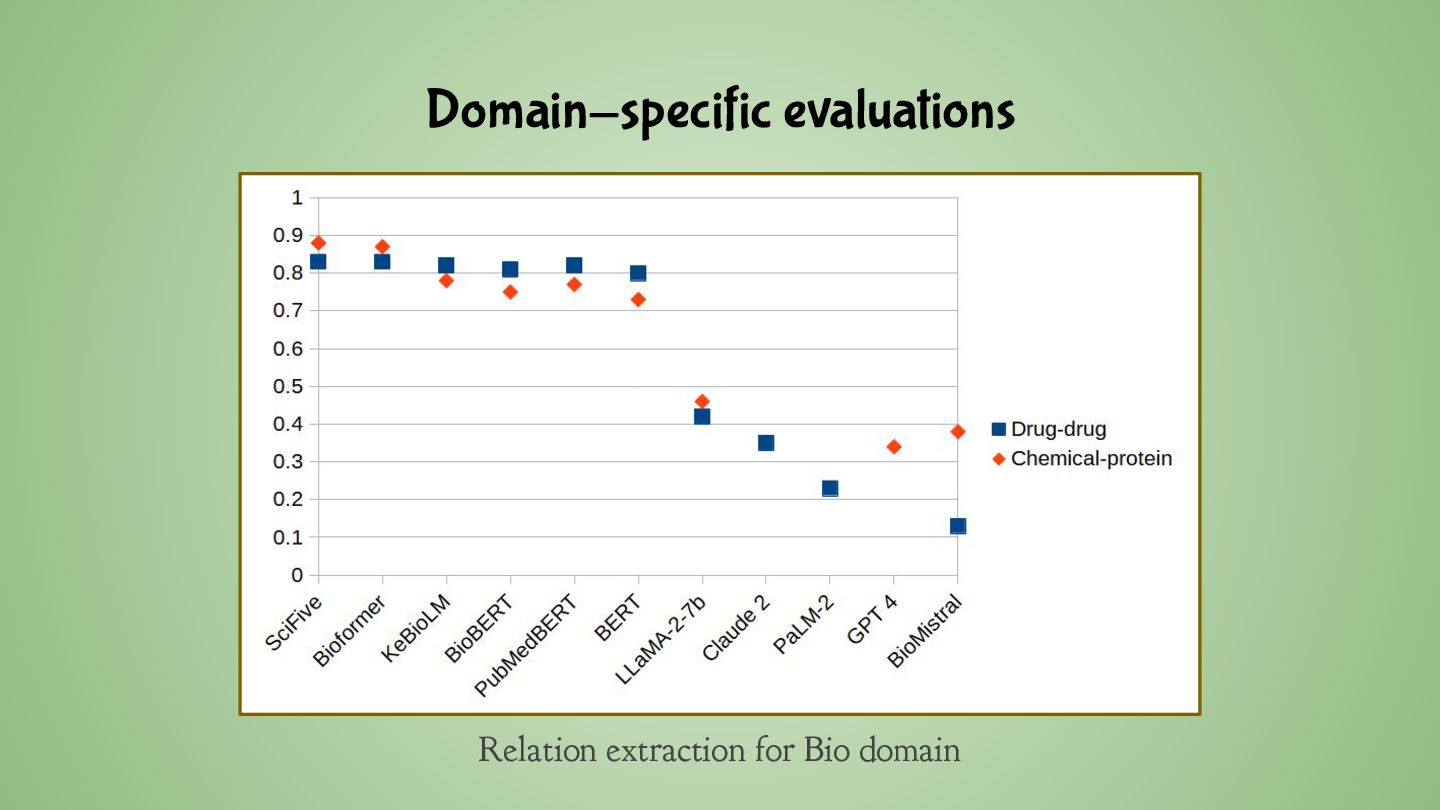
Multi-linguality: Gemma 3, DeepSeek V3, Qwen 3 • Multi-modality: DeepSeek Janus Pro, Qwen 3, Stable Diffusion, Stable Video 3D, Stable Audio, … • Reasoning: DeepSeek R1, Qwen 3, Hunyuan Turbo S, Magistral Small, … • Fully open-source model: OLMo 2 & OLMoE • Long Context Window: Llama 4, Hunyuan Large, Falcon H1 • Efficiency on long sequences: Falcon H1, Hunyuan T1 • Edge or mobile: Qwen 3 0.6B 1B models of Gemma 3 / Falcon 3 / OLMo 2 • Domain specific: requires research! • Performance: run your own evaluations on your data and hardware! -
Github repo's • DeepSeek: https://github.com/deepseek-ai • Gemma: https://github.com/google-deepmind/gemma • Hunyuan:
https://github.com/Tencent-Hunyuan • Llama: https://github.com/meta-llama/llama-models • Mistral: https://github.com/mistralai • OLMo: https://github.com/allenai/OLMo • Qwen: https://github.com/QwenLM/ • Stability AI: https://github.com/stability-ai • TII: https://github.com/tiiuae -
Technical reports • DeepSeek Janus Pro: https://arxiv.org/pdf/2501.17811 • DeepSeek V3:
https://arxiv.org/pdf/2412.19437 • Falcon 3: https://huggingface.co/blog/falcon3 • Gemma 3: https://arxiv.org/pdf/2503.19786 • Hunyuan Large: https://arxiv.org/pdf/2411.02265v1 • Hunyuan TurboS: https://arxiv.org/pdf/2505.15431 • Llama 2: https://arxiv.org/pdf/2307.09288 • Mistral 7B: https://arxiv.org/pdf/2310.06825 • OLMo 2: https://arxiv.org/pdf/2501.00656 • Phi 4: https://arxiv.org/pdf/2412.08905 • Qwen 3: https://arxiv.org/pdf/2505.09388 • Stable LM 2: https://arxiv.org/pdf/2402.17834 • Stable Diffusion 3: https://arxiv.org/pdf/2403.03206