Share
Embed
Transcript
30 slides
-
Design & Implementation of a Beowulf Class Cluster A Presentation
By Venu Gopal Kakarla (2005A7PS124U) For BITS C 331 - Computer Project -
What is a Beowulf? The nodes are dedicated to
the beowulf. The network is dedicated to the beowulf. The nodes are mass market commodity off the shelf (MMCOTS) computers. Nodes are relatively inexpensive hardware. The network is also a COTS entity, eg Standard Ethernet. The nodes all run open source software. The resulting cluster is used for High Performance Computing (HPC), also called parallel supercomputing. -
More Characteristics of a Beowulf. The nodes all run
a variant of GNU/Linux as their base operating system. There is one special node generally called the head or master node. Generally the nodes are all identical i.e have same CPU, motherboard, network, memory, disks. Generally the nodes are all running just one calculation at a time. -
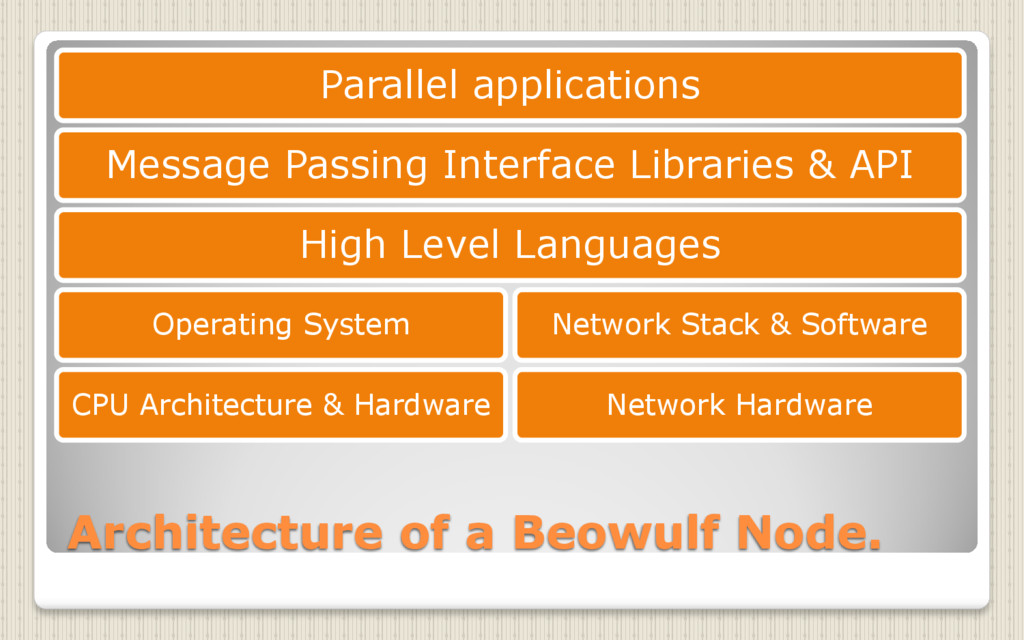
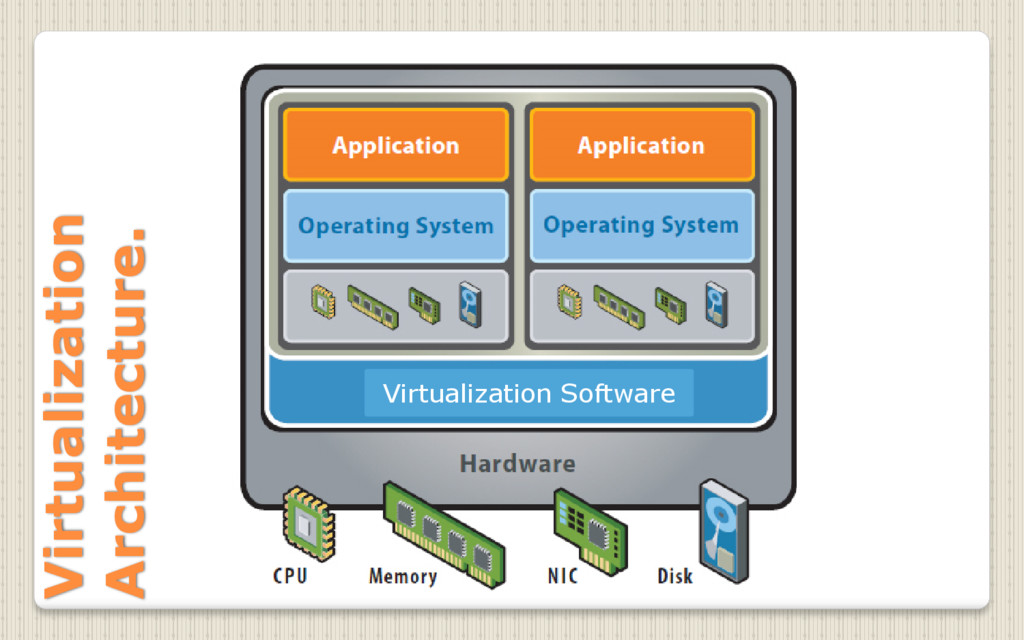
Architecture of a Beowulf Node. Parallel applications Message Passing Interface
Libraries & API High Level Languages Operating System CPU Architecture & Hardware Network Stack & Software Network Hardware -
MPI Routines The MPI standard includes routines for the
following operations: ◦ Point-to-point communication ◦ Collective communications ◦ Process groups ◦ Process topologies ◦ Environment management and inquiry -
MPI Advantages Use MPI when you need: ◦ parallel
code that is portable across platforms ◦ higher performance, e.g. when small-scale "loop- level" parallelism does not provide enough speedup Provide source code portability — MPI programs should compile and run as-is on any platform. Allow efficient implementations across a range of architectures. -
MPI Disadvantages Do not use MPI when you ◦
can achieve sufficient performance and portability by using the "loop level" parallelism available in such software OpenMP. ◦ don't need parallelism at all Dynamic process management — changing the number of processes while the code is running. -
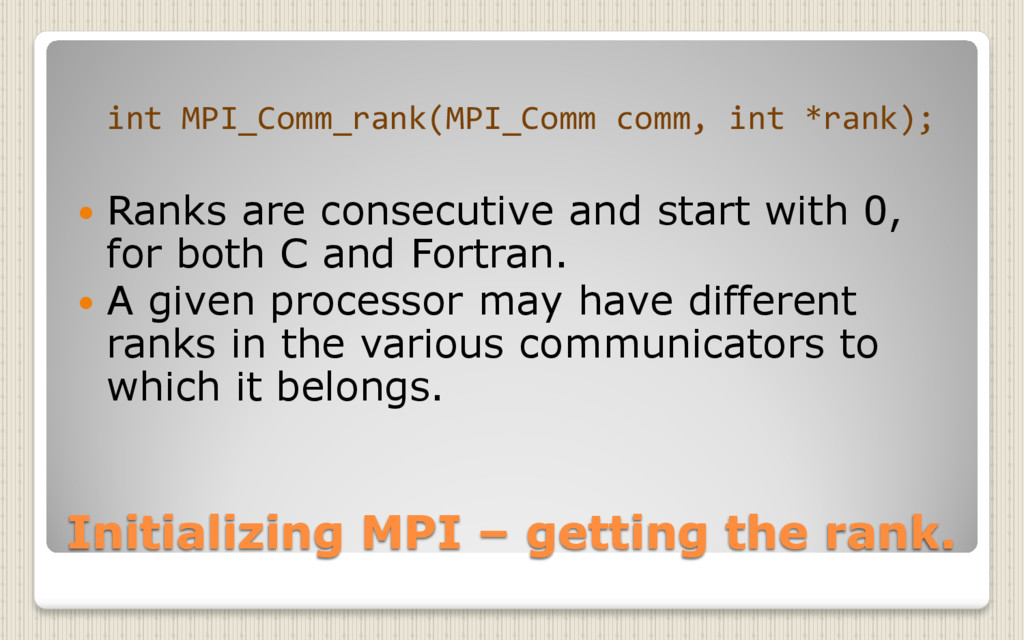
Initializing MPI – getting the rank. int MPI_Comm_rank(MPI_Comm comm, int
*rank); Ranks are consecutive and start with 0, for both C and Fortran. A given processor may have different ranks in the various communicators to which it belongs. -
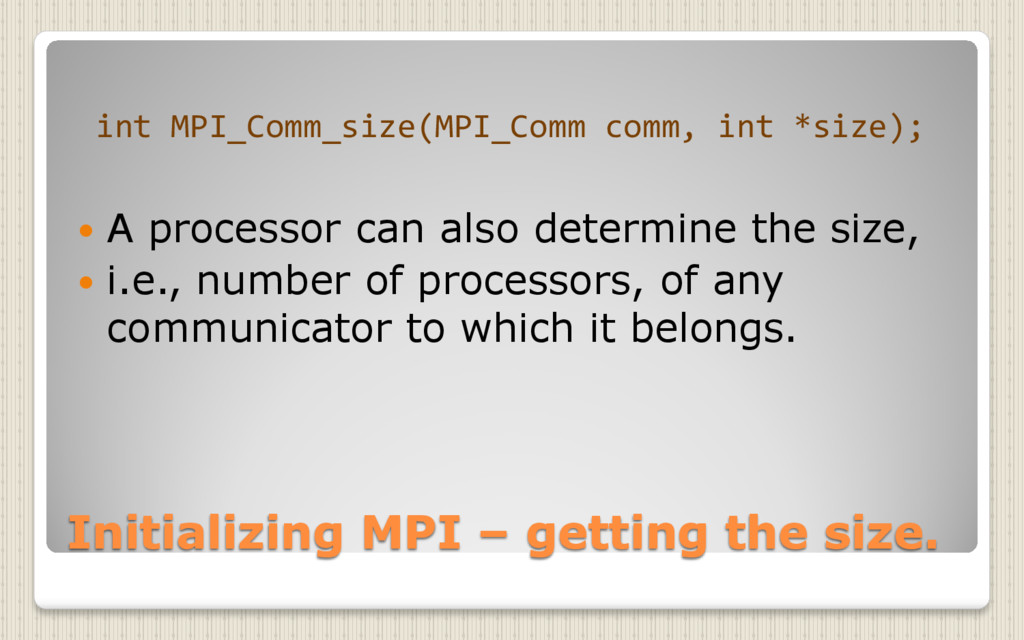
Initializing MPI – getting the size. int MPI_Comm_size(MPI_Comm comm, int
*size); A processor can also determine the size, i.e., number of processors, of any communicator to which it belongs. -
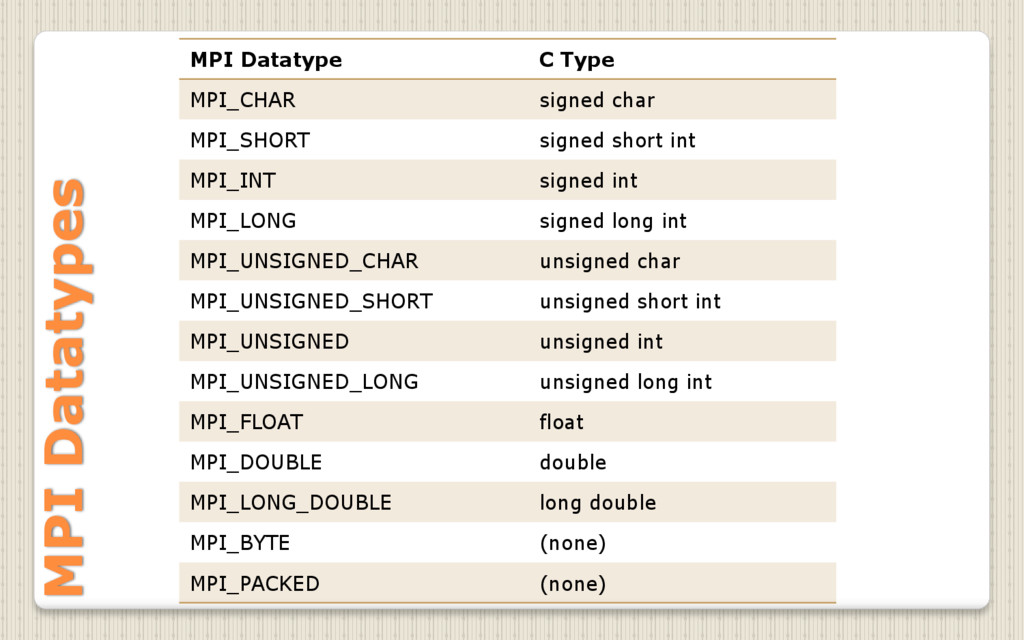
MPI Datatype C Type MPI_CHAR signed char MPI_SHORT signed short
int MPI_INT signed int MPI_LONG signed long int MPI_UNSIGNED_CHAR unsigned char MPI_UNSIGNED_SHORT unsigned short int MPI_UNSIGNED unsigned int MPI_UNSIGNED_LONG unsigned long int MPI_FLOAT float MPI_DOUBLE double MPI_LONG_DOUBLE long double MPI_BYTE (none) MPI_PACKED (none) MPI Datatypes -
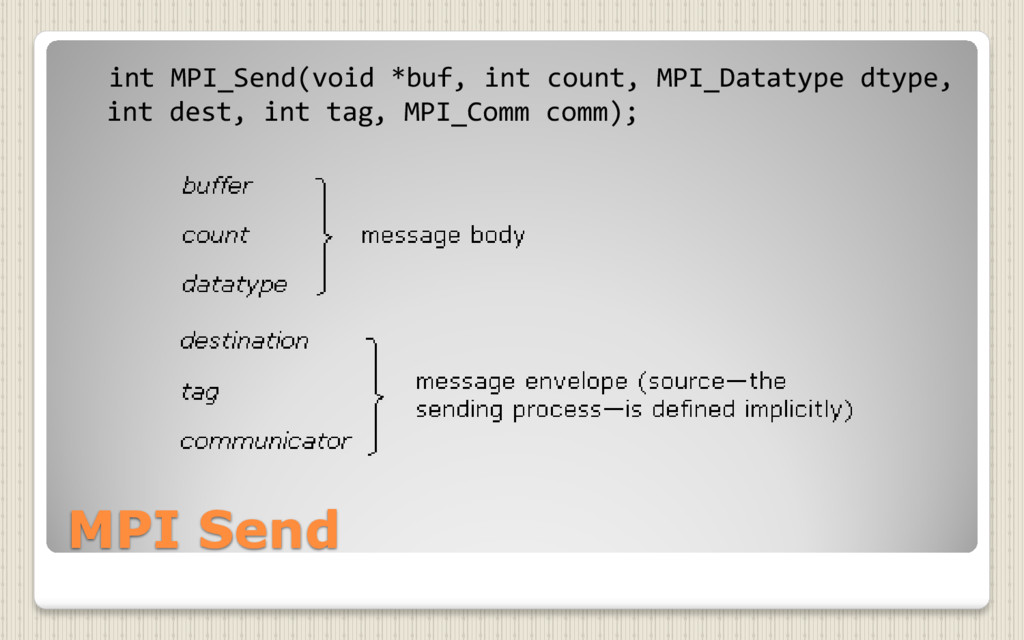
MPI Send int MPI_Send(void *buf, int count, MPI_Datatype dtype, int
dest, int tag, MPI_Comm comm); -
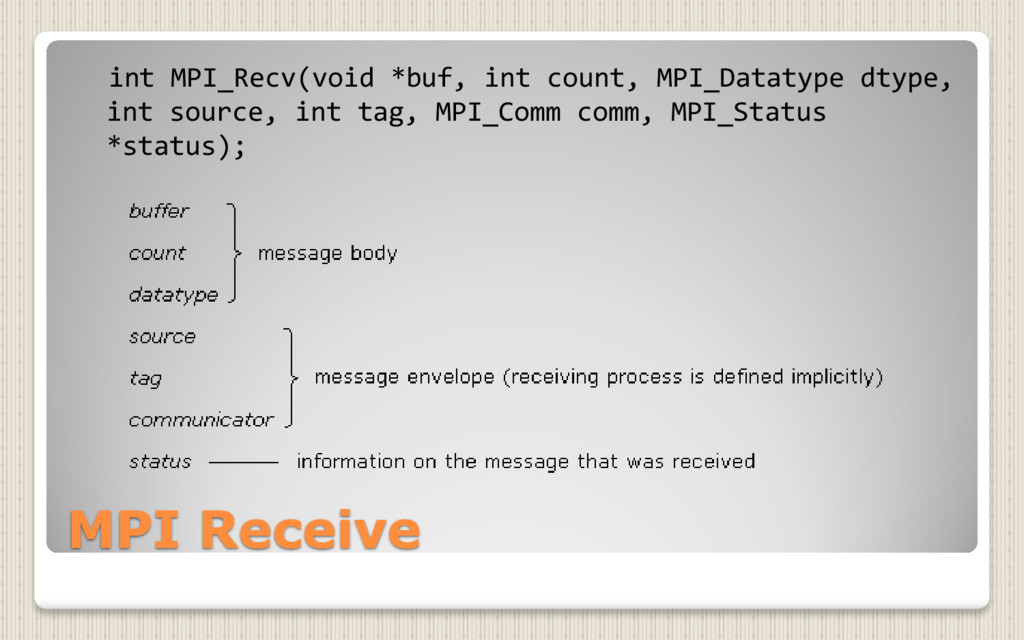
MPI Receive int MPI_Recv(void *buf, int count, MPI_Datatype dtype, int
source, int tag, MPI_Comm comm, MPI_Status *status); -
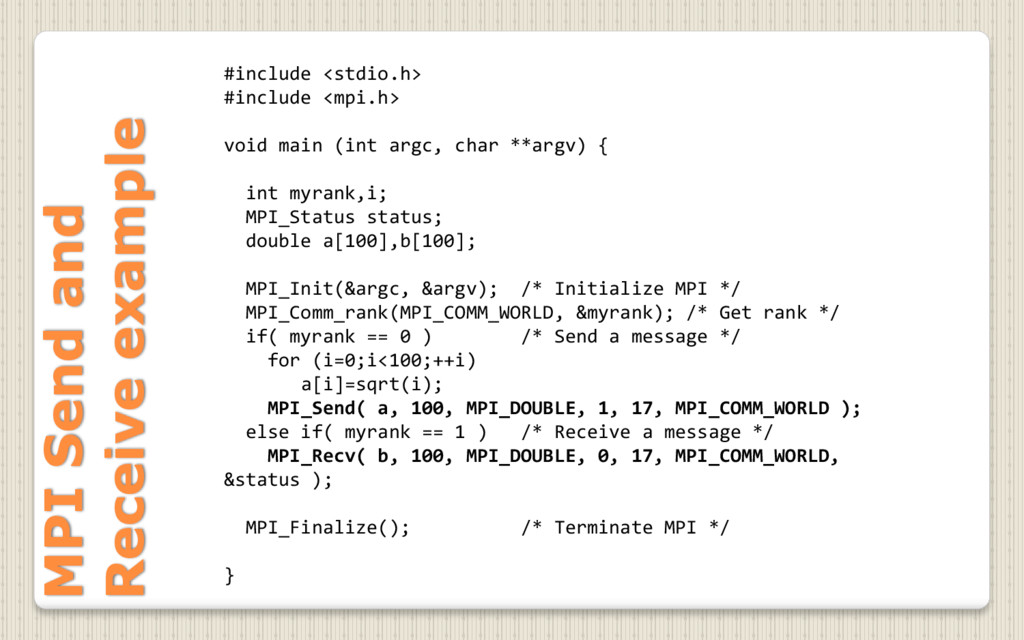
#include <stdio.h> #include <mpi.h> void main (int argc, char **argv)
{ int myrank,i; MPI_Status status; double a[100],b[100]; MPI_Init(&argc, &argv); /* Initialize MPI */ MPI_Comm_rank(MPI_COMM_WORLD, &myrank); /* Get rank */ if( myrank == 0 ) /* Send a message */ for (i=0;i<100;++i) a[i]=sqrt(i); MPI_Send( a, 100, MPI_DOUBLE, 1, 17, MPI_COMM_WORLD ); else if( myrank == 1 ) /* Receive a message */ MPI_Recv( b, 100, MPI_DOUBLE, 0, 17, MPI_COMM_WORLD, &status ); MPI_Finalize(); /* Terminate MPI */ } MPI Send and Receive example -
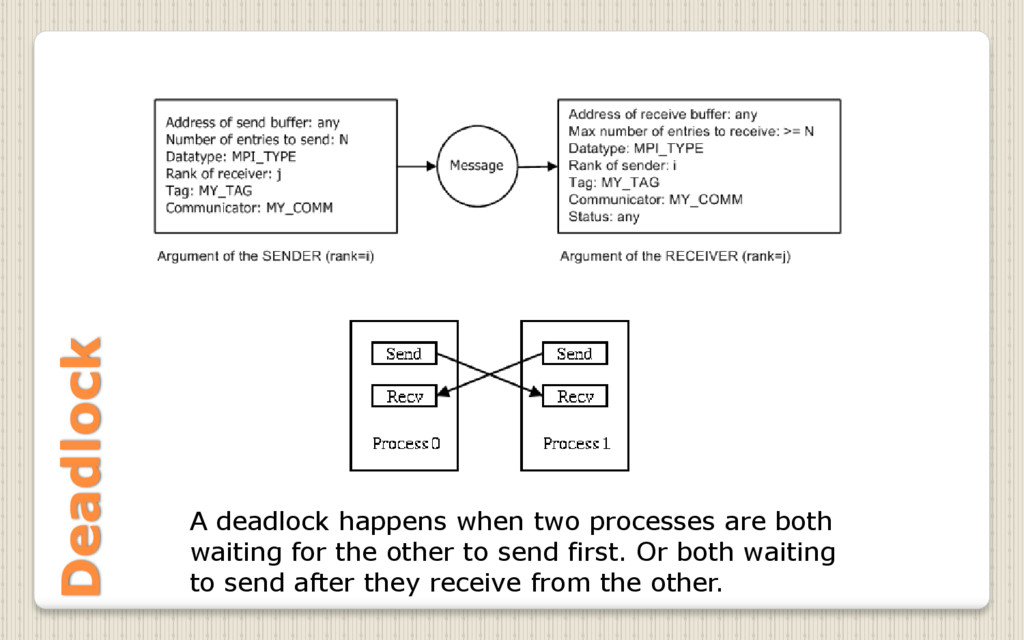
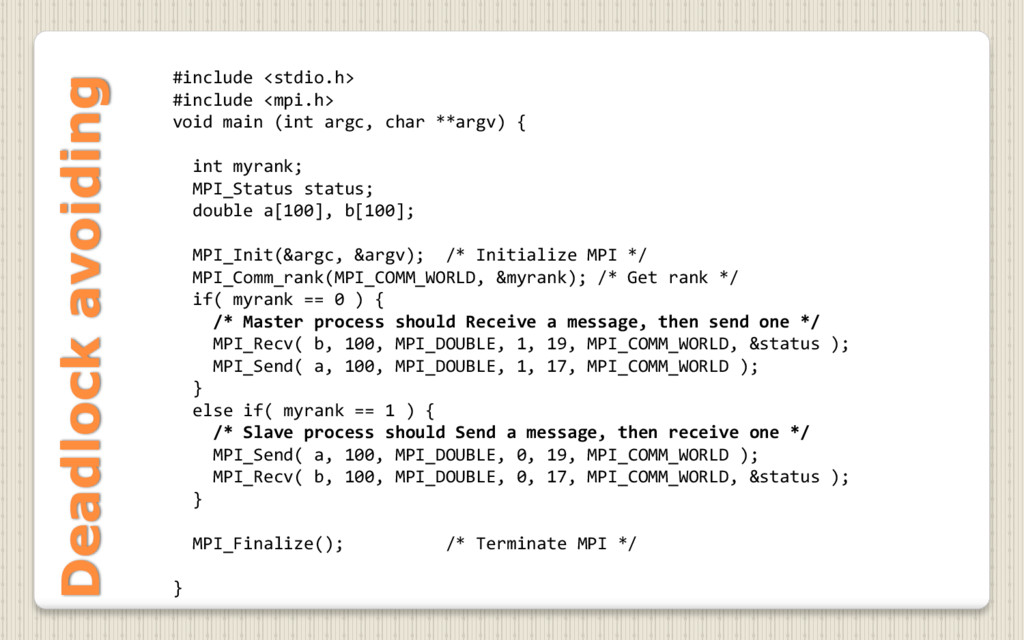
Deadlock A deadlock happens when two processes are both waiting
for the other to send first. Or both waiting to send after they receive from the other. -
#include <stdio.h> #include <mpi.h> void main (int argc, char **argv)
{ int myrank; MPI_Status status; double a[100], b[100]; MPI_Init(&argc, &argv); /* Initialize MPI */ MPI_Comm_rank(MPI_COMM_WORLD, &myrank); /* Get rank */ if( myrank == 0 ) { /* Master process should Receive a message, then send one */ MPI_Recv( b, 100, MPI_DOUBLE, 1, 19, MPI_COMM_WORLD, &status ); MPI_Send( a, 100, MPI_DOUBLE, 1, 17, MPI_COMM_WORLD ); } else if( myrank == 1 ) { /* Slave process should Send a message, then receive one */ MPI_Send( a, 100, MPI_DOUBLE, 0, 19, MPI_COMM_WORLD ); MPI_Recv( b, 100, MPI_DOUBLE, 0, 17, MPI_COMM_WORLD, &status ); } MPI_Finalize(); /* Terminate MPI */ } Deadlock avoiding -
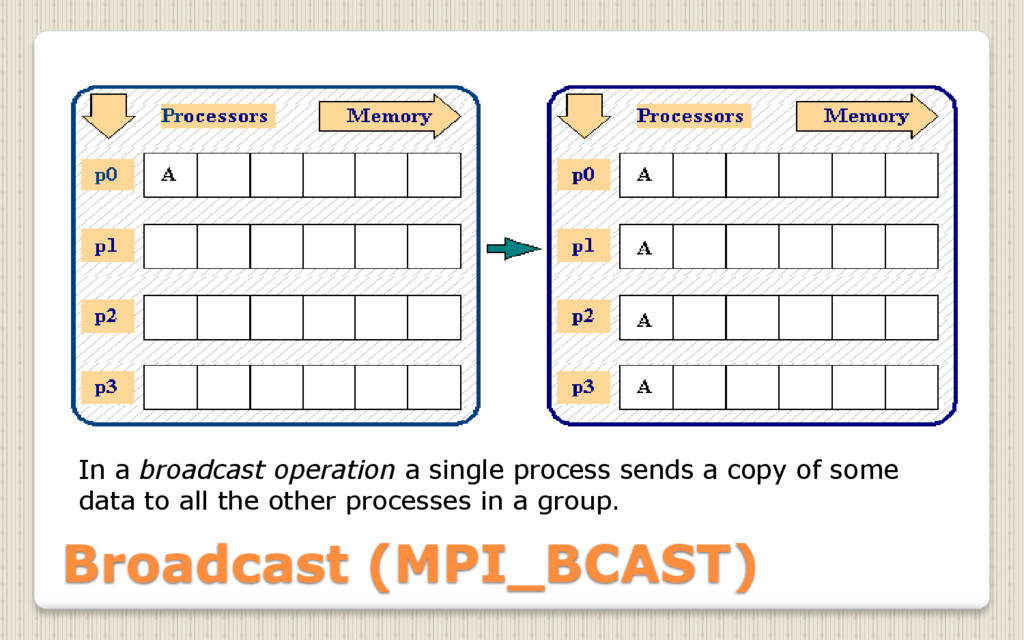
Broadcast (MPI_BCAST) In a broadcast operation a single process sends
a copy of some data to all the other processes in a group. -
#include <mpi.h> void main(int argc, char *argv[]) { int rank;
double param; MPI_Init(&argc, &argv); MPI_Comm_rank(MPI_COMM_WORLD,&rank); if(rank==5) param=23.0; MPI_Bcast(¶m,1,MPI_DOUBLE,5,MPI_COMM_WORLD); printf("P:%d after broadcast parameter is %f \n",rank,param); MPI_Finalize(); } MPI Broadcast example -
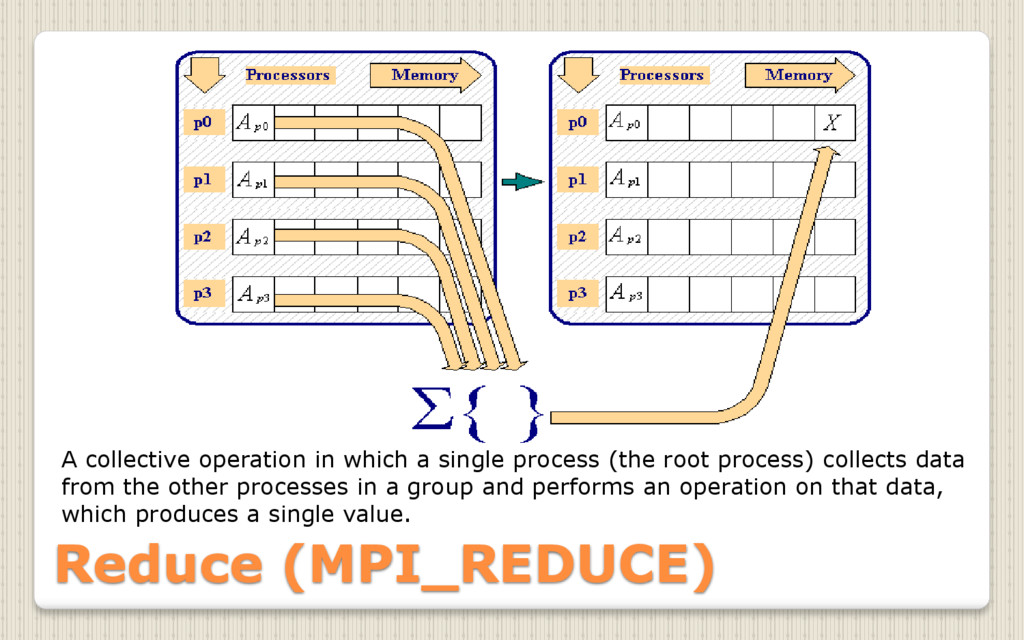
Reduce (MPI_REDUCE) A collective operation in which a single process
(the root process) collects data from the other processes in a group and performs an operation on that data, which produces a single value. -
#include <stdio.h> #include <mpi.h> void main(int argc, char *argv[]) {
int rank,source,result,root; /* run on 10 processors */ MPI_Init(&argc, &argv); MPI_Comm_rank(MPI_COMM_WORLD,&rank); root=7; source=rank+1; MPI_Barrier(MPI_COMM_WORLD); MPI_Reduce(&source,&result,1,MPI_INT,MPI_PROD,root,MPI_COMM_W ORLD); if(rank==root) printf("P:%d MPI_PROD result is %d \n",rank,result); MPI_Finalize(); } MPI Reduce example -
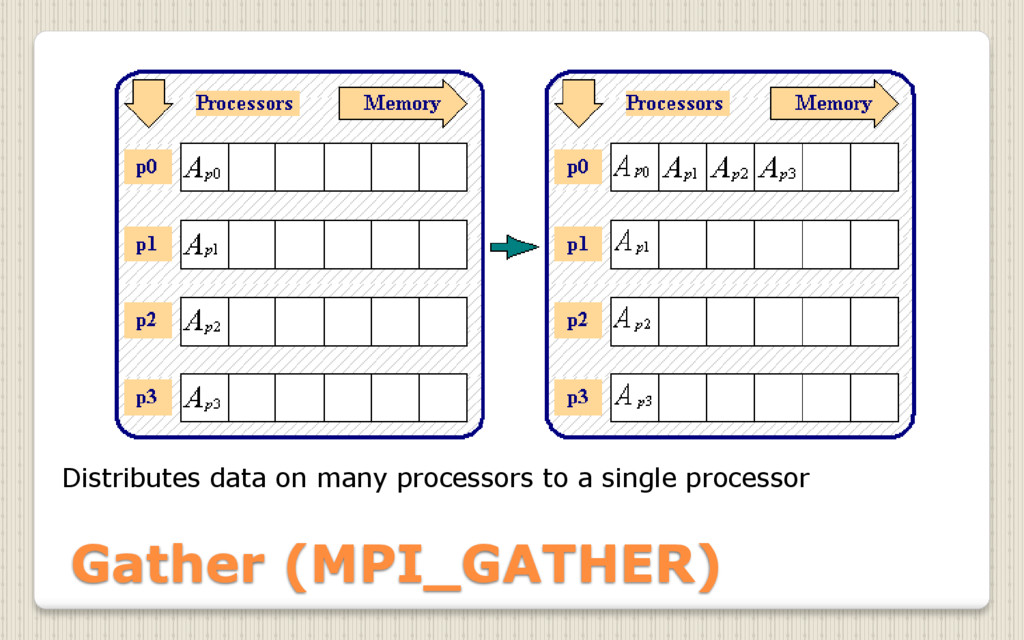
#include <stdio.h> #include <mpi.h> void main(int argc, char *argv[]) {
int rank,size; double param[16],mine; int sndcnt,rcvcnt; int i; MPI_Init(&argc, &argv); MPI_Comm_rank(MPI_COMM_WORLD,&rank); MPI_Comm_size(MPI_COMM_WORLD,&size); sndcnt=1; mine=23.0+rank; if(rank==7) rcvcnt=1; MPI_Gather(&mine,sndcnt,MPI_DOUBLE,param,rcvcnt,MPI_DOUBLE,7,MPI_COMM_WORLD); if(rank==7) for(i=0;i<size;++i) printf("PE:%d param[%d] is %f \n",rank,i,param[i]]); MPI_Finalize(); } MPI Gather example -
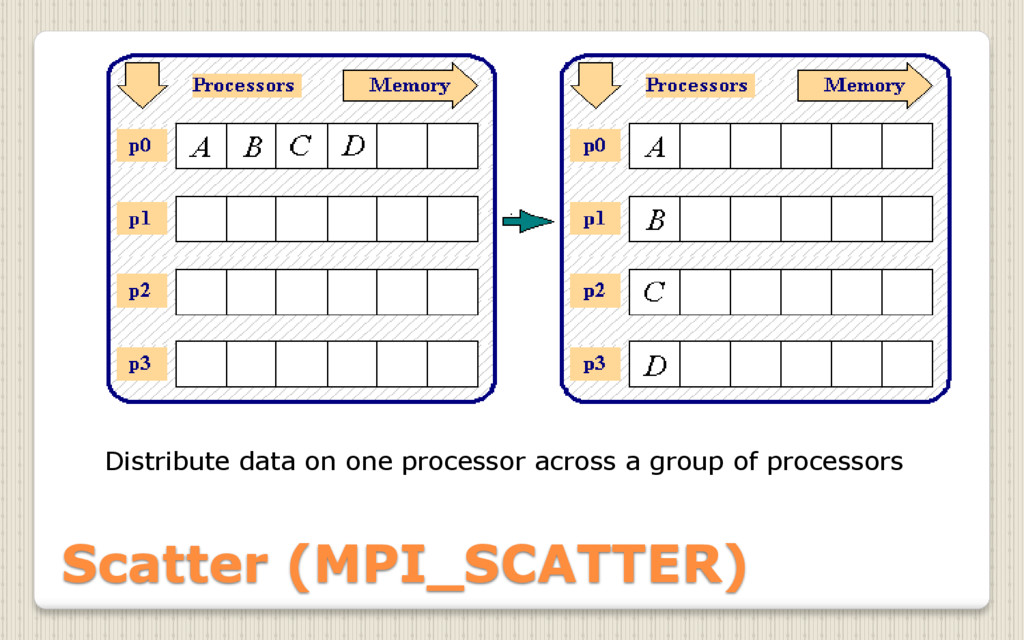
#include <stdio.h> #include <mpi.h> void main(int argc, char *argv[]) {
int rank,size,i; double param[8],mine; int sndcnt,rcvcnt; MPI_Init(&argc, &argv); MPI_Comm_rank(MPI_COMM_WORLD,&rank); MPI_Comm_size(MPI_COMM_WORLD,&size); rcvcnt=1; if(rank==3) { for(i=0;i<8;++i) param[i]=23.0+i; sndcnt=1; } MPI_Scatter(param,sndcnt,MPI_DOUBLE,&mine,rcvcnt,MPI_DOUBLE,3,MPI_COMM_WORLD); for(i=0;i<size;++i) { if(rank==i) printf("P:%d mine is %f n",rank,mine); fflush(stdout); MPI_Barrier(MPI_COMM_WORLD); } MPI_Finalize(); } MPI Scatter example -
Lessons Learnt… Architecting a Beowulf Cluster Linux kernel
customization Creating hardware assisted virtual nodes Programming using the MPI Libraries Linux system Administration (NFS, DHCP, SSH, PXE BOOT, Network Stack) -
Future Directions… Implement the same cluster on Real Hardware
with Real Nodes. More Algorithm Implementations Performance Analysis VPN implementation for connecting nodes across the internet. Many more things… -
Open Problems… There is no easy way to parallelize
a sequential algorithm. Current network topologies are a bottlenecks to Beowulf’s performance. There is no easy way to detect deadlocks in code, and to eliminate them.