Share
Embed
CS Research for Practitioners: Lessons from The Morning Paper
Invited talk for an internal conference of a large financial institution.
Adrian Colyer
March 09, 2017
Transcript
54 slides
-
CS Research for practitioners: lessons from The Morning Paper Adrian
Colyer @adriancolyer -
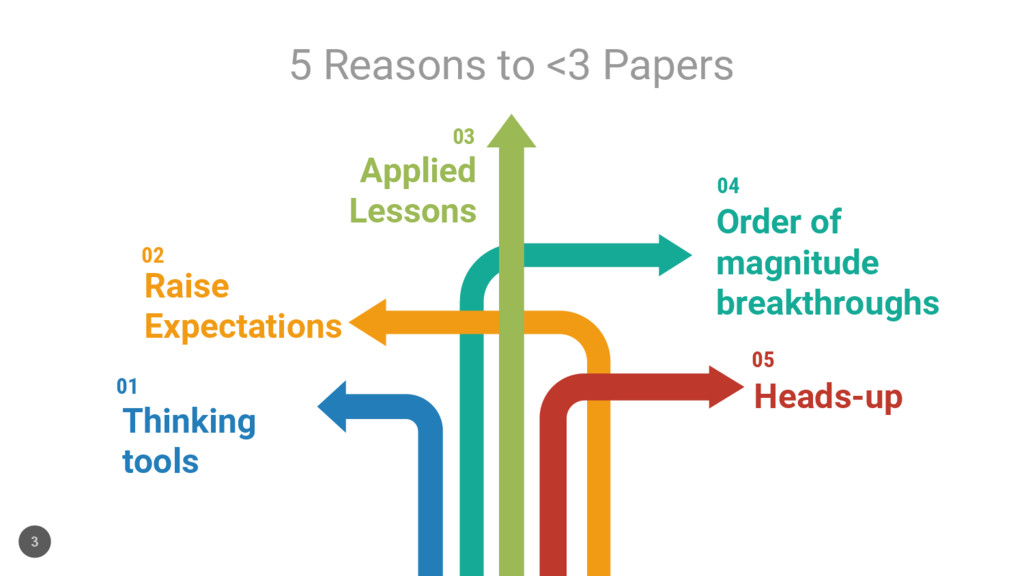
Brain storm 01 02 05 04 rainstorm 03 5 Reasons
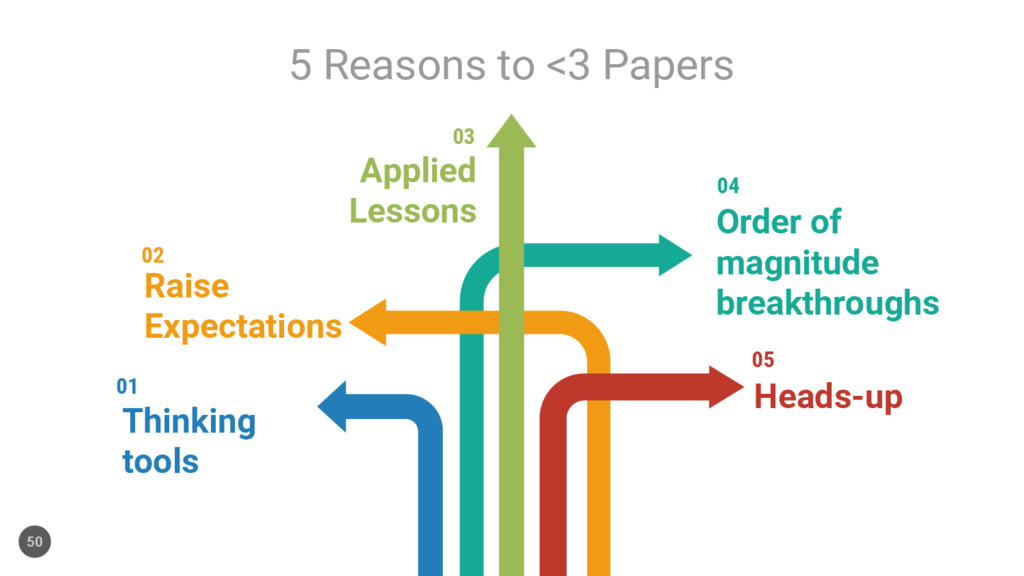
to <3 Papers Thinking tools Raise Expectations Applied Lessons Order of magnitude breakthroughs Heads-up 3 -
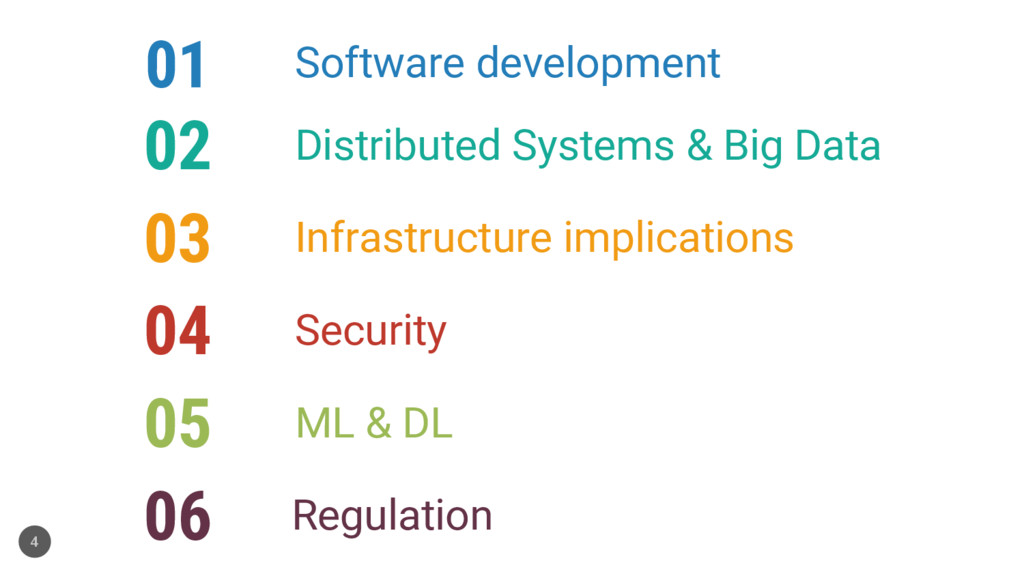
4 01 02 03 04 05 Software development Distributed Systems
& Big Data Infrastructure implications Security ML & DL 06 Regulation -
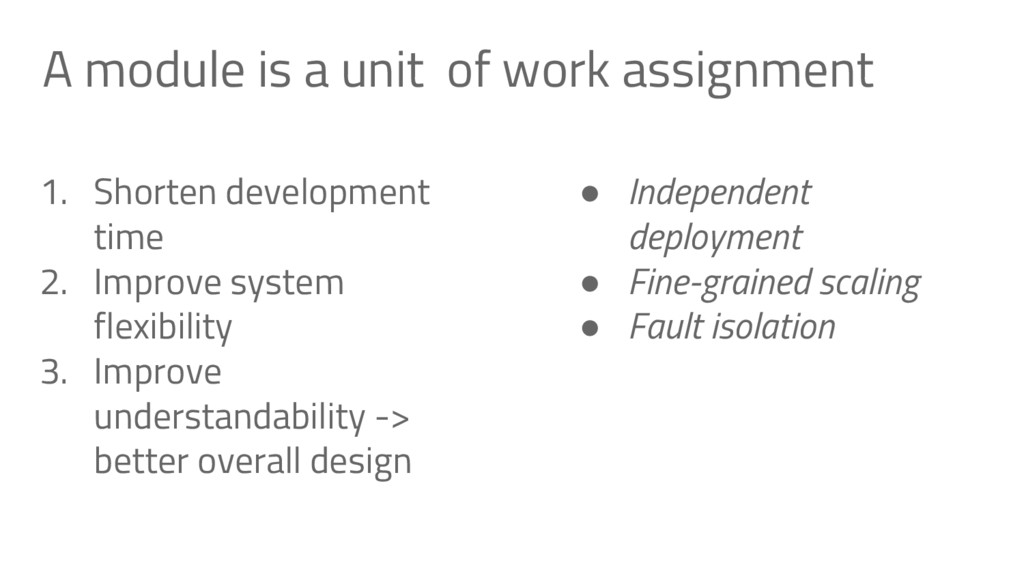
A module is a unit of work assignment 1. Shorten
development time 2. Improve system flexibility 3. Improve understandability -> better overall design • Independent deployment • Fine-grained scaling • Fault isolation -
Copyright: Maxim Popov, 123RF Stock Photo “The effectiveness of a
modularization is dependent upon the criteria used in dividing the system into modules.” -
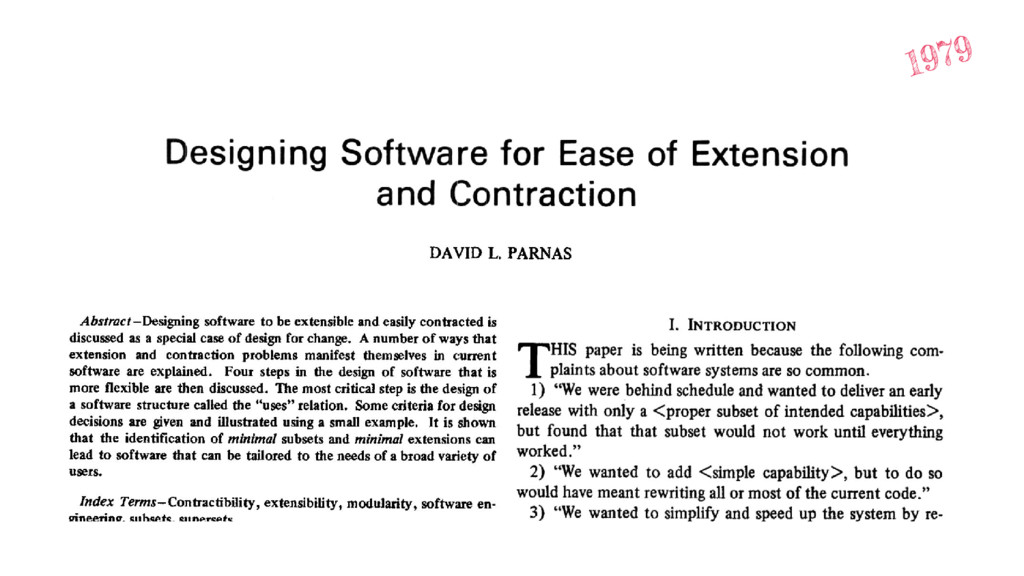
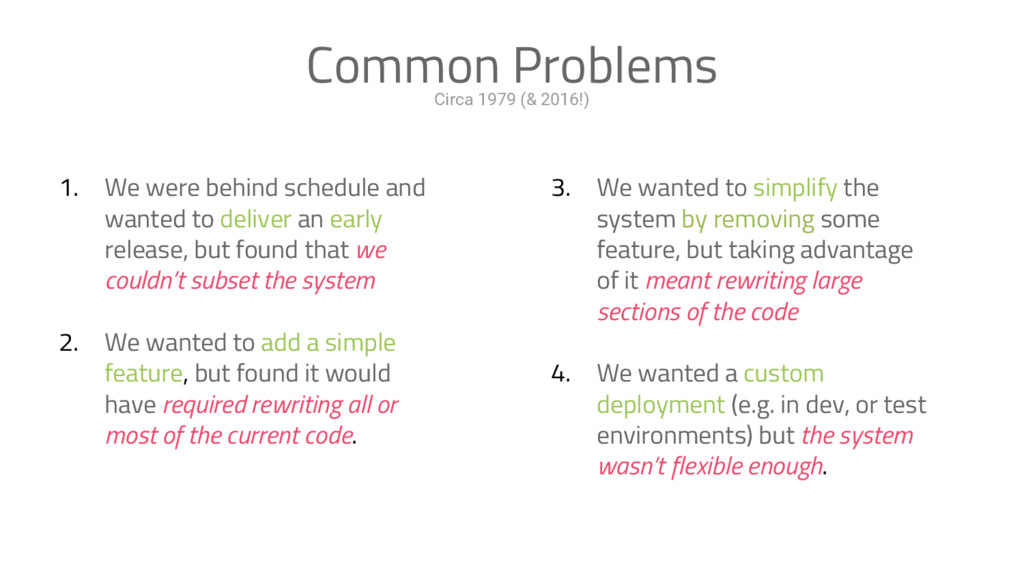
Circa 1979 (& 2016!) Common Problems 1. We were behind
schedule and wanted to deliver an early release, but found that we couldn’t subset the system 2. We wanted to add a simple feature, but found it would have required rewriting all or most of the current code. 3. We wanted to simplify the system by removing some feature, but taking advantage of it meant rewriting large sections of the code 4. We wanted a custom deployment (e.g. in dev, or test environments) but the system wasn’t flexible enough. -
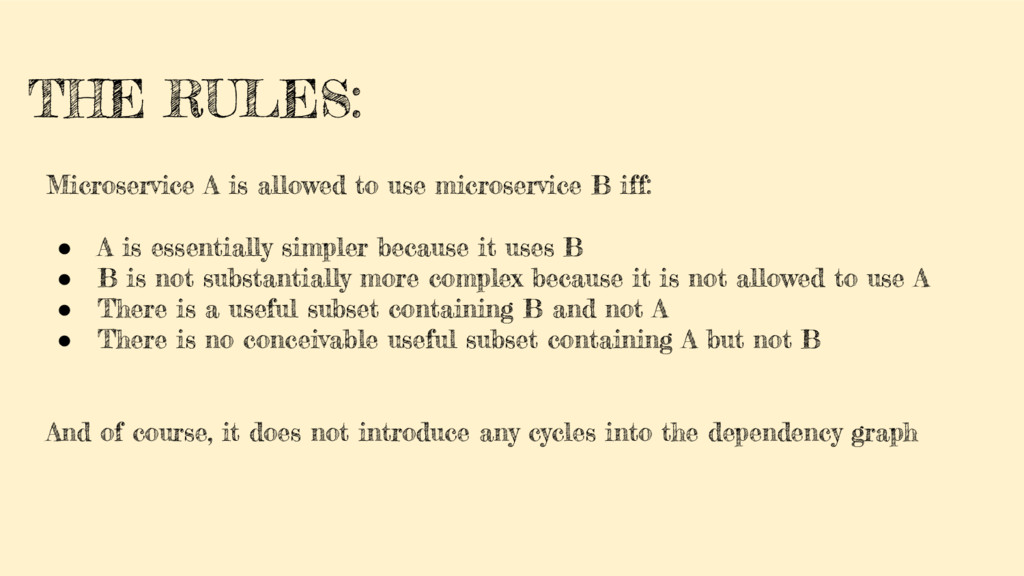
THE RULES: Microservice A is allowed to use microservice B
iff: • A is essentially simpler because it uses B • B is not substantially more complex because it is not allowed to use A • There is a useful subset containing B and not A • There is no conceivable useful subset containing A but not B And of course, it does not introduce any cycles into the dependency graph -
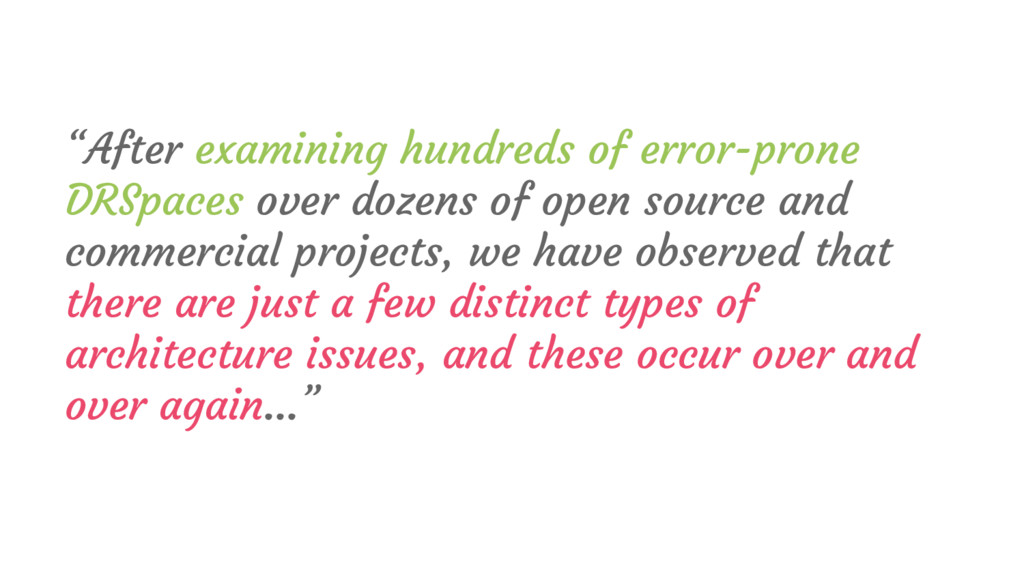
“After examining hundreds of error-prone DRSpaces over dozens of open
source and commercial projects, we have observed that there are just a few distinct types of architecture issues, and these occur over and over again…” -
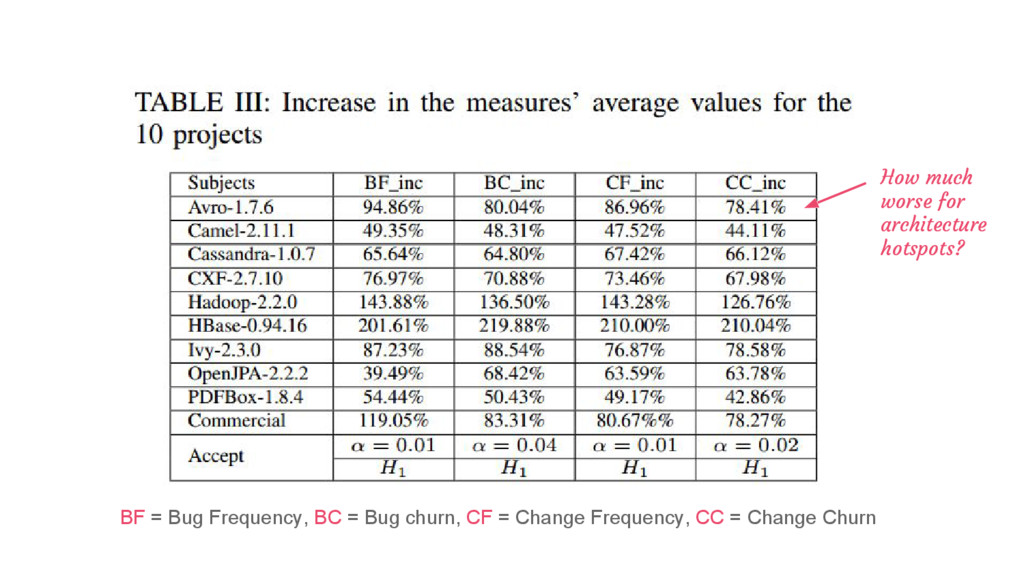
BF = Bug Frequency, BC = Bug churn, CF =
Change Frequency, CC = Change Churn How much worse for architecture hotspots? -
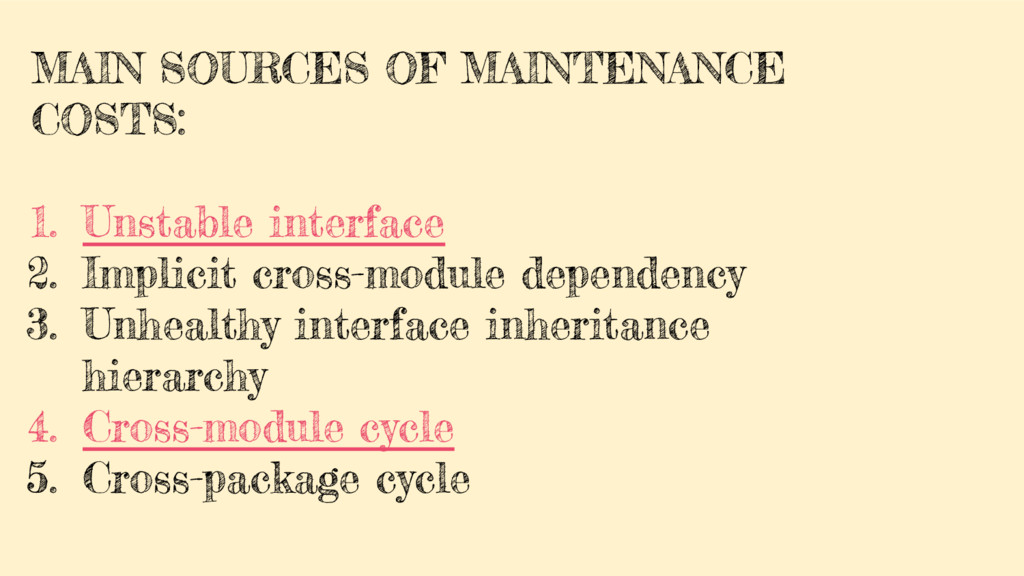
MAIN SOURCES OF MAINTENANCE COSTS: 1. Unstable interface 2. Implicit
cross-module dependency 3. Unhealthy interface inheritance hierarchy 4. Cross-module cycle 5. Cross-package cycle -
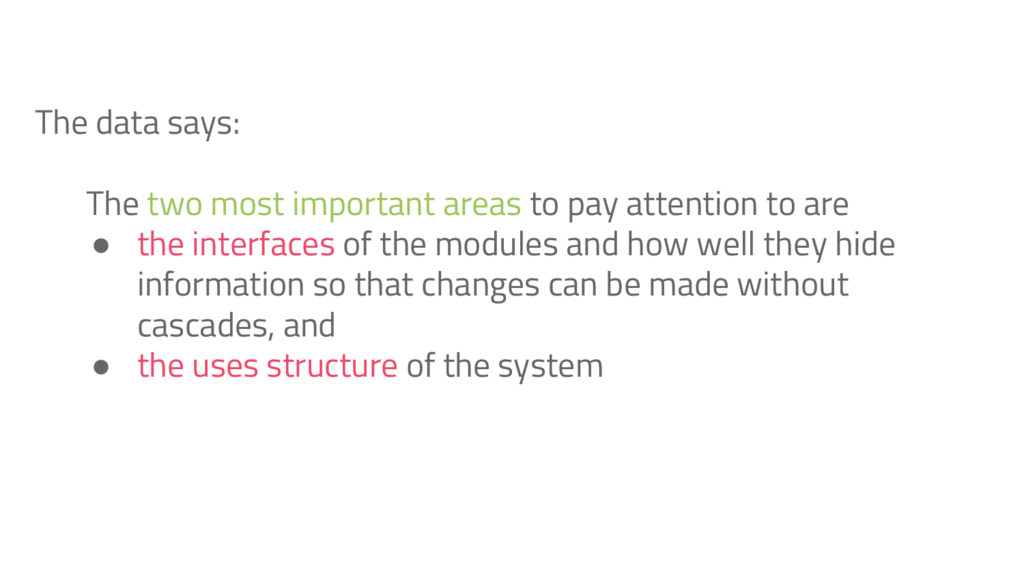
The data says: The two most important areas to pay
attention to are • the interfaces of the modules and how well they hide information so that changes can be made without cascades, and • the uses structure of the system -
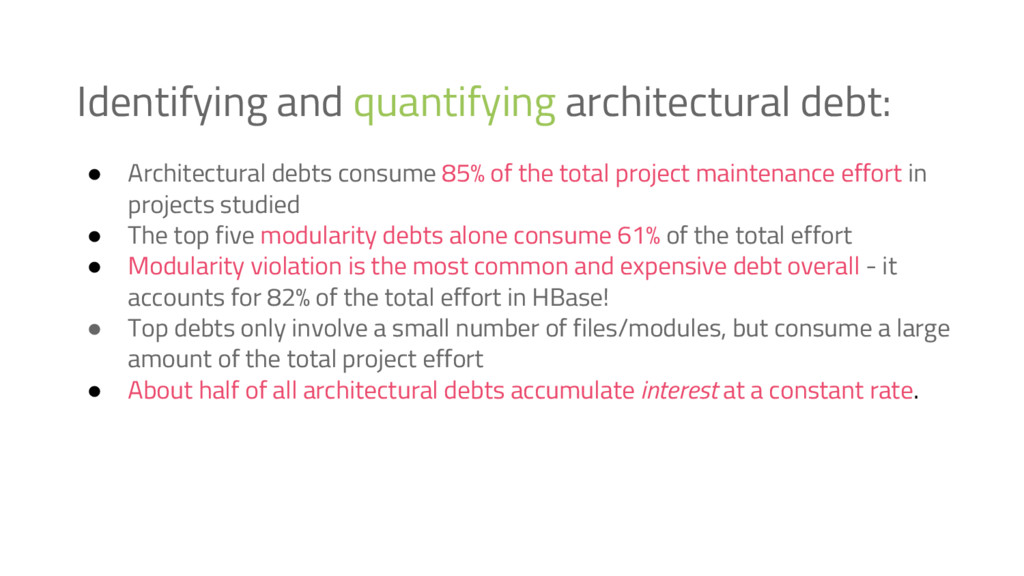
Identifying and quantifying architectural debt: • Architectural debts consume 85%
of the total project maintenance effort in projects studied • The top five modularity debts alone consume 61% of the total effort • Modularity violation is the most common and expensive debt overall - it accounts for 82% of the total effort in HBase! • Top debts only involve a small number of files/modules, but consume a large amount of the total project effort • About half of all architectural debts accumulate interest at a constant rate. -
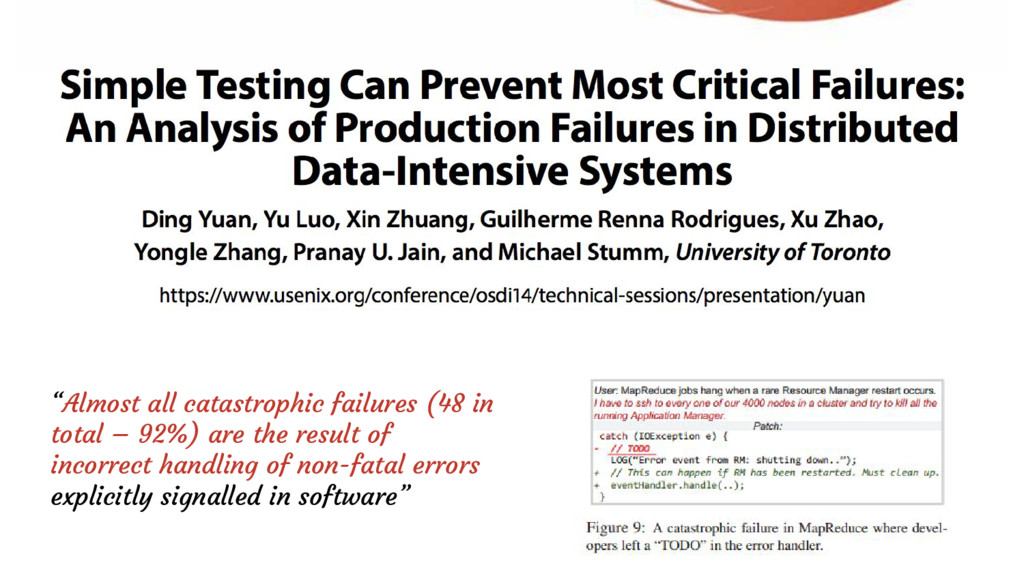
“Almost all catastrophic failures (48 in total – 92%) are
the result of incorrect handling of non-fatal errors explicitly signalled in software” -
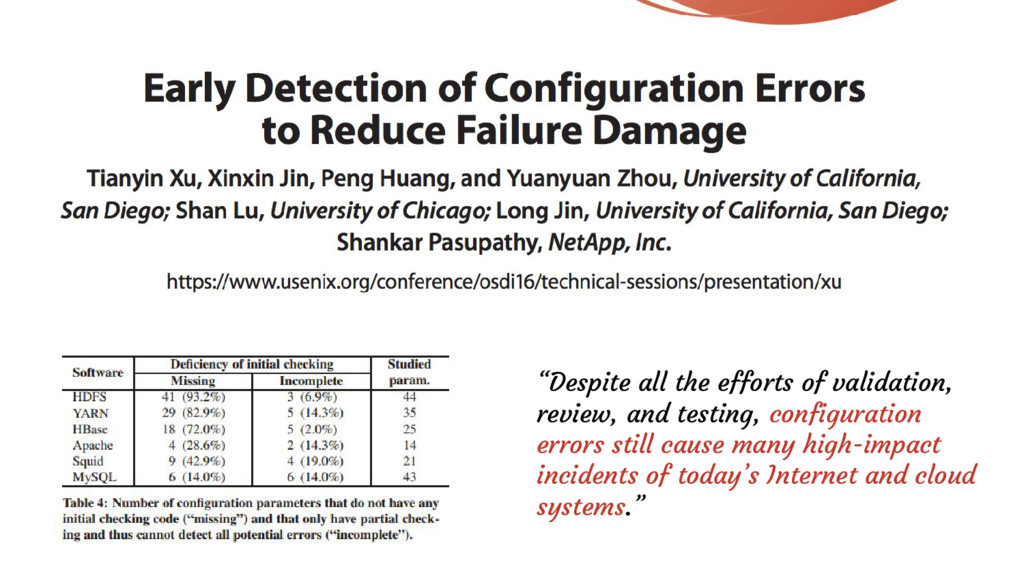
“Despite all the efforts of validation, review, and testing, configuration
errors still cause many high-impact incidents of today’s Internet and cloud systems.” -
But you have BIG Data! 23 Zipf Distribution “Working sets
are Zipf-distributed. We can therefore store in memory all but the very largest datasets.” -
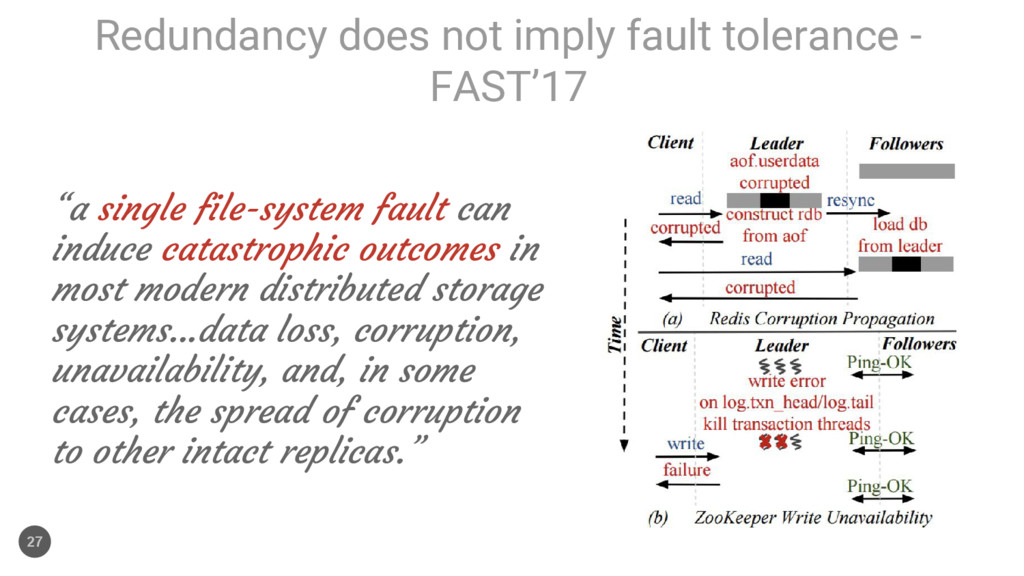
Redundancy does not imply fault tolerance - FAST’17 27 “a
single file-system fault can induce catastrophic outcomes in most modern distributed storage systems...data loss, corruption, unavailability, and, in some cases, the spread of corruption to other intact replicas.” -
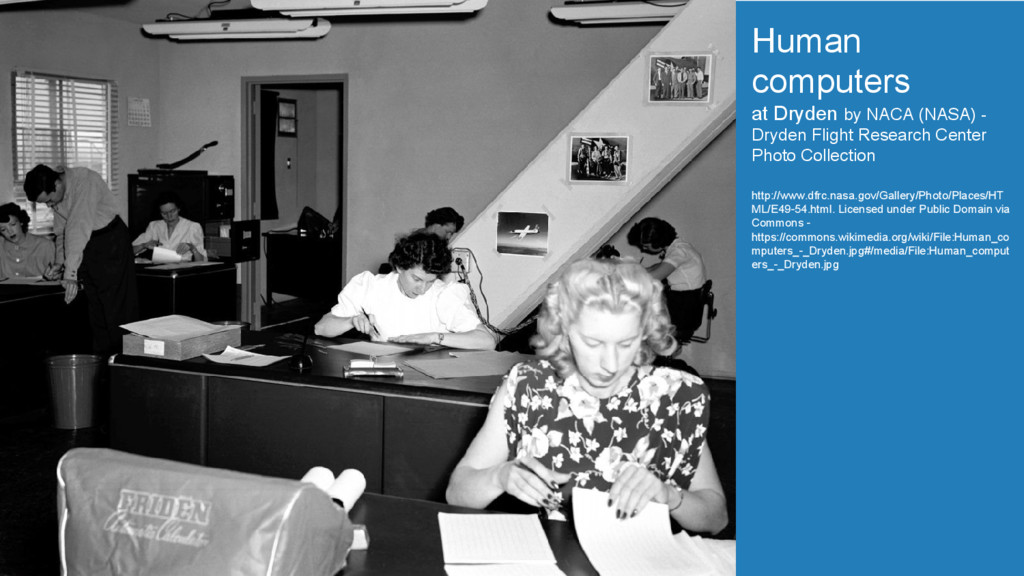
Human computers at Dryden by NACA (NASA) - Dryden Flight
Research Center Photo Collection http://www.dfrc.nasa.gov/Gallery/Photo/Places/HT ML/E49-54.html. Licensed under Public Domain via Commons - https://commons.wikimedia.org/wiki/File:Human_co mputers_-_Dryden.jpg#/media/File:Human_comput ers_-_Dryden.jpg -
Computing on a Human Scale 30 10ns 70ns 10ms 10s
1:10s 116d Registers & L1-L3 File on desk Main memory Office filing cabinet HDD Trip to the warehouse -
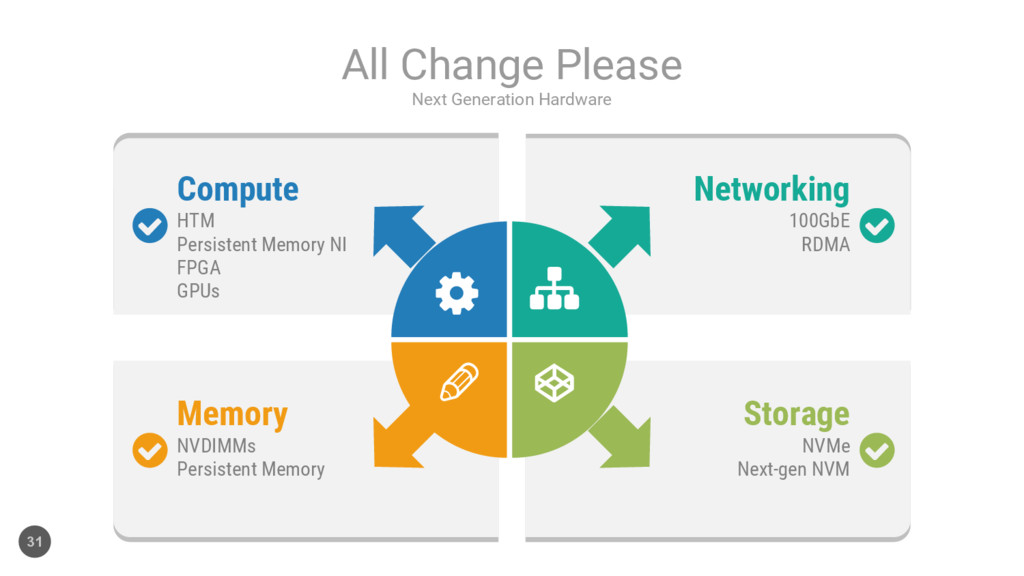
Compute HTM Persistent Memory NI FPGA GPUs Memory NVDIMMs Persistent
Memory Networking 100GbE RDMA Storage NVMe Next-gen NVM Next Generation Hardware All Change Please 31 -
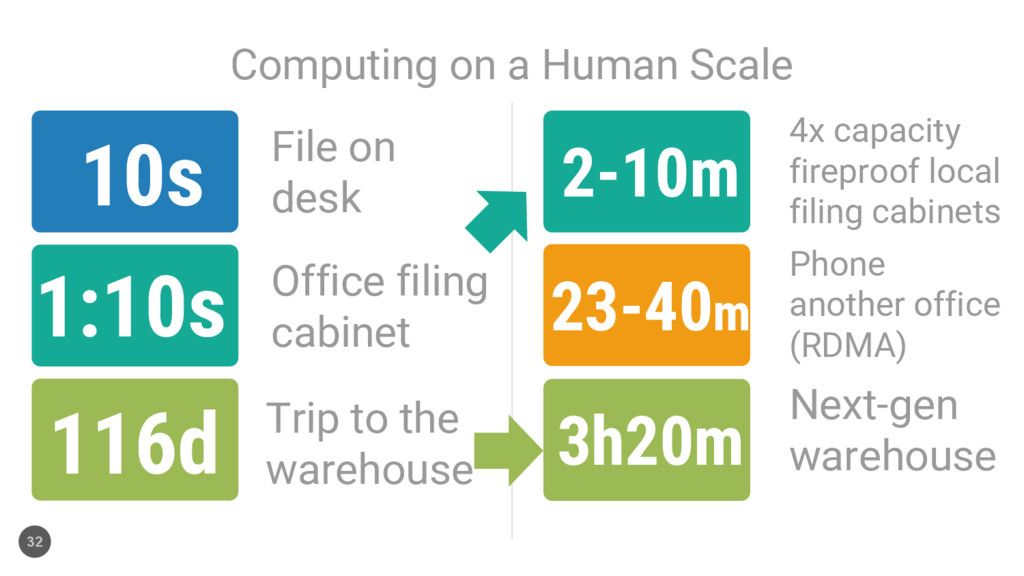
2-10m Computing on a Human Scale 32 10s 1:10s 116d
File on desk Office filing cabinet Trip to the warehouse 4x capacity fireproof local filing cabinets 23-40m Phone another office (RDMA) 3h20m Next-gen warehouse -
The New ~Numbers Everyone Should Know 33 Latency Bandwidth Capacity/IOPS
Register 0.25ns L1 cache 1ns L2 cache 3ns 8MB L3 cache 11ns 45MB DRAM 62ns 120GBs 6TB - 4 socket NVRAM’ DIMM 620ns 60GBs 24TB - 4 socket 1-sided RDMA in Data Center 1.4us 100GbE ~700K IOPS RPC in Data Center 2.4us 100GbE ~400K IOPS NVRAM’ NVMe 12us 6GBs 16TB/disk,~2M/600K NVRAM’ NVMf 90us 5GBs 16TB/disk, ~700/600K -
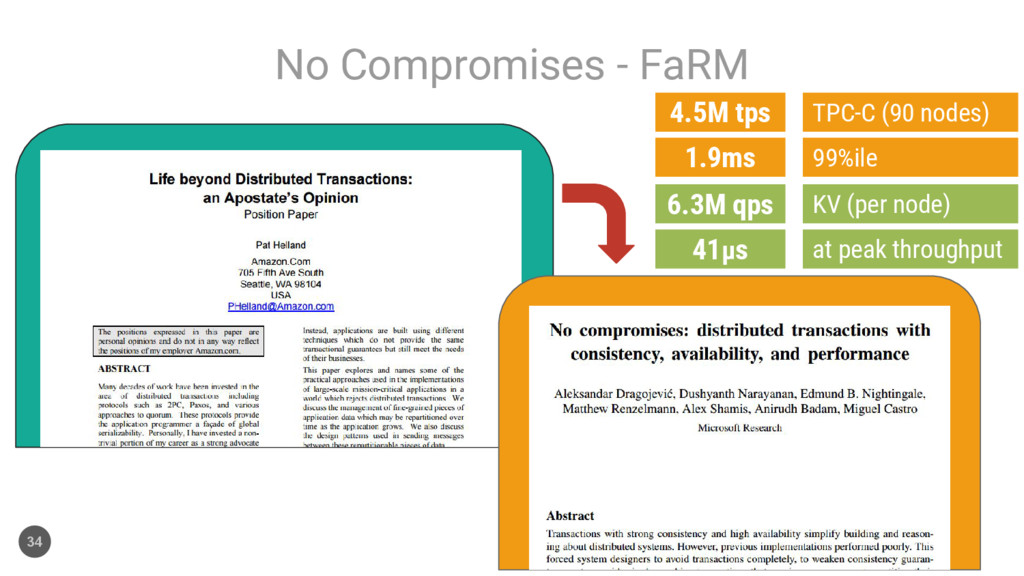
No Compromises - FaRM 34 TPC-C (90 nodes) 4.5M tps
99%ile 1.9ms KV (per node) 6.3M qps at peak throughput 41μs -
No Compromises 35 “This paper demonstrates that new software in
modern data centers can eliminate the need to compromise. It describes the transaction, replication, and recovery protocols in FaRM, a main memory distributed computing platform. FaRM provides distributed ACID transactions with strict serializability, high availability, high throughput and low latency. These protocols were designed from first principles to leverage two hardware trends appearing in data centers: fast commodity networks with RDMA and an inexpensive approach to providing non-volatile DRAM.” -
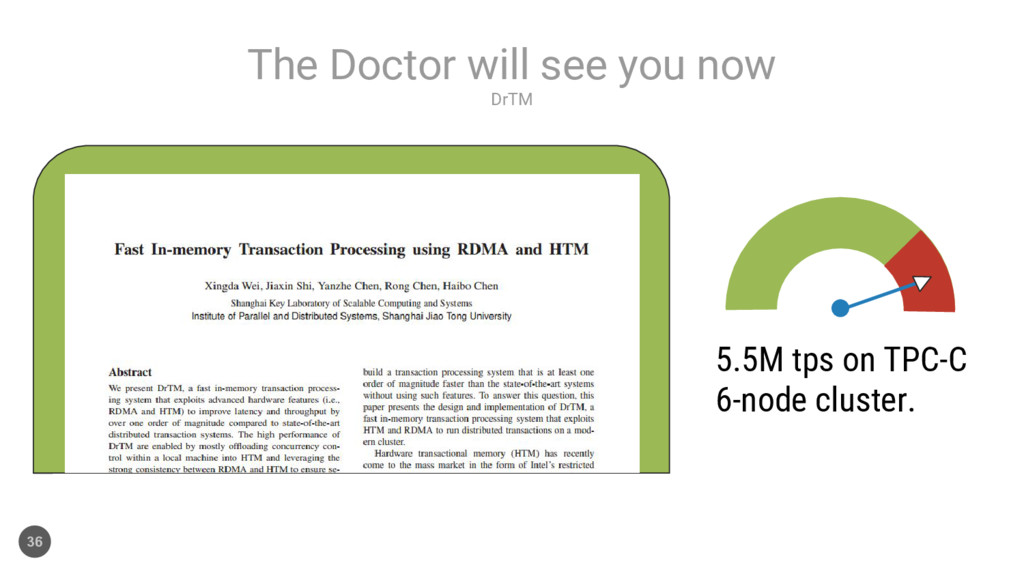
DrTM The Doctor will see you now 36 5.5M tps
on TPC-C 6-node cluster. -
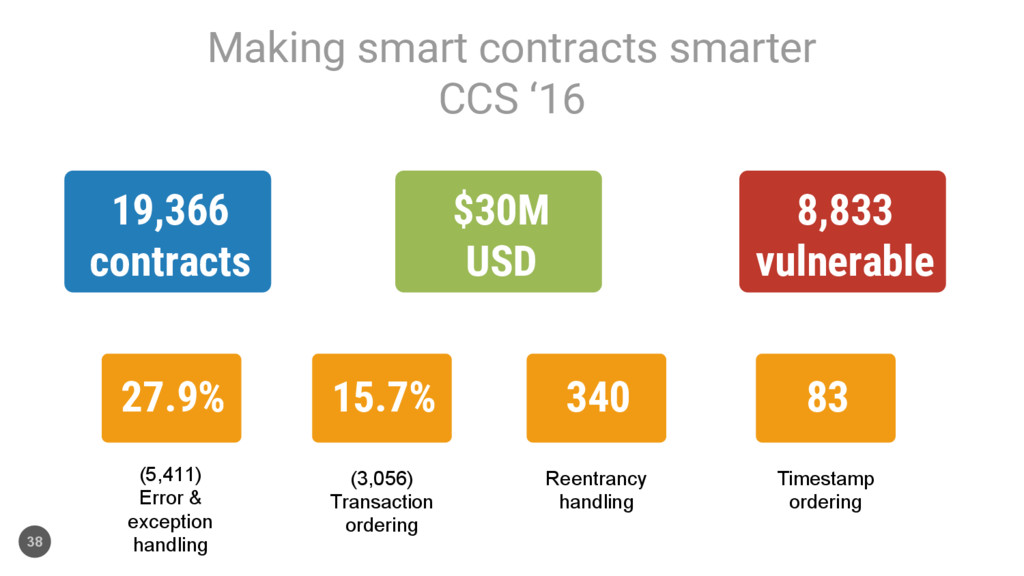
Making smart contracts smarter CCS ‘16 38 19,366 contracts $30M
USD 8,833 vulnerable 27.9% 15.7% 340 83 (5,411) Error & exception handling (3,056) Transaction ordering Reentrancy handling Timestamp ordering -
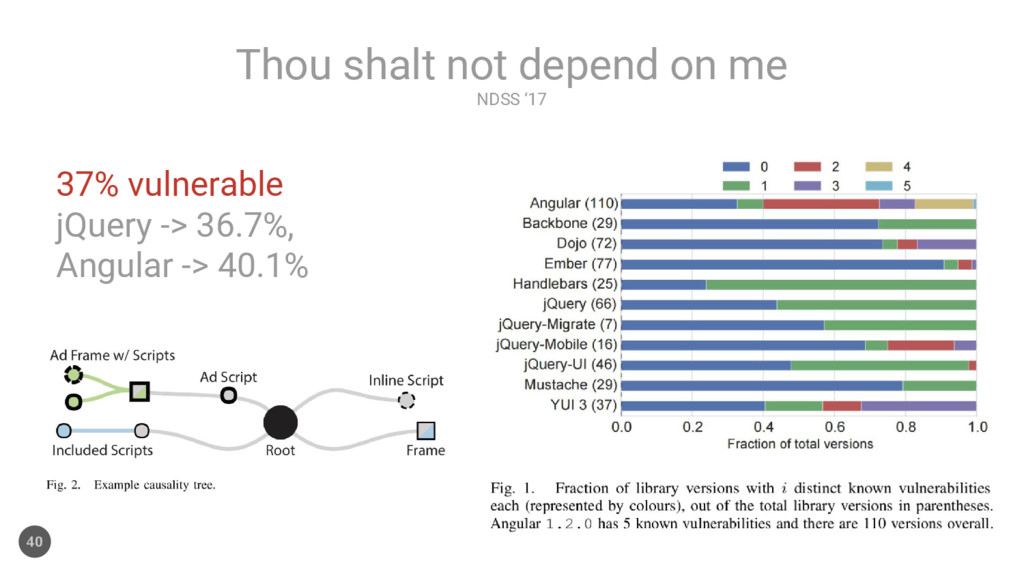
NDSS ‘17 Thou shalt not depend on me 40 37%
vulnerable jQuery -> 36.7%, Angular -> 40.1% -
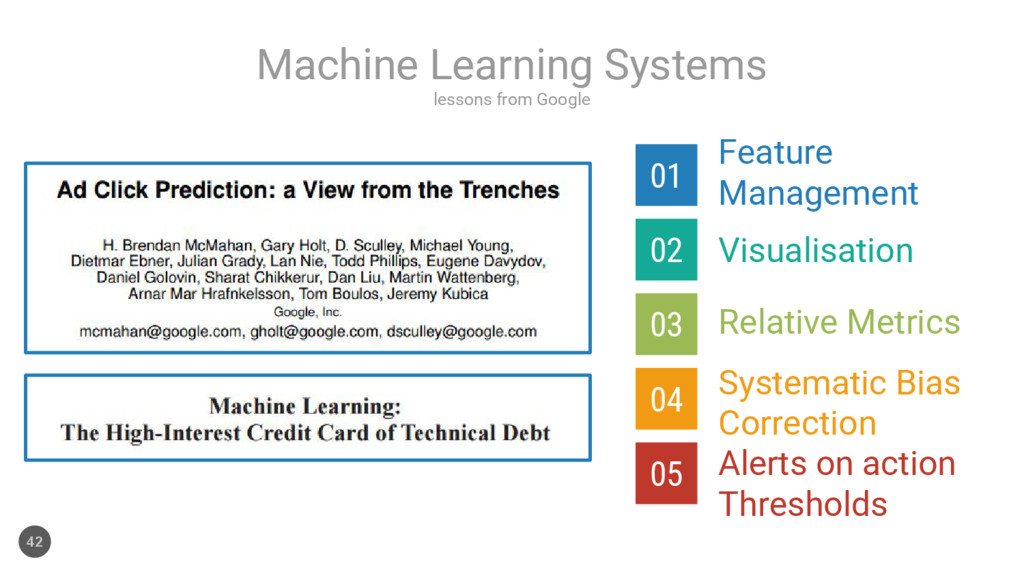
lessons from Google Machine Learning Systems 42 Feature Management Visualisation
Relative Metrics Systematic Bias Correction Alerts on action Thresholds 01 02 03 04 05 -
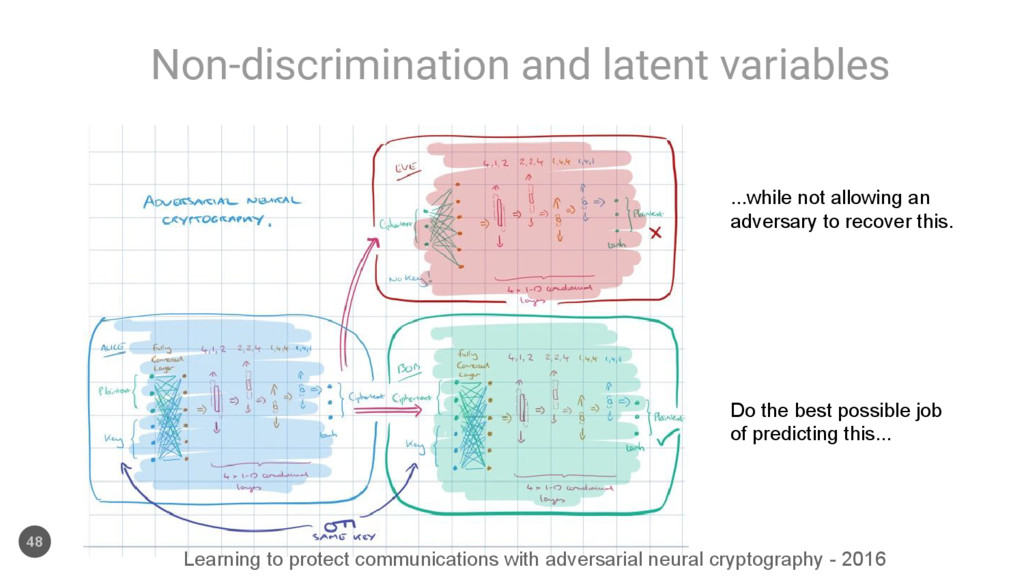
Non-discrimination and latent variables 48 Do the best possible job
of predicting this... ...while not allowing an adversary to recover this. Learning to protect communications with adversarial neural cryptography - 2016 -
Brain storm 01 02 05 04 rainstorm 03 5 Reasons
to <3 Papers Thinking tools Raise Expectations Applied Lessons Order of magnitude breakthroughs Heads-up 50 -
Don’t just take my word for it... 51 When I
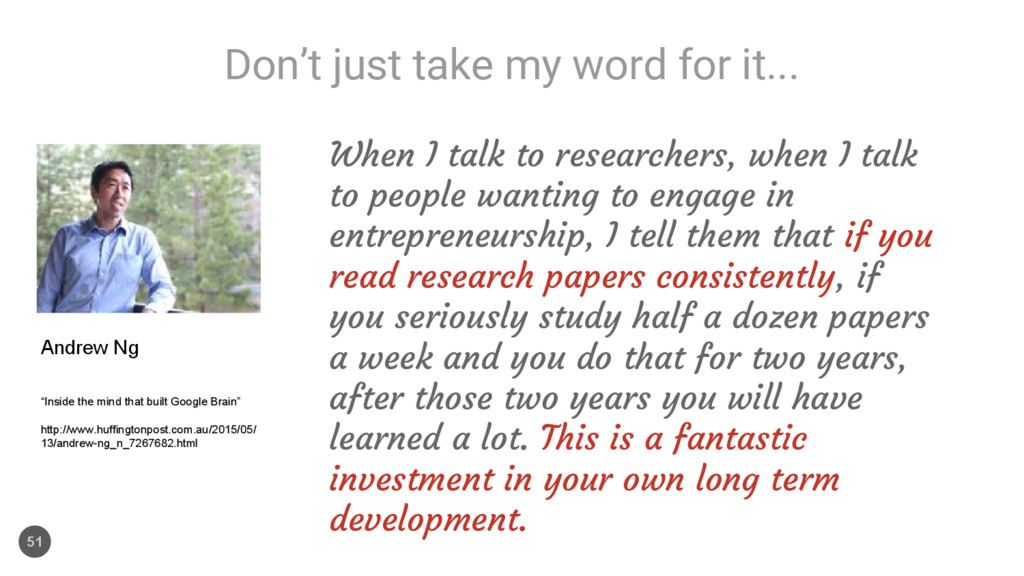
talk to researchers, when I talk to people wanting to engage in entrepreneurship, I tell them that if you read research papers consistently, if you seriously study half a dozen papers a week and you do that for two years, after those two years you will have learned a lot. This is a fantastic investment in your own long term development. Andrew Ng “Inside the mind that built Google Brain” http://www.huffingtonpost.com.au/2015/05/ 13/andrew-ng_n_7267682.html -
Don’t just take my word for it... 52 I don’t
know how the human brain works, but it’s almost magical - when you read enough or talk to enough experts, when you have enough inputs, new ideas start appearing. Andrew Ng “Inside the mind that built Google Brain” : http://www.huffingtonpost.com.au/2015/05/13/andrew-ng_n_7267682.html -
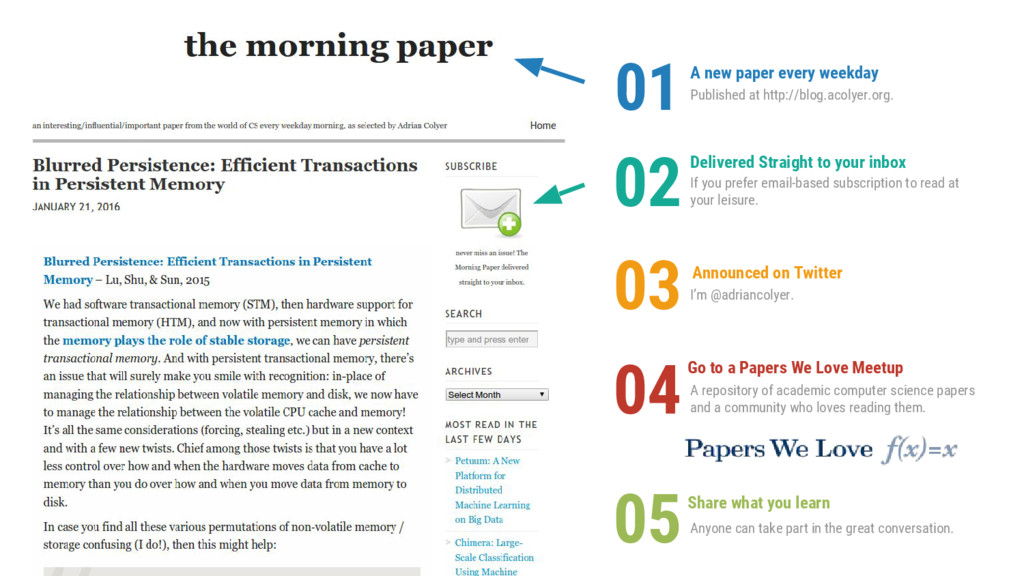
A new paper every weekday Published at http://blog.acolyer.org. 01 Delivered
Straight to your inbox If you prefer email-based subscription to read at your leisure. 02 Announced on Twitter I’m @adriancolyer. 03 Go to a Papers We Love Meetup A repository of academic computer science papers and a community who loves reading them. 04 Share what you learn Anyone can take part in the great conversation. 05