Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
[RSJ26] Hierarchy-Aware Multimodal Retrieval-Au...
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Semantic Machine Intelligence Lab., Keio Univ.
PRO
August 28, 2026
Technology
200
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
[RSJ26] Hierarchy-Aware Multimodal Retrieval-Augmented Generation for Embodied Question Answering
Semantic Machine Intelligence Lab., Keio Univ.
PRO
August 28, 2026
More Decks by Semantic Machine Intelligence Lab., Keio Univ.
See All by Semantic Machine Intelligence Lab., Keio Univ.
[EMNLP26] RIGEL: Self-Distilled Score Adaptation for Image and Video Captioning Evaluation
keio_smilab
PRO
0
130
[RSJ26] Building a VLA Model Based on Self-Distilled Classification
keio_smilab
PRO
0
220
[RSJ26] AnoleVLA: Lightweight Vision-Language-Action Model with Deep State Space Models for Mobile Manipulation
keio_smilab
PRO
0
190
[RSJ26] NarrativeFlow: Flow-Based Vision-Language-Action Model Using Robot Velocity Fields
keio_smilab
PRO
0
260
[RSJ26] Flow as Flow: Modeling Robot Velocity Fields as Probability Velocity Fields
keio_smilab
PRO
1
250
[MIRU26] Open-Vocabulary Intention-Guided Object Detection in Diverse Scenes
keio_smilab
PRO
0
250
[Journal club] Evo-1: Lightweight Vision-Language-Action Model with Preserved Semantic Alignment
keio_smilab
PRO
0
75
[MIRU26] To What Extent Does MLLM-as-a-Judge Exhibit Cross-Model Preference Bias?
keio_smilab
PRO
0
340
[Journal club] FlashVID: Efficient Video Large Language Models via Training-free Tree-based Spatiotemporal Token Merging
keio_smilab
PRO
0
58
Other Decks in Technology
See All in Technology
書き手が人でもAIでも正しくなる道、 SREを埋め込んだDeveloper Platform / tech drivers day8
chmikata
4
800
ひとりで始めた AI駆動開発、チームに広げて何が変わったのか
kenichiodo
0
130
"計画的無茶振り"を通してAIネイティブ世代の新人を育てる
subroh0508
1
120
Devin プロモコードの受け取りと適用(2026.10.27)
kinopeee
1
660
OneLakeをデータソースにした AI Search(Foundry IQ)の ライフサイクル管理
ryuseiiida
0
130
Snowflake でできることが増えたら、 ABAC が必要になった
kaeton
0
110
E2Eってつらくないですか?E2Eの管理コストを下げる手段とその実践
akaboshinit
5
2.5k
PostgreSQL at Microsoft: Open Source, AI, & Cloud | Claire Giordano | PGConf.EU 2026
clairegiordano
0
110
AI駆動開発における開発環境のセキュリティの考え方
yamahiro
2
650
あなたのDartコードは丸見えかもしれない ~reFlutterで暴くFlutterアプリの中身と多層防御~
zozotech
PRO
0
480
Flutter Widget Previewerで始めるUIプレビューとVRTの自動化
sakusaku3939
0
150
AI時代のエンジニアの情報発信〜個人の発信を組織の力に変える〜
ryo_kawamata
0
190
Featured
See All Featured
How to optimise 3,500 product descriptions for ecommerce in one day using ChatGPT
katarinadahlin
PRO
3
3.9k
Practical Orchestrator
shlominoach
192
12k
AI in Enterprises - Java and Open Source to the Rescue
ivargrimstad
0
1.6k
Pawsitive SEO: Lessons from My Dog (and Many Mistakes) on Thriving as a Consultant in the Age of AI
davidcarrasco
0
280
The Curious Case for Waylosing
cassininazir
1
580
How Software Deployment tools have changed in the past 20 years
geshan
2
35k
Templates, Plugins, & Blocks: Oh My! Creating the theme that thinks of everything
marktimemedia
31
2.9k
What the history of the web can teach us about the future of AI
inesmontani
PRO
2
750
The SEO identity crisis: Don't let AI make you average
varn
0
610
Effective software design: The role of men in debugging patriarchy in IT @ Voxxed Days AMS
baasie
1
580
Speed Design
sergeychernyshev
33
2.2k
No one is an island. Learnings from fostering a developers community.
thoeni
21
3.9k
Transcript
多階層スコアリングに基づく マルチモーダル RAG による Embodied QA ⾼科明哲 1,是⽅諒介 1,王亜楠 2,杉浦孔明
1 1慶應義塾⼤学, 2KDDI総合研究所 -1
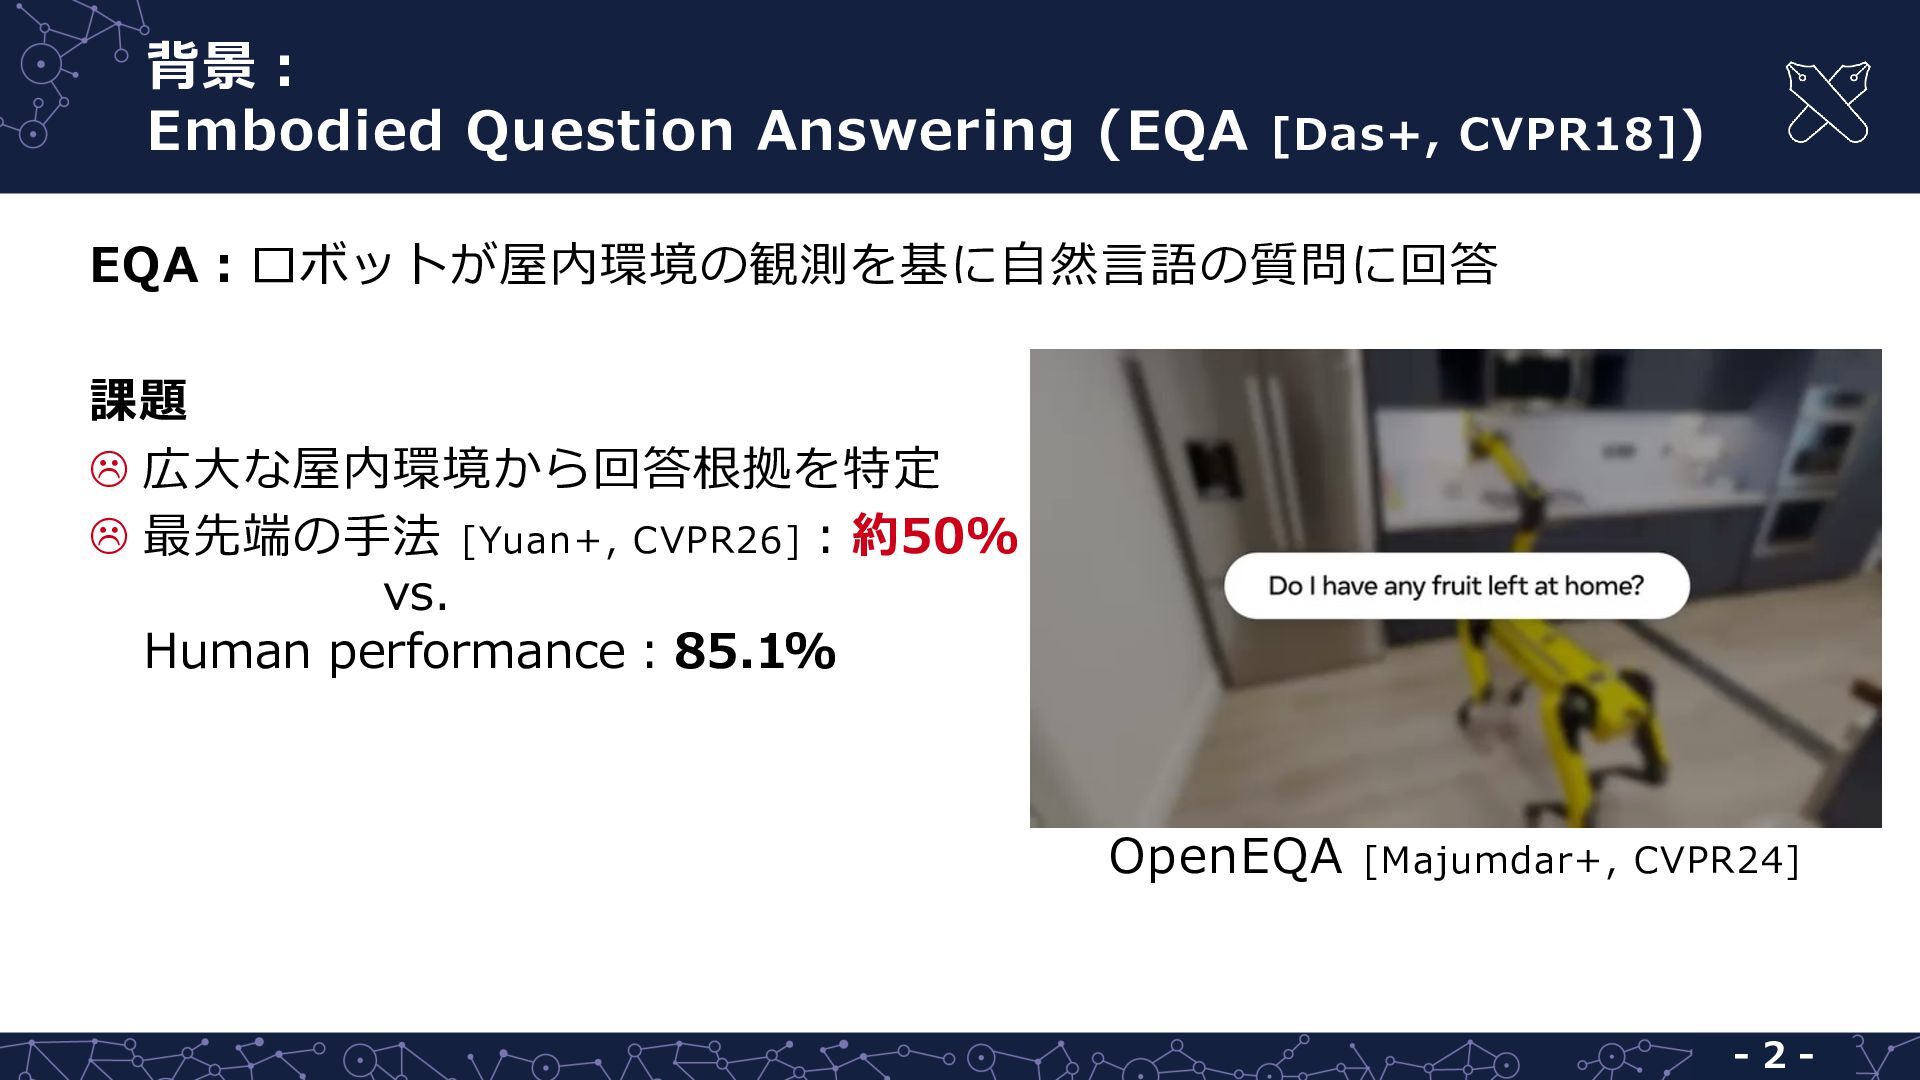
背景︓ Embodied Question Answering (EQA [Das+, CVPR18] ) EQA︓ロボットが屋内環境の観測を基に⾃然⾔語の質問に回答 課題
L 広⼤な屋内環境から回答根拠を特定 L 最先端の⼿法 [Yuan+, CVPR26] ︓約50% vs. Human performance︓85.1% OpenEQA [Majumdar+, CVPR24] -2-
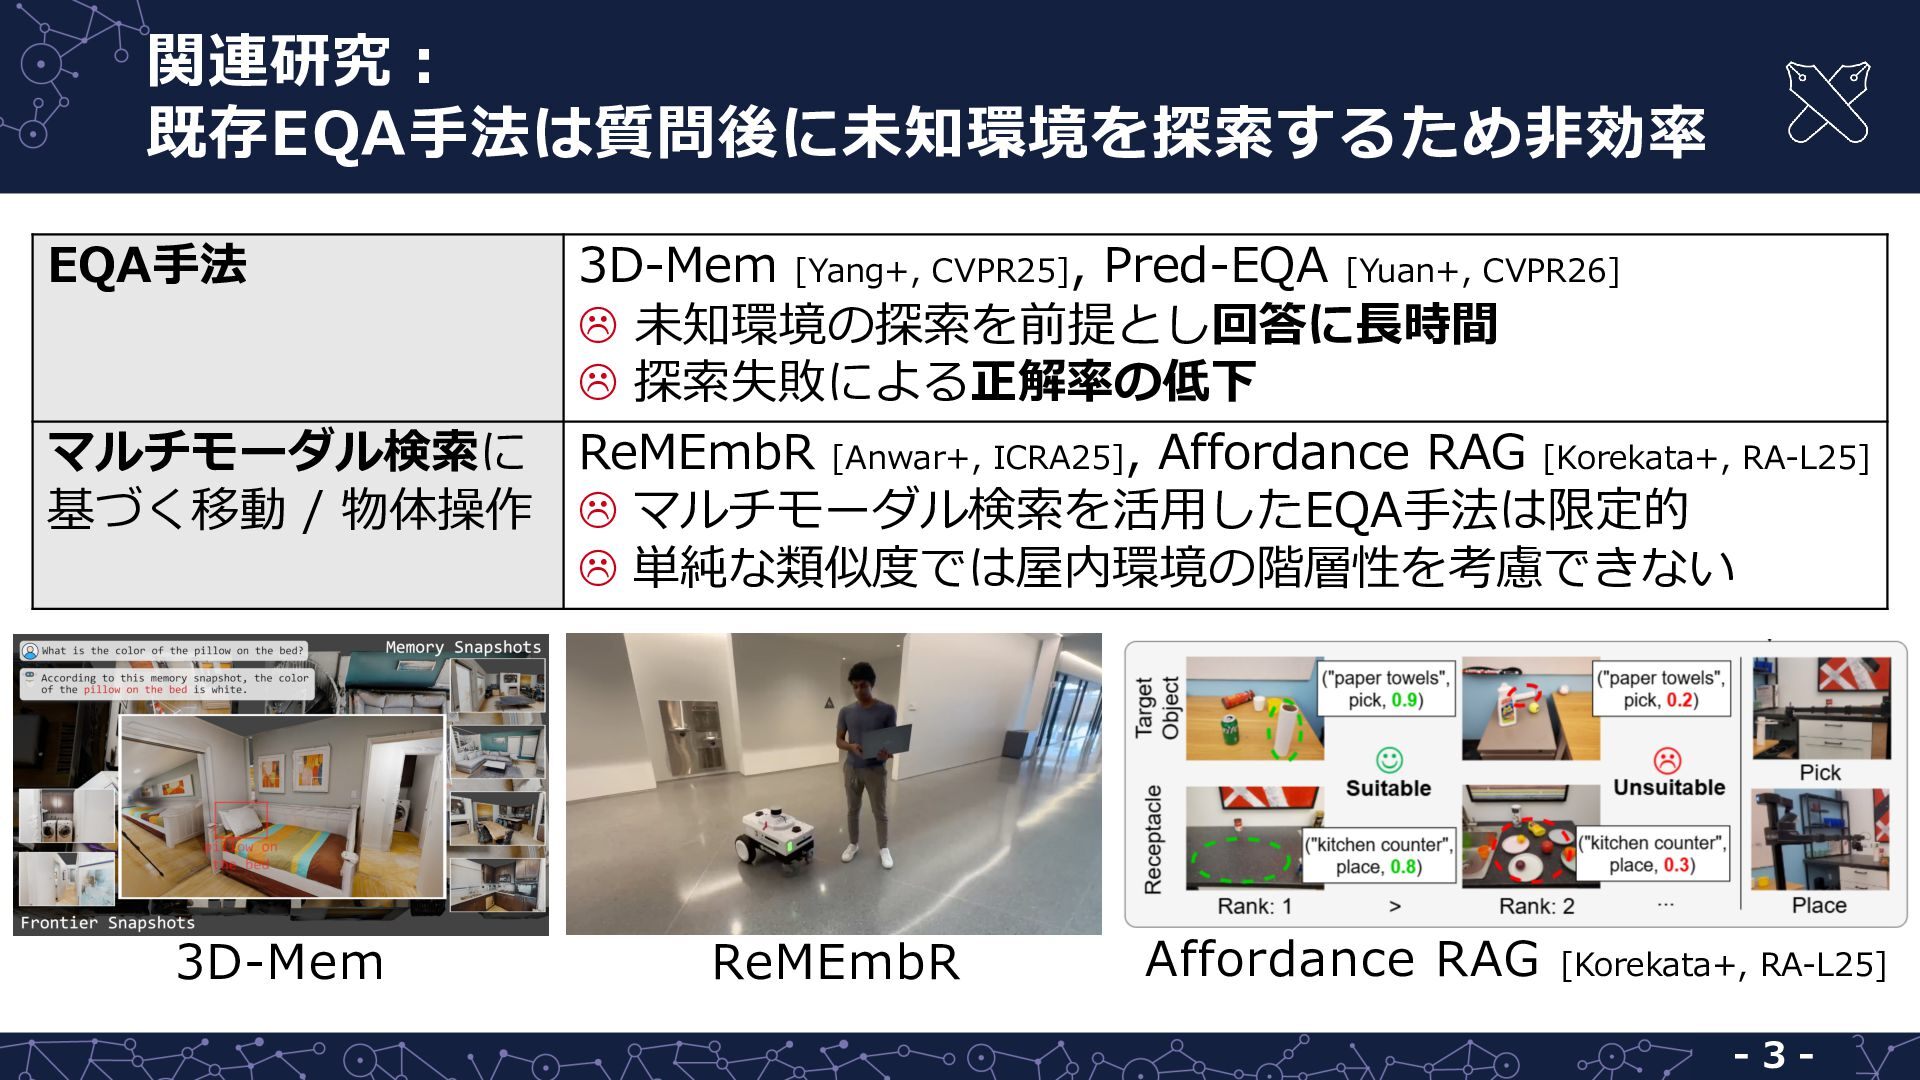
関連研究︓ 既存EQA⼿法は質問後に未知環境を探索するため⾮効率 EQA⼿法 ▪ aaa 3D-Mem [Yang+, CVPR25], Pred-EQA [Yuan+,
CVPR26] L 未知環境の探索を前提とし回答に⻑時間 L 探索失敗による正解率の低下 マルチモーダル検索に ReMEmbR [Anwar+, ICRA25], Affordance RAG [Korekata+, RA-L25] 基づく移動 / 物体操作 L マルチモーダル検索を活⽤したEQA⼿法は限定的 L 単純な類似度では屋内環境の階層性を考慮できない 3D-Mem ReMEmbR Affordance RAG [Korekata+, RA-L25] -3-
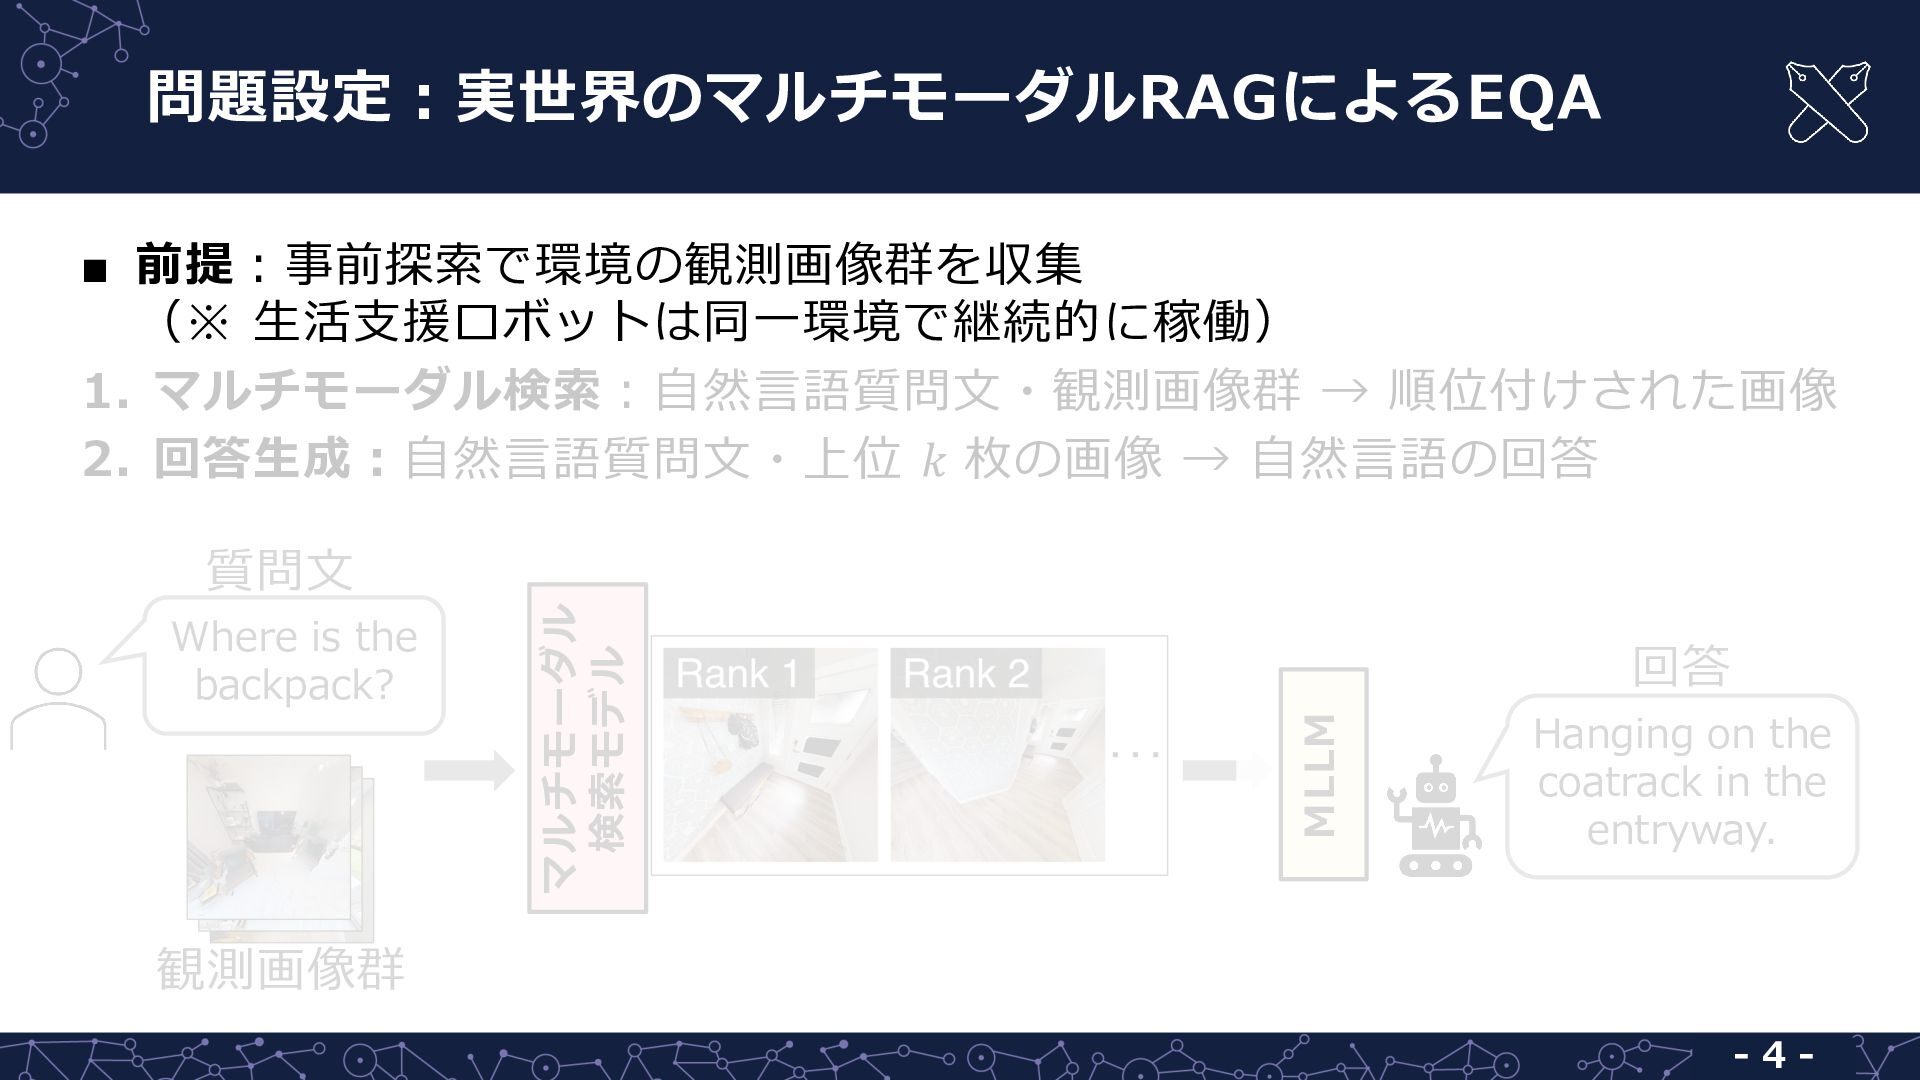
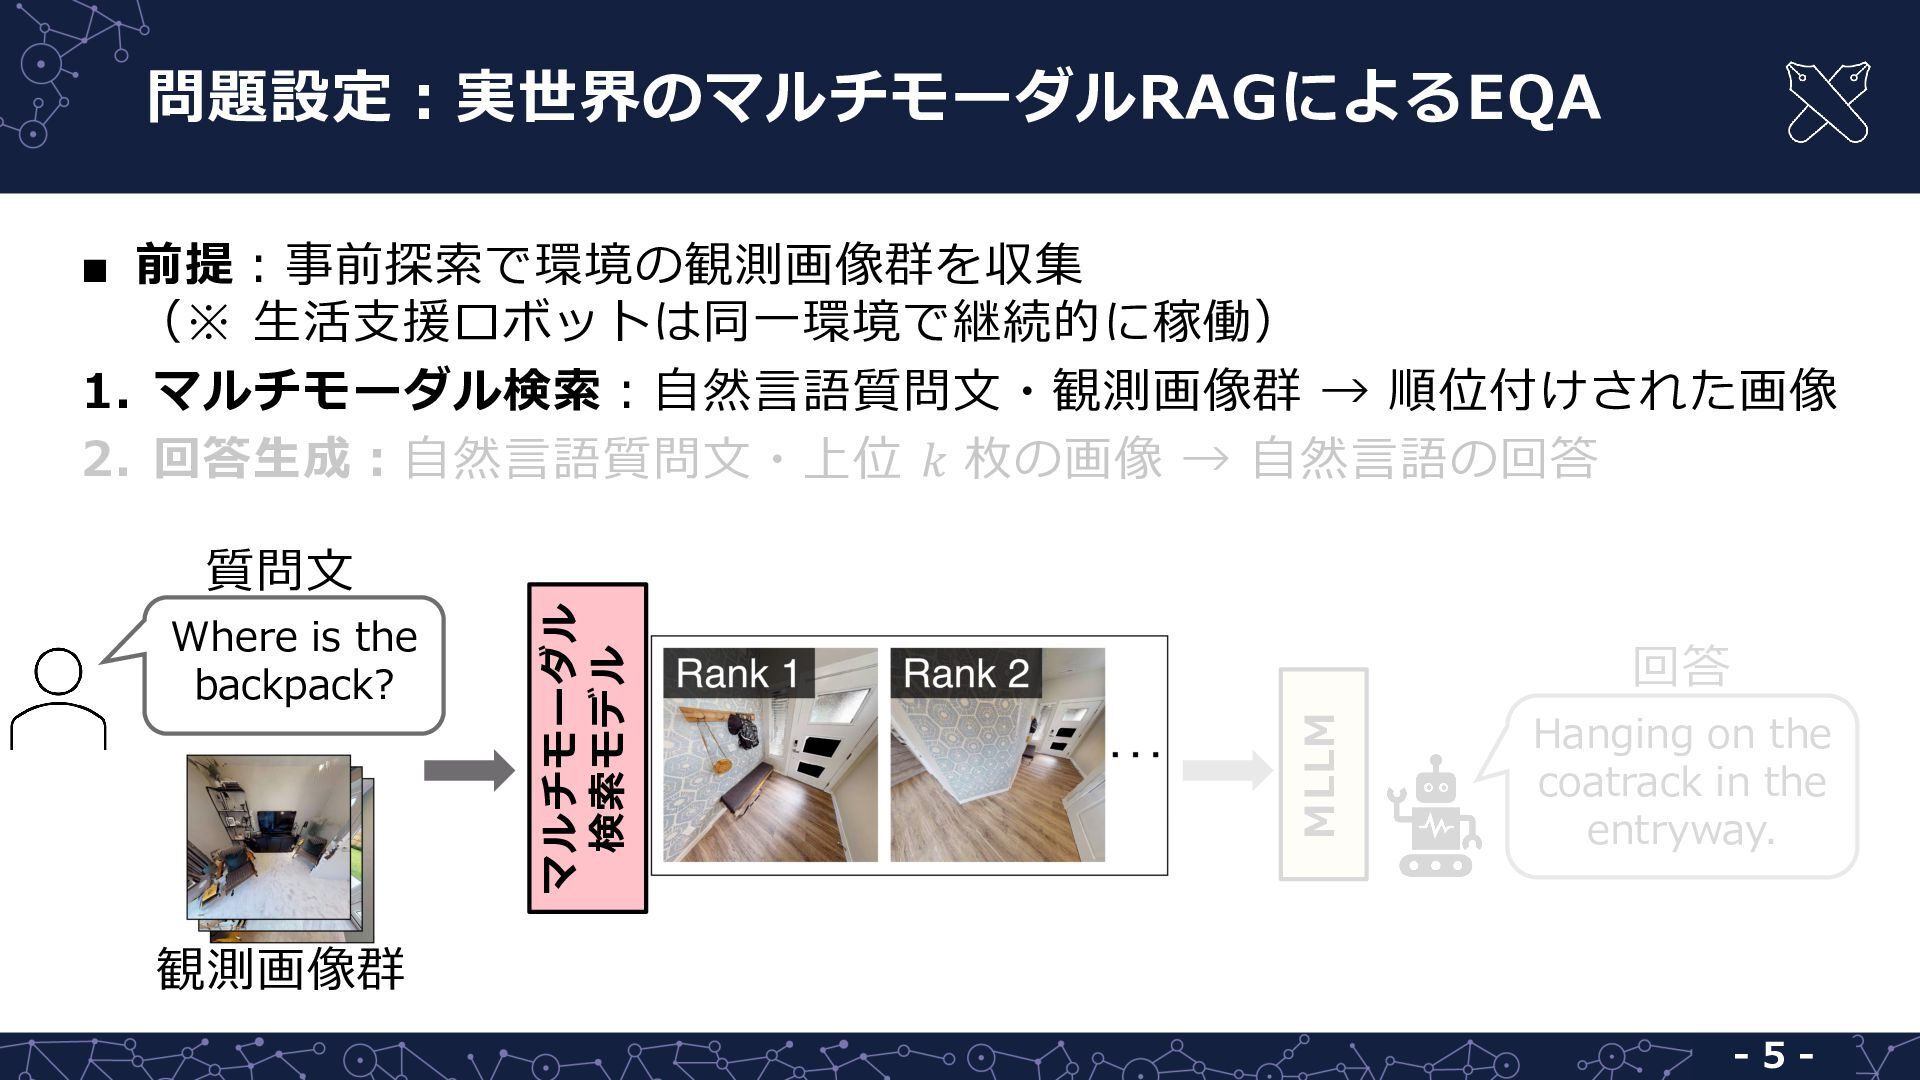
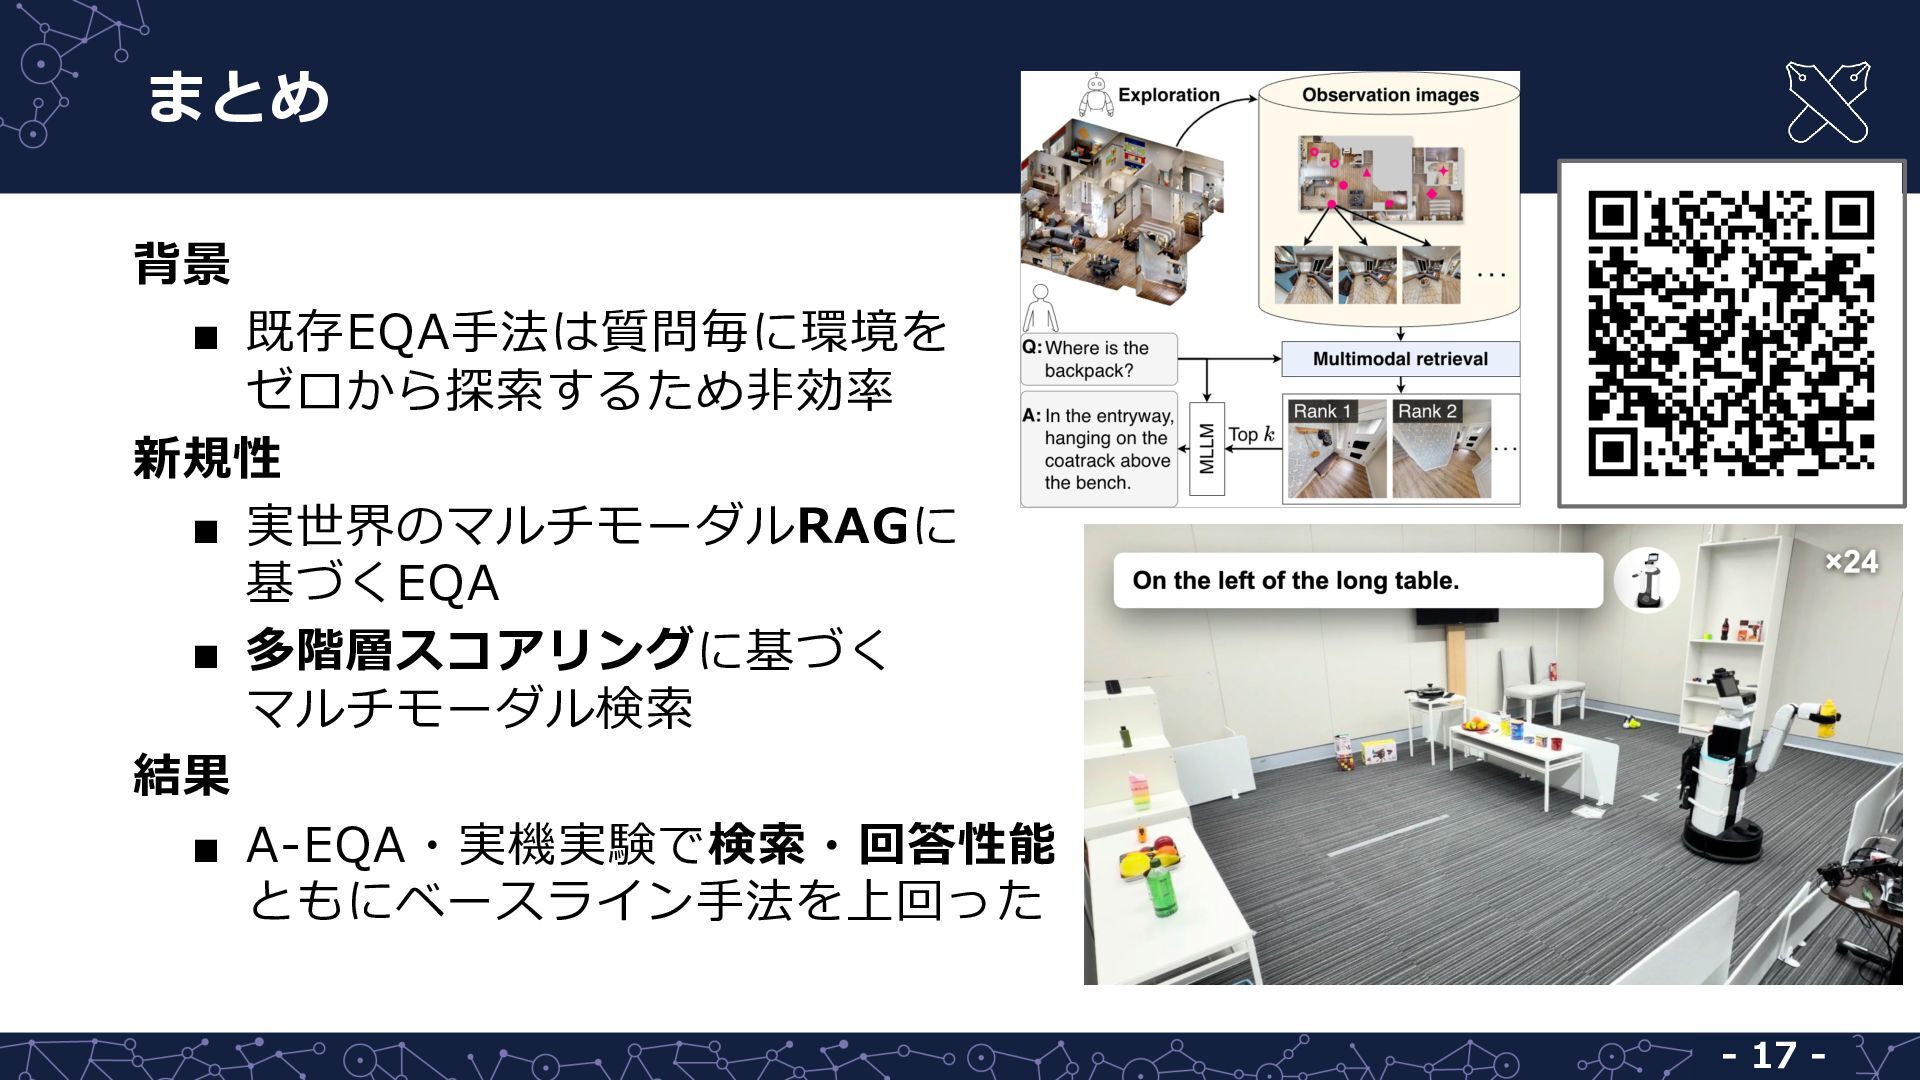
問題設定︓実世界のマルチモーダルRAGによるEQA Where is the backpack? 回答 MLLM 質問⽂ マルチモーダル 検索モデル
▪ 前提︓事前探索で環境の観測画像群を収集 (※ ⽣活⽀援ロボットは同⼀環境で継続的に稼働) 1. マルチモーダル検索︓⾃然⾔語質問⽂・観測画像群 → 順位付けされた画像 2. 回答⽣成︓⾃然⾔語質問⽂・上位 𝑘 枚の画像 → ⾃然⾔語の回答 Hanging on the coatrack in the entryway. 観測画像群 -4-
問題設定︓実世界のマルチモーダルRAGによるEQA Where is the backpack? 回答 MLLM 質問⽂ マルチモーダル 検索モデル
▪ 前提︓事前探索で環境の観測画像群を収集 (※ ⽣活⽀援ロボットは同⼀環境で継続的に稼働) 1. マルチモーダル検索︓⾃然⾔語質問⽂・観測画像群 → 順位付けされた画像 2. 回答⽣成︓⾃然⾔語質問⽂・上位 𝑘 枚の画像 → ⾃然⾔語の回答 Hanging on the coatrack in the entryway. 観測画像群 -5-
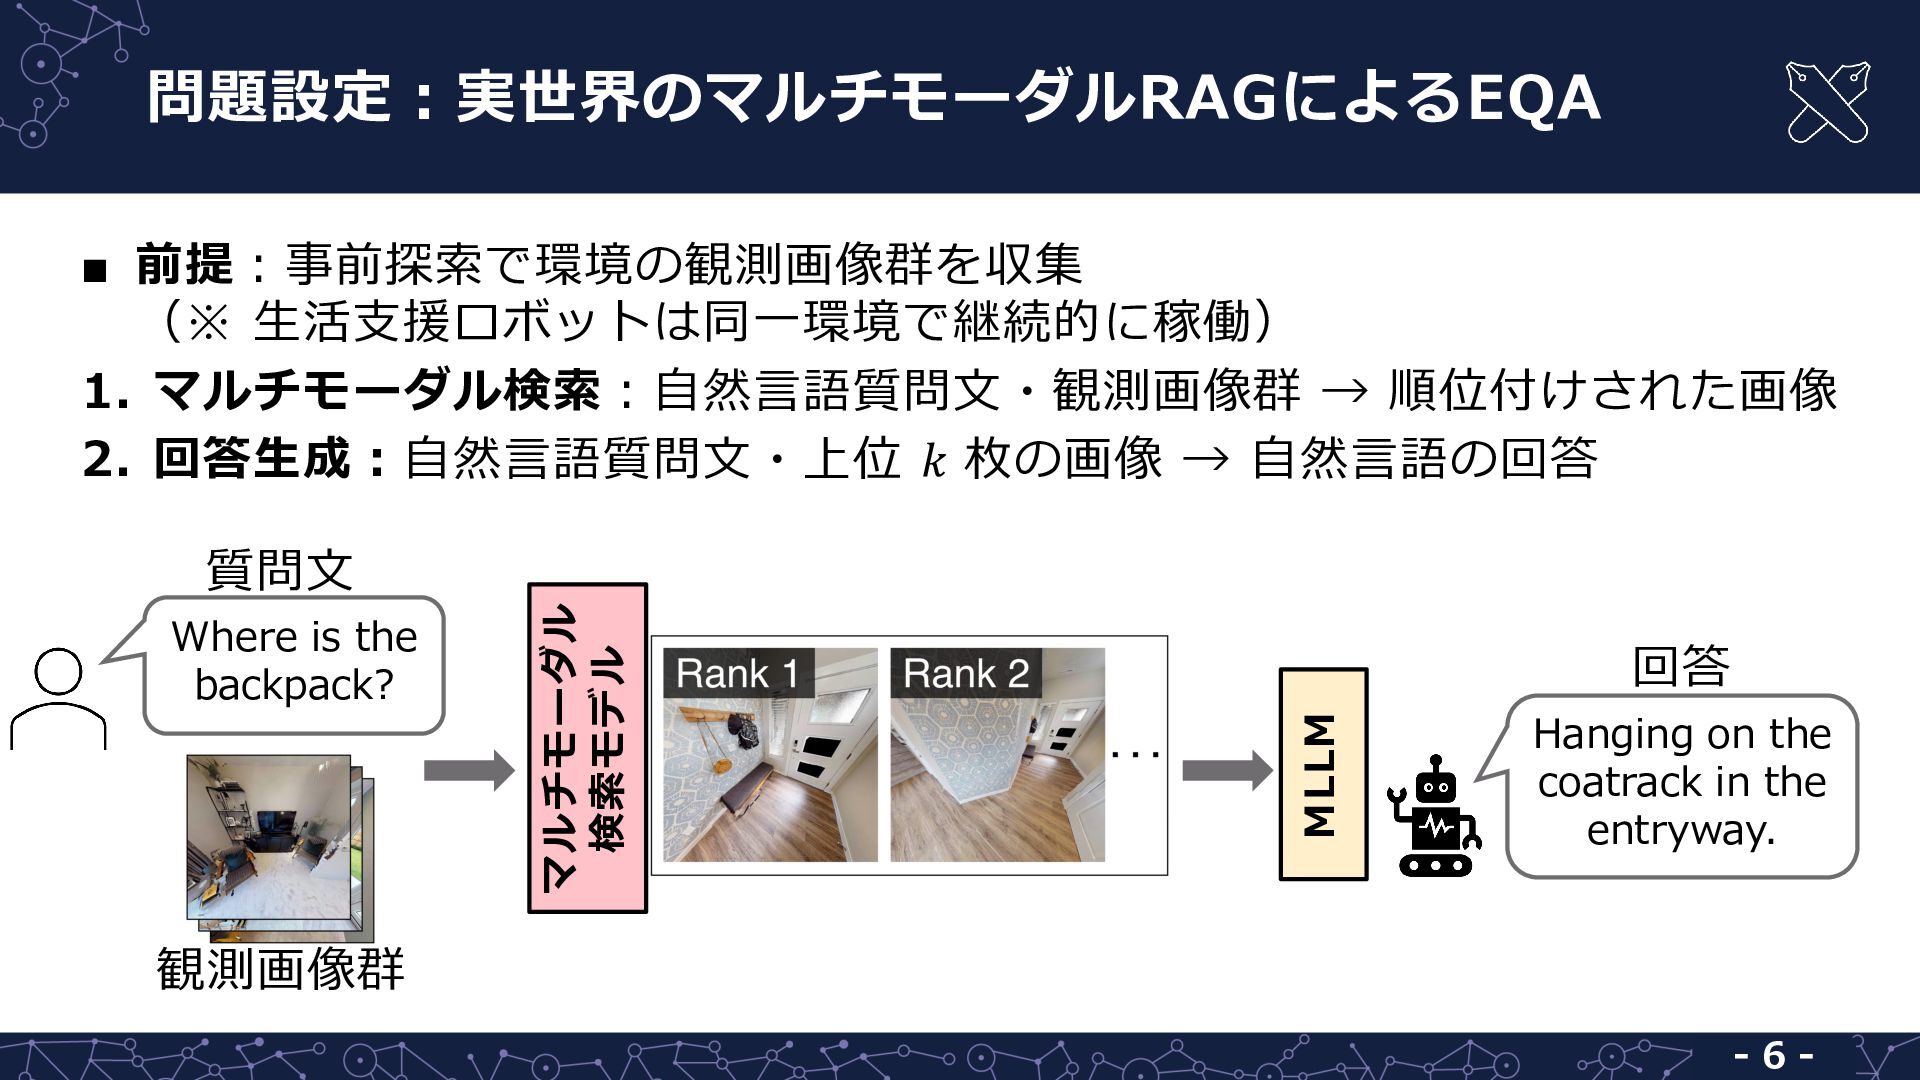
問題設定︓実世界のマルチモーダルRAGによるEQA Where is the backpack? 回答 MLLM 質問⽂ マルチモーダル 検索モデル
▪ 前提︓事前探索で環境の観測画像群を収集 (※ ⽣活⽀援ロボットは同⼀環境で継続的に稼働) 1. マルチモーダル検索︓⾃然⾔語質問⽂・観測画像群 → 順位付けされた画像 2. 回答⽣成︓⾃然⾔語質問⽂・上位 𝑘 枚の画像 → ⾃然⾔語の回答 Hanging on the coatrack in the entryway. 観測画像群 -6-
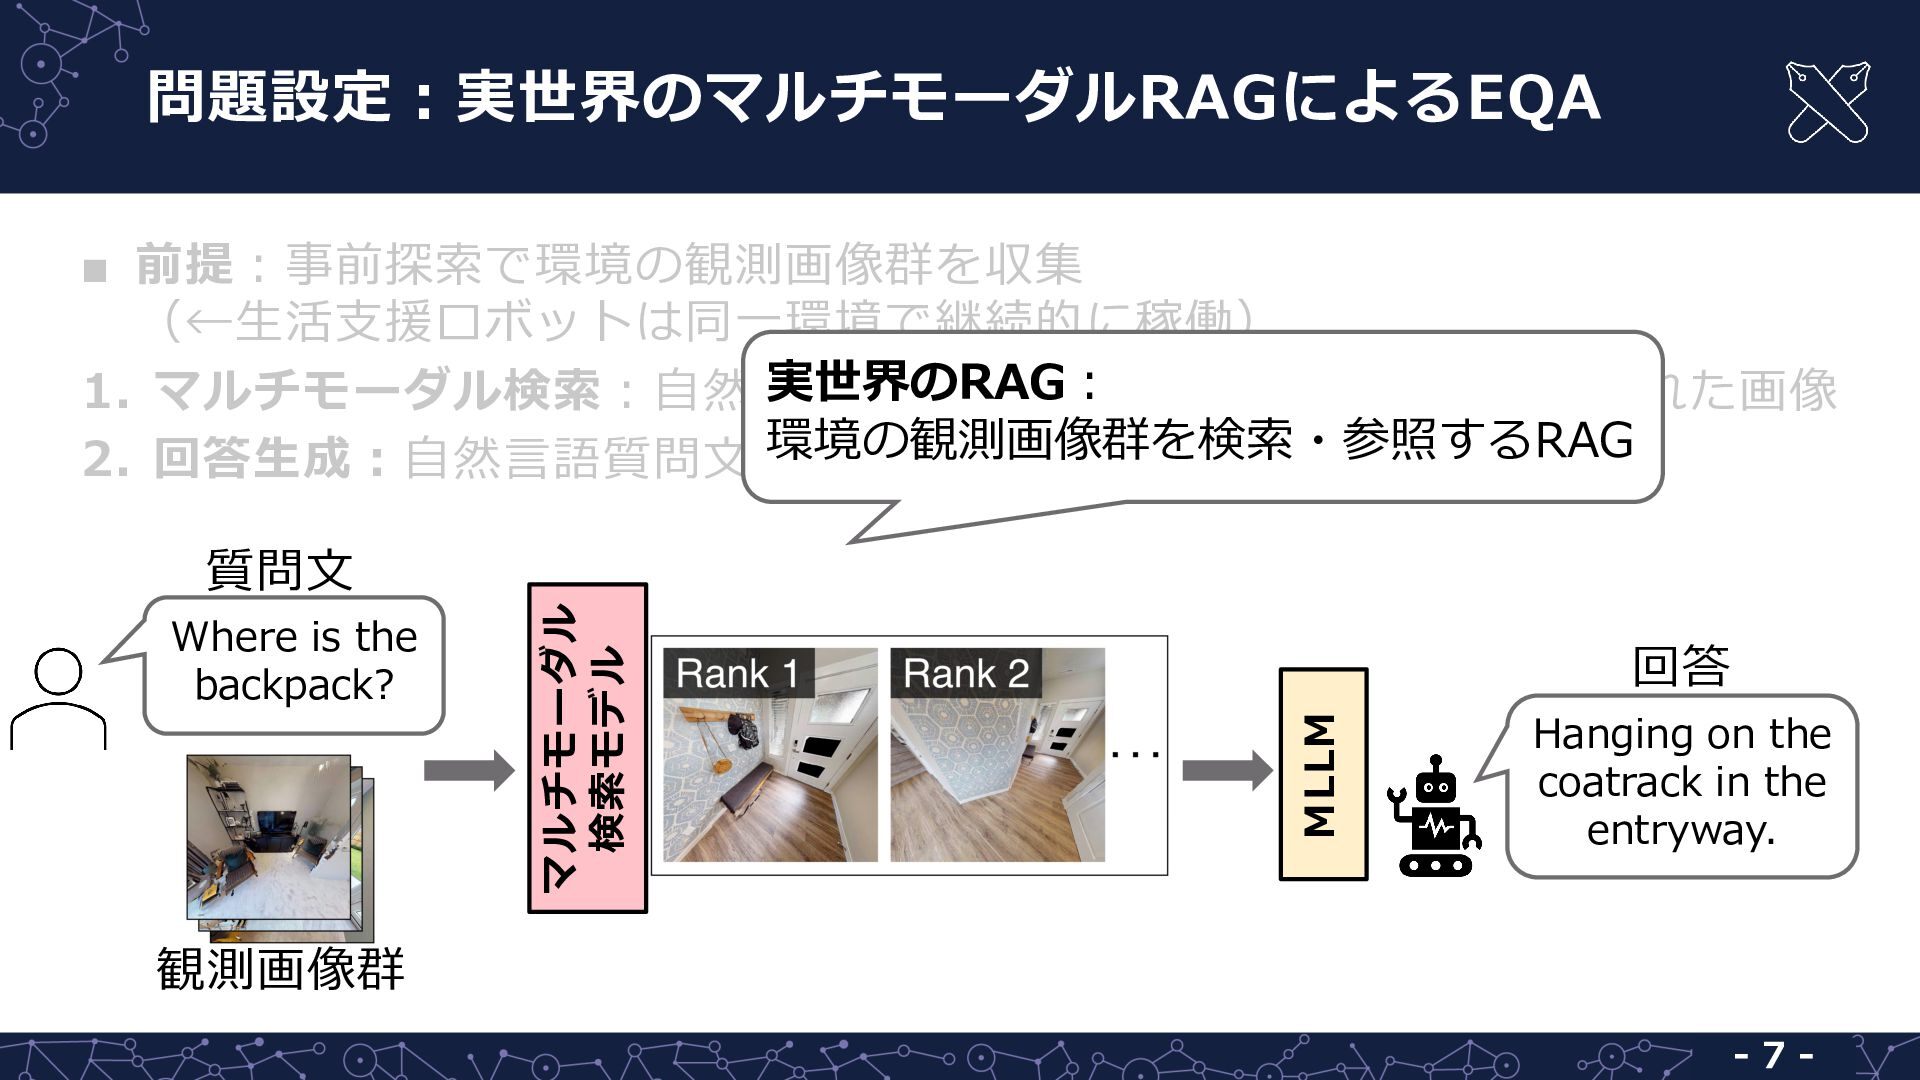
問題設定︓実世界のマルチモーダルRAGによるEQA Where is the backpack? 回答 MLLM 質問⽂ マルチモーダル 検索モデル
▪ 前提︓事前探索で環境の観測画像群を収集 (←⽣活⽀援ロボットは同⼀環境で継続的に稼働) 実世界のRAG︓ 1. マルチモーダル検索︓⾃然⾔語質問⽂・観測画像群 → 順位付けされた画像 環境の観測画像群を検索・参照するRAG 2. 回答⽣成︓⾃然⾔語質問⽂・上位 𝑘 枚の画像 → ⾃然⾔語の回答 Hanging on the coatrack in the entryway. 観測画像群 -7-
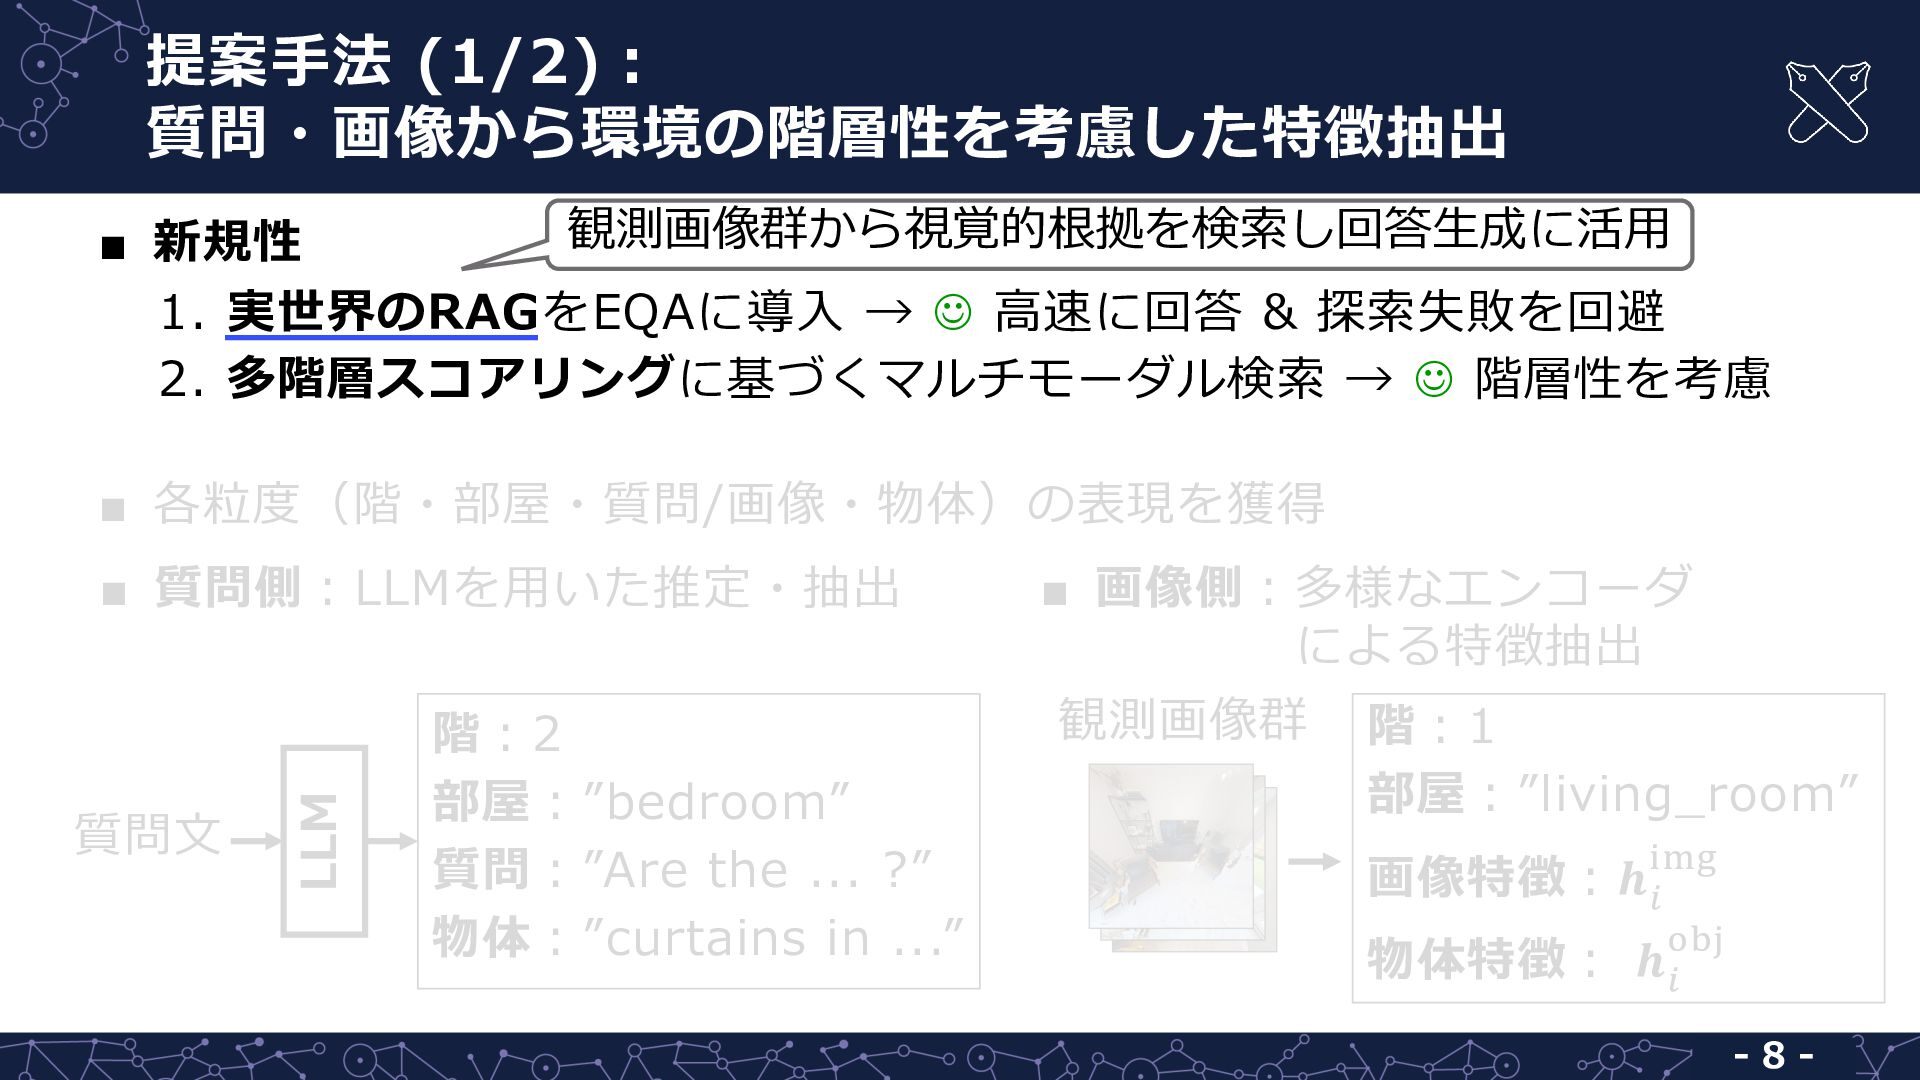
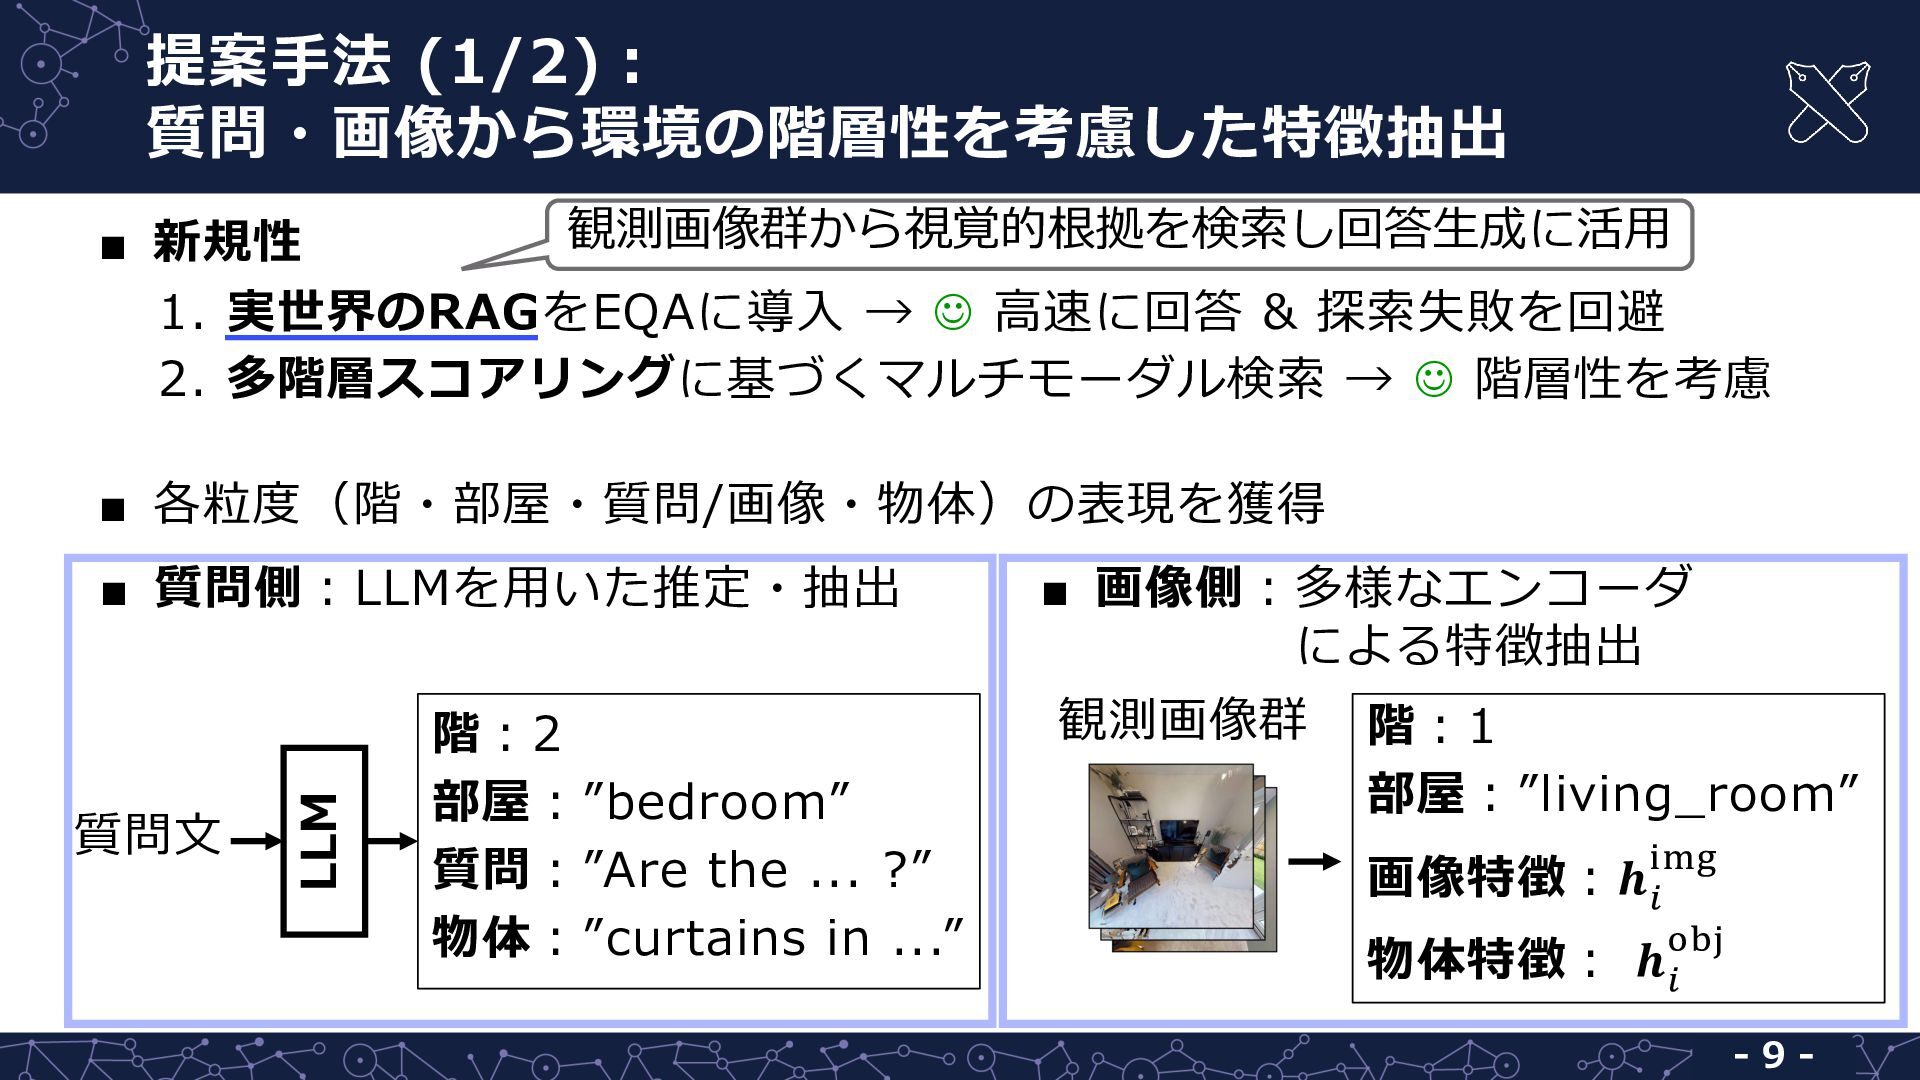
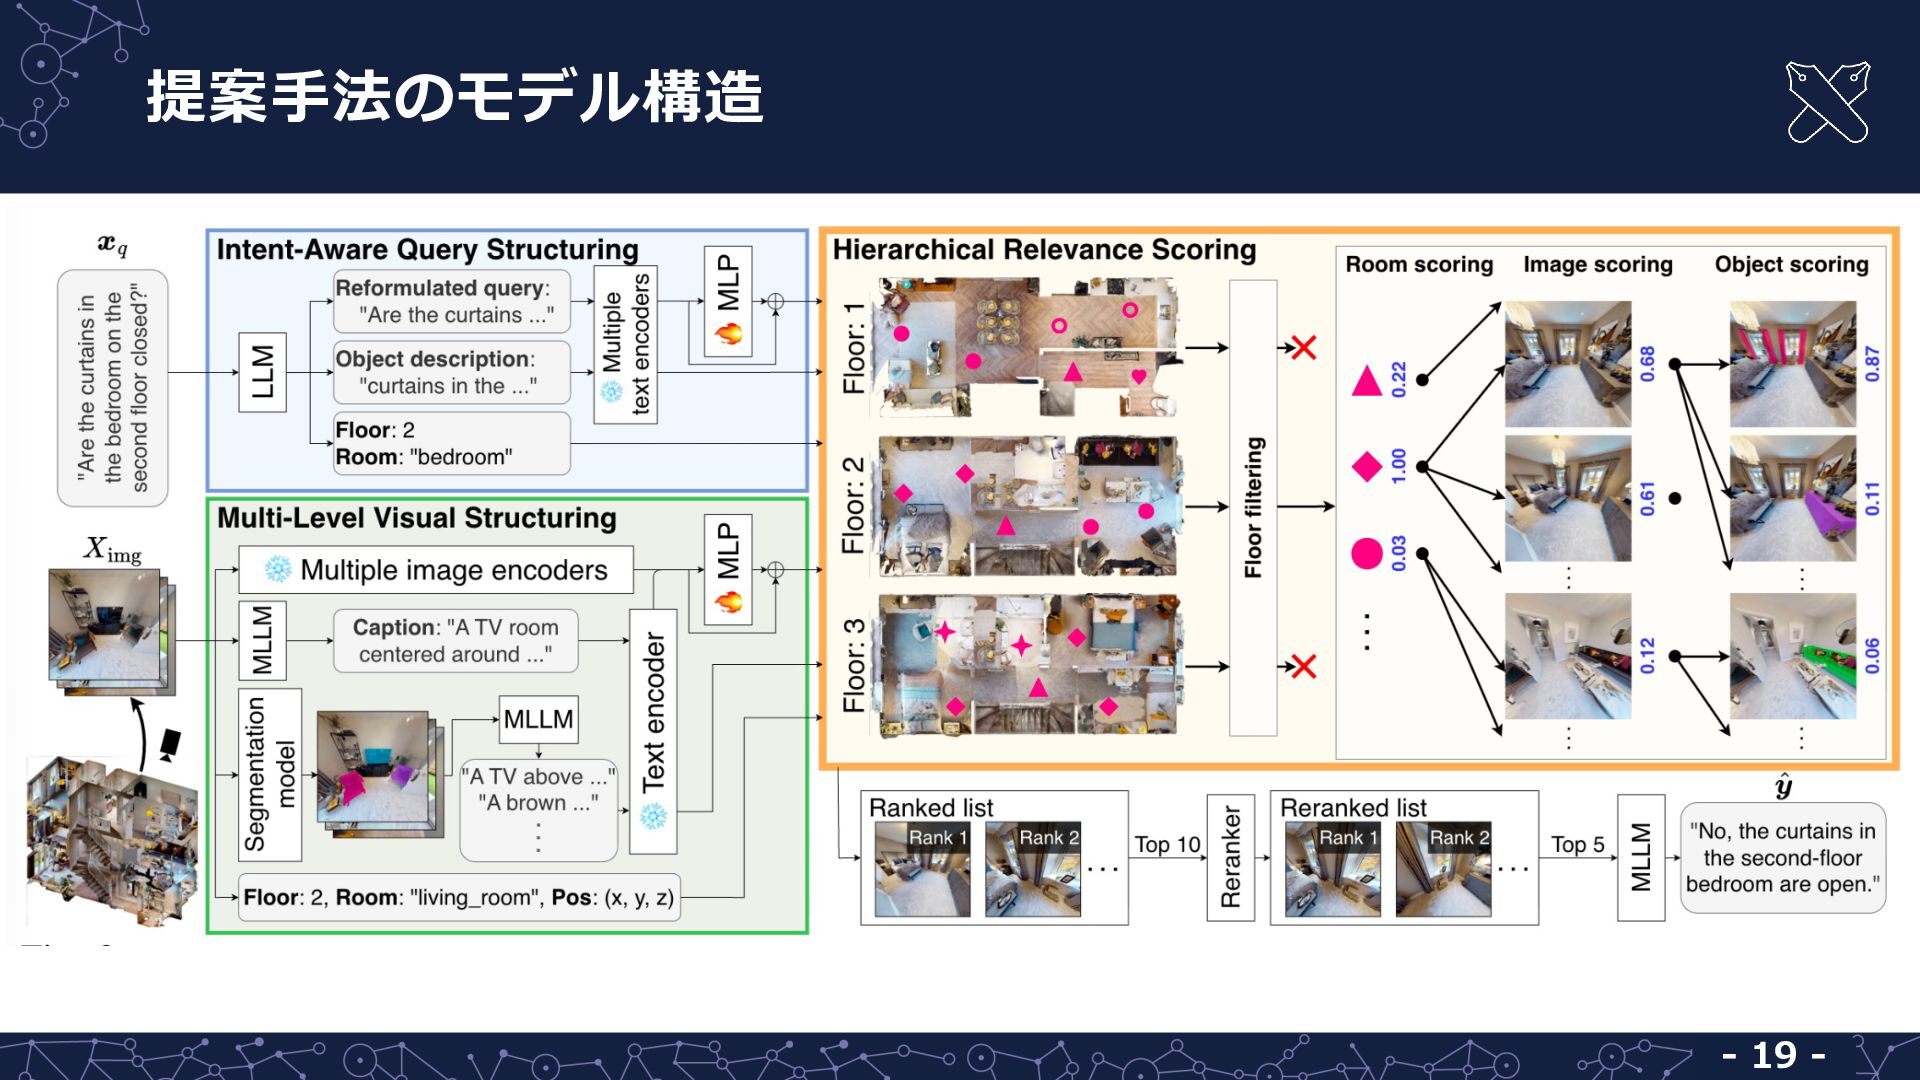
提案⼿法 (1/2)︓ 質問・画像から環境の階層性を考慮した特徴抽出 観測画像群から視覚的根拠を検索し回答⽣成に活⽤ ▪ 新規性 1. 実世界のRAGをEQAに導⼊ → J
⾼速に回答 & 探索失敗を回避 2. 多階層スコアリングに基づくマルチモーダル検索 → J 階層性を考慮 ▪ 各粒度(階・部屋・質問/画像・物体)の表現を獲得 質問⽂ LLM ▪ 質問側︓LLMを⽤いた推定・抽出 階︓2 部屋︓”bedroom” 質問︓”Are the ... ?” 物体︓”curtains in ...” ▪ 画像側︓多様なエンコーダ による特徴抽出 観測画像群 階︓1 部屋︓”living_room” "#$ 画像特徴︓𝒉 ! %&' 物体特徴︓ 𝒉 ! -8-
提案⼿法 (1/2)︓ 質問・画像から環境の階層性を考慮した特徴抽出 観測画像群から視覚的根拠を検索し回答⽣成に活⽤ ▪ 新規性 1. 実世界のRAGをEQAに導⼊ → J
⾼速に回答 & 探索失敗を回避 2. 多階層スコアリングに基づくマルチモーダル検索 → J 階層性を考慮 ▪ 各粒度(階・部屋・質問/画像・物体)の表現を獲得 質問⽂ LLM ▪ 質問側︓LLMを⽤いた推定・抽出 階︓2 部屋︓”bedroom” 質問︓”Are the ... ?” 物体︓”curtains in ...” ▪ 画像側︓多様なエンコーダ による特徴抽出 観測画像群 階︓1 部屋︓”living_room” "#$ 画像特徴︓𝒉 ! %&' 物体特徴︓ 𝒉 ! -9-
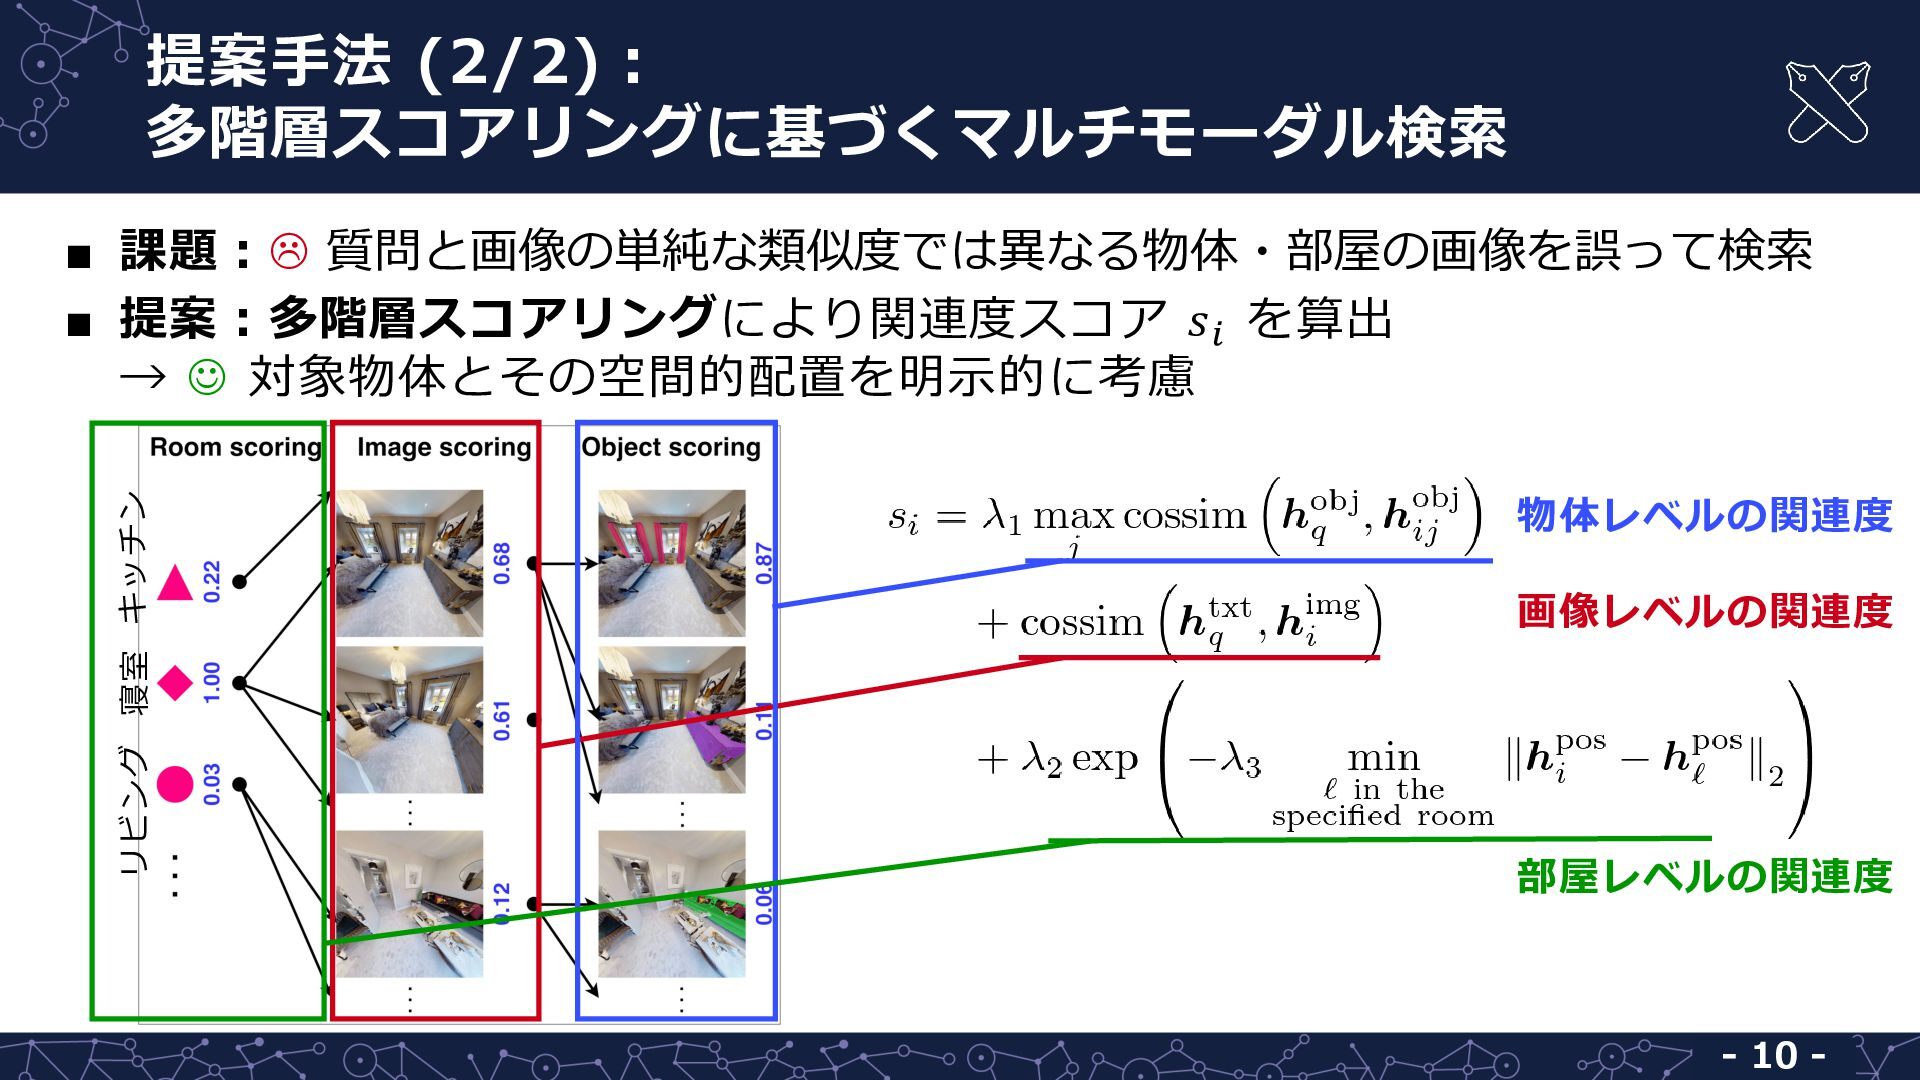
提案⼿法 (2/2)︓ 多階層スコアリングに基づくマルチモーダル検索 リビング 寝室 キッチン ▪ 課題︓L 質問と画像の単純な類似度では異なる物体・部屋の画像を誤って検索 ▪
提案︓多階層スコアリングにより関連度スコア 𝑠! を算出 → J 対象物体とその空間的配置を明⽰的に考慮 物体レベルの関連度 画像レベルの関連度 部屋レベルの関連度 - 10 -
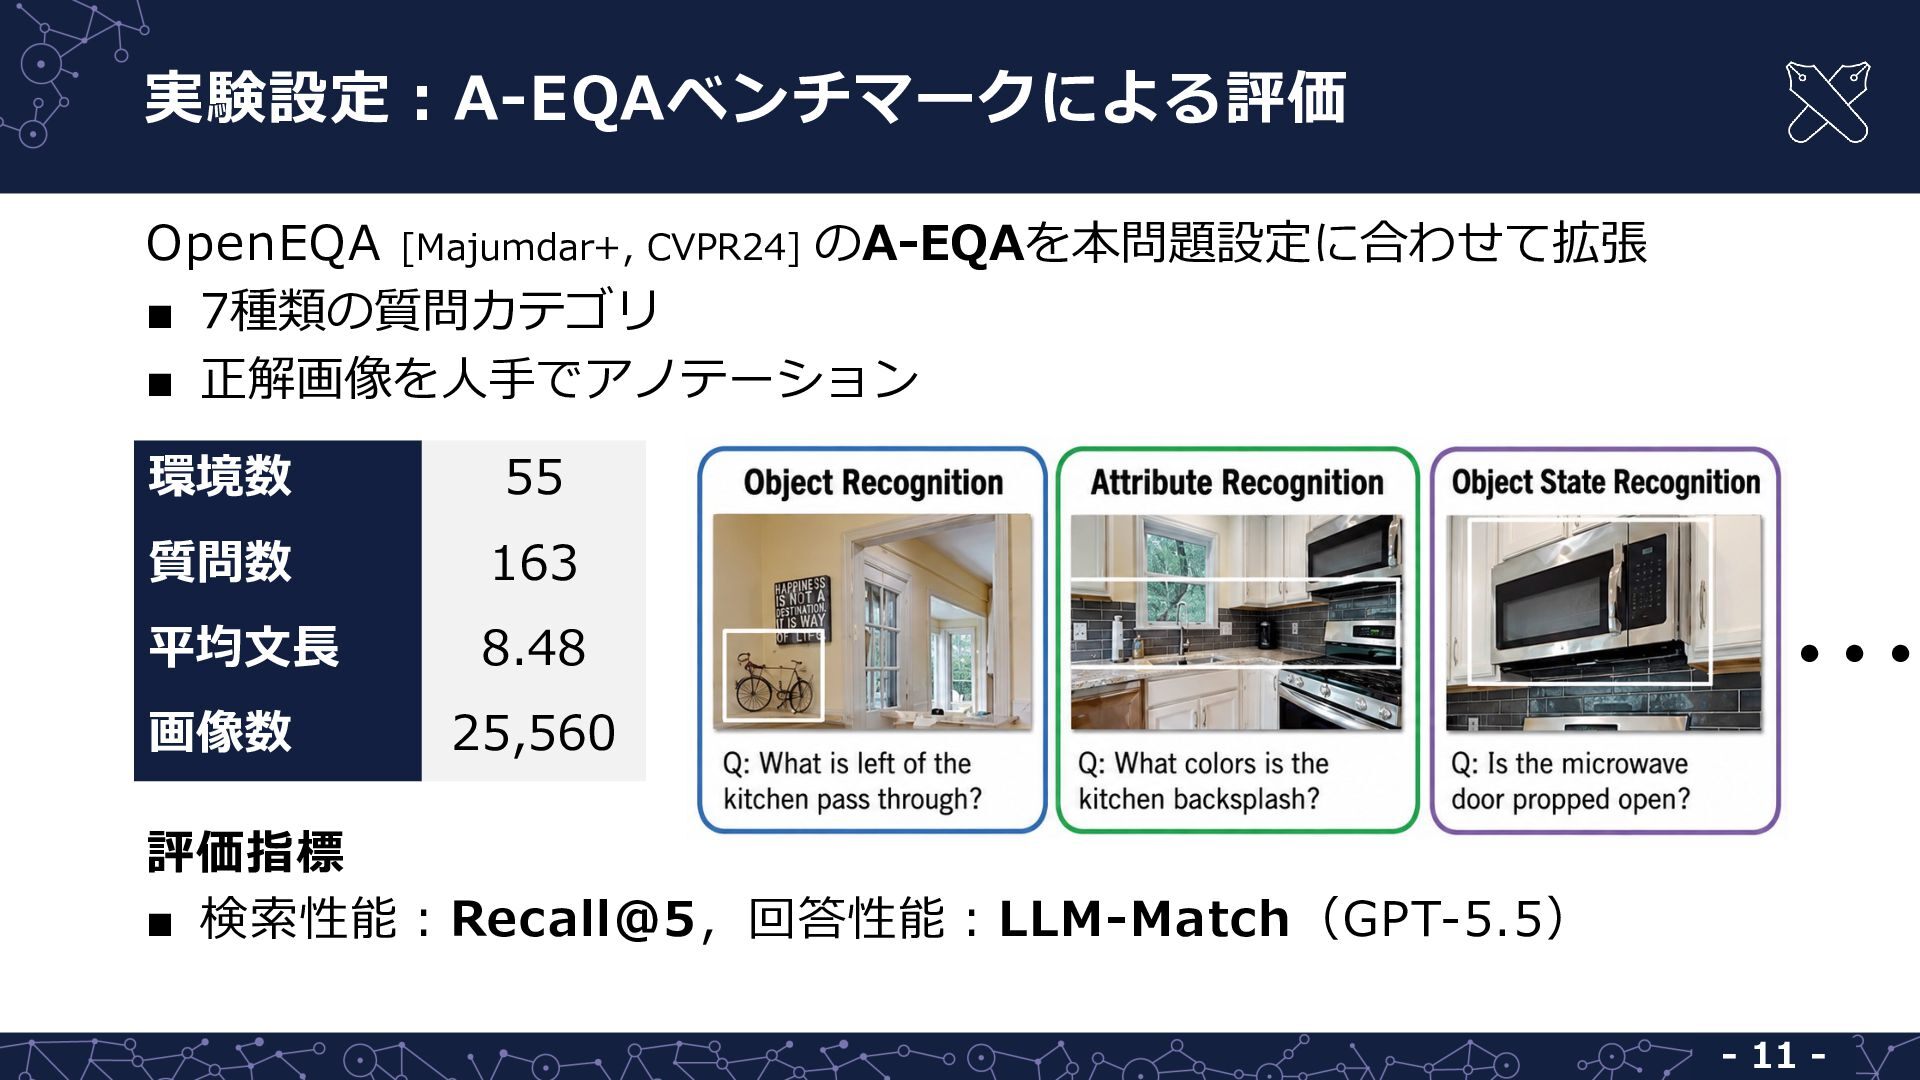
実験設定︓A-EQAベンチマークによる評価 OpenEQA [Majumdar+, CVPR24] のA-EQAを本問題設定に合わせて拡張 ▪ 7種類の質問カテゴリ ▪ 正解画像を⼈⼿でアノテーション 環境数
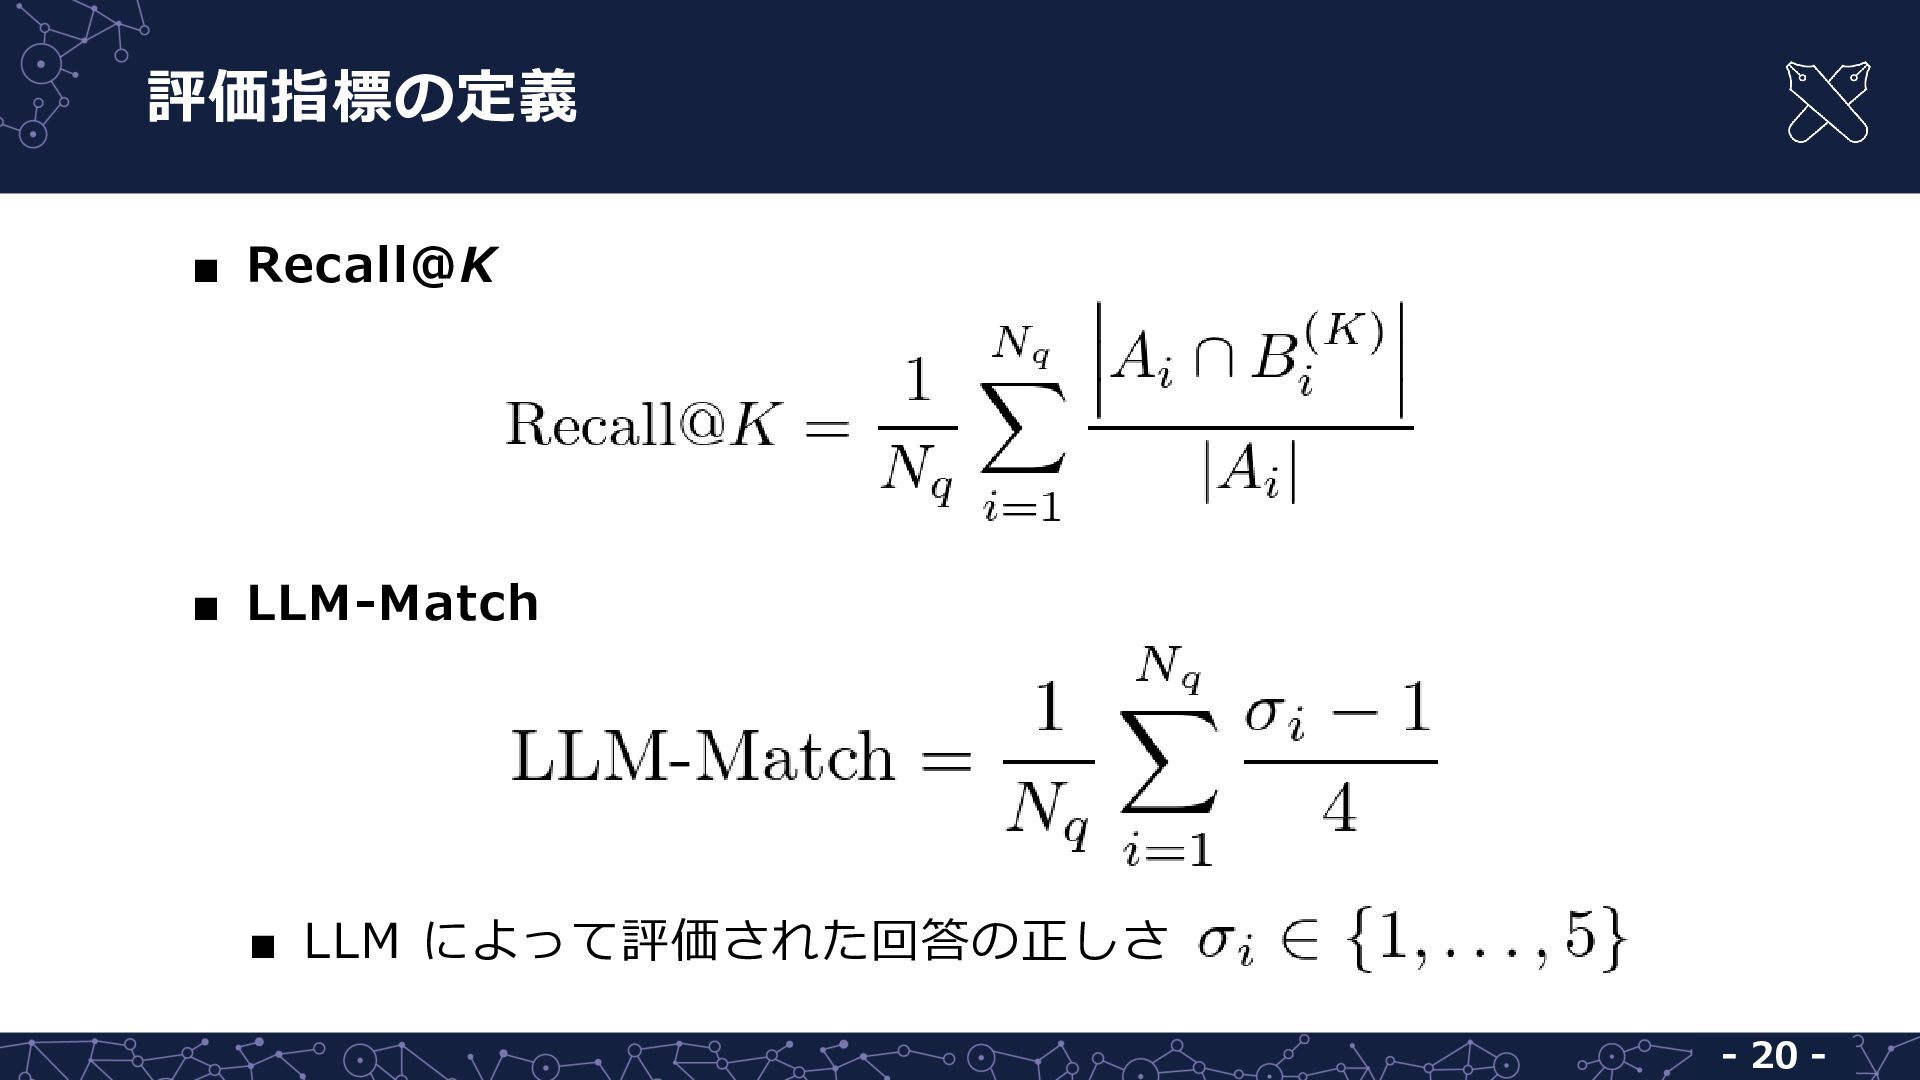
55 質問数 163 平均⽂⻑ 8.48 画像数 25,560 • • • 評価指標 ▪ 検索性能︓Recall@5,回答性能︓LLM-Match(GPT-5.5) - 11 -
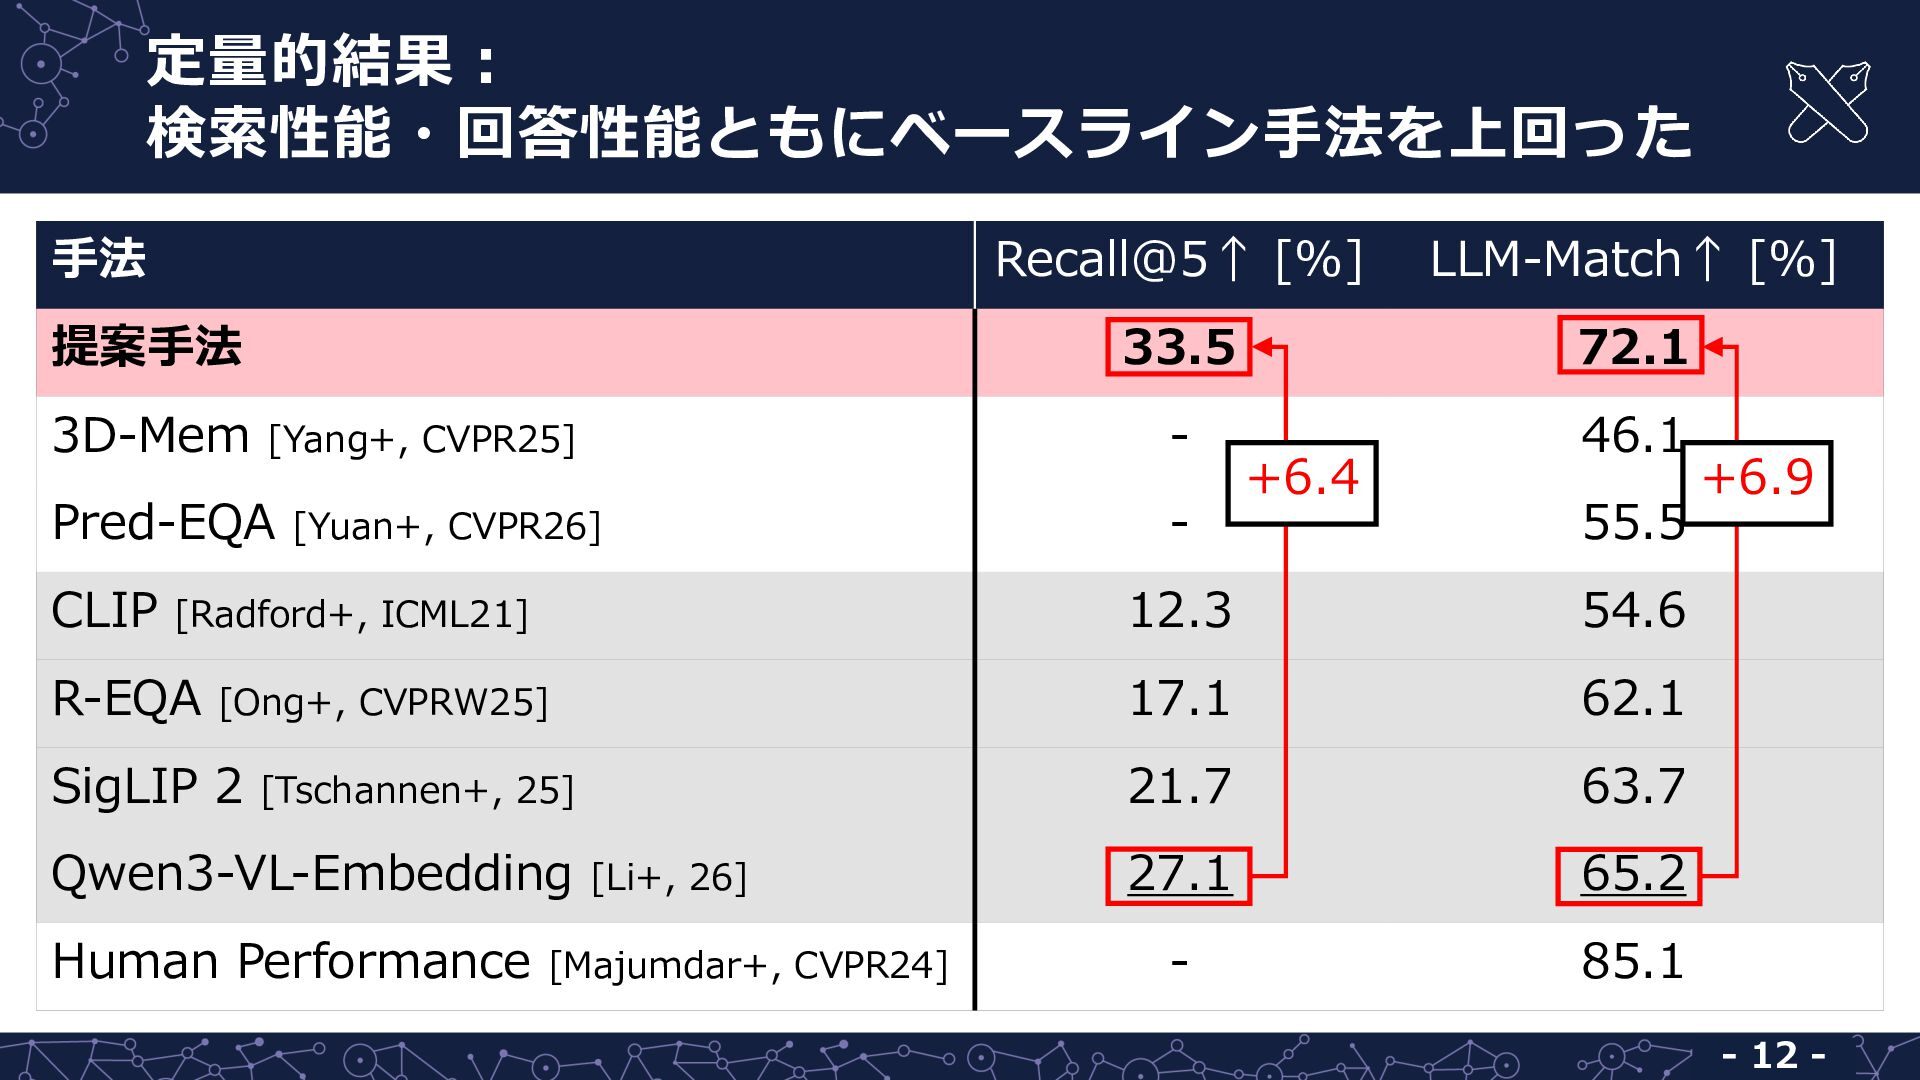
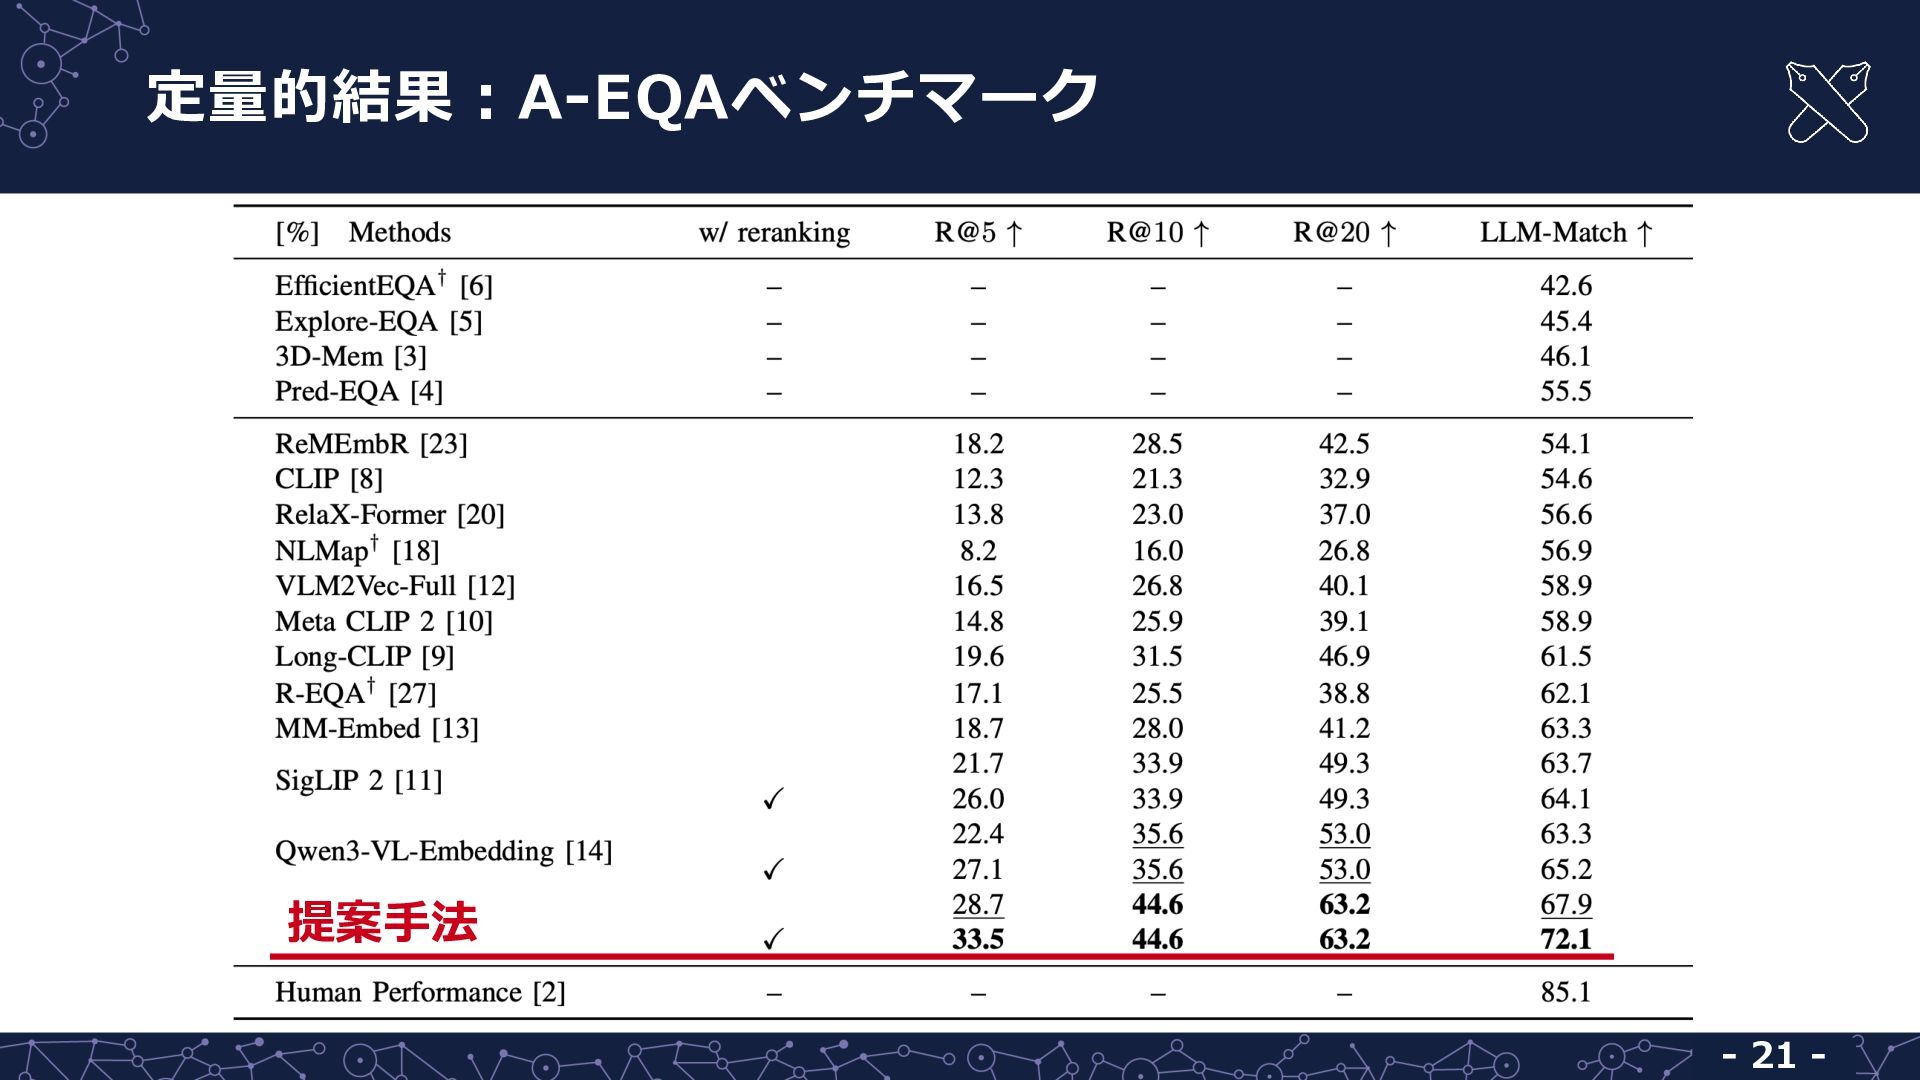
定量的結果︓ 検索性能・回答性能ともにベースライン⼿法を上回った ⼿法 Recall@5↑ [%] LLM-Match↑ [%] 33.5 72.1 3D-Mem
[Yang+, CVPR25] - 46.1 Pred-EQA [Yuan+, CVPR26] - 提案⼿法 +6.4 55.5 CLIP [Radford+, ICML21] 12.3 54.6 R-EQA [Ong+, CVPRW25] 17.1 62.1 SigLIP 2 [Tschannen+, 25] 21.7 63.7 Qwen3-VL-Embedding [Li+, 26] 27.1 65.2 - 85.1 Human Performance [Majumdar+, CVPR24] +6.9 - 12 -
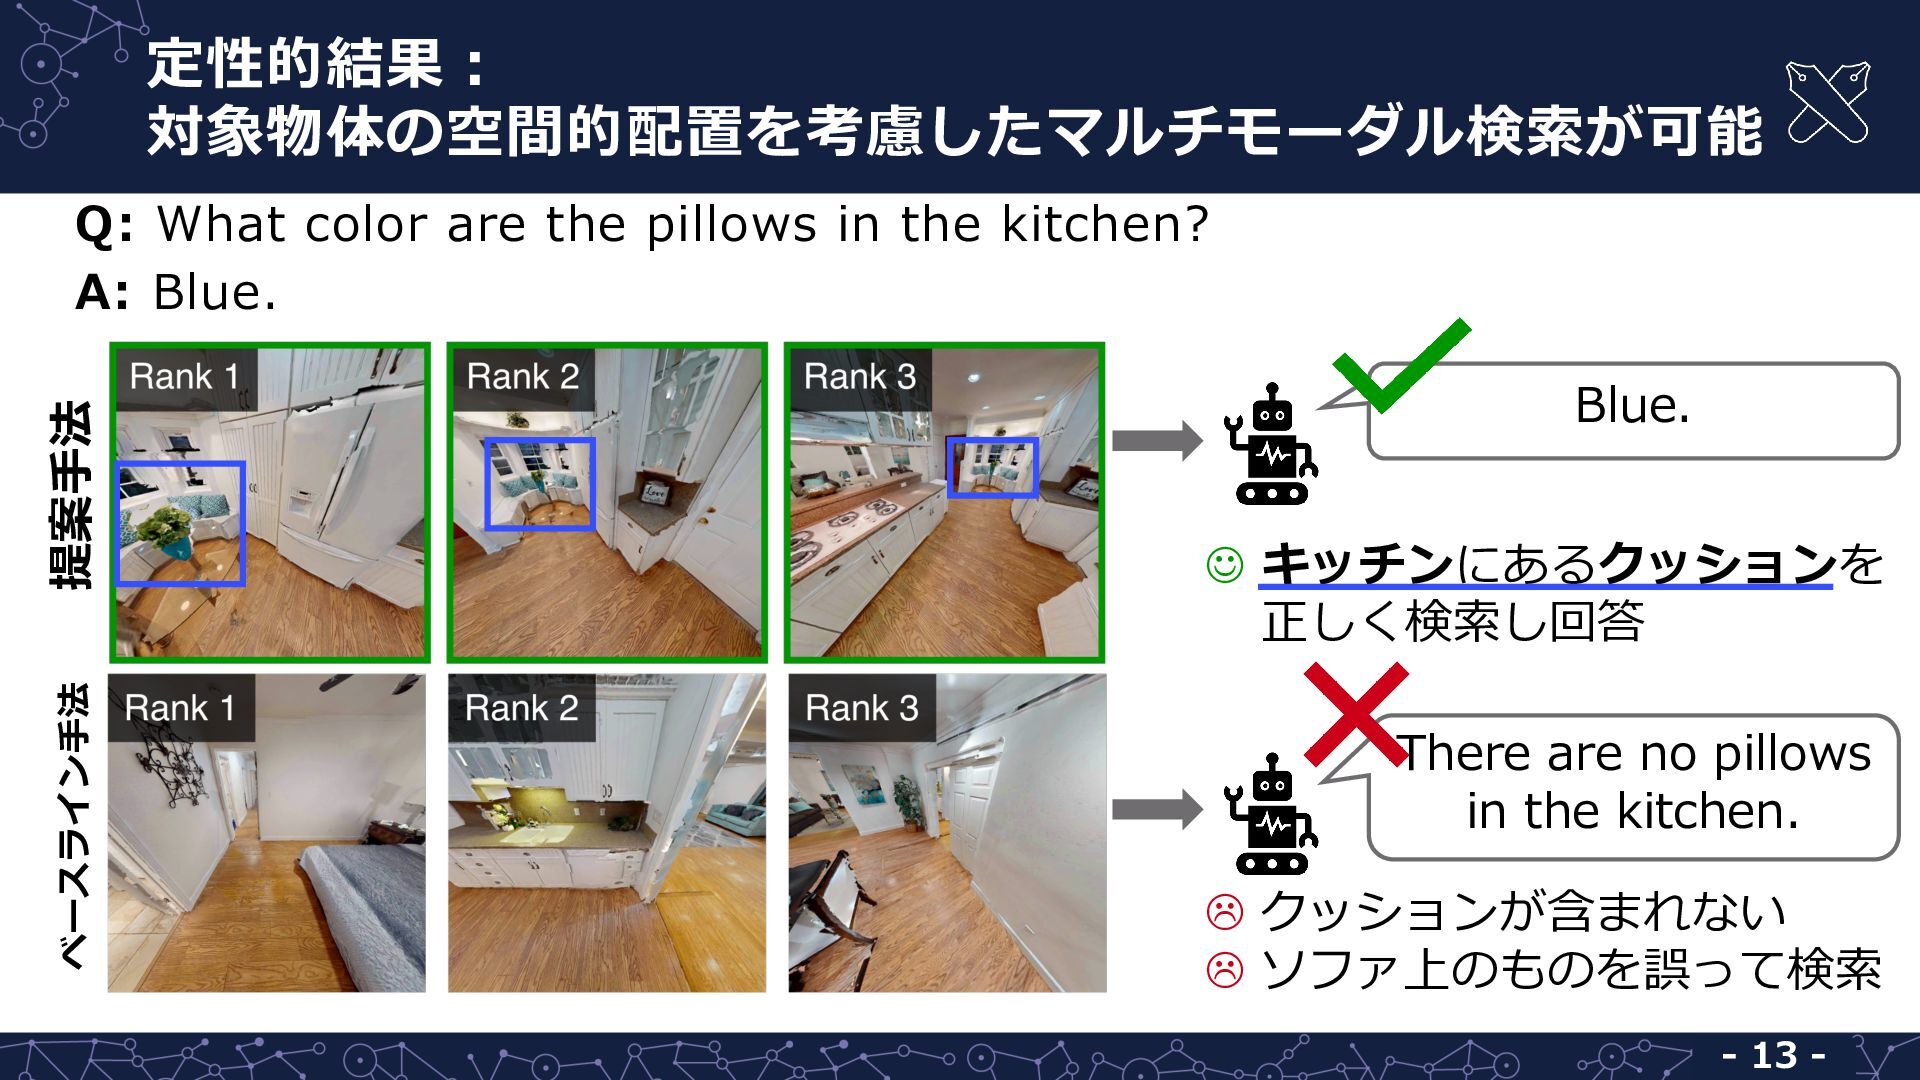
定性的結果︓ 対象物体の空間的配置を考慮したマルチモーダル検索が可能 ベースライン⼿法 提案⼿法 Q: What color are the pillows
in the kitchen? A: Blue. Blue. J キッチンにあるクッションを J 正しく検索し回答 There are no pillows in the kitchen. L クッションが含まれない L ソファ上のものを誤って検索 - 13 -
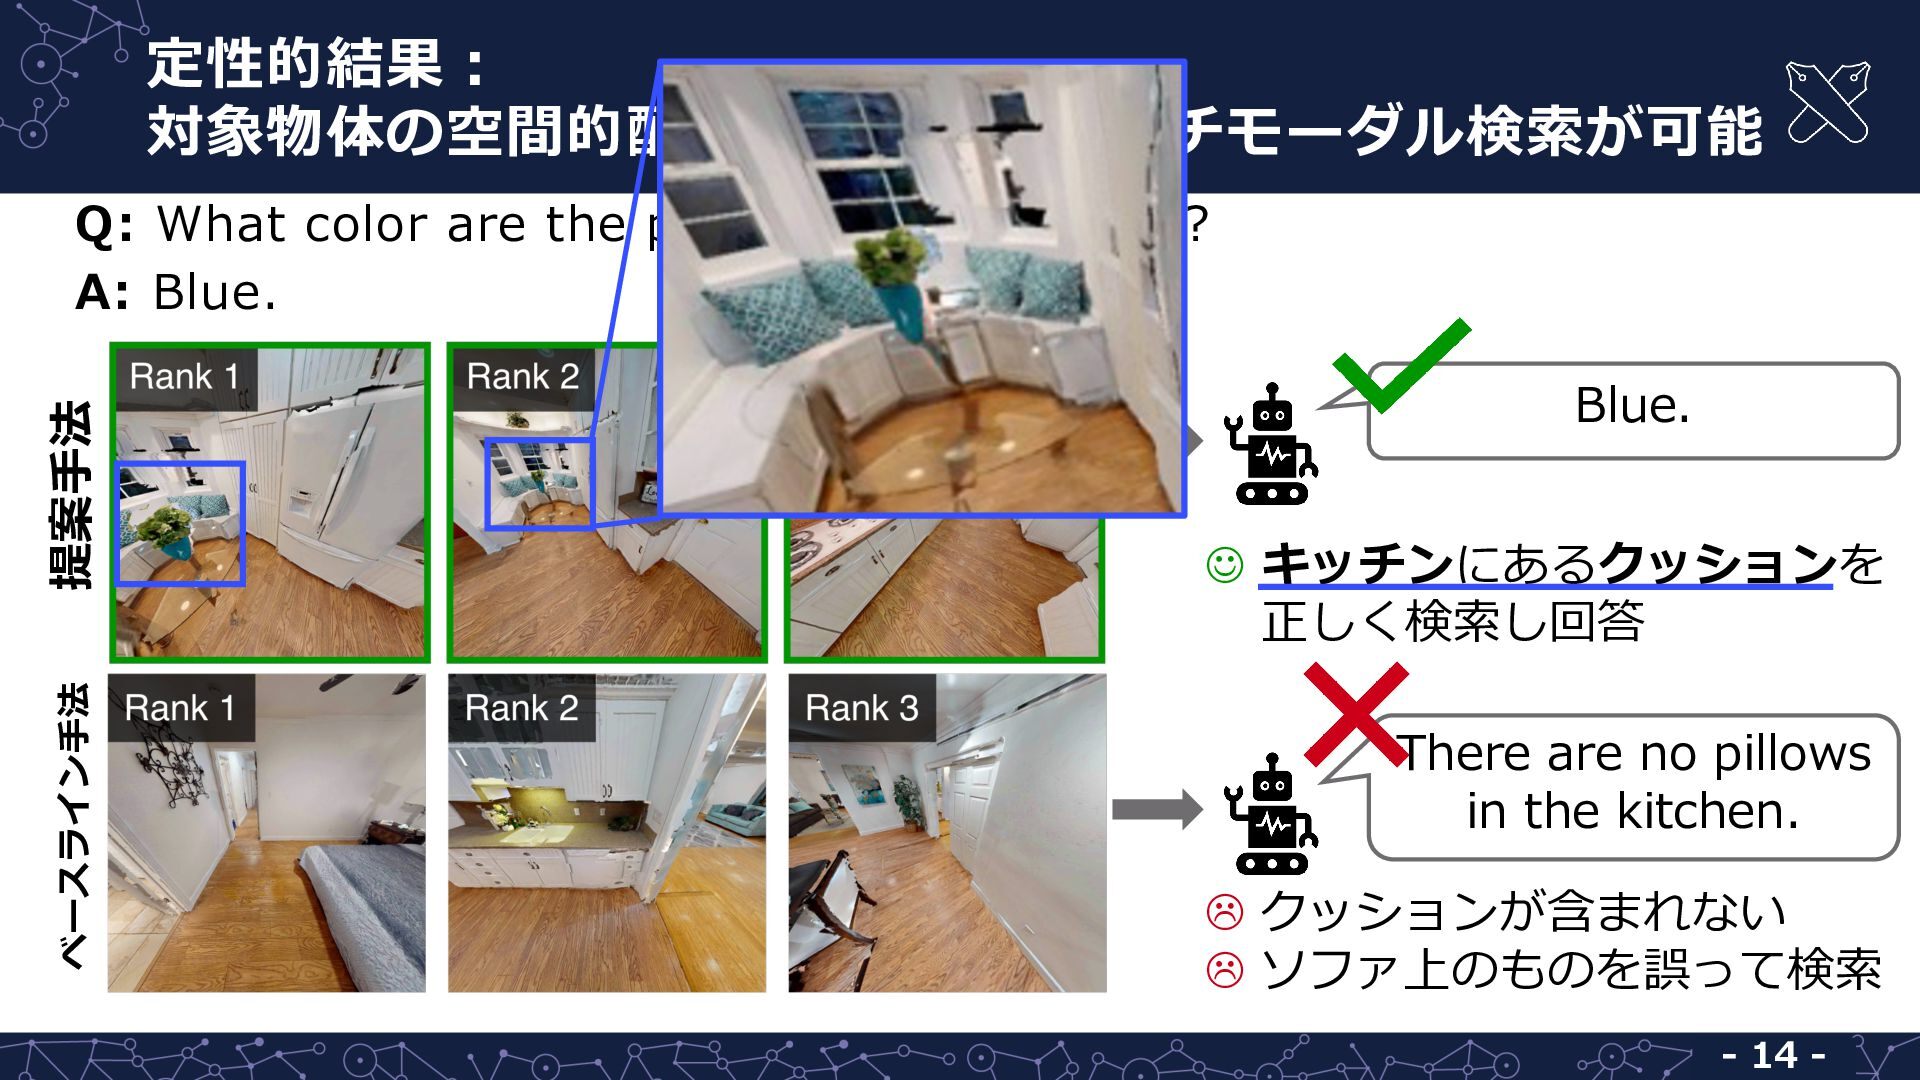
定性的結果︓ 対象物体の空間的配置を考慮したマルチモーダル検索が可能 ベースライン⼿法 提案⼿法 Q: What color are the pillows
in the kitchen? A: Blue. Blue. J キッチンにあるクッションを J 正しく検索し回答 There are no pillows in the kitchen. L クッションが含まれない L ソファ上のものを誤って検索 - 14 -
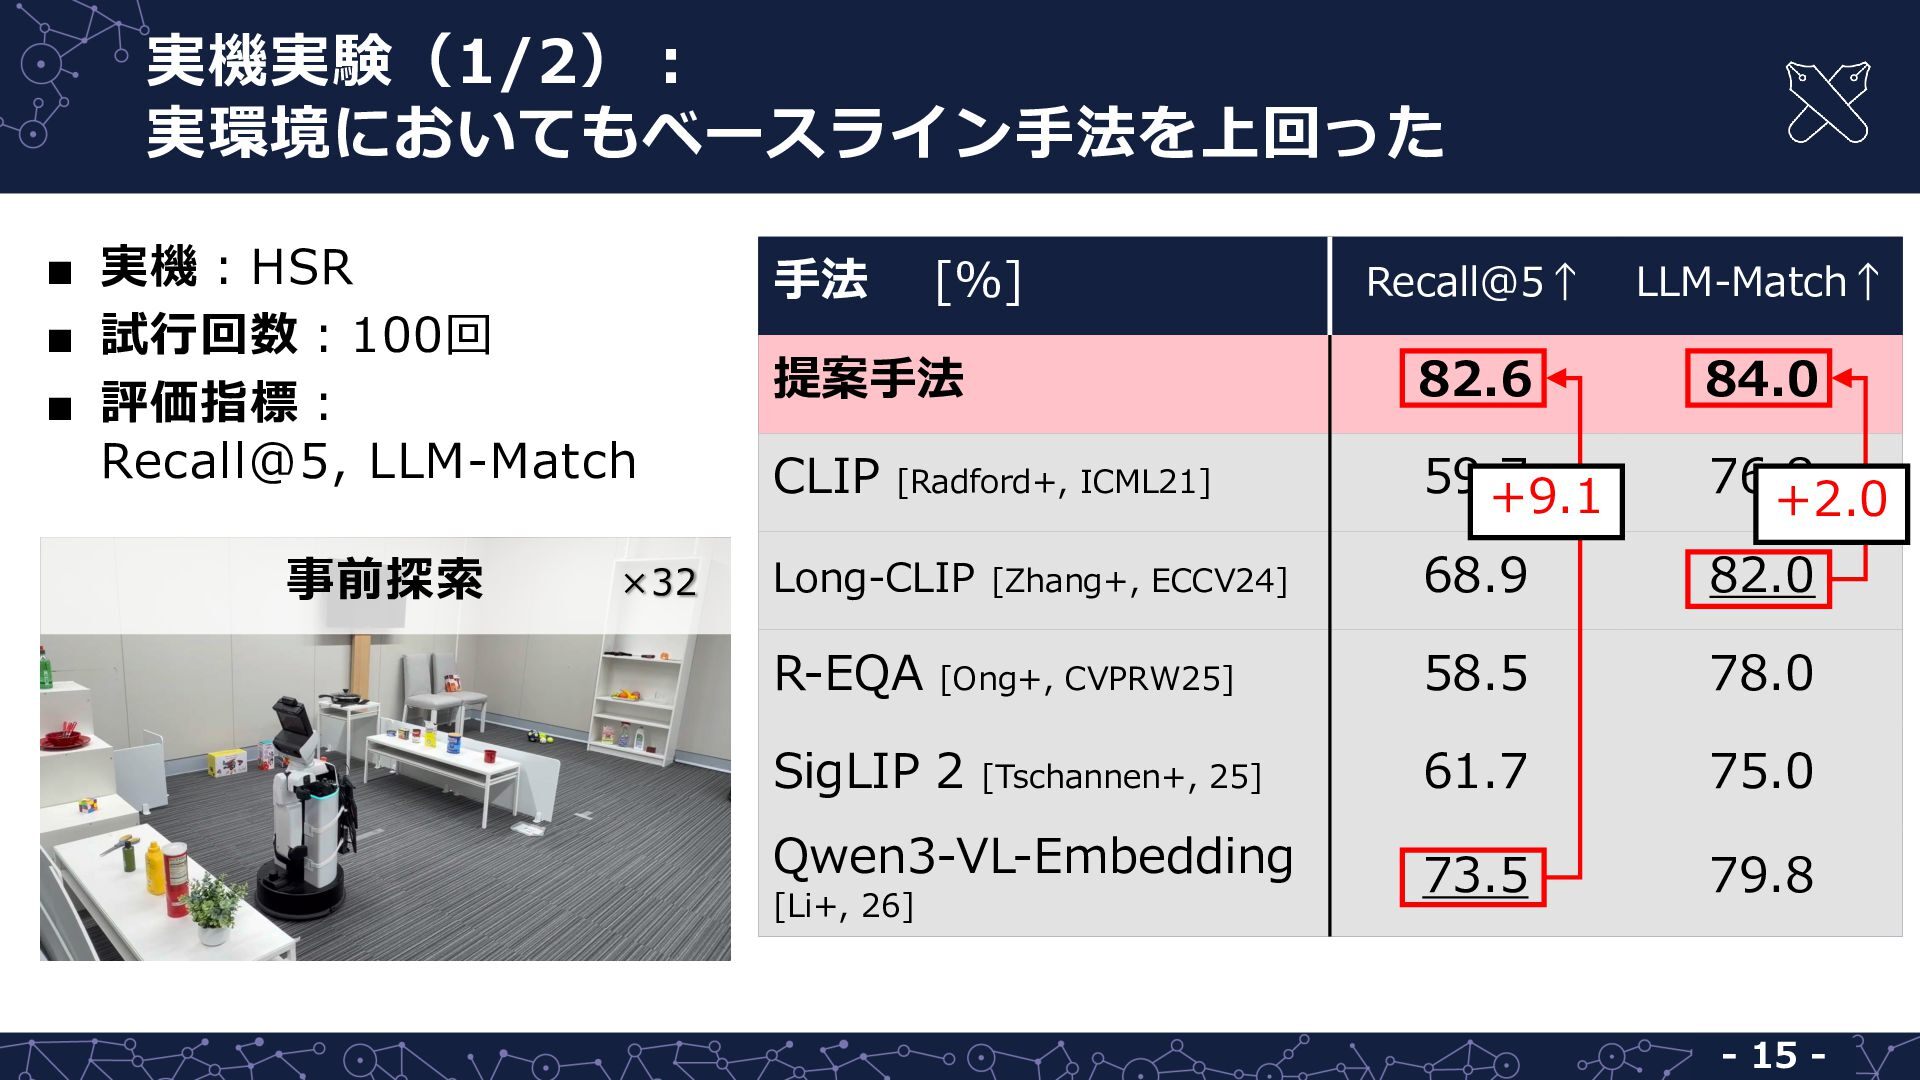
実機実験(1/2)︓ 実環境においてもベースライン⼿法を上回った ▪ 実機︓HSR ▪ 試⾏回数︓100回 ▪ 評価指標︓ Recall@5, LLM-Match
事前探索 ×32 ⼿法 [%] Recall@5↑ LLM-Match↑ 提案⼿法 82.6 84.0 CLIP [Radford+, ICML21] 59.7 +9.1 76.8 +2.0 Long-CLIP [Zhang+, ECCV24] 68.9 82.0 R-EQA [Ong+, CVPRW25] 58.5 78.0 SigLIP 2 [Tschannen+, 25] 61.7 75.0 Qwen3-VL-Embedding 73.5 79.8 [Li+, 26] - 15 -
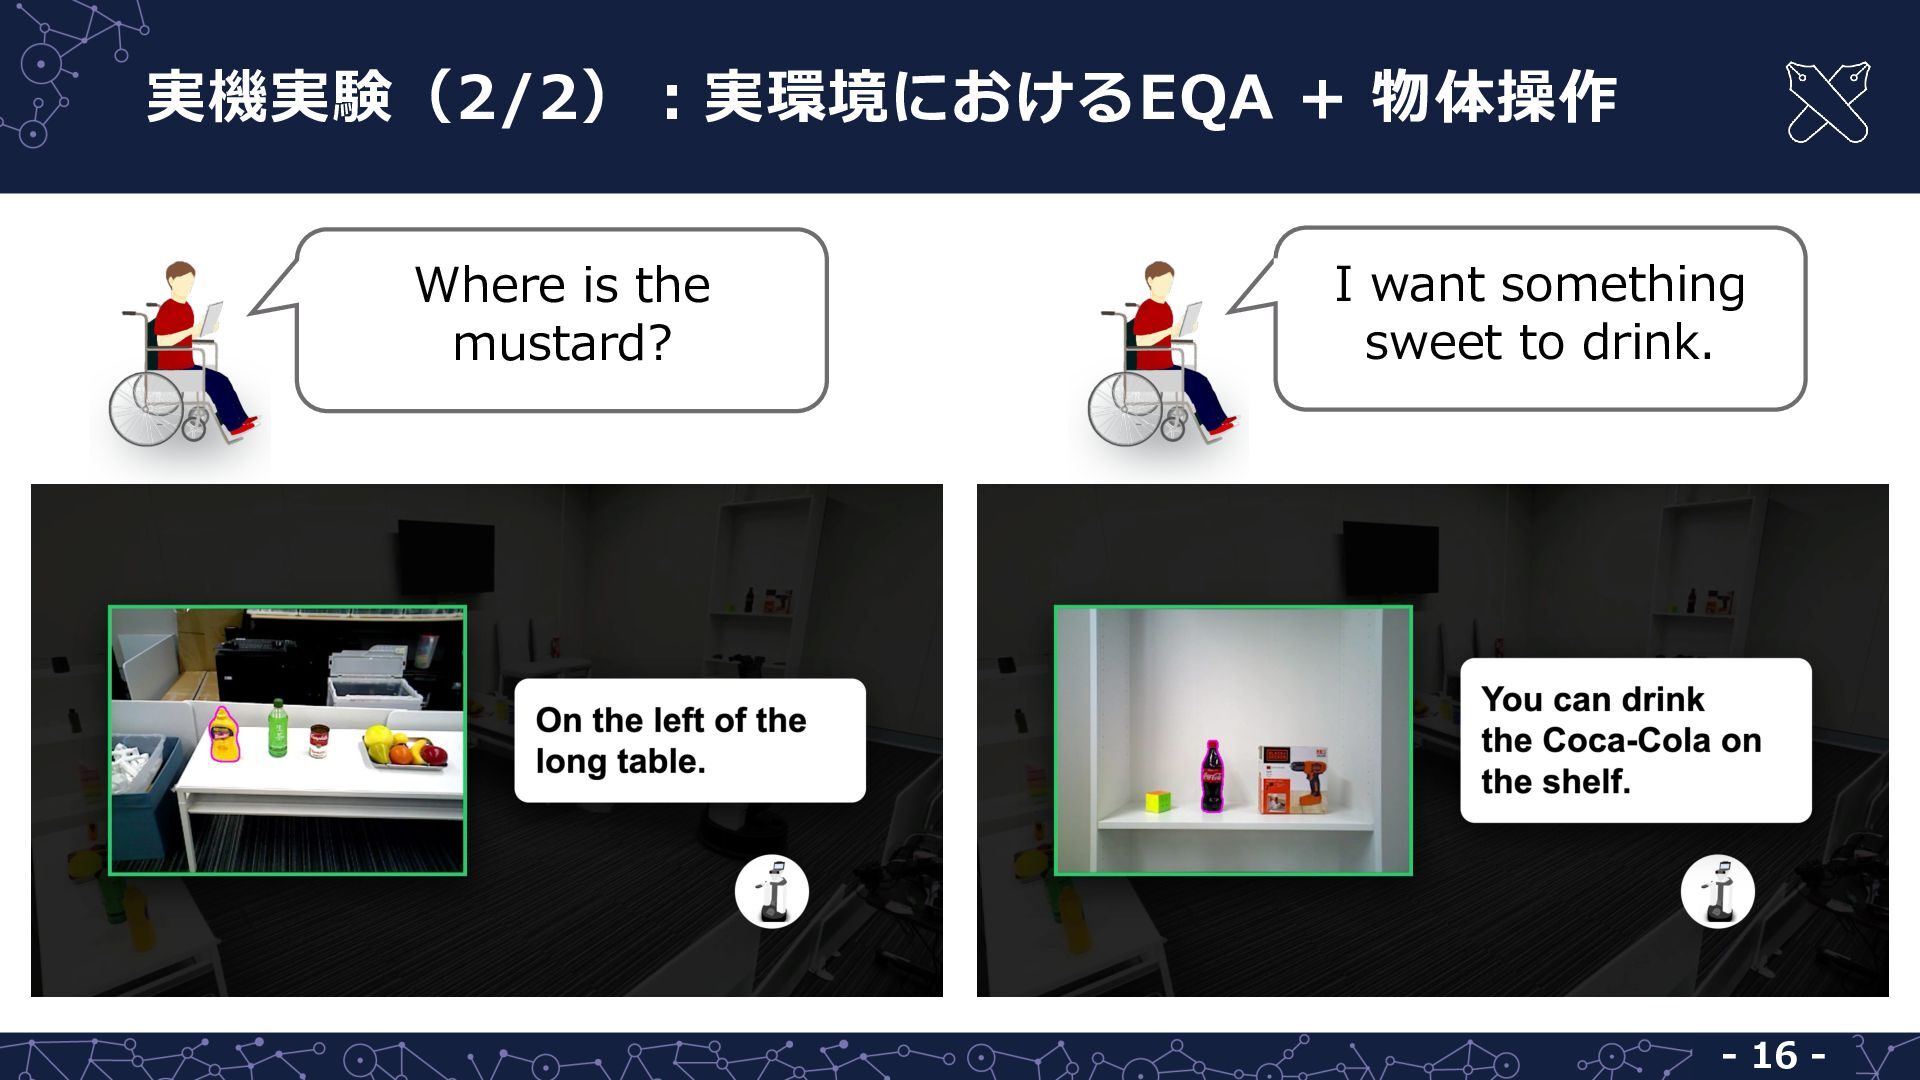
実機実験(2/2)︓実環境におけるEQA + 物体操作 Where is the mustard? I want something
sweet to drink. - 16 -
まとめ 背景 ▪ 既存EQA⼿法は質問毎に環境を ゼロから探索するため⾮効率 新規性 ▪ 実世界のマルチモーダルRAGに 基づくEQA ▪
多階層スコアリングに基づく マルチモーダル検索 結果 ▪ A-EQA・実機実験で検索・回答性能 ともにベースライン⼿法を上回った - 17 -
Appendix - 18 -
提案⼿法のモデル構造 - 19 -
評価指標の定義 ▪ Recall@K ▪ LLM-Match ▪ LLM によって評価された回答の正しさ - 20
-
定量的結果︓A-EQAベンチマーク 提案⼿法 - 21 -
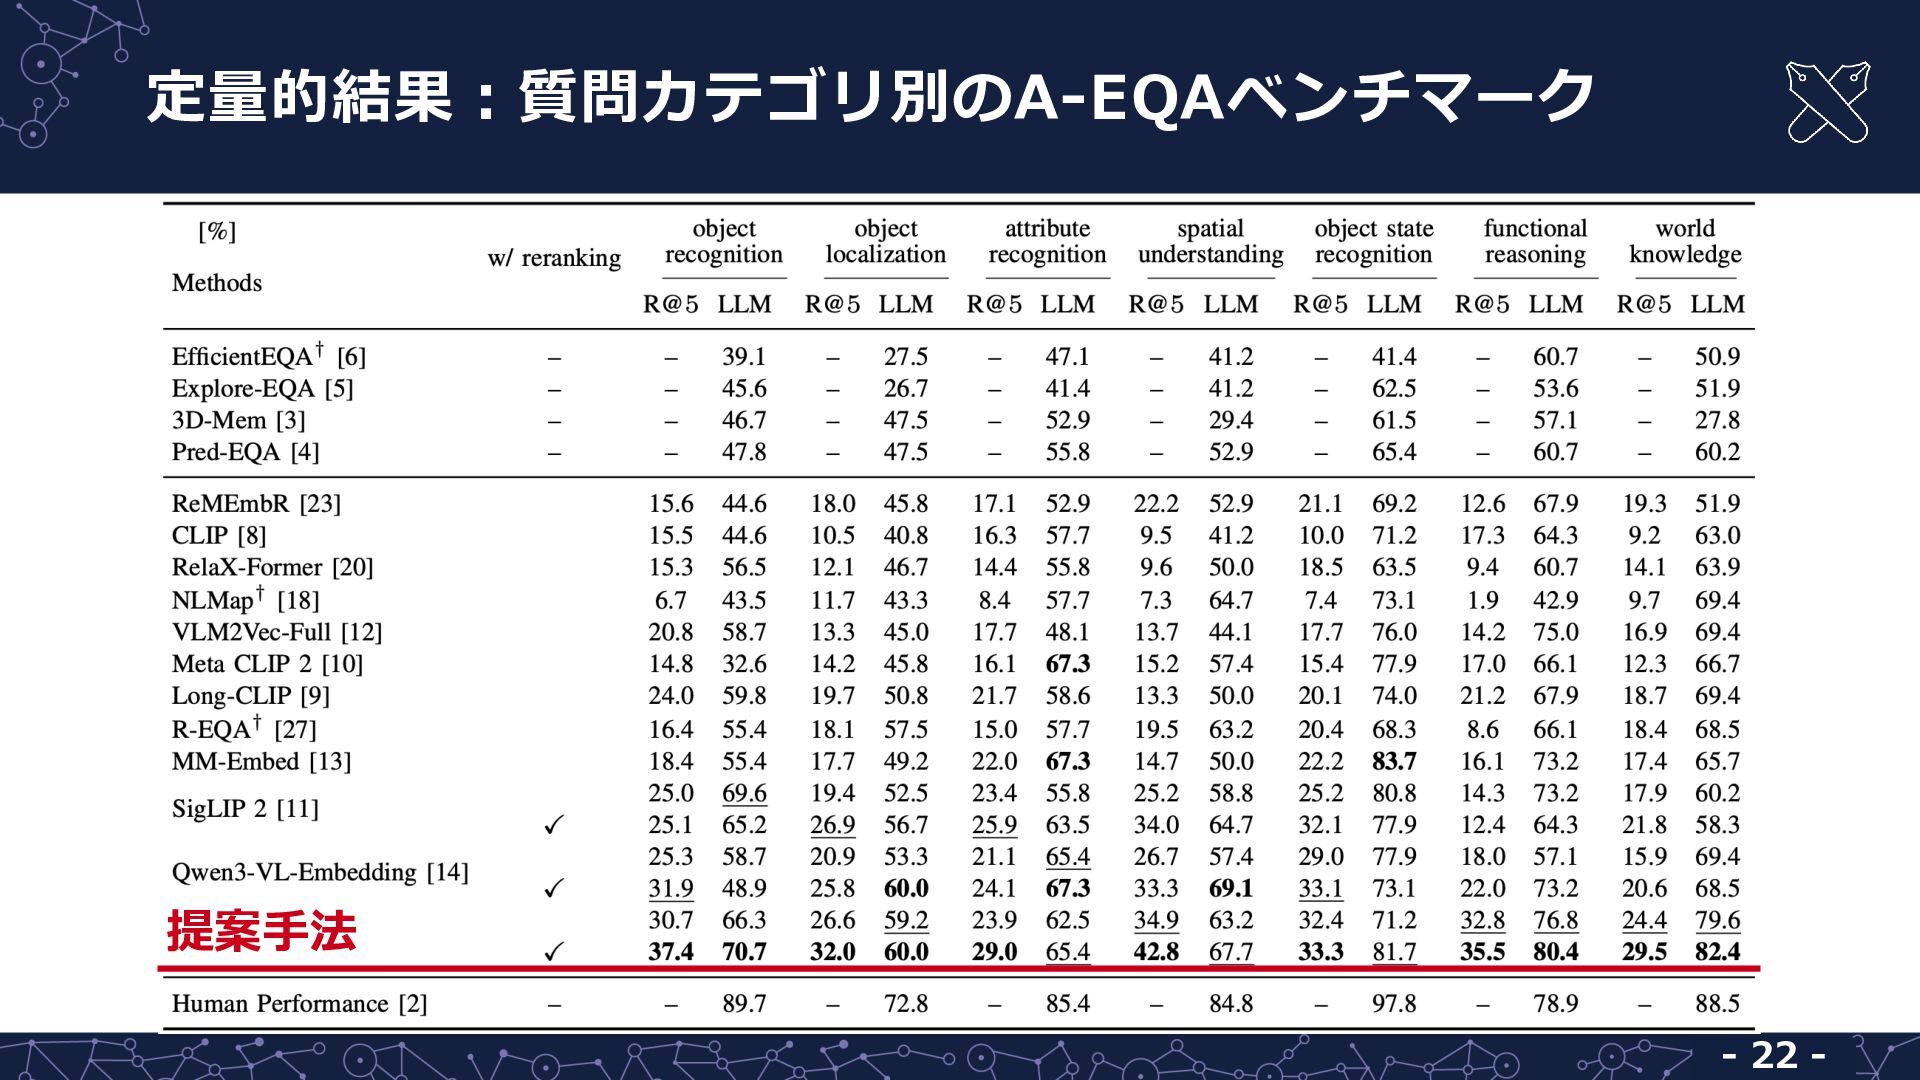
定量的結果︓質問カテゴリ別のA-EQAベンチマーク 提案⼿法 - 22 -
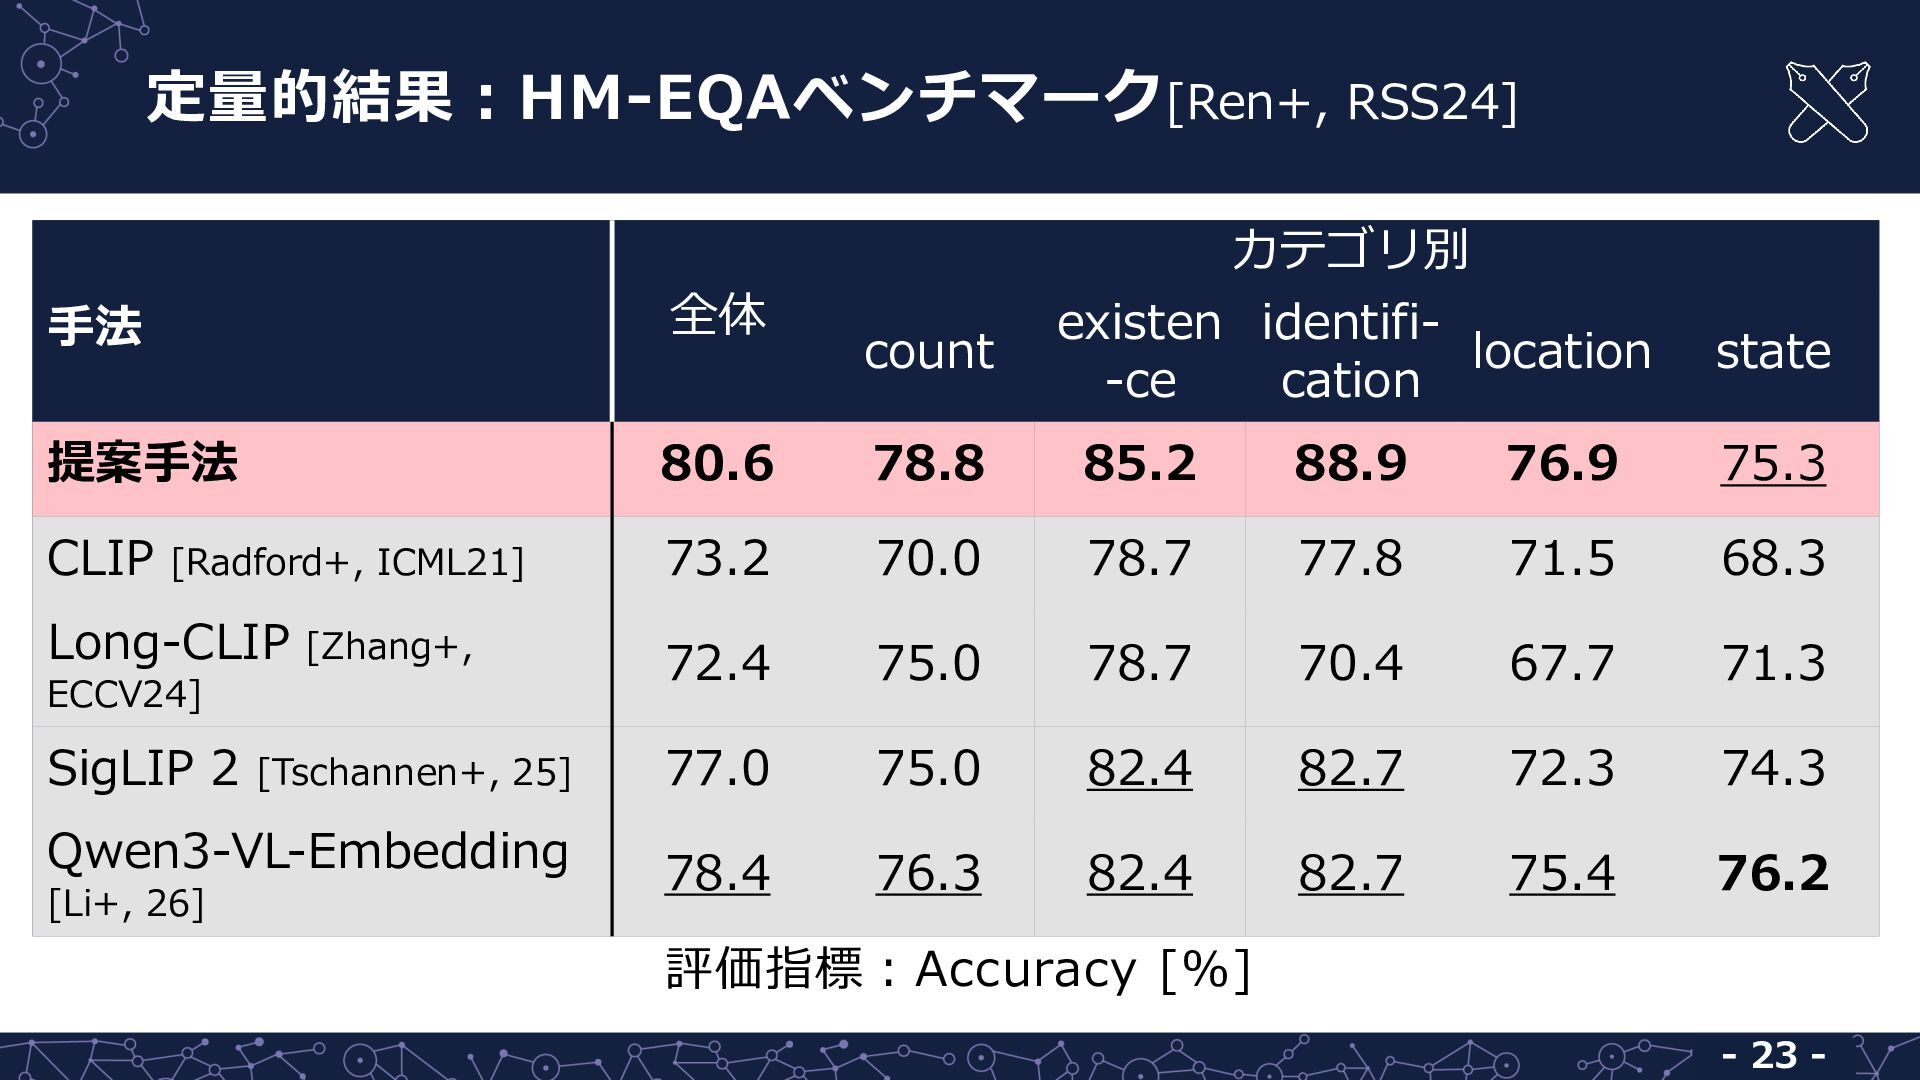
定量的結果︓HM-EQAベンチマーク [Ren+, RSS24] カテゴリ別 existen identifilocation -ce cation ⼿法 全体
提案⼿法 80.6 78.8 85.2 88.9 76.9 75.3 CLIP [Radford+, ICML21] 73.2 70.0 78.7 77.8 71.5 68.3 Long-CLIP [Zhang+, 72.4 75.0 78.7 70.4 67.7 71.3 SigLIP 2 [Tschannen+, 25] 77.0 75.0 82.4 82.7 72.3 74.3 Qwen3-VL-Embedding 78.4 76.3 82.4 82.7 75.4 76.2 ECCV24] [Li+, 26] count state 評価指標︓Accuracy [%] - 23 -
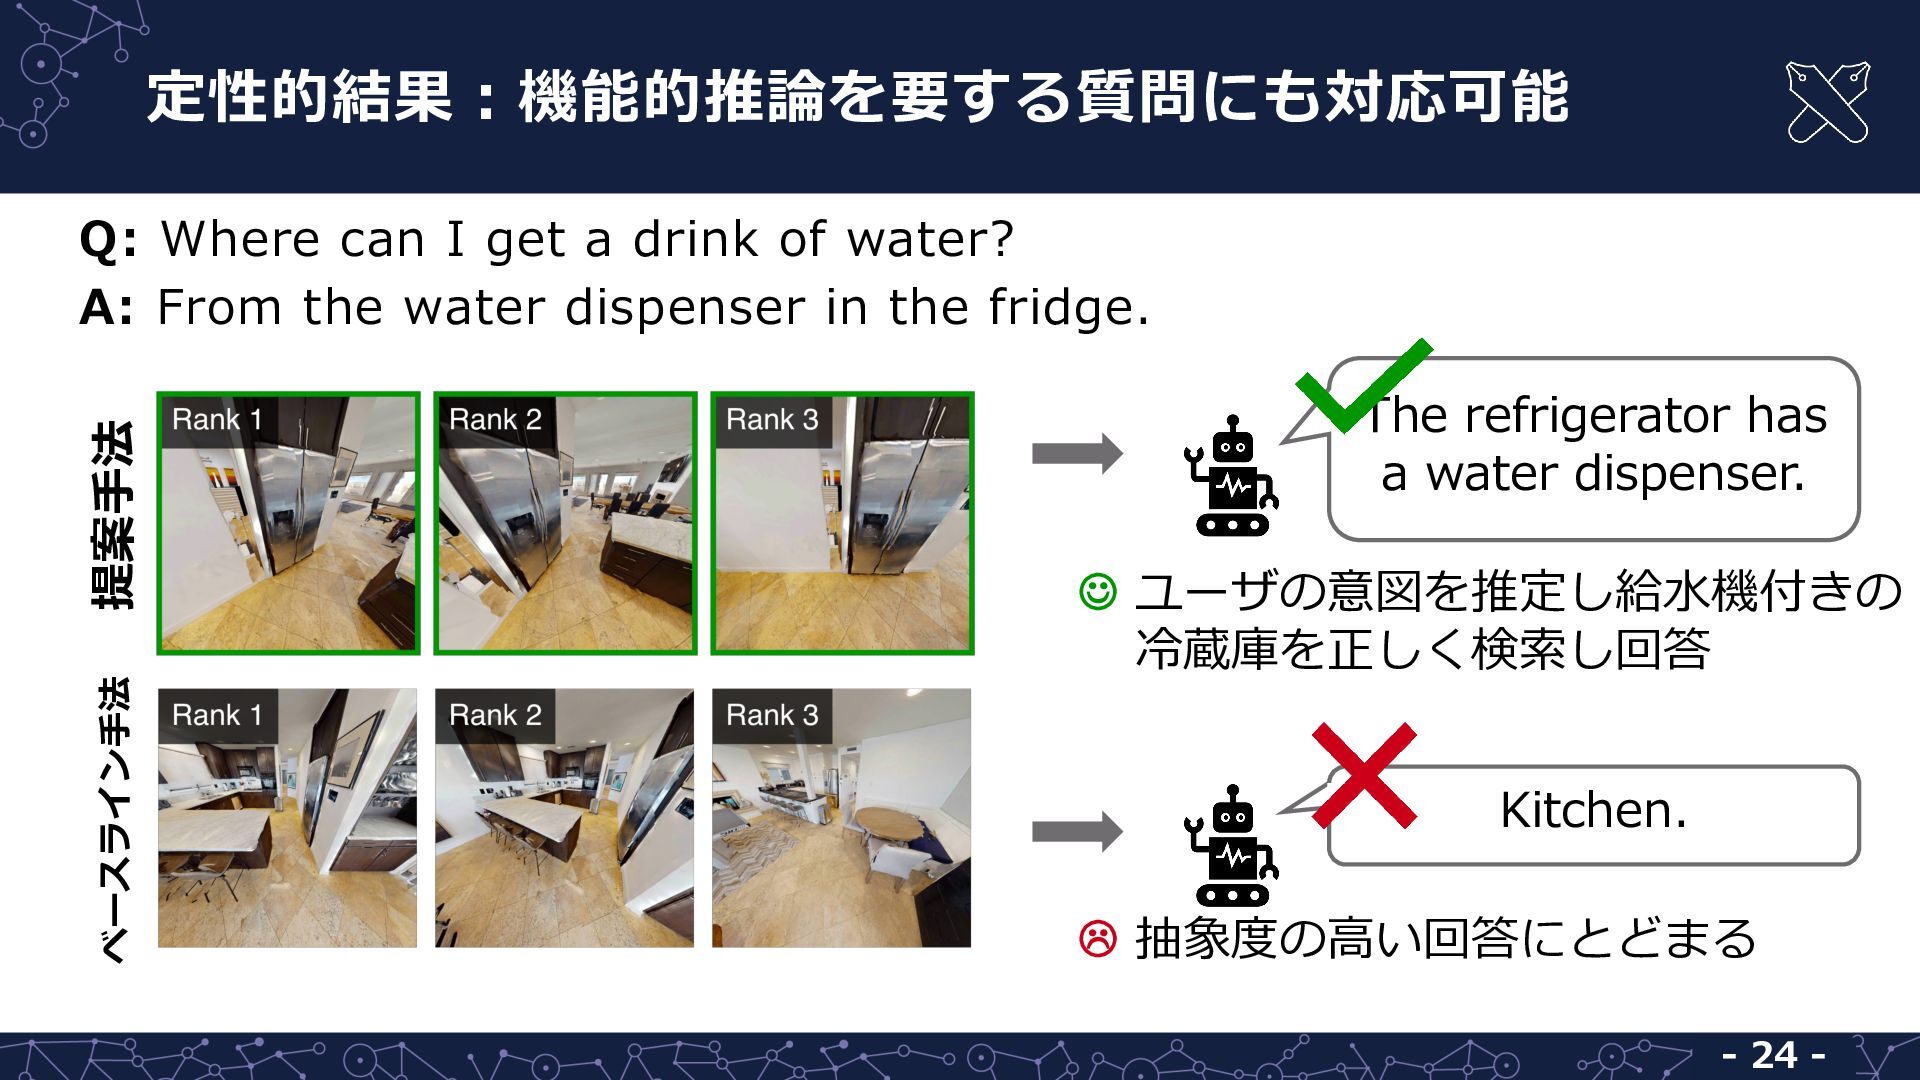
定性的結果︓機能的推論を要する質問にも対応可能 ベースライン⼿法 提案⼿法 Q: Where can I get a drink
of water? A: From the water dispenser in the fridge. The refrigerator has a water dispenser. J ユーザの意図を推定し給⽔機付きの J 冷蔵庫を正しく検索し回答 Kitchen. L 抽象度の⾼い回答にとどまる - 24 -
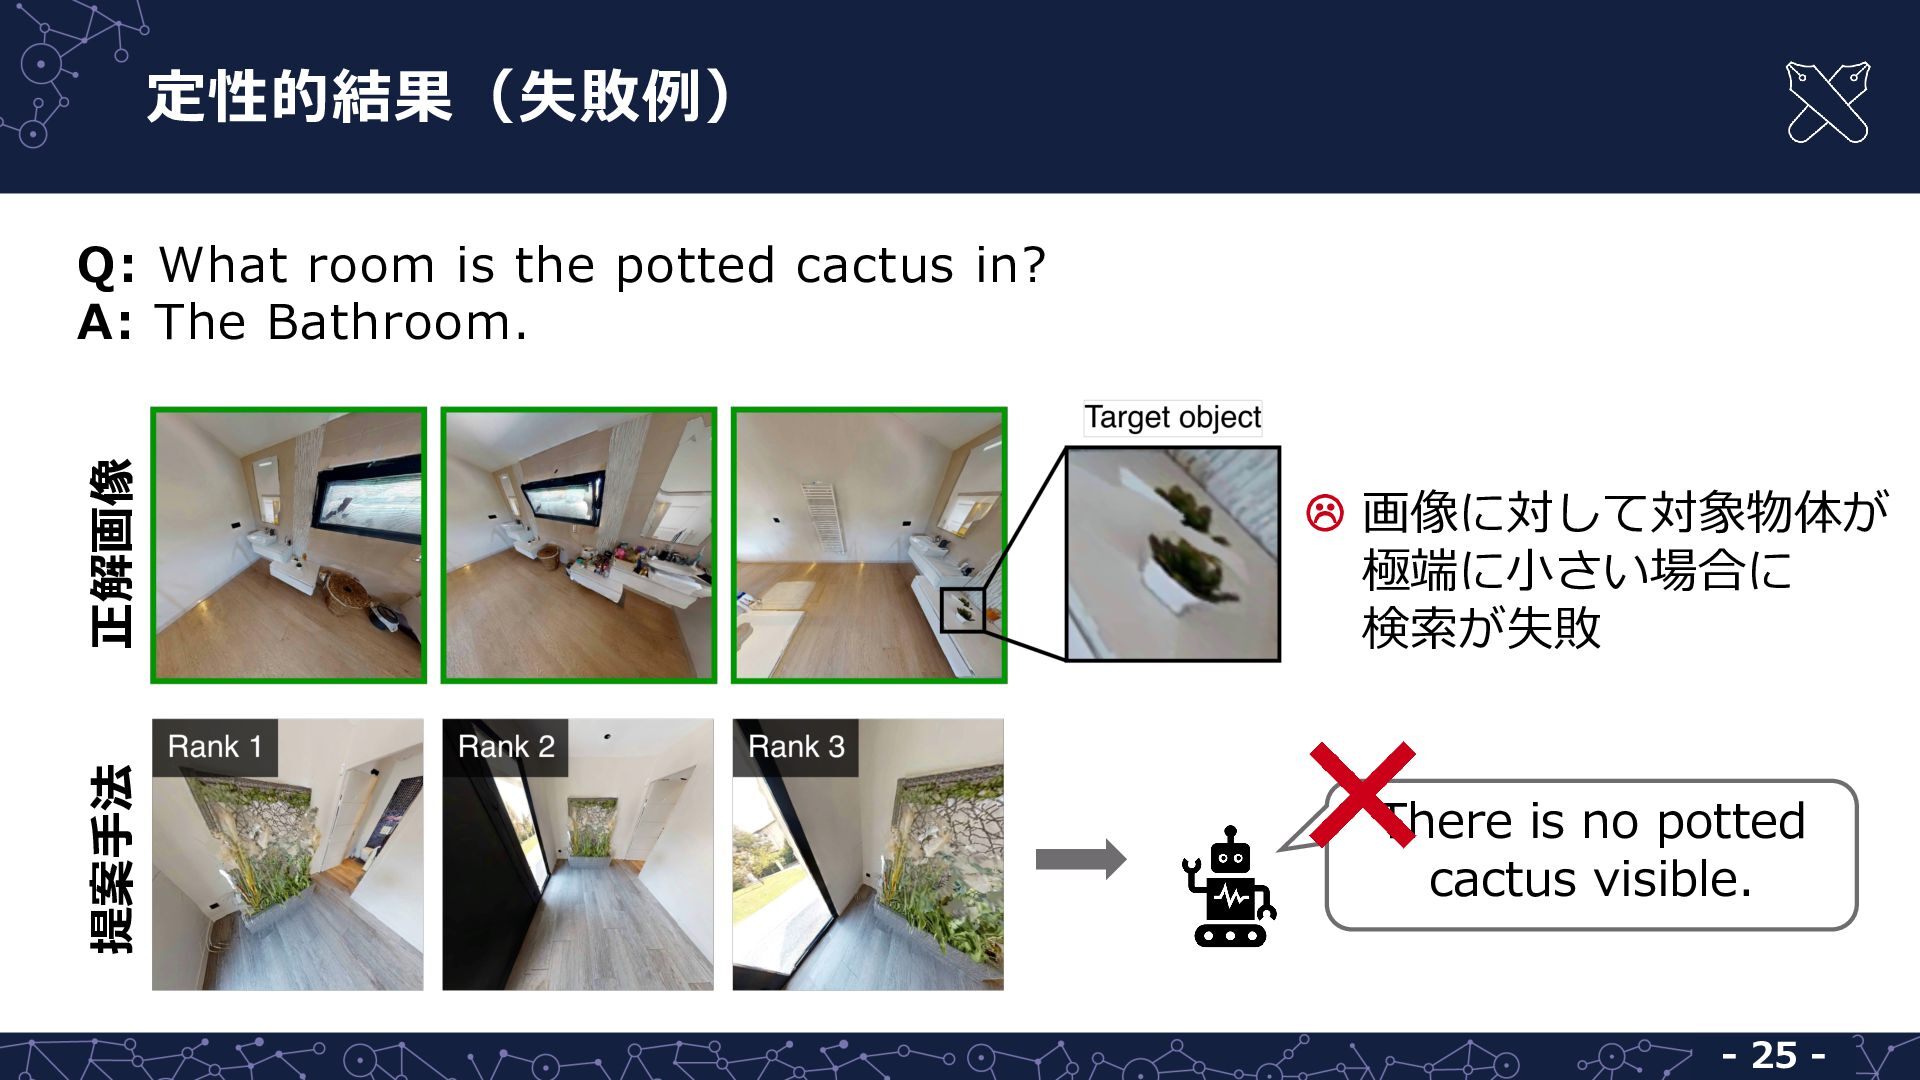
定性的結果(失敗例) 正解画像 L 画像に対して対象物体が L 極端に⼩さい場合に L 検索が失敗 提案⼿法 Q:
What room is the potted cactus in? A: The Bathroom. There is no potted cactus visible. - 25 -
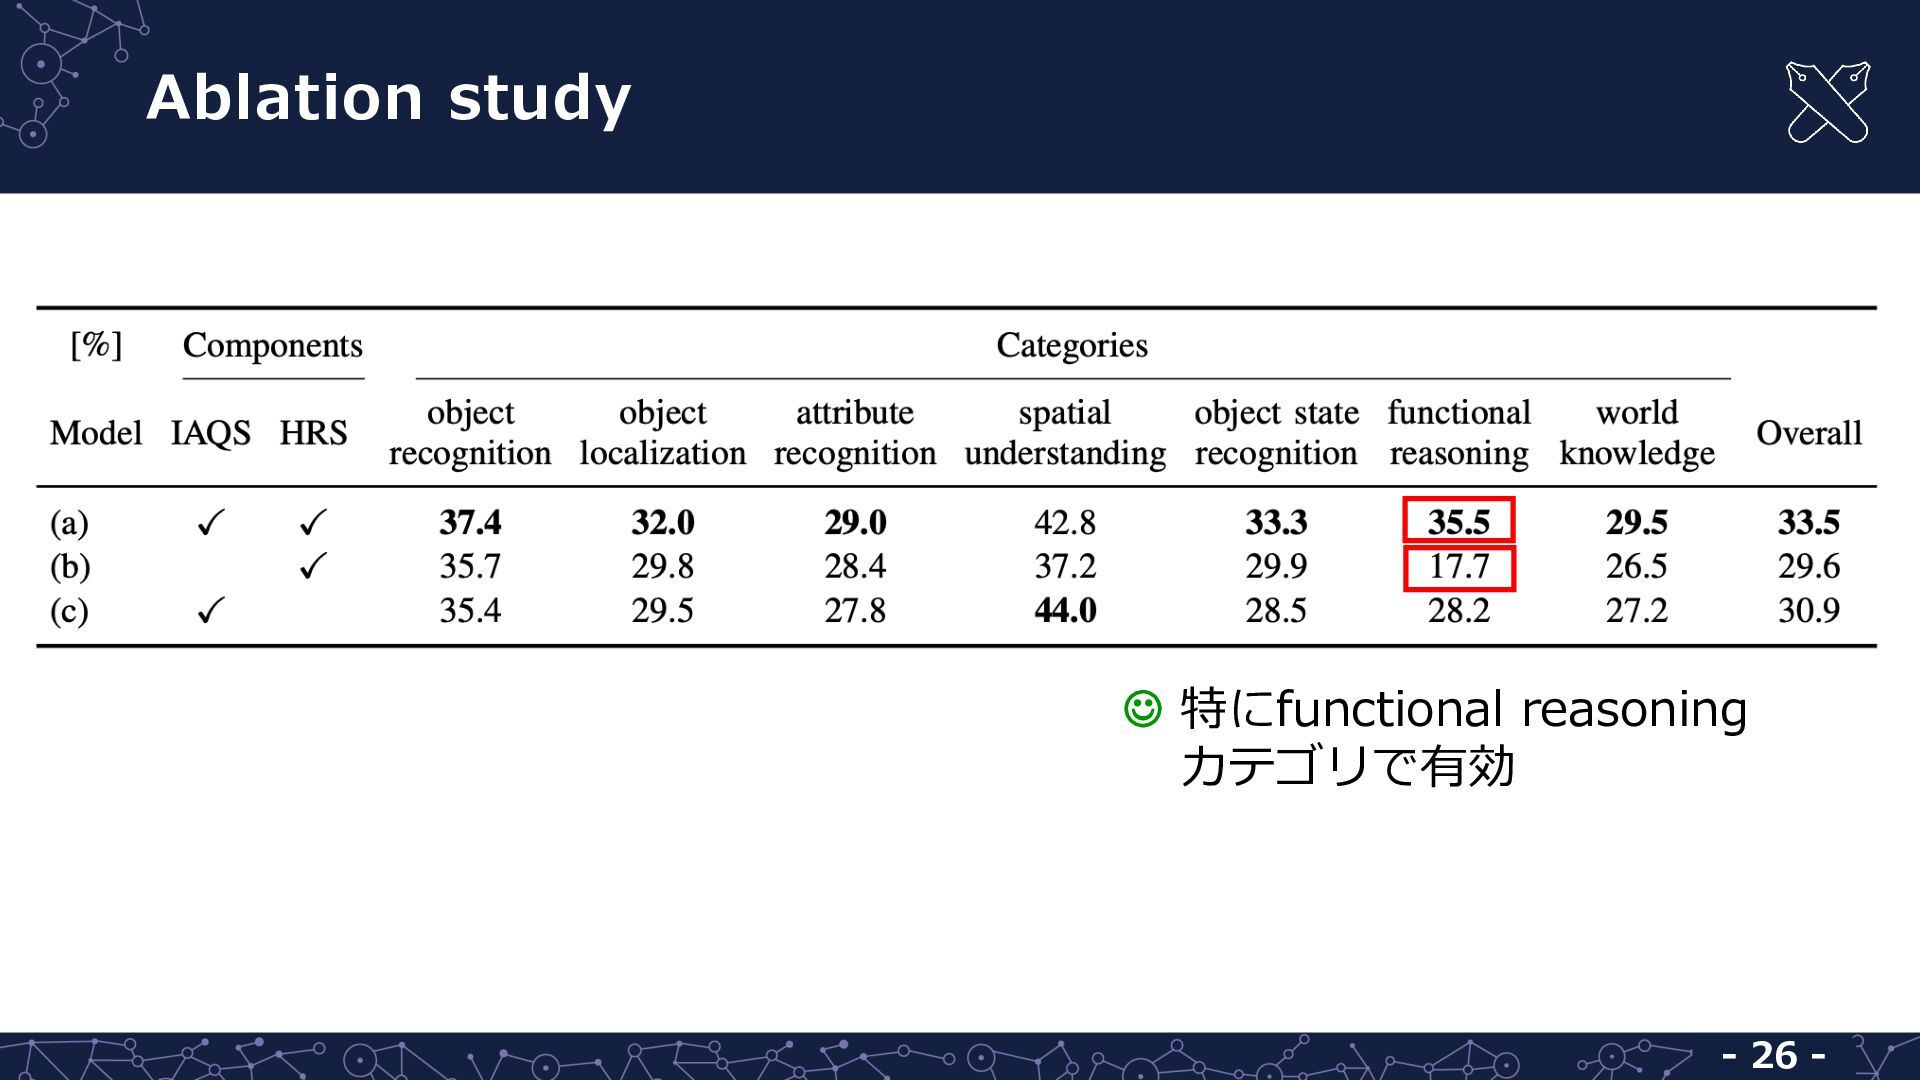
Ablation study J 特にfunctional reasoning J カテゴリで有効 - 26 -
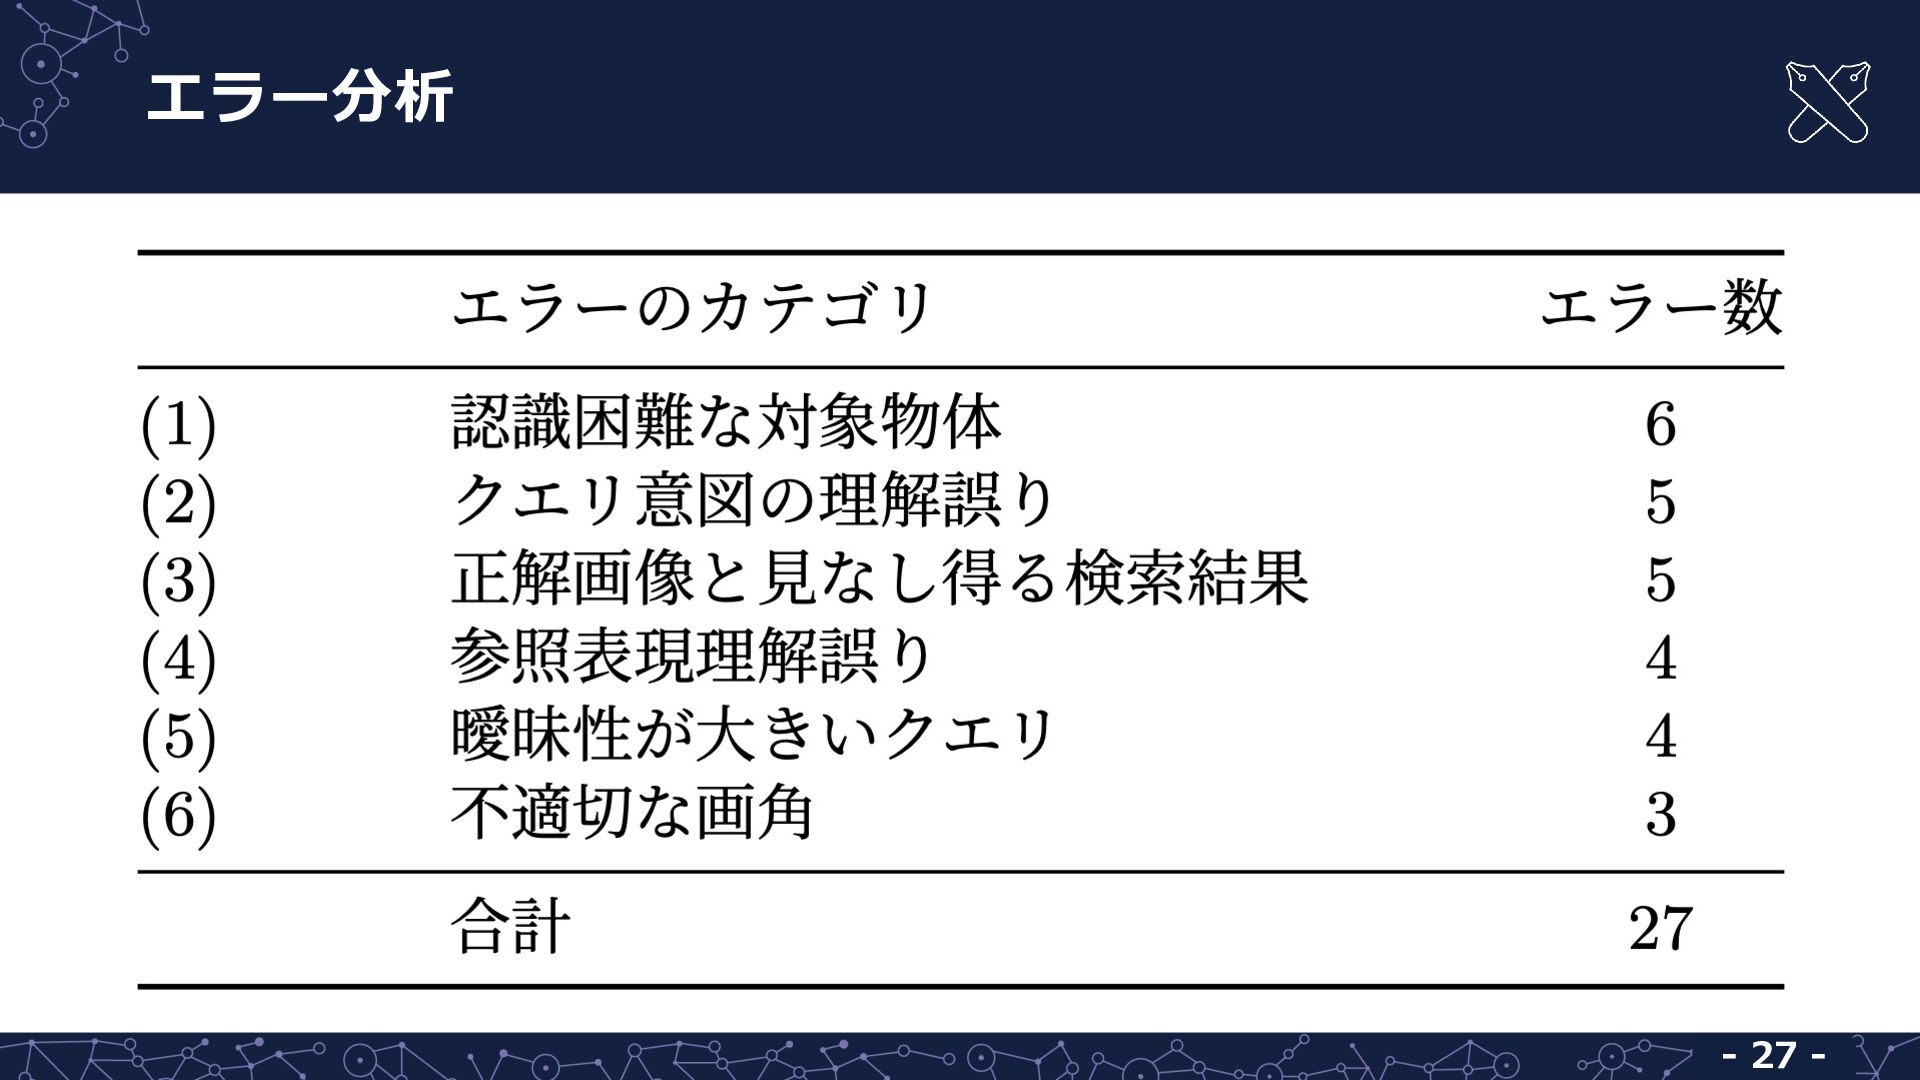
エラー分析 - 27 -


 keio_smilab
 chmikata
 kenichiodo
 subroh0508
 kinopeee
 ryuseiiida
 kaeton
 akaboshinit
 clairegiordano
 yamahiro
 zozotech
 sakusaku3939
 ryo_kawamata
 katarinadahlin
 shlominoach
 ivargrimstad
 davidcarrasco
 cassininazir
 geshan
 marktimemedia
 inesmontani
 varn
 baasie
 sergeychernyshev
 thoeni