Share
Embed
Compute in 10 minutes in the cloud, rather than 1 week on your server
Ever had a batch job taking days to complete? By distributing an algorithm over 1,000 cores, a 1 week computation can be completed in 10 minutes only. Moreover, storing/processing the results can be complex and time consuming. This demo shows how this can be seamless, real-time and serverless.
Laurent Picard
October 20, 2017
Transcript
20 slides
-
Compute in 10 minutes in the cloud, rather than 1
week on your server Laurent Picard @PicardParis PyData Warsaw October 20, 2017 -
Laurent Picard - @PicardParis - Developer Advocate ‒ Google Cloud
Platform - Co-founder & CTO of Bookeen - Co-creator of 1st European ebook reader Who are you? - Developers? - Already working in the cloud? - Already using Hadoop or Spark? BigQuery? Who are we? -
01 Time consuming computation 02 Running an algorithm in parallel
03 Streaming the results live 04 Analyzing the results in real-time Take aways -
My computer has several CPUs 1 2 3 4 5
6 CPU 1 CPU 2 CPU 3 CPU 4 CPU 5 CPU 6 [ ... 1 hour (= 6 x 10 min) computation ... ] [10 min] [ ... 1 hour computation ... ] -
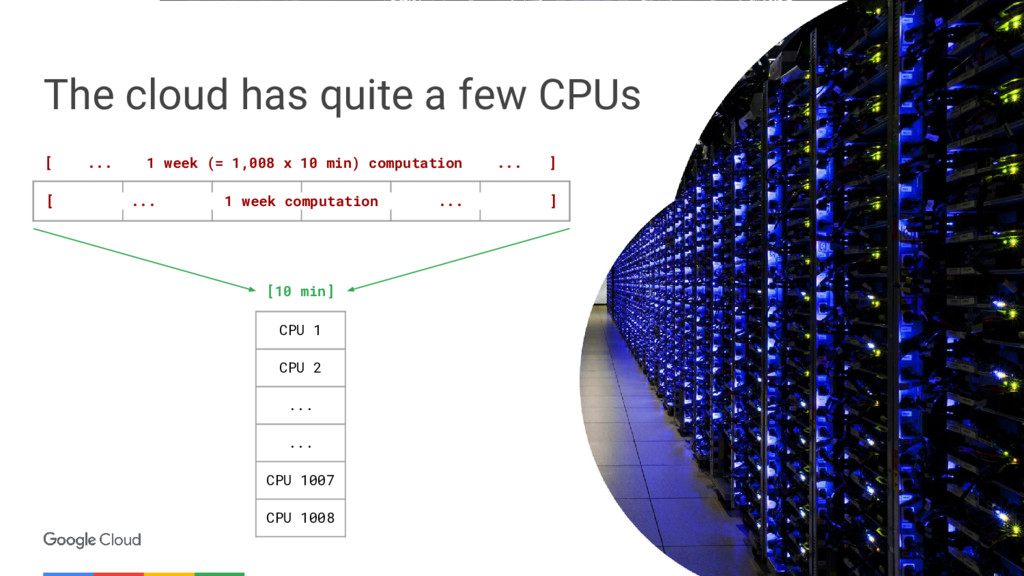
The cloud has quite a few CPUs 1 2 ...
... 1007 1008 CPU 1 CPU 2 ... ... CPU 1007 CPU 1008 [ ... 1 week (= 1,008 x 10 min) computation ... ] [10 min] [ ... 1 week computation ... ] -
1 solution: Apache Spark Spark runs locally or on a
cluster: 1 master node + X worker nodes #python #scala #java #R #fast #flexible #realtime -
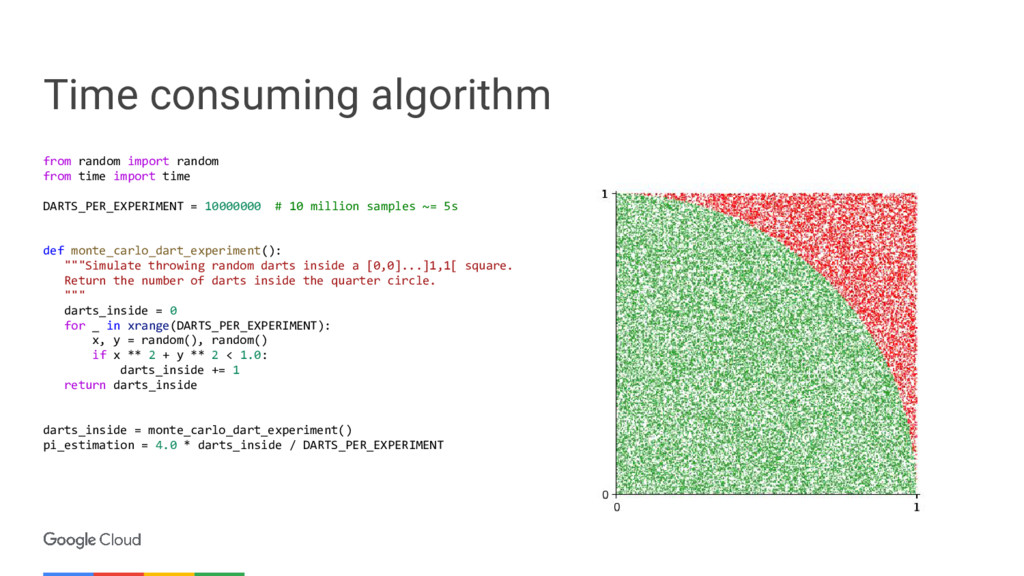
Time consuming algorithm from random import random from time import
time DARTS_PER_EXPERIMENT = 10000000 # 10 million samples ~= 5s def monte_carlo_dart_experiment(): """Simulate throwing random darts inside a [0,0]...]1,1[ square. Return the number of darts inside the quarter circle. """ darts_inside = 0 for _ in xrange(DARTS_PER_EXPERIMENT): x, y = random(), random() if x ** 2 + y ** 2 < 1.0: darts_inside += 1 return darts_inside darts_inside = monte_carlo_dart_experiment() pi_estimation = 4.0 * darts_inside / DARTS_PER_EXPERIMENT -
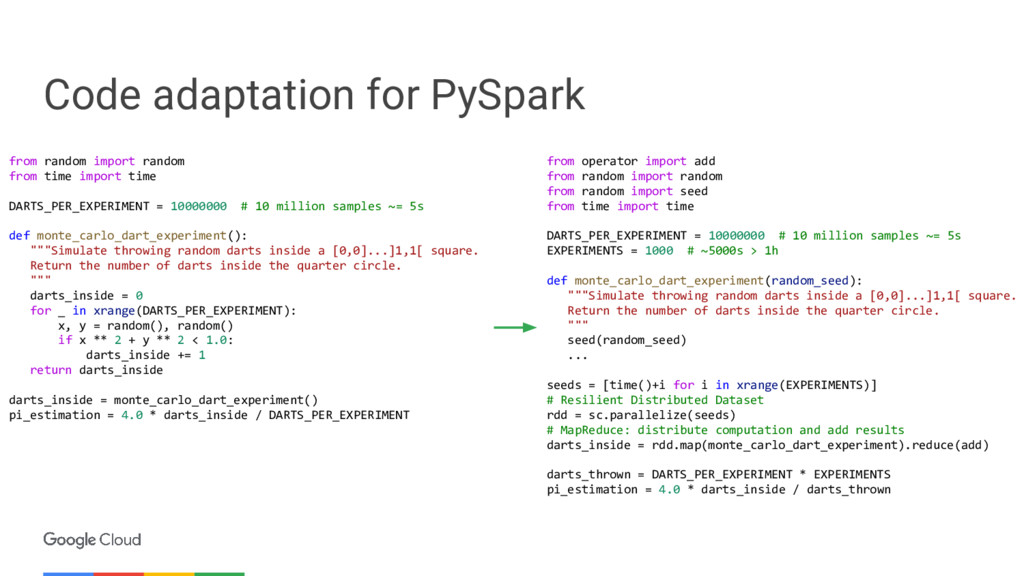
Code adaptation for PySpark from operator import add from random
import random from random import seed from time import time DARTS_PER_EXPERIMENT = 10000000 # 10 million samples ~= 5s EXPERIMENTS = 1000 # ~5000s > 1h def monte_carlo_dart_experiment(random_seed): """Simulate throwing random darts inside a [0,0]...]1,1[ square. Return the number of darts inside the quarter circle. """ seed(random_seed) ... seeds = [time()+i for i in xrange(EXPERIMENTS)] # Resilient Distributed Dataset rdd = sc.parallelize(seeds) # MapReduce: distribute computation and add results darts_inside = rdd.map(monte_carlo_dart_experiment).reduce(add) darts_thrown = DARTS_PER_EXPERIMENT * EXPERIMENTS pi_estimation = 4.0 * darts_inside / darts_thrown from random import random from time import time DARTS_PER_EXPERIMENT = 10000000 # 10 million samples ~= 5s def monte_carlo_dart_experiment(): """Simulate throwing random darts inside a [0,0]...]1,1[ square. Return the number of darts inside the quarter circle. """ darts_inside = 0 for _ in xrange(DARTS_PER_EXPERIMENT): x, y = random(), random() if x ** 2 + y ** 2 < 1.0: darts_inside += 1 return darts_inside darts_inside = monte_carlo_dart_experiment() pi_estimation = 4.0 * darts_inside / DARTS_PER_EXPERIMENT -
BigQuery table to store results from google.cloud import bigquery BQ_DATASET_LOCATION
= 'EU' BQ_DATASET = 'monte_carlo' BQ_TABLE = 'experiments' def get_bq_dataset(bq_client, create_if_necessary=False): dataset = bq_client.dataset(BQ_DATASET) if not dataset.exists() and create_if_necessary: dataset = bq_client.dataset(BQ_DATASET) dataset.location = BQ_DATASET_LOCATION dataset.create() return dataset if dataset.exists() else None def get_bq_table(create_if_necessary=False): bq_client = bigquery.Client() dataset = get_bq_dataset(bq_client, create_if_necessary) if dataset is None: return None table = dataset.table(BQ_TABLE) if not table.exists() and create_if_necessary: table.schema = ( bigquery.SchemaField("timestamp", "TIMESTAMP"), bigquery.SchemaField("duration", "INTEGER"), bigquery.SchemaField("darts_inside", "INTEGER"), bigquery.SchemaField("darts_thrown", "INTEGER"), ) table.create() if table.exists(): table.reload() return table return None bq_table = get_bq_table(create_if_necessary=True) -
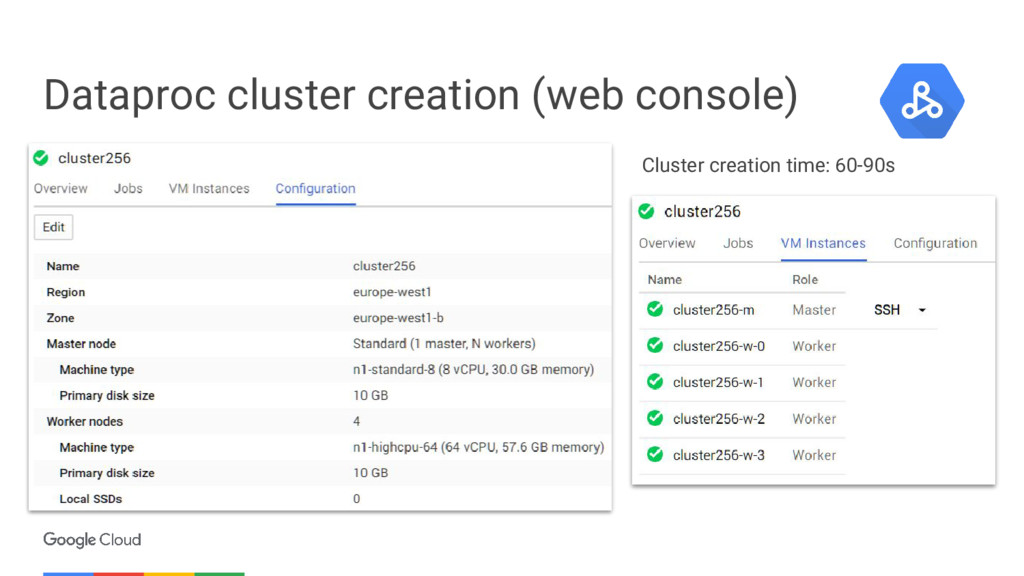
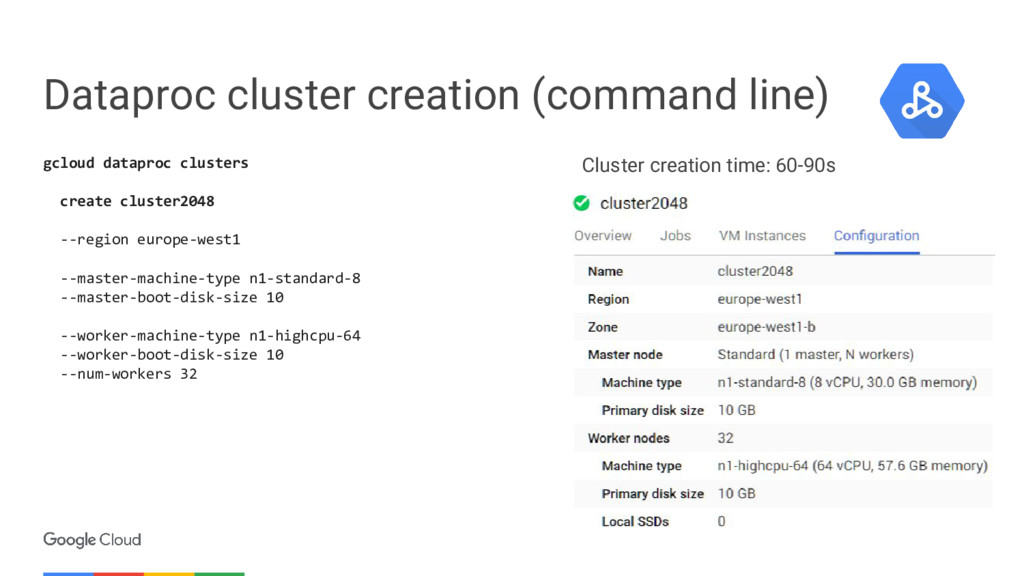
Dataproc cluster creation (command line) Cluster creation time: 60-90s gcloud
dataproc clusters create cluster2048 --region europe-west1 --master-machine-type n1-standard-8 --master-boot-disk-size 10 --worker-machine-type n1-highcpu-64 --worker-boot-disk-size 10 --num-workers 32 -
Algorithm adaptation to stream results DARTS_PER_EXPERIMENT = 10000000 # 10
million samples ~= 5s EXPERIMENTS = 120000 # ~7 days WORKER_CORES = 2048 def monte_carlo_dart_experiment(random_seed): """Simulate throwing random darts inside a [0,0]...]1,1[ square. Return the experiment metrics. """ timestamp = time() ... duration = int((time() - timestamp)*1000) return [timestamp, duration, darts_inside] darts_inside = 0 for i in range(0, EXPERIMENTS, WORKER_CORES): experiments = min(WORKER_CORES, EXPERIMENTS-i) seeds = [time()+i+j for j in xrange(experiments)] rdd = sc.parallelize(seeds, experiments) rows = rdd.map(monte_carlo_dart_experiment).collect() for row in rows: darts_inside += row[2] stream_to_bigquery(rows) darts_thrown = DARTS_PER_EXPERIMENT * EXPERIMENTS pi_estimation = 4.0 * darts_inside / darts_thrown DARTS_PER_EXPERIMENT = 10000000 # 10 million samples ~= 5s EXPERIMENTS = 1000 # ~5000s > 1h def monte_carlo_dart_experiment(random_seed): """Simulate throwing random darts inside a [0,0]...]1,1[ square. Return the number of darts inside the quarter circle. """ ... return darts_inside seeds = [time()+i for i in xrange(EXPERIMENTS)] rdd = sc.parallelize(seeds) # MapReduce: distribute computation and add results darts_inside = rdd.map(monte_carlo_dart_experiment).reduce(add) darts_thrown = DARTS_PER_EXPERIMENT * EXPERIMENTS pi_estimation = 4.0 * darts_inside / darts_thrown -
PySpark job launch command line Cluster creation time: 60-90s gcloud
dataproc jobs submit pyspark --region europe-west1 --cluster cluster2048 my-job.py