Share
Embed
Data Processing and Aggregation options with MongoDB
The why, whats and whens of big data aggregation with MongoDB
rozza
April 09, 2013
Transcript
60 slides
-
• Ross Lawley - @RossC0 • 10gen Driver Engineer -
Python and Scala • 12 Years of web application development • Started out my career as a database manager Who am I? -
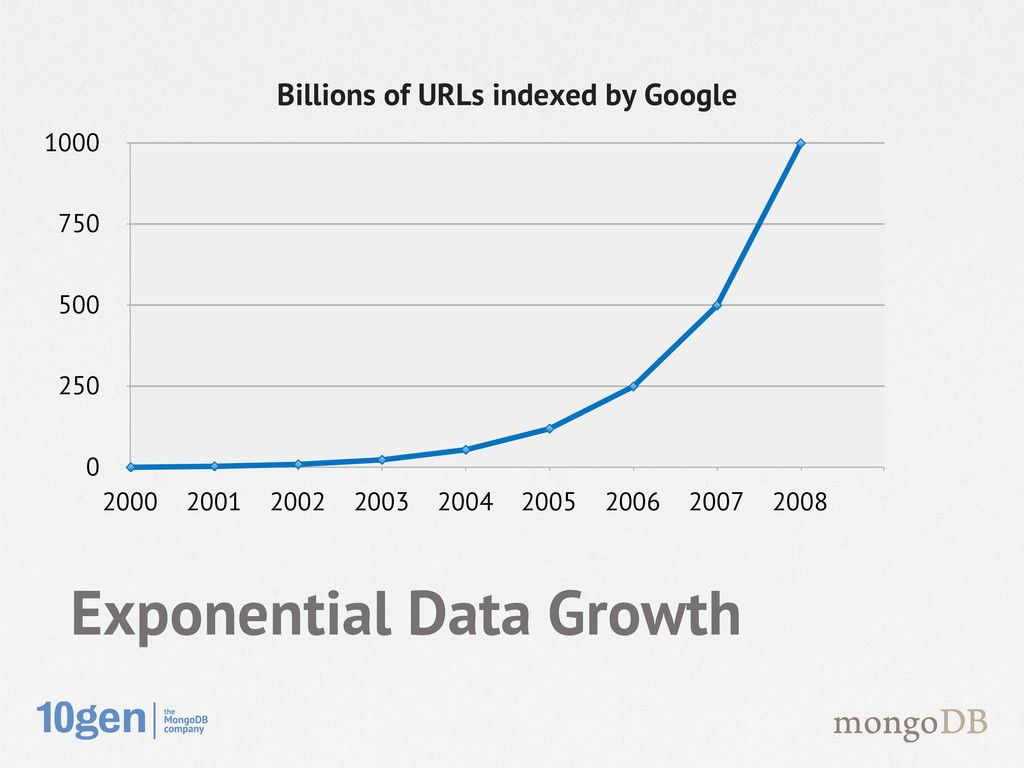
Exponential Data Growth 0 250 500 750 1000 2000 2001
2002 2003 2004 2005 2006 2007 2008 Billions of URLs indexed by Google -
In the past few years Open source software emerged enabling
the rest of us to handle Big Data -
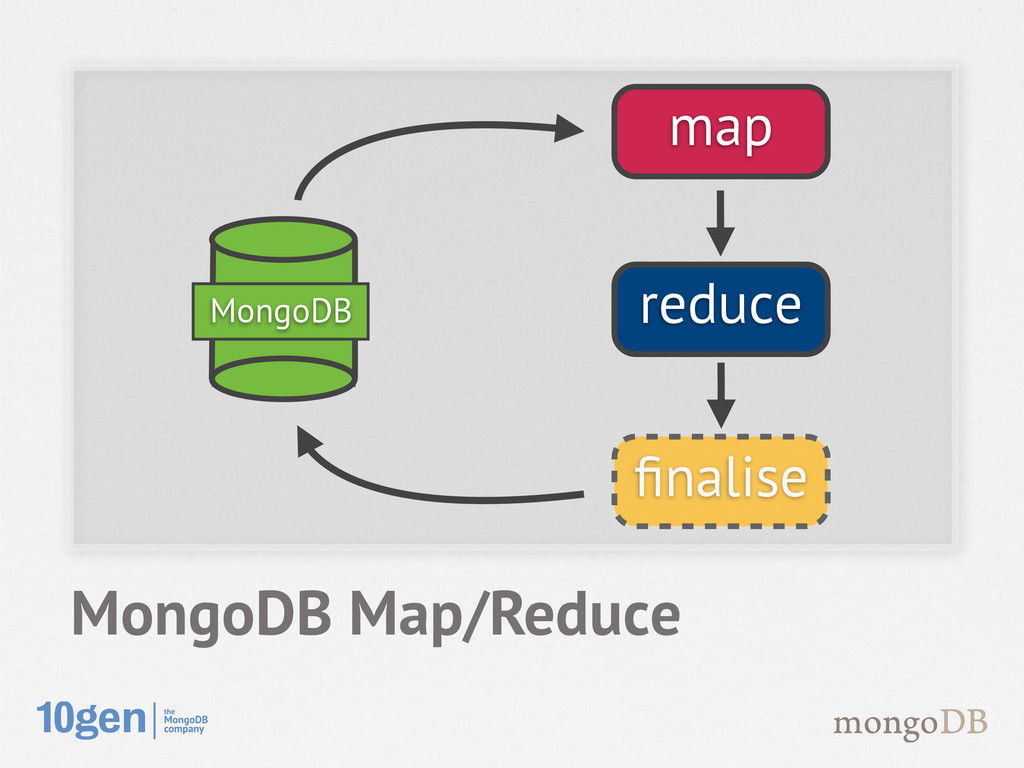
• MongoDB is an ideal operational database • MongoDB provides
high performance for storage and retrieval at large scale • MongoDB has a robust query interface permitting intelligent operations • MongoDB is not a data processing engine, but provides processing functionality How MongoDB solves our needs -
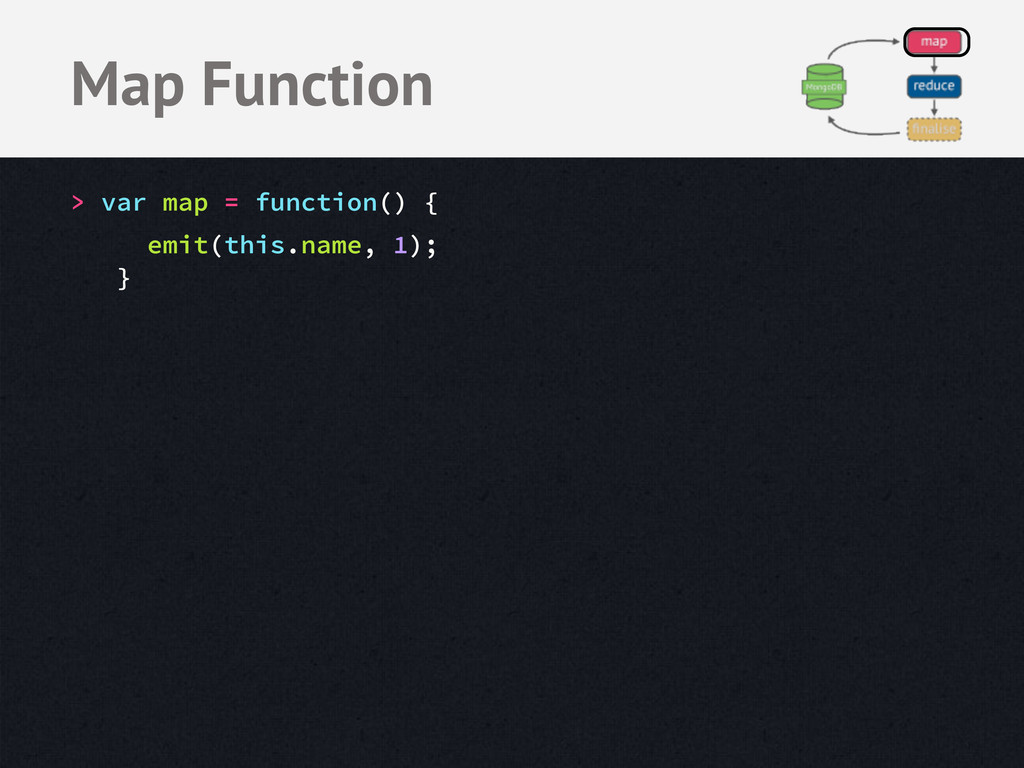
The "hello world" of map reduce is counting words in
a paragraph of text. We could do that but lets do something a little more interesting... -
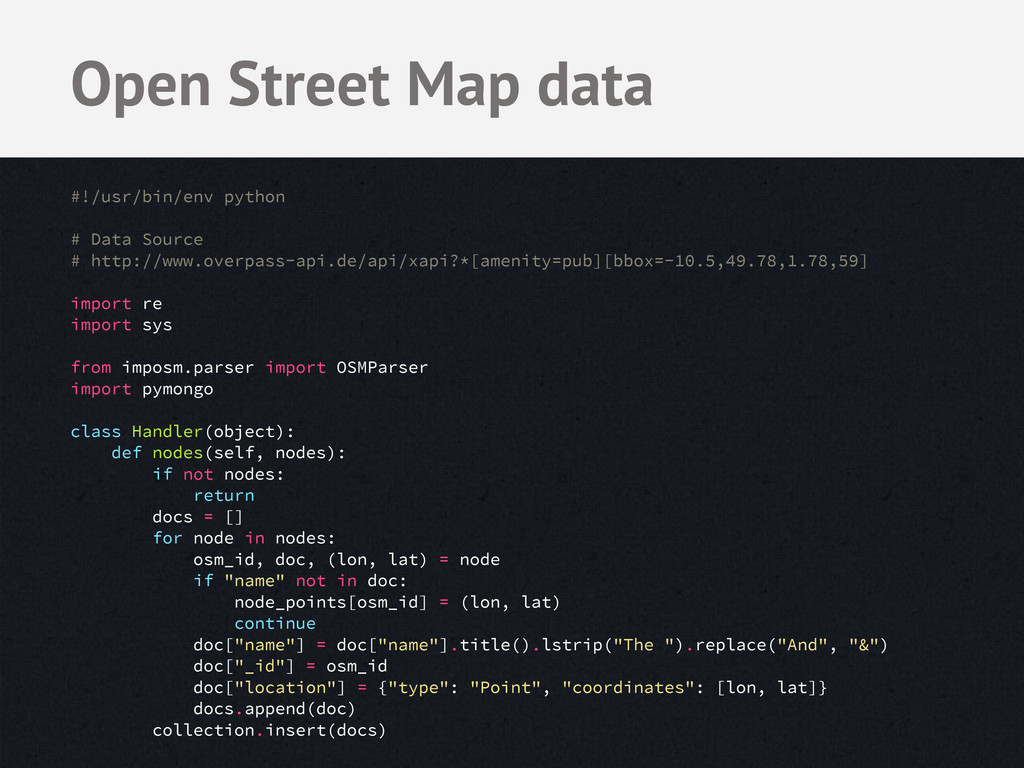
Open Street Map data #!/usr/bin/env python # Data Source #
http://www.overpass-api.de/api/xapi?*[amenity=pub][bbox=-10.5,49.78,1.78,59] import re import sys from imposm.parser import OSMParser import pymongo class Handler(object): def nodes(self, nodes): if not nodes: return docs = [] for node in nodes: osm_id, doc, (lon, lat) = node if "name" not in doc: node_points[osm_id] = (lon, lat) continue doc["name"] = doc["name"].title().lstrip("The ").replace("And", "&") doc["_id"] = osm_id doc["location"] = {"type": "Point", "coordinates": [lon, lat]} docs.append(doc) collection.insert(docs) -
{ "_id" : 451152, "amenity" : "pub", "name" : "The
Dignity", "addr:housenumber" : "363", "addr:street" : "Regents Park Road", "addr:city" : "London", "addr:postcode" : "N3 1DH", "toilets" : "yes", "toilets:access" : "customers", "location" : { "type" : "Point", "coordinates" : [-0.1945732, 51.6008172] } } Example pub data -
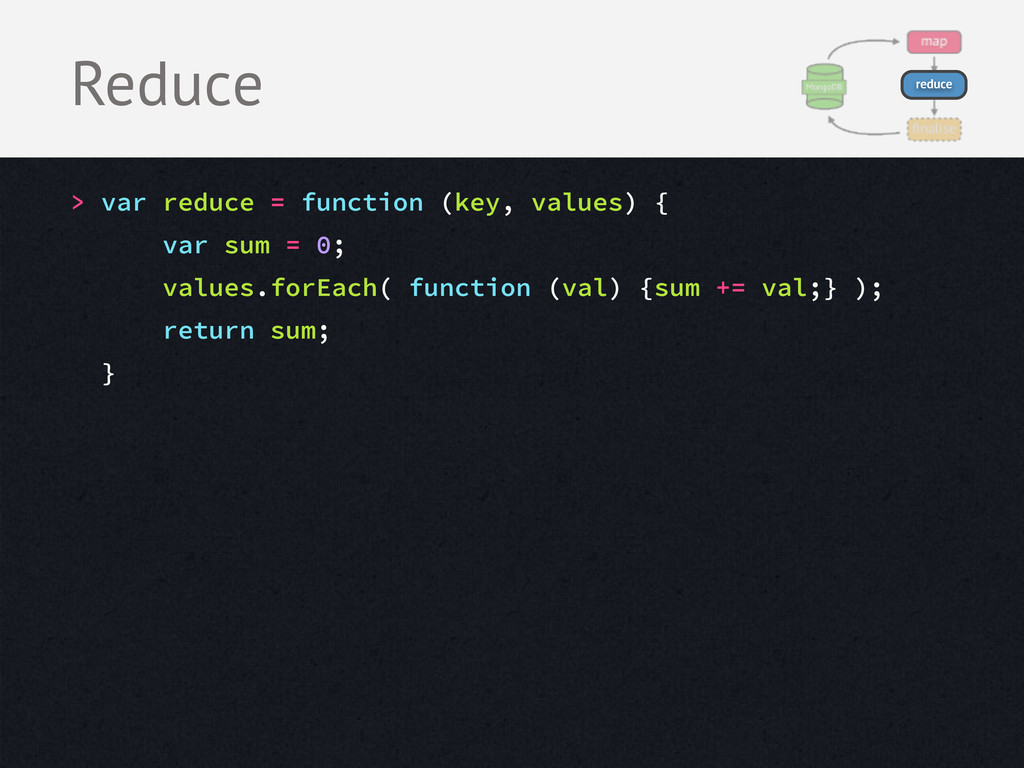
> var reduce = function (key, values) { var sum
= 0; values.forEach( function (val) {sum += val;} ); return sum; } Reduce reduce -
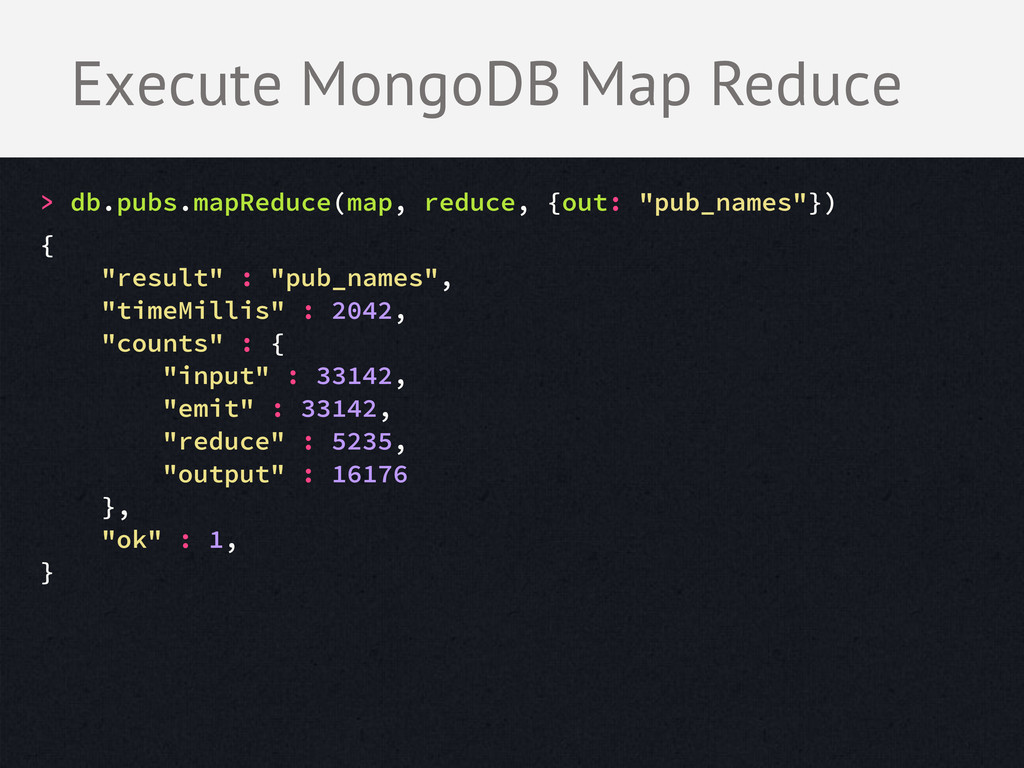
> db.pubs.mapReduce(map, reduce, {out: "pub_names"}) { "result" : "pub_names", "timeMillis"
: 2042, "counts" : { "input" : 33142, "emit" : 33142, "reduce" : 5235, "output" : 16176 }, "ok" : 1, } Execute MongoDB Map Reduce -
> db.pub_names.find().sort({value: -1}).limit(10) { "_id" : "The Red Lion", "value"
: 407 } { "_id" : "The Royal Oak", "value" : 328 } { "_id" : "The Crown", "value" : 242 } { "_id" : "The White Hart", "value" : 214 } { "_id" : "The White Horse", "value" : 200 } { "_id" : "The New Inn", "value" : 187 } { "_id" : "The Plough", "value" : 185 } { "_id" : "The Rose & Crown", "value" : 164 } { "_id" : "The Wheatsheaf", "value" : 147 } { "_id" : "The Swan", "value" : 140 } Results -
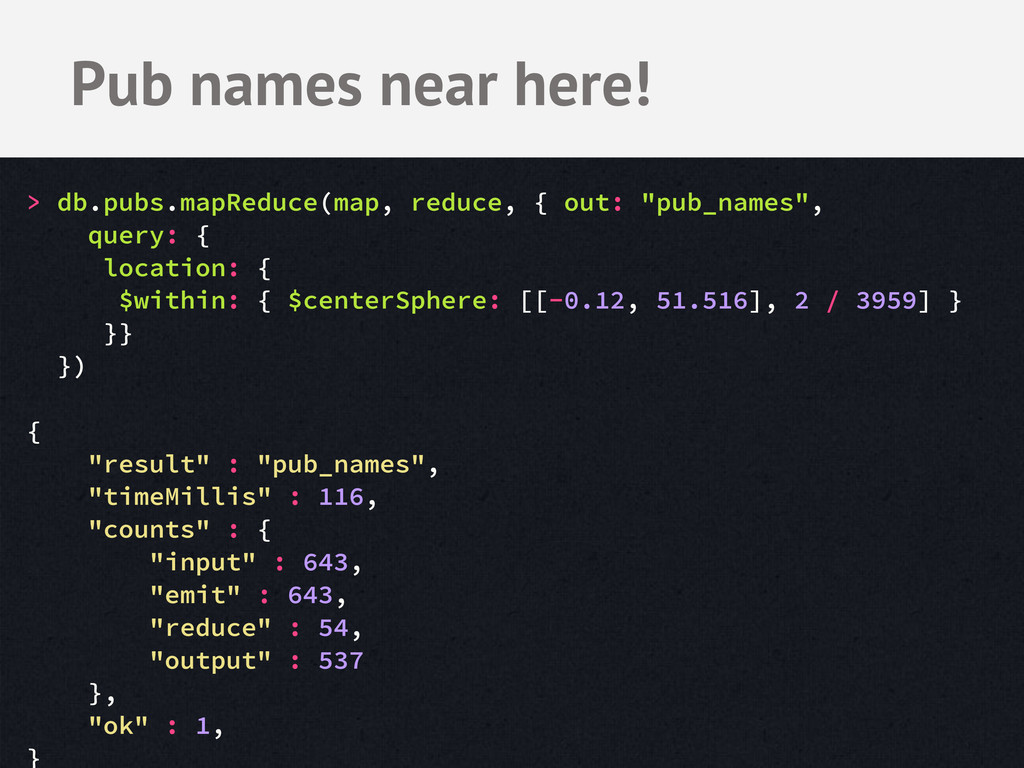
Pub names near here! > db.pubs.mapReduce(map, reduce, { out: "pub_names",
query: { location: { $within: { $centerSphere: [[-0.12, 51.516], 2 / 3959] } }} }) { "result" : "pub_names", "timeMillis" : 116, "counts" : { "input" : 643, "emit" : 643, "reduce" : 54, "output" : 537 }, "ok" : 1, } -
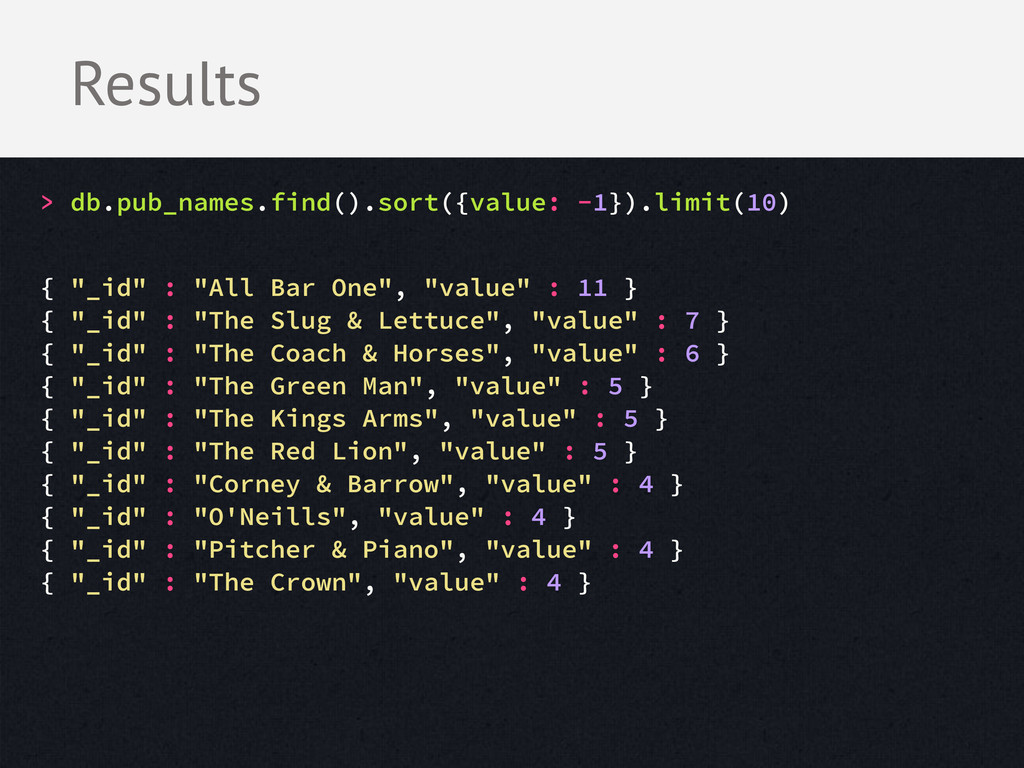
> db.pub_names.find().sort({value: -1}).limit(10) { "_id" : "All Bar One", "value"
: 11 } { "_id" : "The Slug & Lettuce", "value" : 7 } { "_id" : "The Coach & Horses", "value" : 6 } { "_id" : "The Green Man", "value" : 5 } { "_id" : "The Kings Arms", "value" : 5 } { "_id" : "The Red Lion", "value" : 5 } { "_id" : "Corney & Barrow", "value" : 4 } { "_id" : "O'Neills", "value" : 4 } { "_id" : "Pitcher & Piano", "value" : 4 } { "_id" : "The Crown", "value" : 4 } Results -
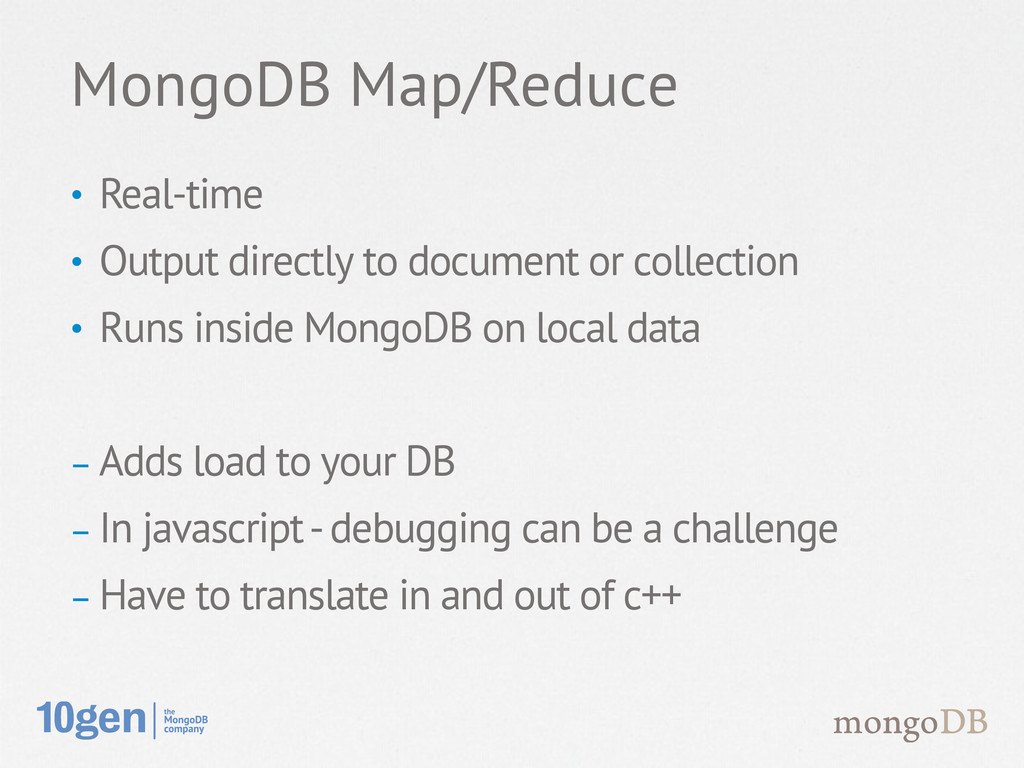
• Real-time • Output directly to document or collection •
Runs inside MongoDB on local data - Adds load to your DB - In javascript - debugging can be a challenge - Have to translate in and out of c++ MongoDB Map/Reduce -
• $project • $match • $limit • $skip • $sort
• $unwind • $group Aggregation framework operators -
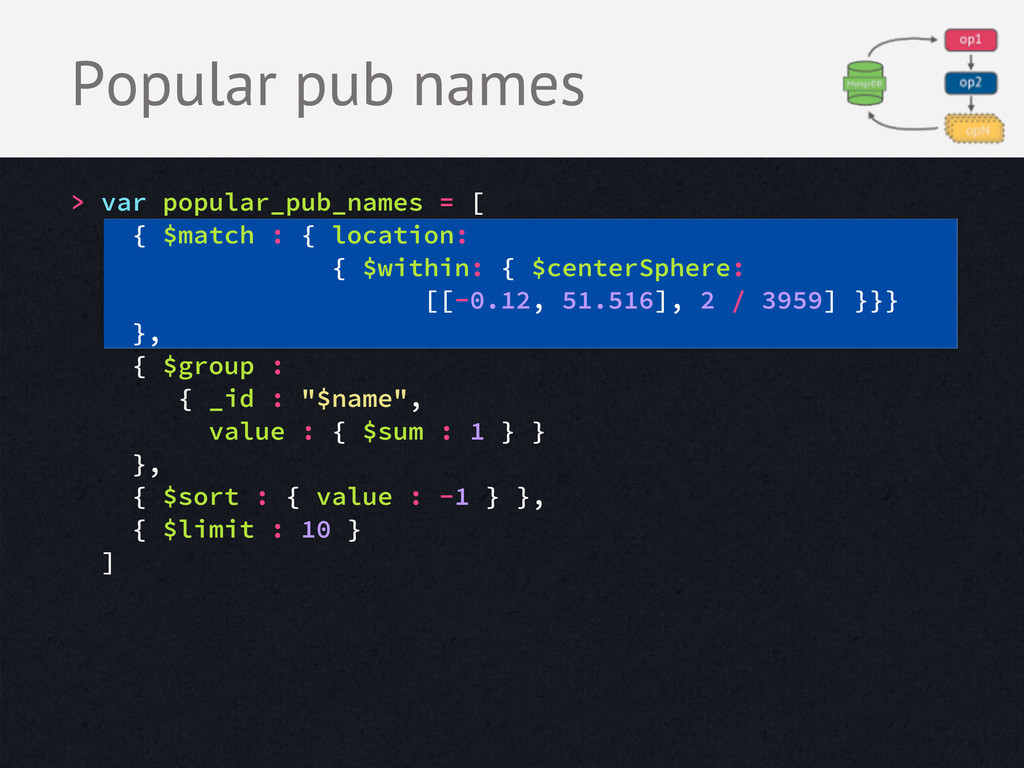
• Filter documents • Uses existing query syntax • If
using $geoNear it has to be first in pipeline • $where not supported $match -
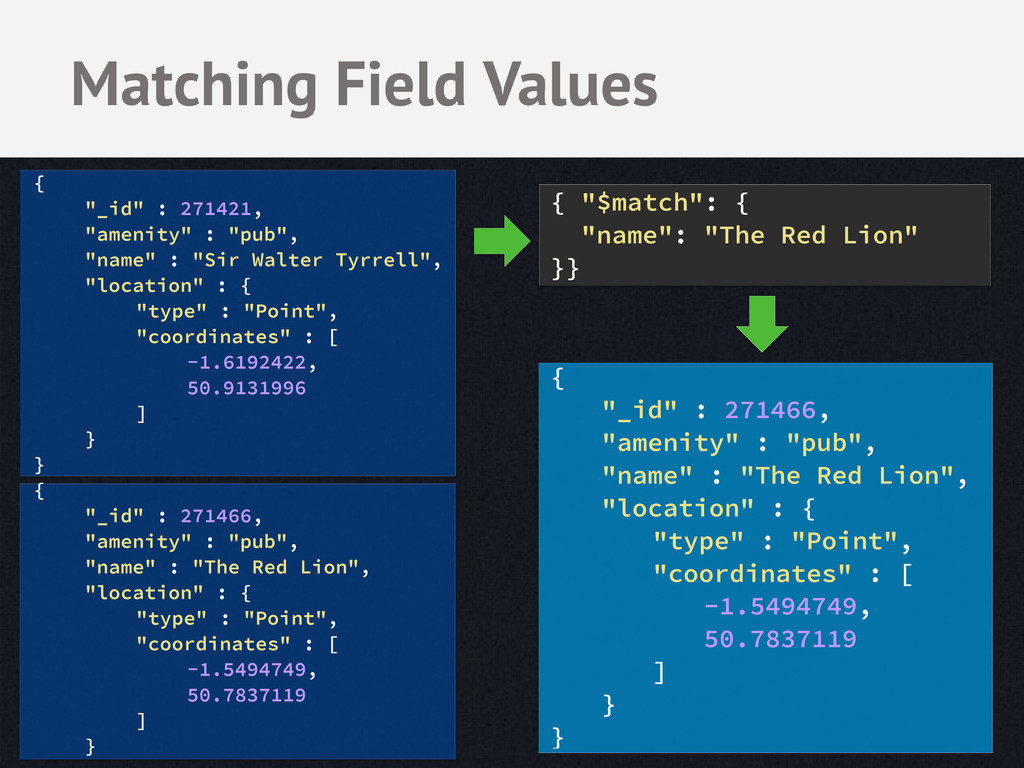
Matching Field Values { "_id" : 271421, "amenity" : "pub",
"name" : "Sir Walter Tyrrell", "location" : { "type" : "Point", "coordinates" : [ -1.6192422, 50.9131996 ] } } { "_id" : 271466, "amenity" : "pub", "name" : "The Red Lion", "location" : { "type" : "Point", "coordinates" : [ -1.5494749, 50.7837119 ] } { "$match": { "name": "The Red Lion" }} { "_id" : 271466, "amenity" : "pub", "name" : "The Red Lion", "location" : { "type" : "Point", "coordinates" : [ -1.5494749, 50.7837119 ] } } -
• Reshape documents • Include, exclude or rename fields •
Inject computed fields • Create sub-document fields $project -
Including and Excluding Fields { "_id" : 271466, "amenity" :
"pub", "name" : "The Red Lion", "location" : { "type" : "Point", "coordinates" : [ -1.5494749, 50.7837119 ] } } { "$project": { "_id": 0, "amenity": 1, "name": 1 }} { "amenity" : "pub", "name" : "The Red Lion" } -
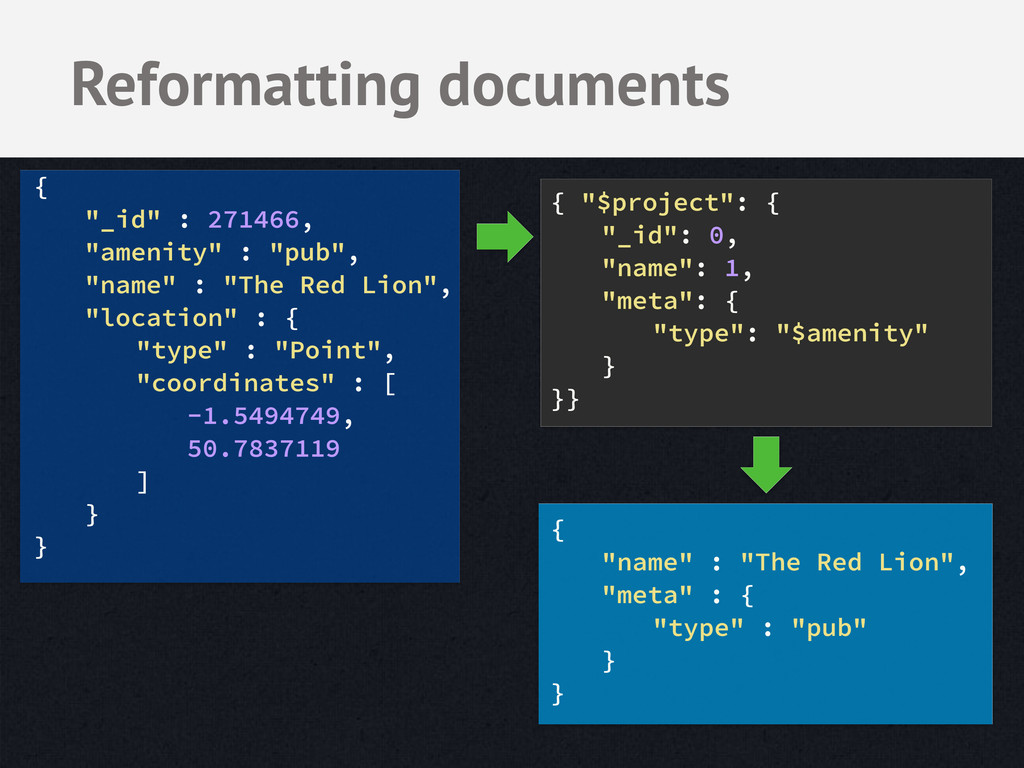
Reformatting documents { "_id" : 271466, "amenity" : "pub", "name"
: "The Red Lion", "location" : { "type" : "Point", "coordinates" : [ -1.5494749, 50.7837119 ] } } { "$project": { "_id": 0, "name": 1, "meta": { "type": "$amenity" } }} { "name" : "The Red Lion", "meta" : { "type" : "pub" } } -
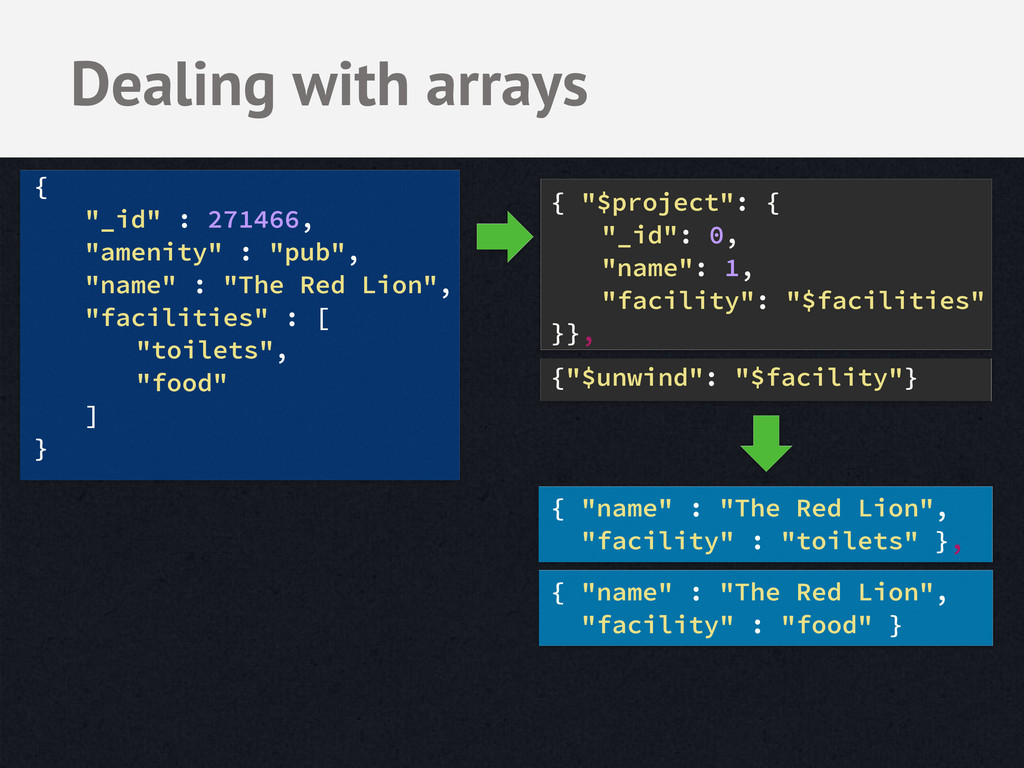
Dealing with arrays { "_id" : 271466, "amenity" : "pub",
"name" : "The Red Lion", "facilities" : [ "toilets", "food" ] } { "$project": { "_id": 0, "name": 1, "facility": "$facilities" }}, {"$unwind": "$facility"} { "name" : "The Red Lion", "facility" : "toilets" }, { "name" : "The Red Lion", "facility" : "food" } -
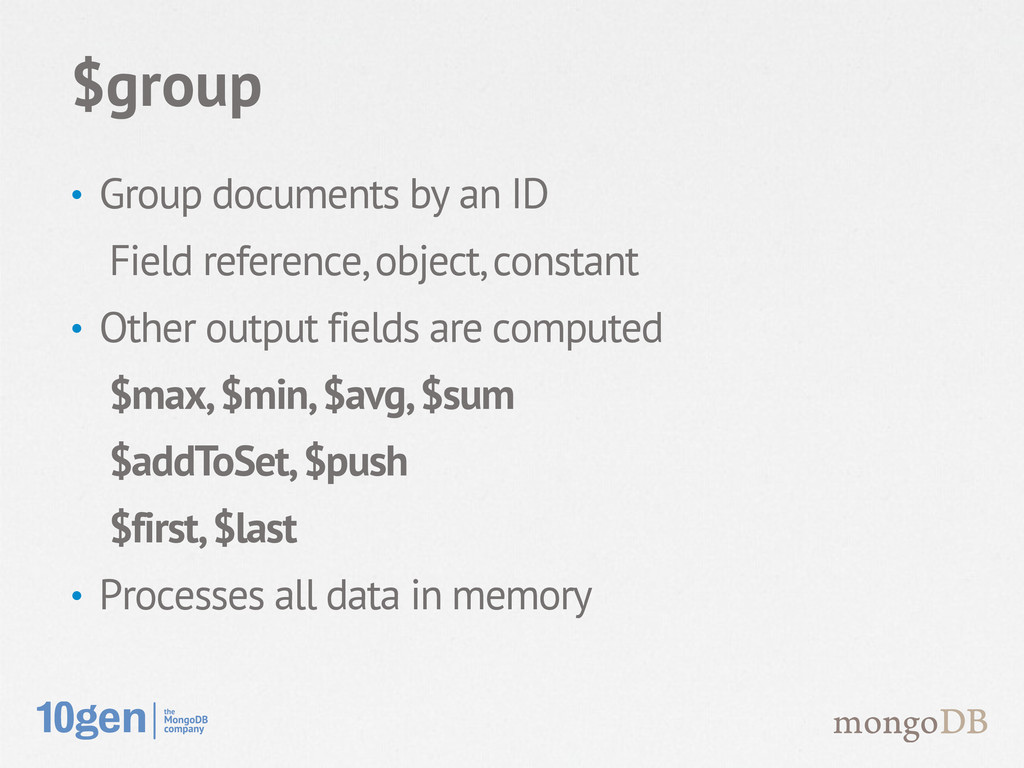
• Group documents by an ID Field reference, object, constant
• Other output fields are computed $max, $min, $avg, $sum $addToSet, $push $first, $last • Processes all data in memory $group -
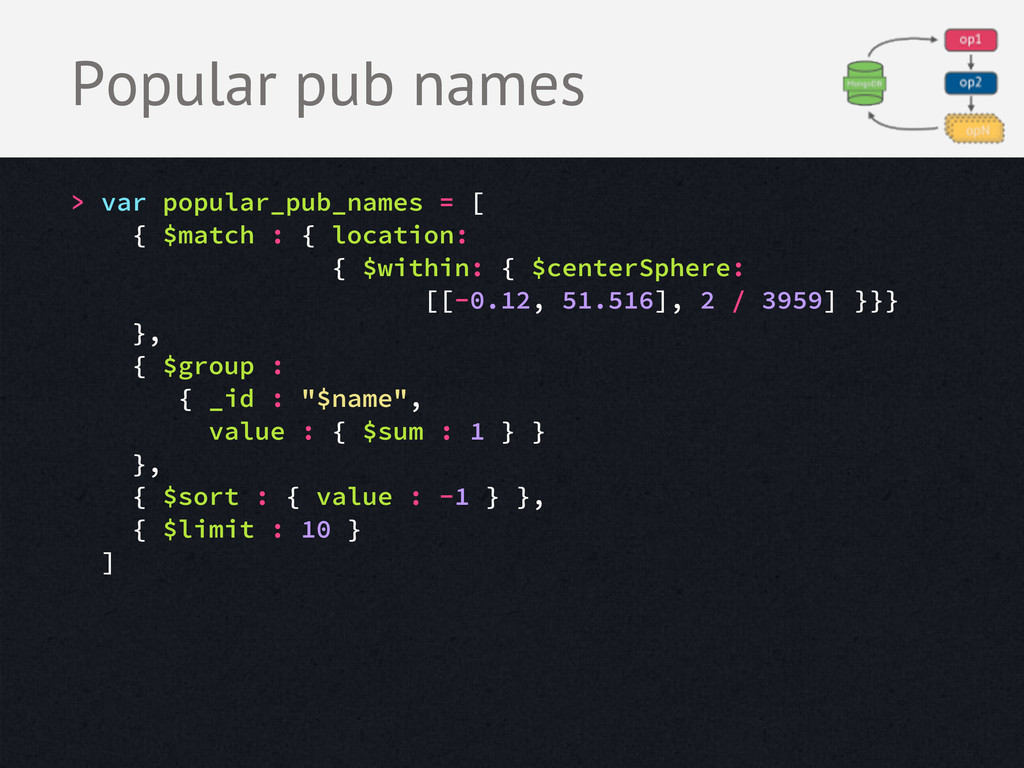
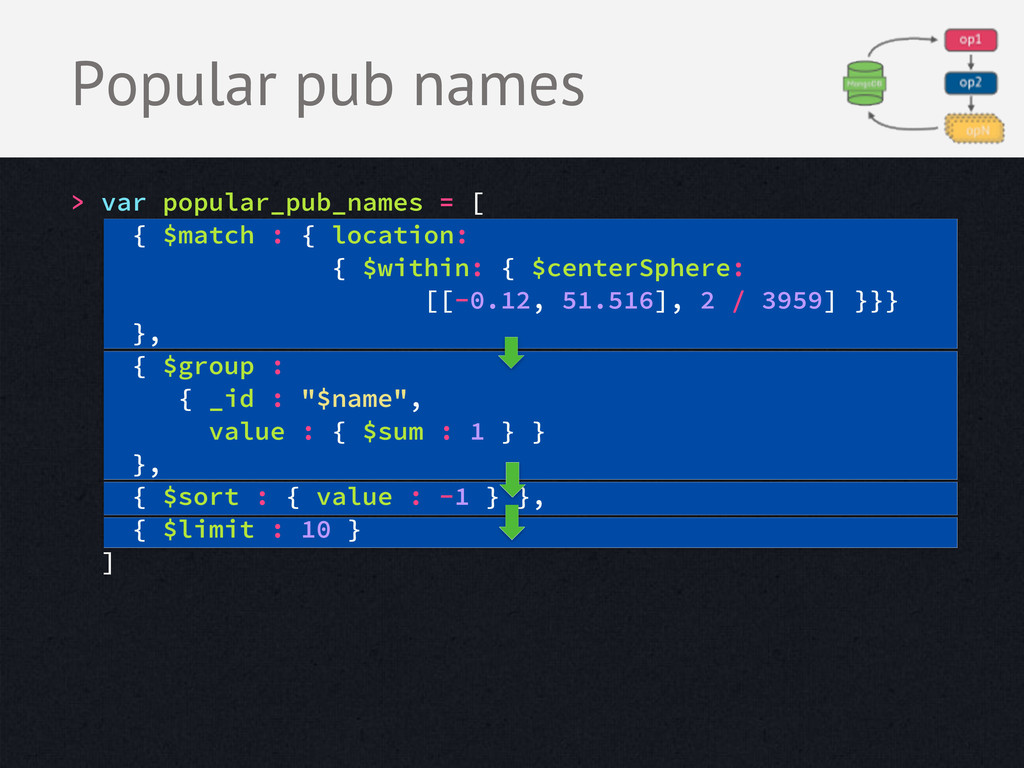
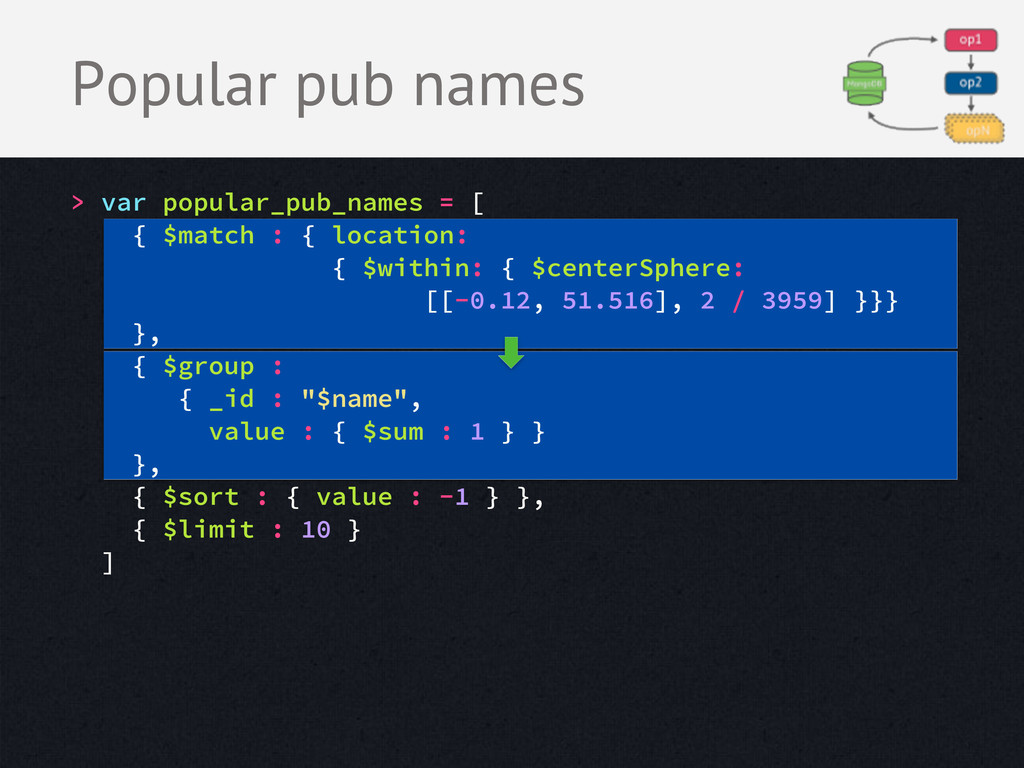
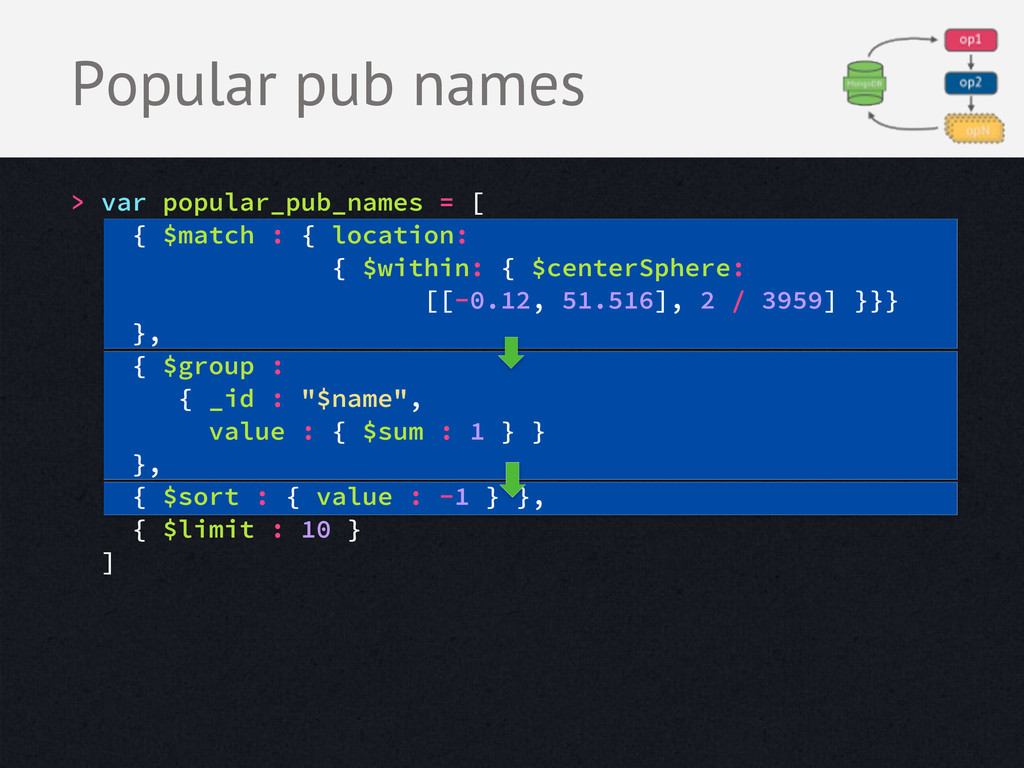
Popular pub names > var popular_pub_names = [ { $match
: { location: { $within: { $centerSphere: [[-0.12, 51.516], 2 / 3959] }}} }, { $group : { _id : "$name", value : { $sum : 1 } } }, { $sort : { value : -1 } }, { $limit : 10 } ] -
Popular pub names > var popular_pub_names = [ { $match
: { location: { $within: { $centerSphere: [[-0.12, 51.516], 2 / 3959] }}} }, { $group : { _id : "$name", value : { $sum : 1 } } }, { $sort : { value : -1 } }, { $limit : 10 } ] -
Popular pub names > var popular_pub_names = [ { $match
: { location: { $within: { $centerSphere: [[-0.12, 51.516], 2 / 3959] }}} }, { $group : { _id : "$name", value : { $sum : 1 } } }, { $sort : { value : -1 } }, { $limit : 10 } ] -
Popular pub names > var popular_pub_names = [ { $match
: { location: { $within: { $centerSphere: [[-0.12, 51.516], 2 / 3959] }}} }, { $group : { _id : "$name", value : { $sum : 1 } } }, { $sort : { value : -1 } }, { $limit : 10 } ] -
Popular pub names > var popular_pub_names = [ { $match
: { location: { $within: { $centerSphere: [[-0.12, 51.516], 2 / 3959] }}} }, { $group : { _id : "$name", value : { $sum : 1 } } }, { $sort : { value : -1 } }, { $limit : 10 } ] -
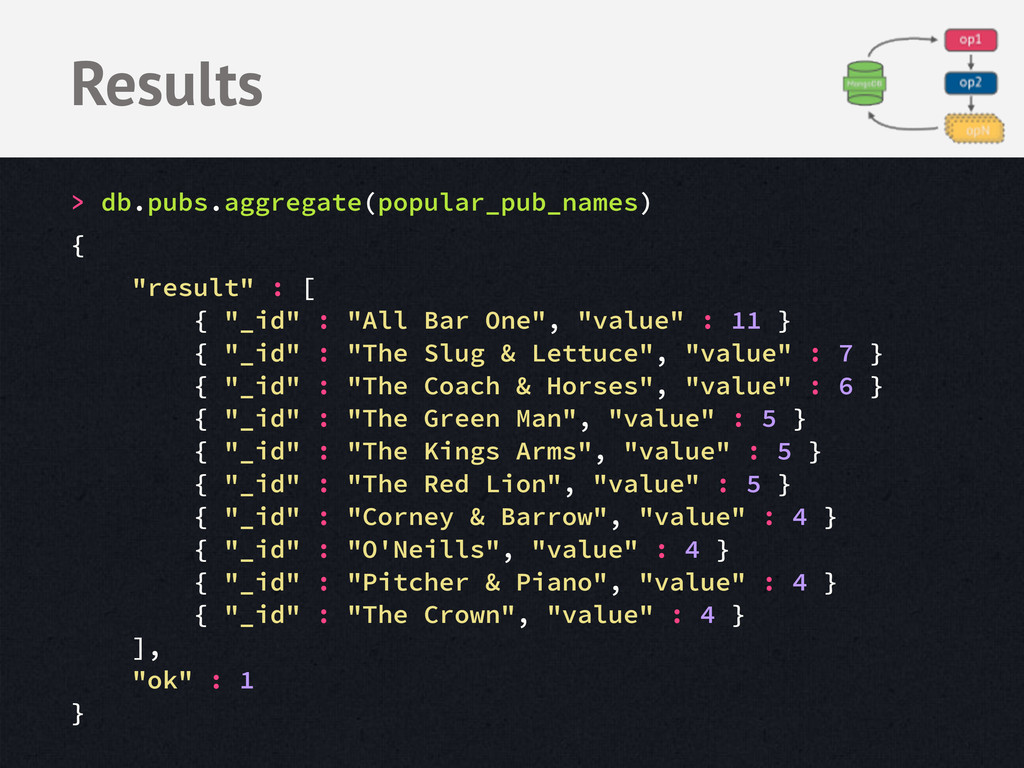
Results > db.pubs.aggregate(popular_pub_names) { "result" : [ { "_id" :
"All Bar One", "value" : 11 } { "_id" : "The Slug & Lettuce", "value" : 7 } { "_id" : "The Coach & Horses", "value" : 6 } { "_id" : "The Green Man", "value" : 5 } { "_id" : "The Kings Arms", "value" : 5 } { "_id" : "The Red Lion", "value" : 5 } { "_id" : "Corney & Barrow", "value" : 4 } { "_id" : "O'Neills", "value" : 4 } { "_id" : "Pitcher & Piano", "value" : 4 } { "_id" : "The Crown", "value" : 4 } ], "ok" : 1 } -
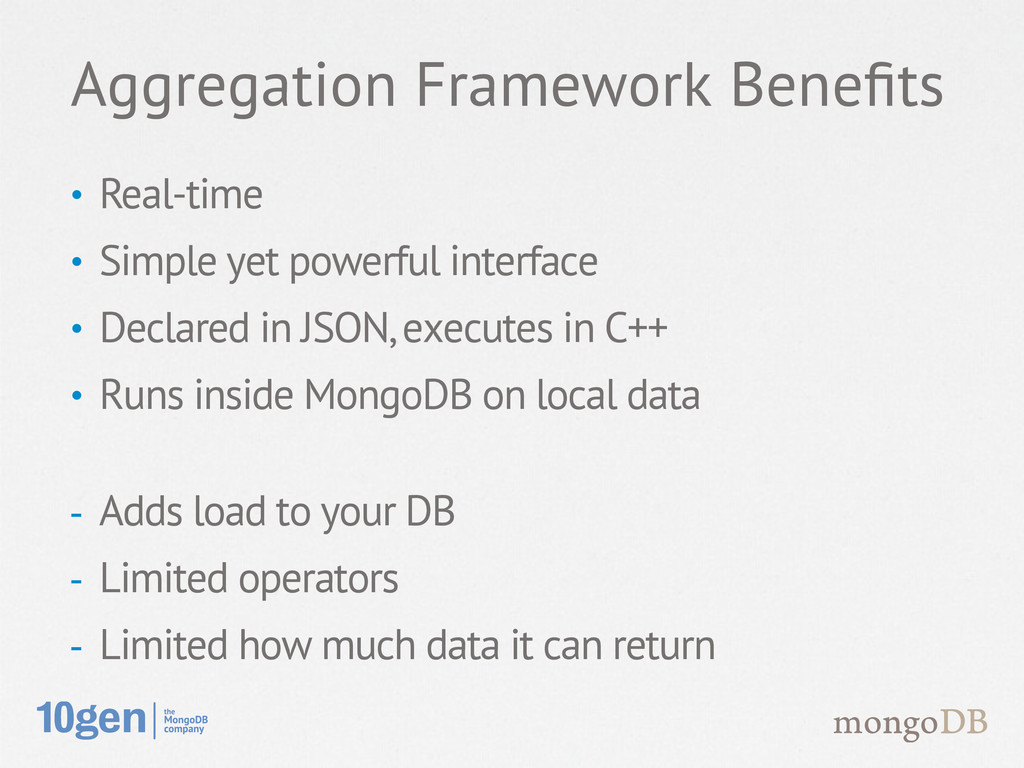
• Real-time • Simple yet powerful interface • Declared in
JSON, executes in C++ • Runs inside MongoDB on local data - Adds load to your DB - Limited operators - Limited how much data it can return Aggregation Framework Benefits -
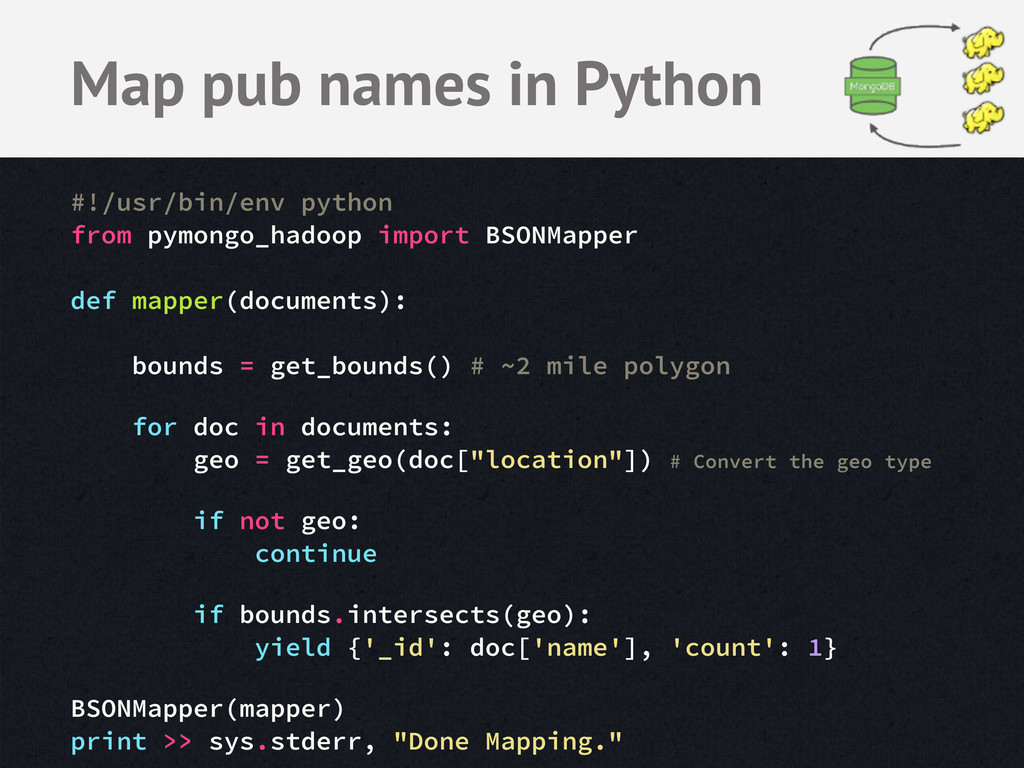
#!/usr/bin/env python from pymongo_hadoop import BSONMapper def mapper(documents): bounds =
get_bounds() # ~2 mile polygon for doc in documents: geo = get_geo(doc["location"]) # Convert the geo type if not geo: continue if bounds.intersects(geo): yield {'_id': doc['name'], 'count': 1} BSONMapper(mapper) print >> sys.stderr, "Done Mapping." Map pub names in Python -
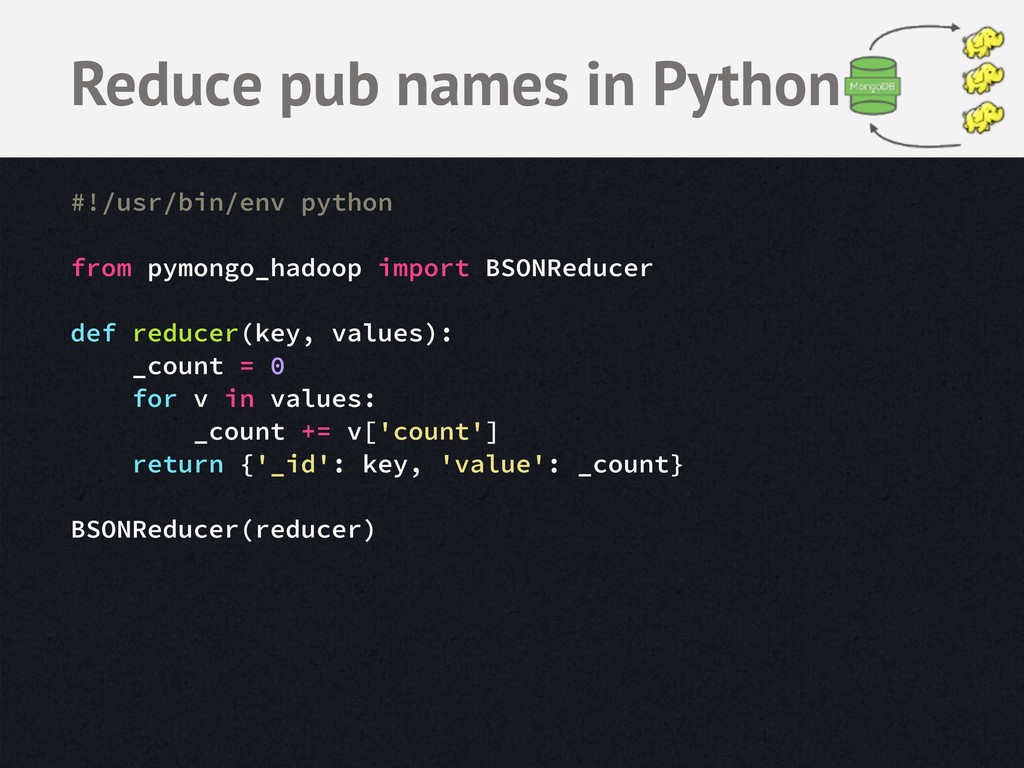
#!/usr/bin/env python from pymongo_hadoop import BSONReducer def reducer(key, values): _count
= 0 for v in values: _count += v['count'] return {'_id': key, 'value': _count} BSONReducer(reducer) Reduce pub names in Python -
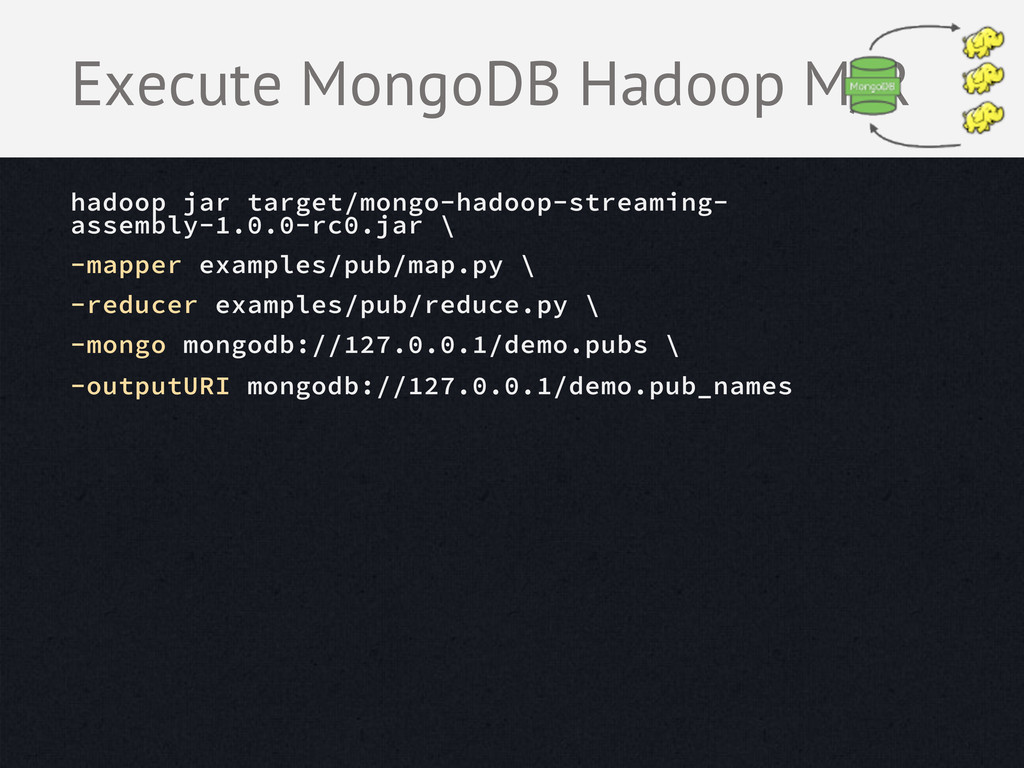
hadoop jar target/mongo-hadoop-streaming- assembly-1.0.0-rc0.jar \ -mapper examples/pub/map.py \ -reducer examples/pub/reduce.py
\ -mongo mongodb://127.0.0.1/demo.pubs \ -outputURI mongodb://127.0.0.1/demo.pub_names Execute MongoDB Hadoop M/R -
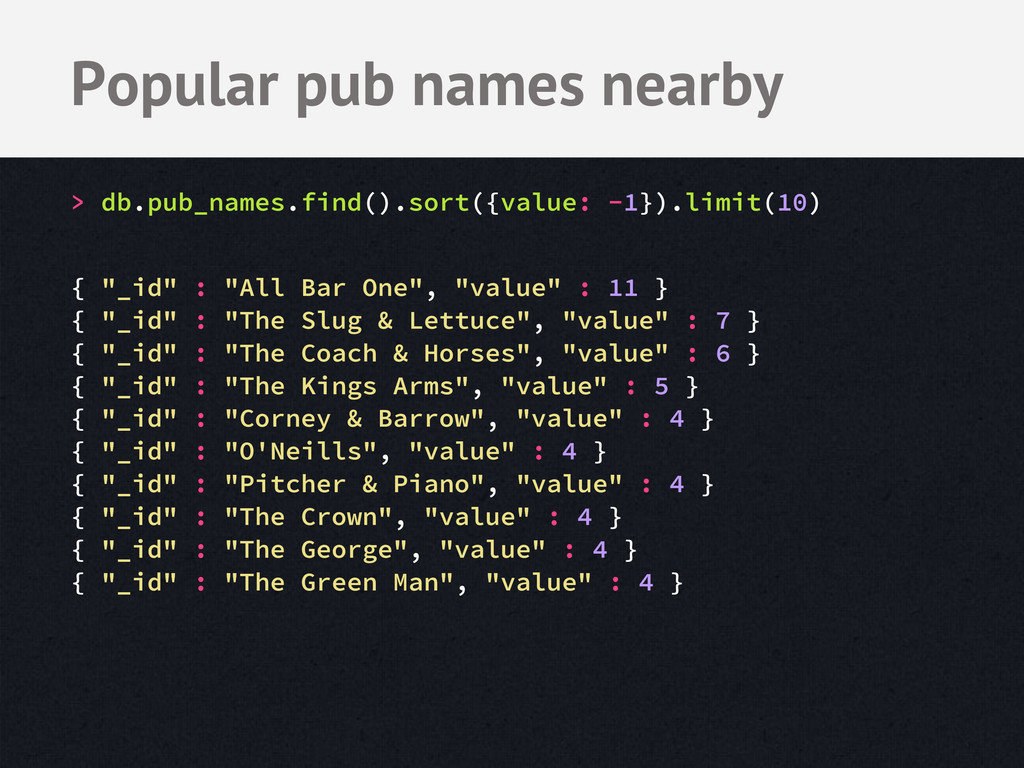
Popular pub names nearby > db.pub_names.find().sort({value: -1}).limit(10) { "_id" :
"All Bar One", "value" : 11 } { "_id" : "The Slug & Lettuce", "value" : 7 } { "_id" : "The Coach & Horses", "value" : 6 } { "_id" : "The Kings Arms", "value" : 5 } { "_id" : "Corney & Barrow", "value" : 4 } { "_id" : "O'Neills", "value" : 4 } { "_id" : "Pitcher & Piano", "value" : 4 } { "_id" : "The Crown", "value" : 4 } { "_id" : "The George", "value" : 4 } { "_id" : "The Green Man", "value" : 4 } -
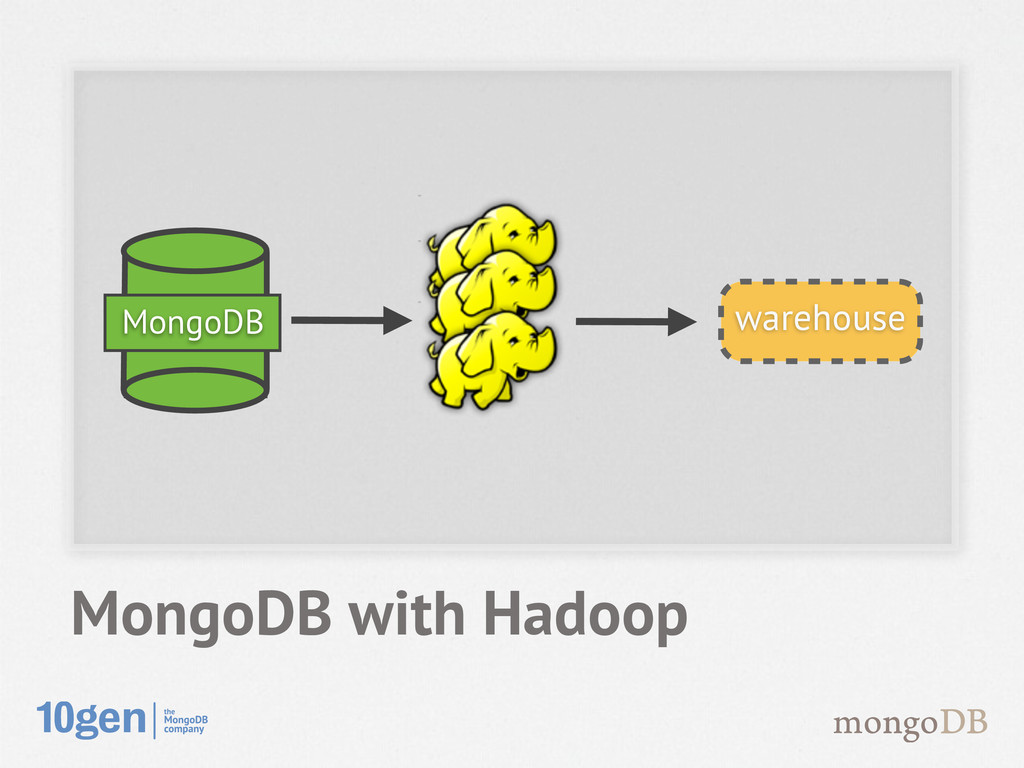
• Away from data store • Can leverage existing data
processing infrastructure • Can horizontally scale your data processing - Offline batch processing - Requires synchronisation between store & processor - Infrastructure is much more complex MongoDB and Hadoop -
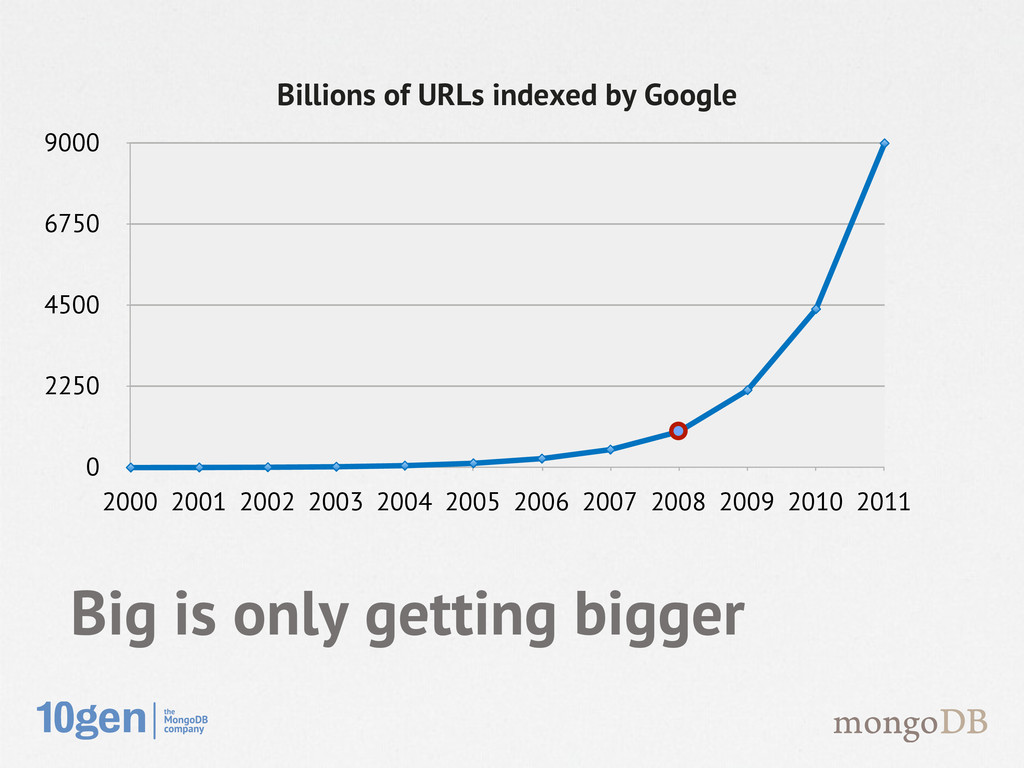
Big is only getting bigger 0 2250 4500 6750 9000
2000 2001 2002 2003 2004 2005 2006 2007 2008 2009 2010 2011 Billions of URLs indexed by Google -
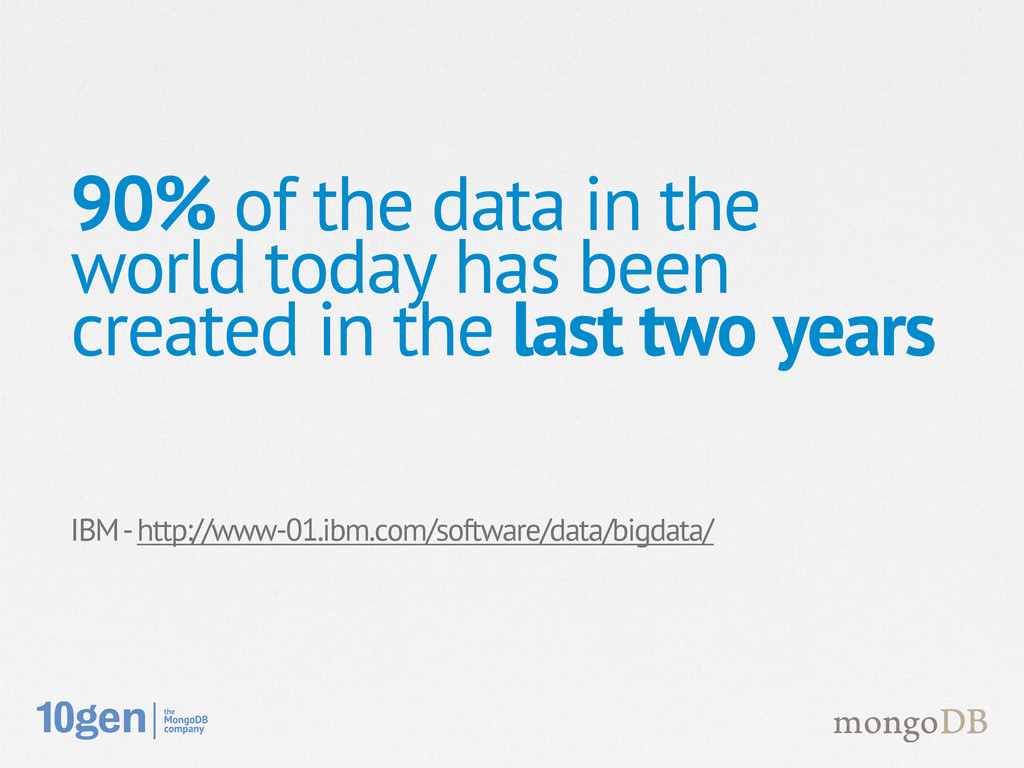
IBM - http://www-01.ibm.com/software/data/bigdata/ 90% of the data in the world
today has been created in the last two years -
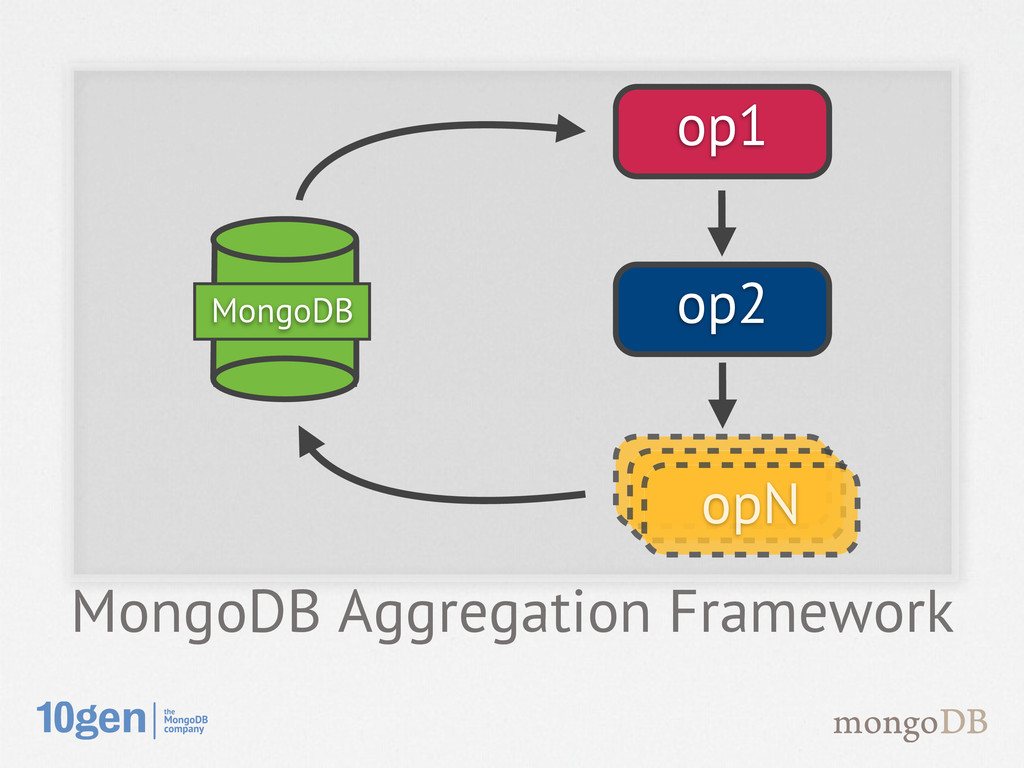
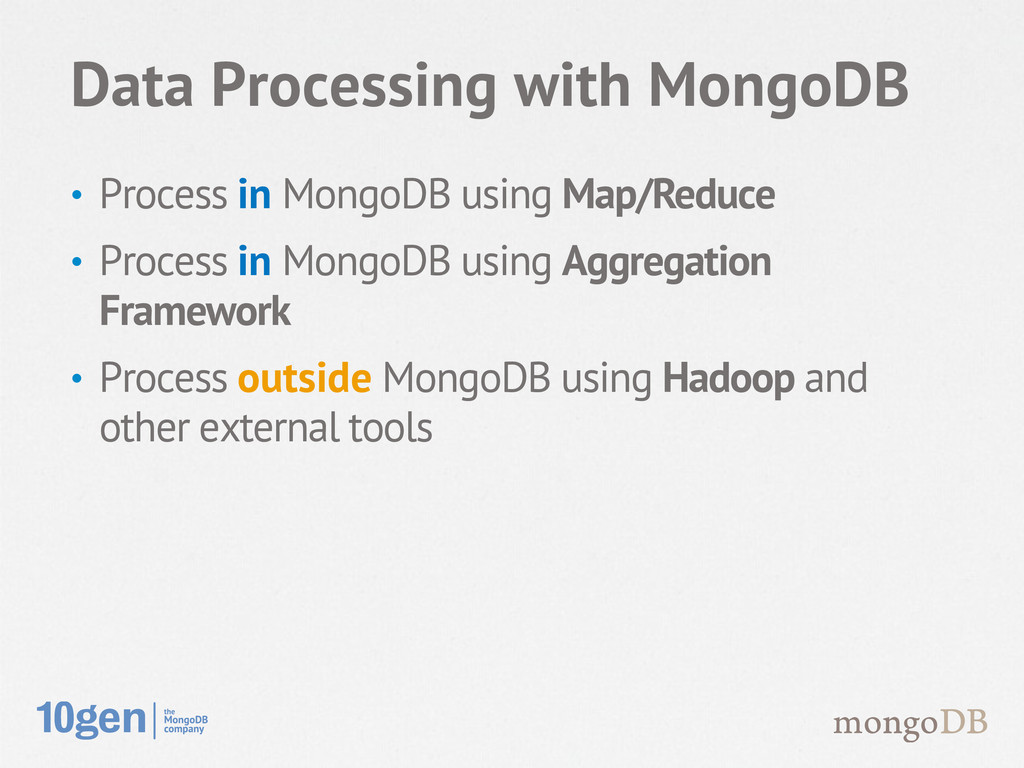
• Process in MongoDB using Map/Reduce • Process in MongoDB
using Aggregation Framework • Process outside MongoDB using Hadoop and other external tools Data Processing with MongoDB -
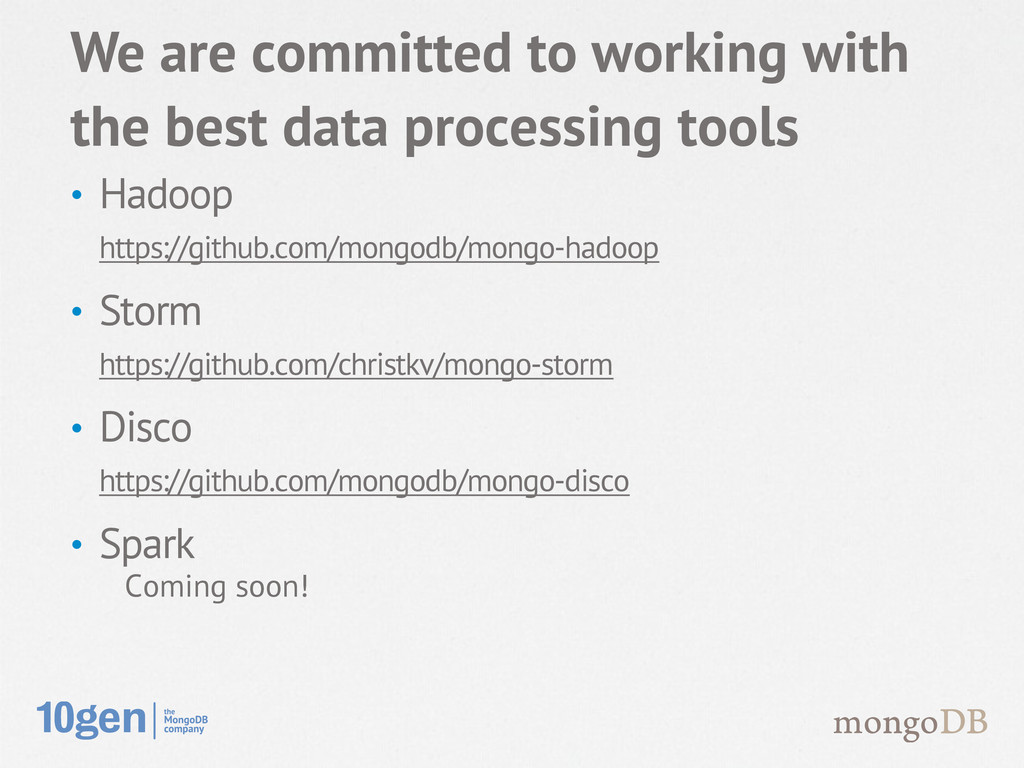
• Hadoop https://github.com/mongodb/mongo-hadoop • Storm https://github.com/christkv/mongo-storm • Disco https://github.com/mongodb/mongo-disco •
Spark Coming soon! We are committed to working with the best data processing tools