Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
Beating State-of-the-art By -10000% @ CIDR Gong...
Search
Reynold Xin
January 07, 2013
Research
170
1
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
Beating State-of-the-art By -10000% @ CIDR Gong Show
I gave a 5-min Gong Show talk at CIDR on my experience with Spark, Shark, and GraphX.
Reynold Xin
January 07, 2013
More Decks by Reynold Xin
See All by Reynold Xin
(Berkeley CS186 guest lecture) Big Data Analytics Systems: What Goes Around Comes Around
rxin
12
2k
Interface Design for Spark Community
rxin
12
1.4k
Spark Committer Night meetup @ NYC
rxin
1
150
Apache Spark: Unified Platform for Big Data
rxin
1
260
Advanced Spark @ Spark Summit 2014
rxin
4
370
Apache Spark: Easier and Faster Big Data
rxin
2
320
GraphX at Spark User Meetup
rxin
0
190
Shark SIGMOD research deck
rxin
2
580
The Spark Ecosystem: Fast and Expressive Big Data Analytics in Scala @ Scala Days 2013
rxin
3
730
Other Decks in Research
See All in Research
Evaluation génomique des femelles laitières croisées : comprendre la méthode pour accompagner les éleveurs à son utilisation
institutdelelevage
PRO
0
160
COMETAを用いたデータ民主化運動の歴史
sazimai
0
270
Être éleveur dans un monde en transition : Comprendre les changements pour mieux les accompagner
institutdelelevage
PRO
0
110
ros2-perf-multihost: Automated Coordination Framework for Objective Architecture Evaluation in Distributed Systems
takasehideki
0
140
適応的スパムフィルタのための軽量な類似メッセージカウンタ / jsai2026-adaptive-spam-filter
monochromegane
0
5.8k
[IR Reading 2026春 論文紹介] LLM-based Listwise Reranking under the Effect of Positional Bias (ECIR 2026) /IR-Reading-2026-Spring
koheishinden
PRO
0
460
最先端NLP 2026 論文紹介: Wait, Wait, Wait... Why Do Reasoning Models Loop? / SNLP Paper Review: Wait, Wait, Wait... Why Do Reasoning Models Loop?
tkng
0
250
Développer des solutions de réduction des émissions de méthane entérique : 1ers résultats Méthane 2030
institutdelelevage
PRO
0
240
20260624 NLP colloquium: 単一のhubテキストがCLIPを壊す:hubnessによる埋め込みの脆弱性特定
de9uch1
2
290
Apache Gravitinoで実現する Icebergカタログ統合とアクセスの一元化
matsumooon
0
590
横浜市長(山中氏)の言動にかかる第三者による調査報告書
sishi2026
0
590
Cross-Media Human-Information Interaction
signer
PRO
0
270
Featured
See All Featured
Automating Front-end Workflow
addyosmani
1369
210k
Build The Right Thing And Hit Your Dates
maggiecrowley
39
3.5k
Tell your own story through comics
letsgokoyo
1
1.1k
It's Worth the Effort
3n
188
29k
Gemini Prompt Engineering: Practical Techniques for Tangible AI Outcomes
mfonobong
2
580
What's in a price? How to price your products and services
michaelherold
247
13k
How Fast Is Fast Enough? [PerfNow 2025]
tammyeverts
3
920
Stewardship and Sustainability of Urban and Community Forests
pwiseman
0
540
Fireside Chat
paigeccino
43
4.1k
Exploring anti-patterns in Rails
aemeredith
4
520
Cheating the UX When There Is Nothing More to Optimize - PixelPioneers
stephaniewalter
287
14k
Facilitating Awesome Meetings
lara
57
7.2k
Transcript
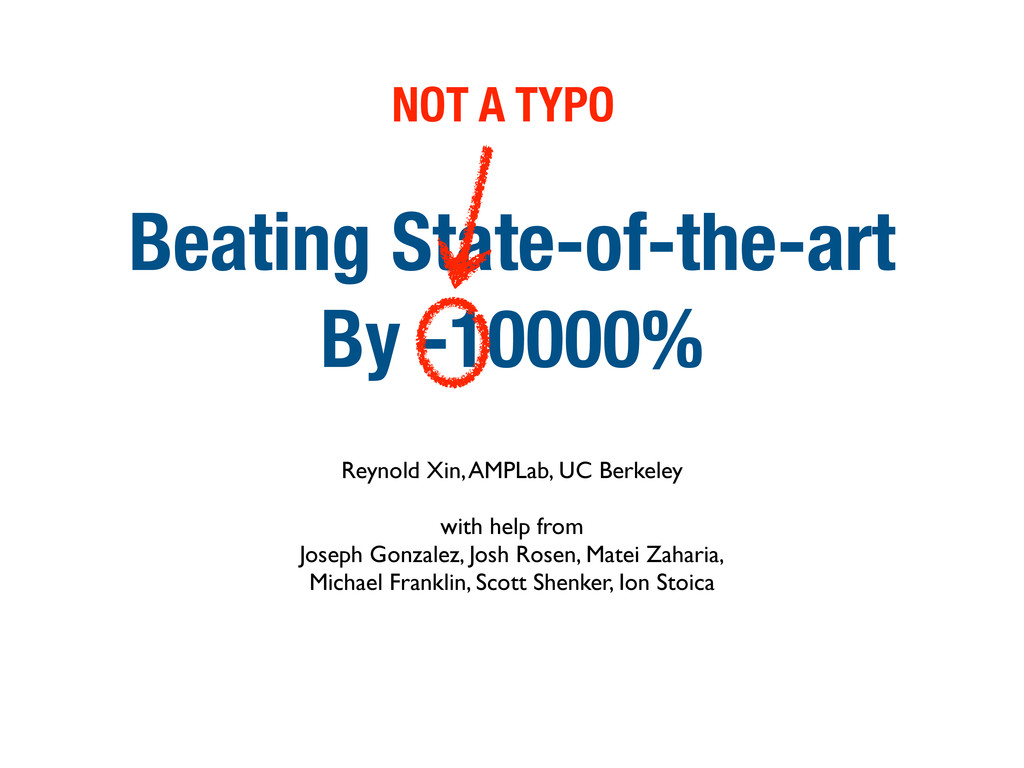
Beating State-of-the-art By -10000% Reynold Xin, AMPLab, UC Berkeley with
help from Joseph Gonzalez, Josh Rosen, Matei Zaharia, Michael Franklin, Scott Shenker, Ion Stoica
Beating State-of-the-art By -10000% NOT A TYPO Reynold Xin, AMPLab,
UC Berkeley with help from Joseph Gonzalez, Josh Rosen, Matei Zaharia, Michael Franklin, Scott Shenker, Ion Stoica
MapReduce deterministic, idempotent tasks fault-tolerance elasticity resource sharing
“The bar for open source software is at historical low.”
“The bar for open source software is at historical low.”
i.e. “This is the right time to do grad school.”
iterative machine learning OLAP strong temporal locality
Does in-memory computation help in petabyte-scale warehouses?
Does in-memory computation help in petabyte-scale warehouses? YES
Spark How to do in-memory computation efficiently in a fault-tolerant
way?
Shark How to do SQL query processing efficiently in “MapReduce”
style SQL on top of Spark Hive compatible (UDF, Type, InputFormat, Metadata)
“You need to beat Hadoop by at least 100X to
publish a paper in 2013.”
“You need to beat Hadoop by at least 100X to
publish a paper in 2013.” i.e. “You should’ve come to grad school 2 years earlier.”
Shark in-memory columnar store dynamic query re-optimization and a lot
of engineering...
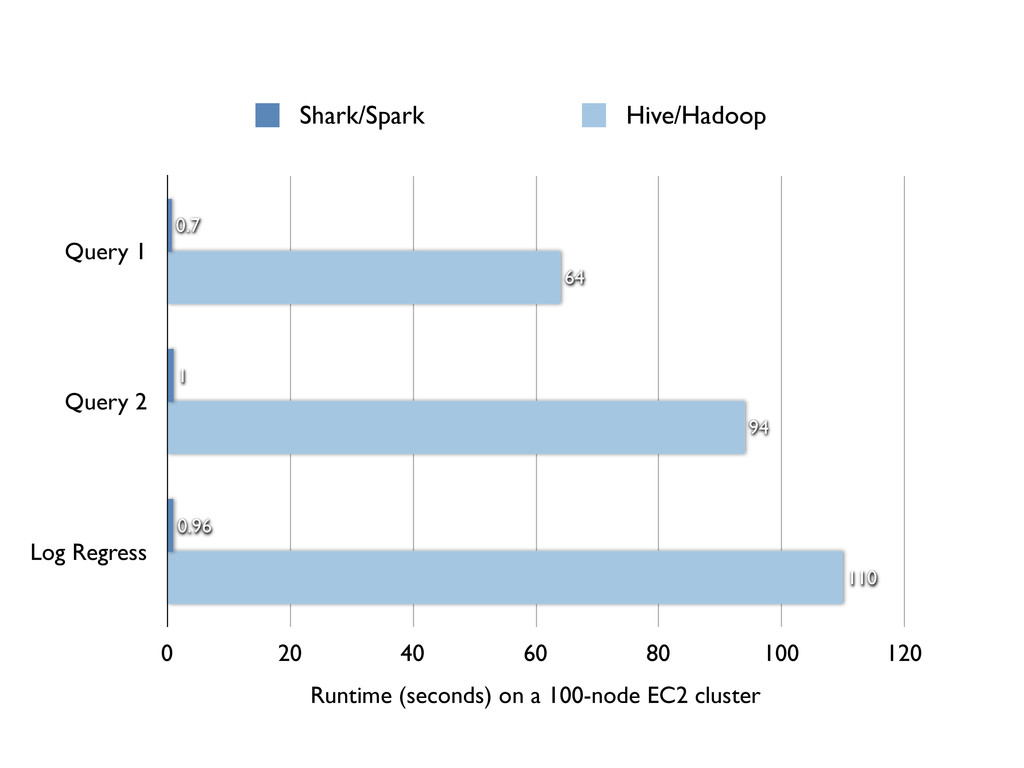
Query 1 Query 2 Log Regress 0 20 40 60
80 100 120 110 94 64 0.96 1 0.7 Runtime (seconds) on a 100-node EC2 cluster Shark/Spark Hive/Hadoop
iterative machine learning SQL query processing
iterative machine learning SQL query processing graph computation
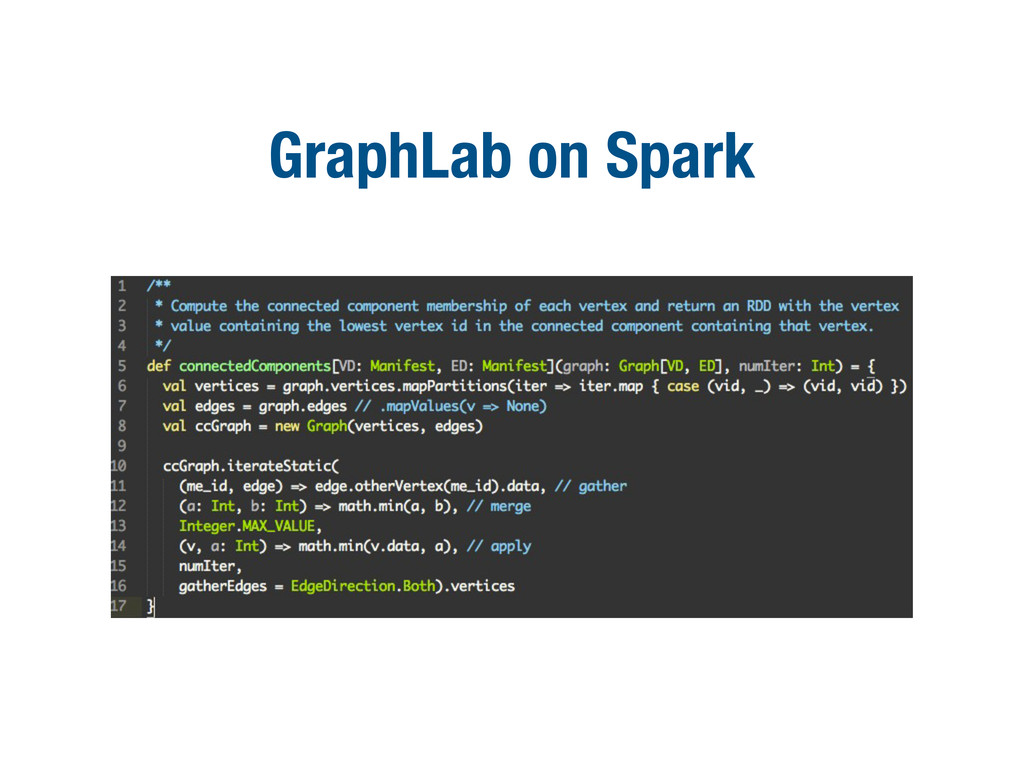
GraphLab on Spark
I spent a day pair-programming with Joey Gonzalez and improved
performance by 10X. Not bad for a day of work!
I spent a day pair-programming with Joey Gonzalez and improved
performance by 10X. but I later found out that it is still 10X slower than the latest version of GraphLab :(
A lot of open questions for fault- tolerant, distributed graph
computation. “MapReduce”? Data partitioning? Fault-tolerance? Asynchrony?
iterative machine learning www.spark-project.org SQL query processing shark.cs.berkeley.edu graph computation
www.wait-another-year.com


 rxin
 institutdelelevage
 sazimai
 takasehideki
 monochromegane
 koheishinden
 tkng
 de9uch1
 matsumooon
 sishi2026
 signer
 addyosmani
 maggiecrowley
 letsgokoyo
 3n
 mfonobong
 michaelherold
 tammyeverts
 pwiseman
 paigeccino
 aemeredith
 stephaniewalter
 lara