Share
Embed
Machine Learning on Spark @ Strata Conference
Talk by Shivaram Venkataraman
Reynold Xin
February 26, 2013
Transcript
34 slides
-
Implementing Machine Learning § Machine learning algorithms are - Complex, multi-stage
- Iterative § MapReduce/Hadoop unsuitable § Need efficient primitives for data sharing -
§ Spark RDDs à efficient data sharing § In-memory caching
accelerates performance - Up to 20x faster than Hadoop § Easy to use high-level programming interface - Express complex algorithms ~100 lines. Machine Learning using Spark -
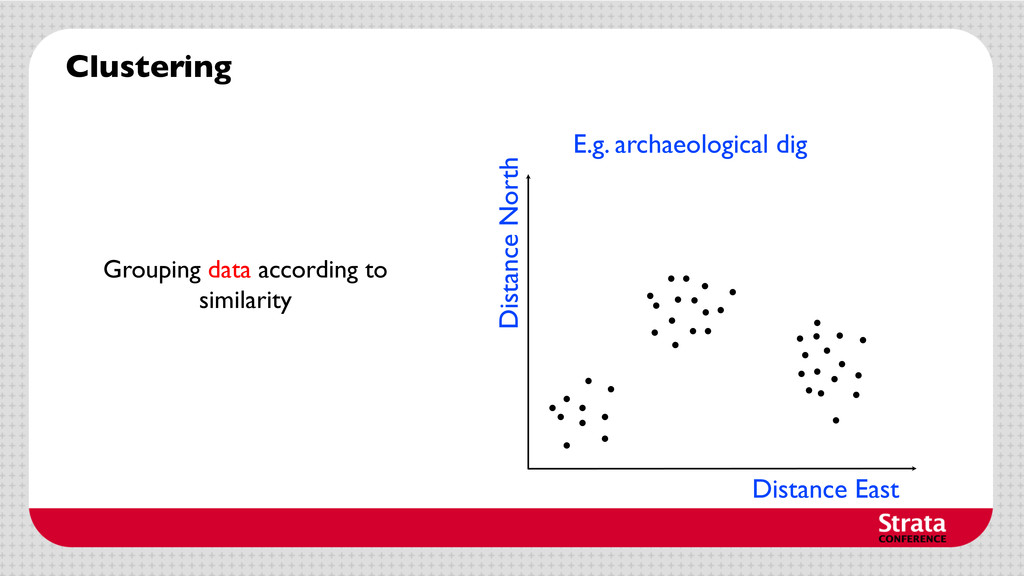
Clustering Grouping data according to similarity Distance East Distance North
E.g. archaeological dig -
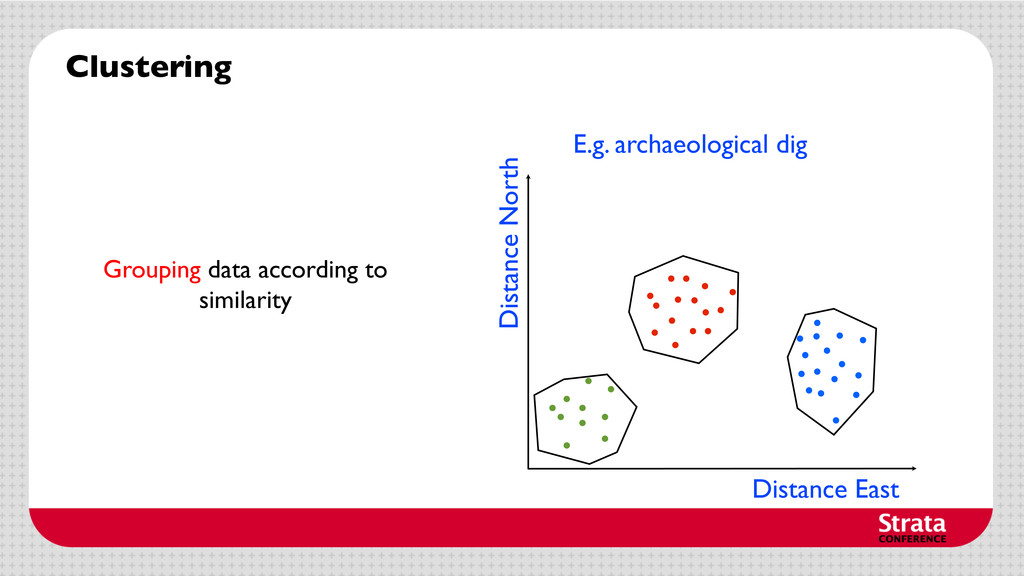
Clustering Grouping data according to similarity Distance East Distance North
E.g. archaeological dig -
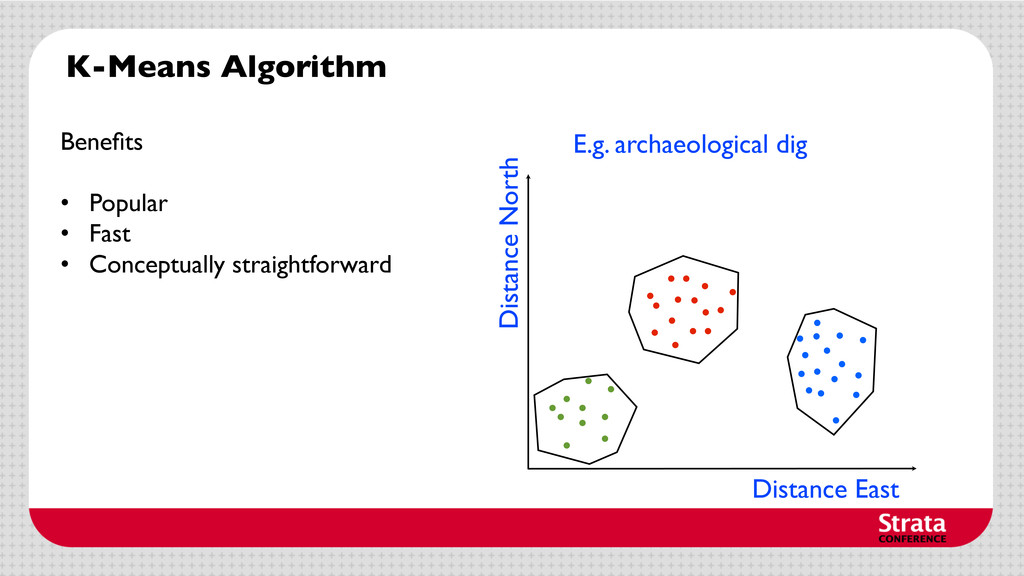
K-Means Algorithm Benefits • Popular • Fast • Conceptually straightforward
Distance East Distance North E.g. archaeological dig -
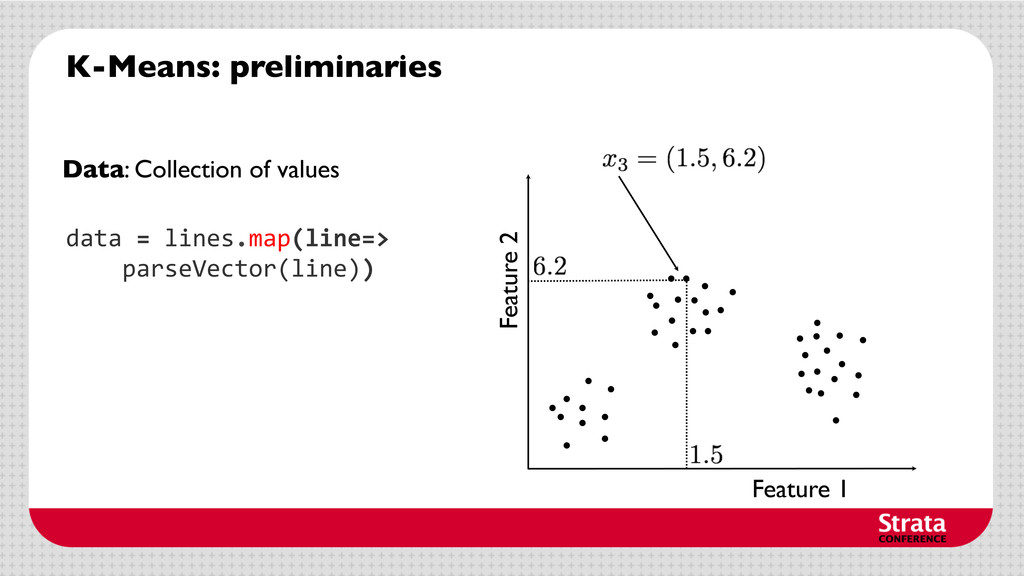
K-Means: preliminaries Feature 1 Feature 2 Data: Collection of values
data = lines.map(line=> parseVector(line)) -
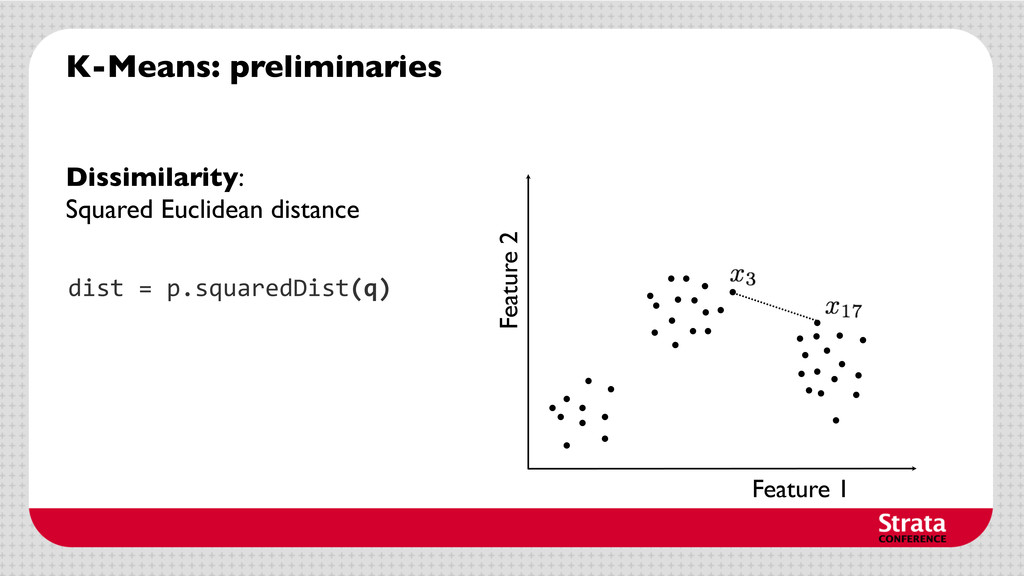
K-Means: preliminaries Feature 1 Feature 2 Dissimilarity: Squared Euclidean distance
dist = p.squaredDist(q) -
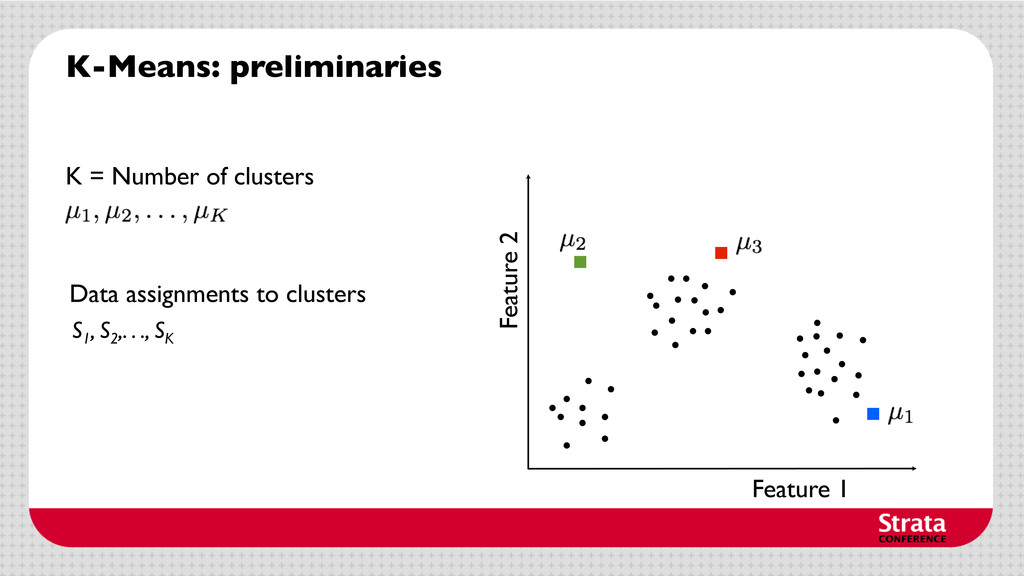
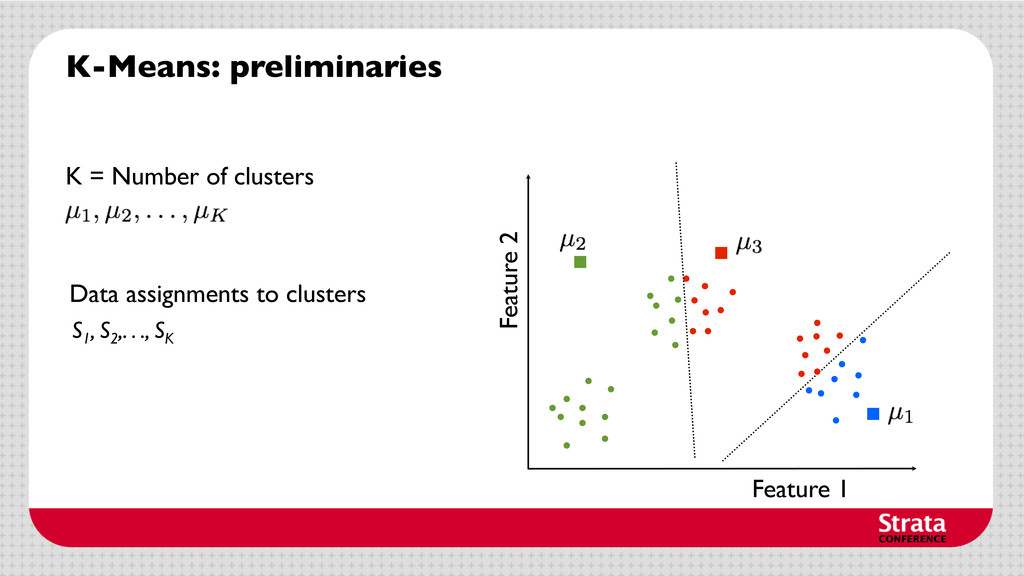
K-Means: preliminaries Feature 1 Feature 2 K = Number of
clusters Data assignments to clusters S1 , S2 ,. . ., SK -
K-Means: preliminaries Feature 1 Feature 2 K = Number of
clusters Data assignments to clusters S1 , S2 ,. . ., SK -
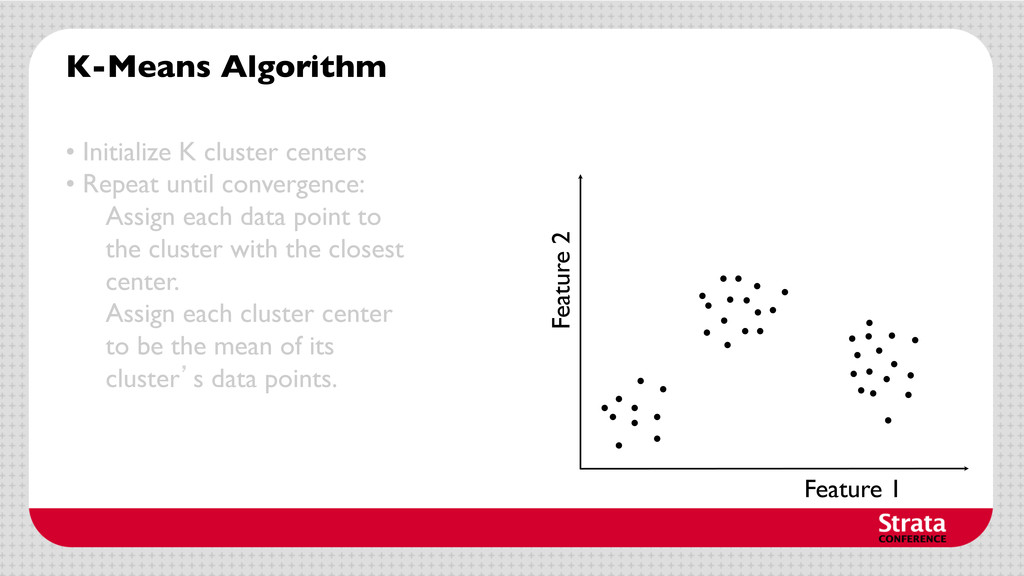
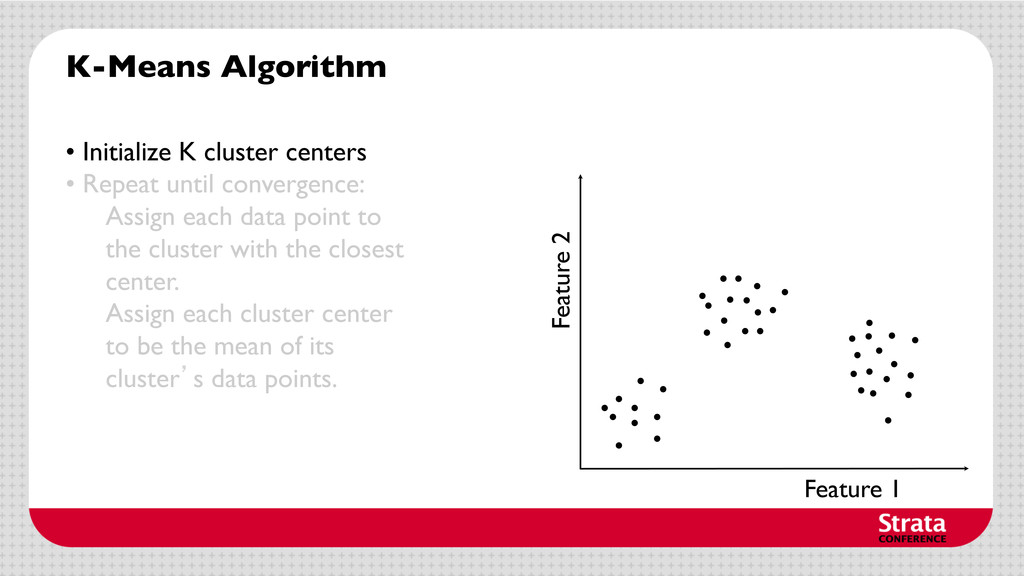
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: Assign each data point to the cluster with the closest center. Assign each cluster center to be the mean of its cluster’s data points. -
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: Assign each data point to the cluster with the closest center. Assign each cluster center to be the mean of its cluster’s data points. -
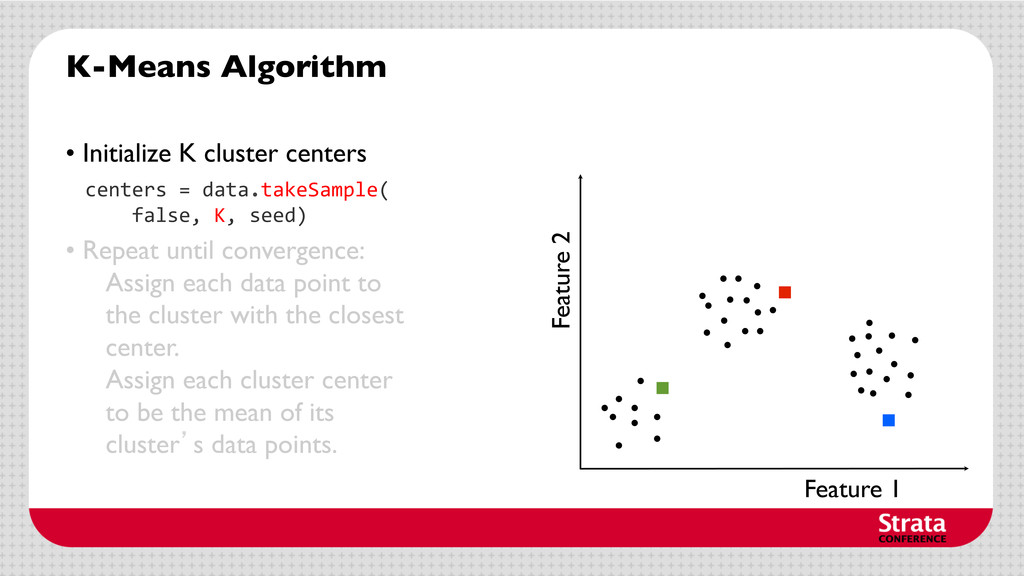
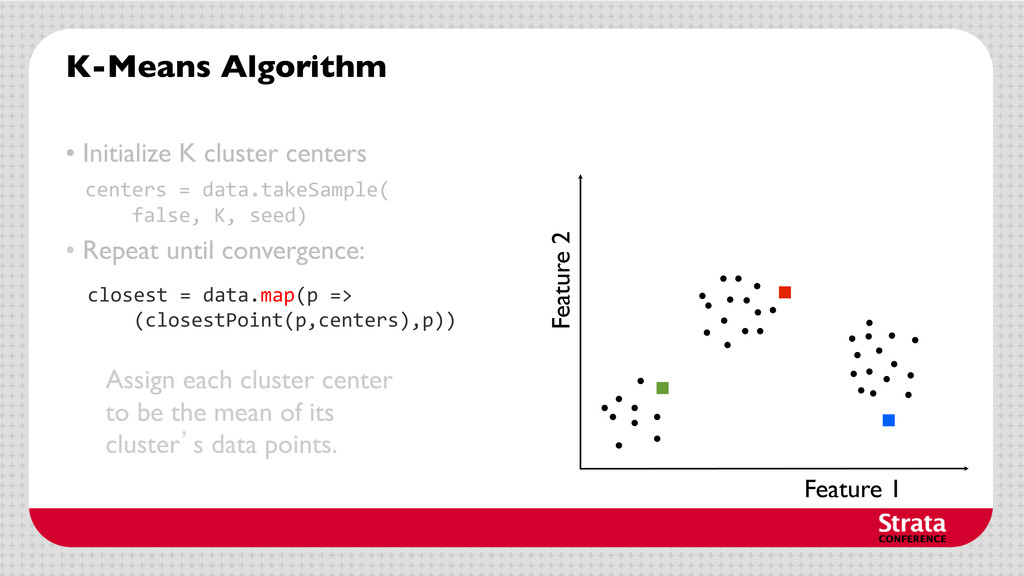
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: Assign each data point to the cluster with the closest center. Assign each cluster center to be the mean of its cluster’s data points. centers = data.takeSample( false, K, seed) -
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: Assign each data point to the cluster with the closest center. Assign each cluster center to be the mean of its cluster’s data points. centers = data.takeSample( false, K, seed) -
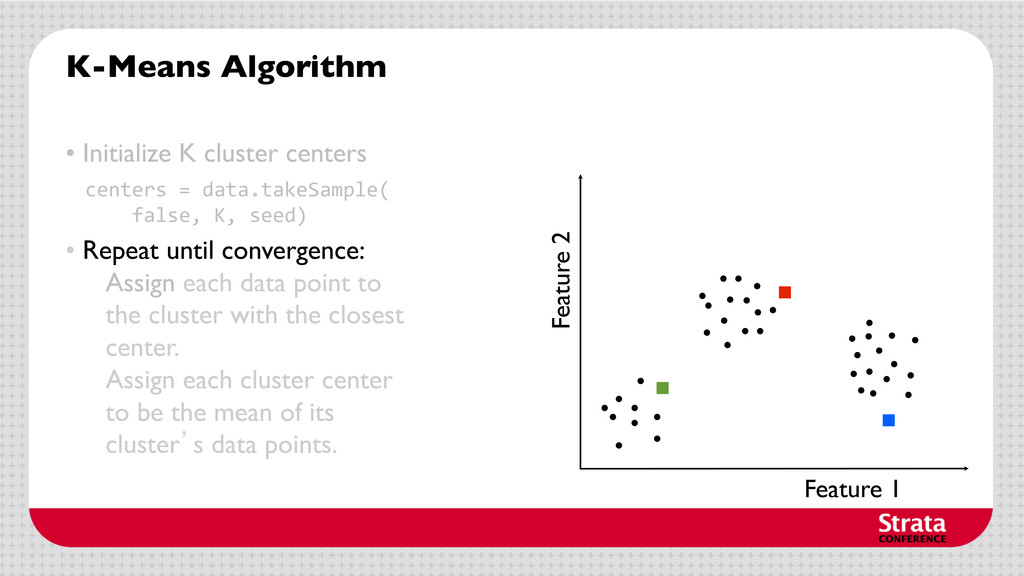
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: Assign each data point to the cluster with the closest center. Assign each cluster center to be the mean of its cluster’s data points. centers = data.takeSample( false, K, seed) -
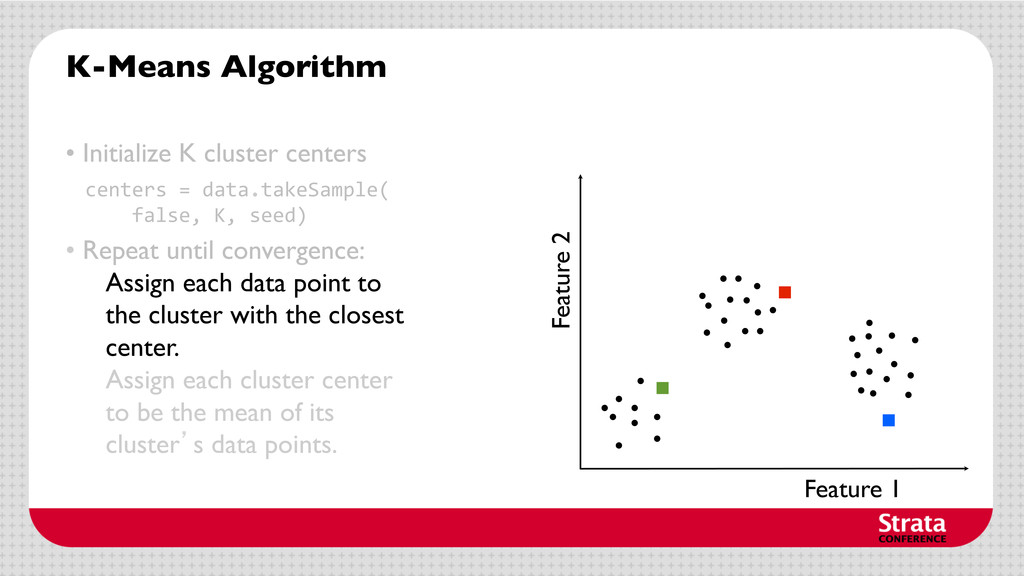
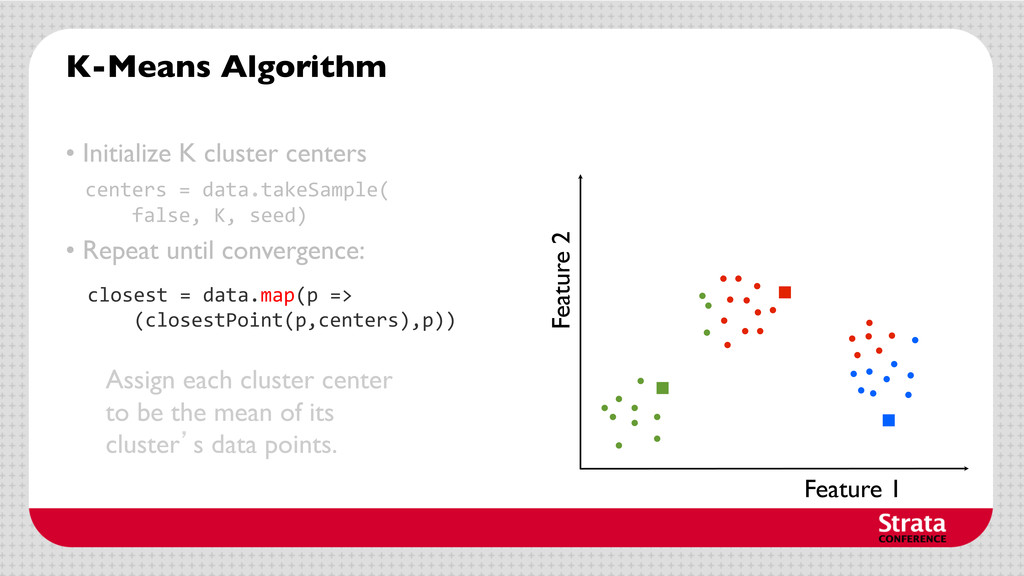
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: Assign each cluster center to be the mean of its cluster’s data points. centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) -
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: Assign each cluster center to be the mean of its cluster’s data points. centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) -
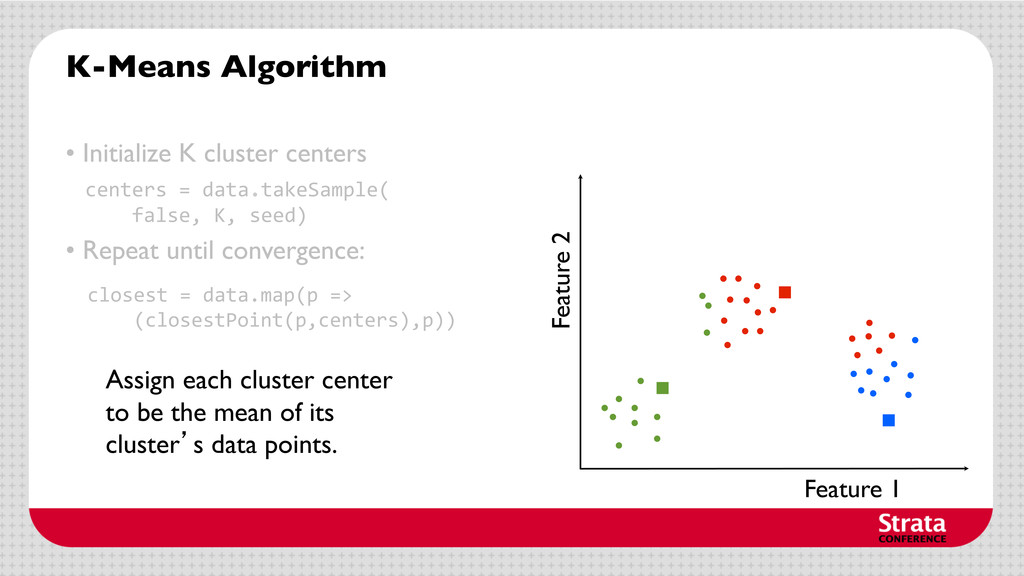
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: Assign each cluster center to be the mean of its cluster’s data points. centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) -
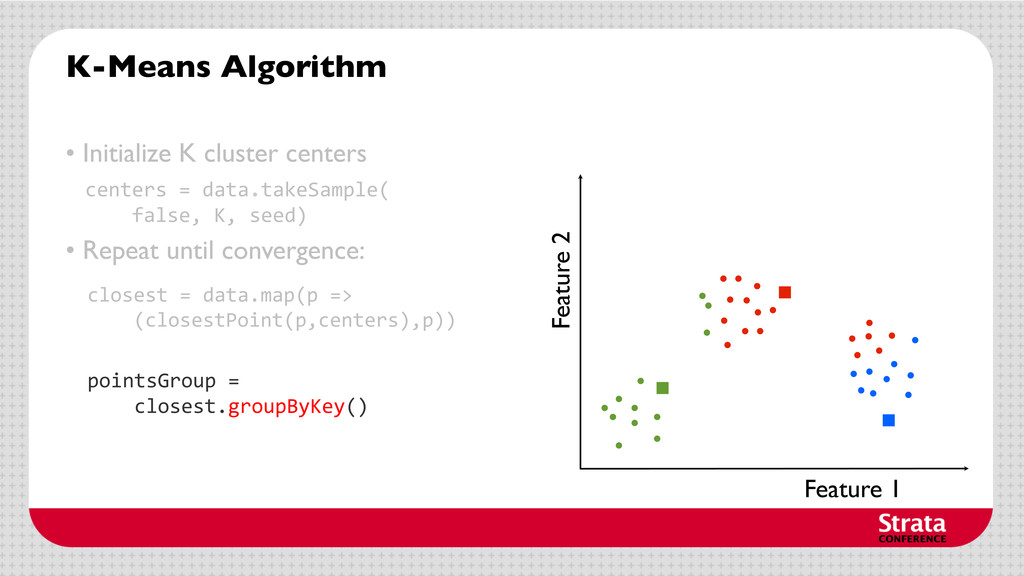
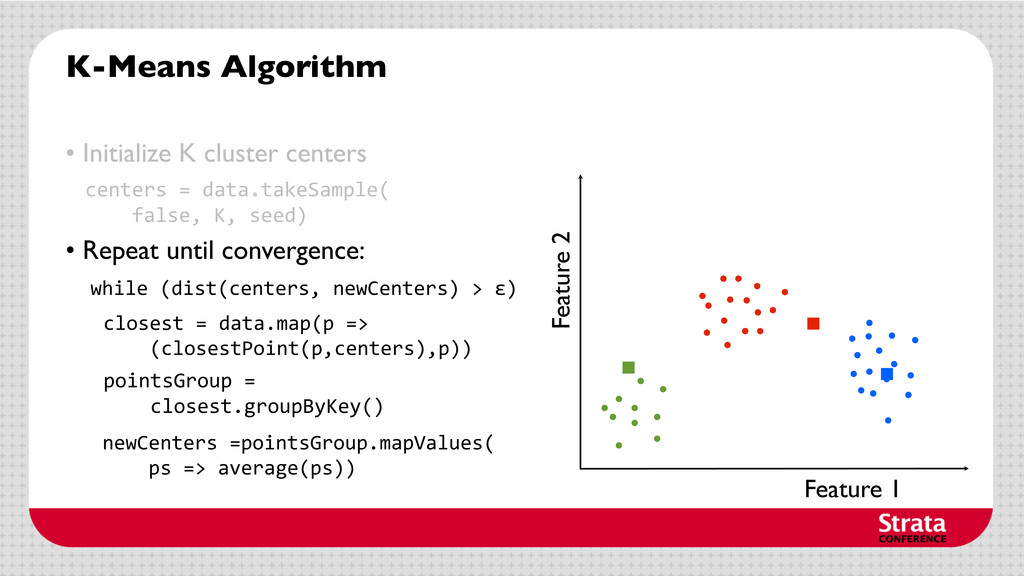
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
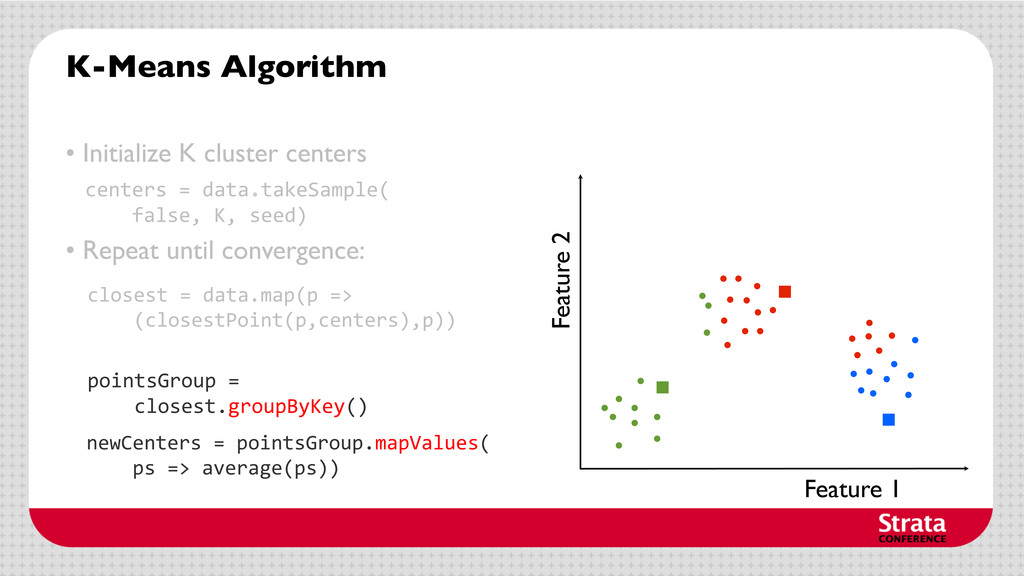
centers • Repeat until convergence: centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) pointsGroup = closest.groupByKey() -
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
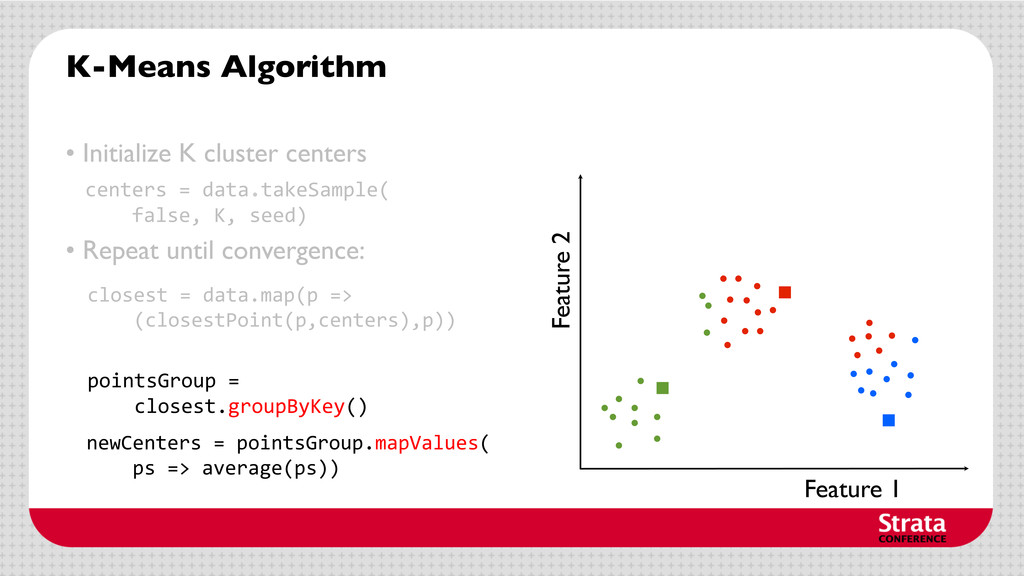
centers • Repeat until convergence: centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) pointsGroup = closest.groupByKey() newCenters = pointsGroup.mapValues( ps => average(ps)) -
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
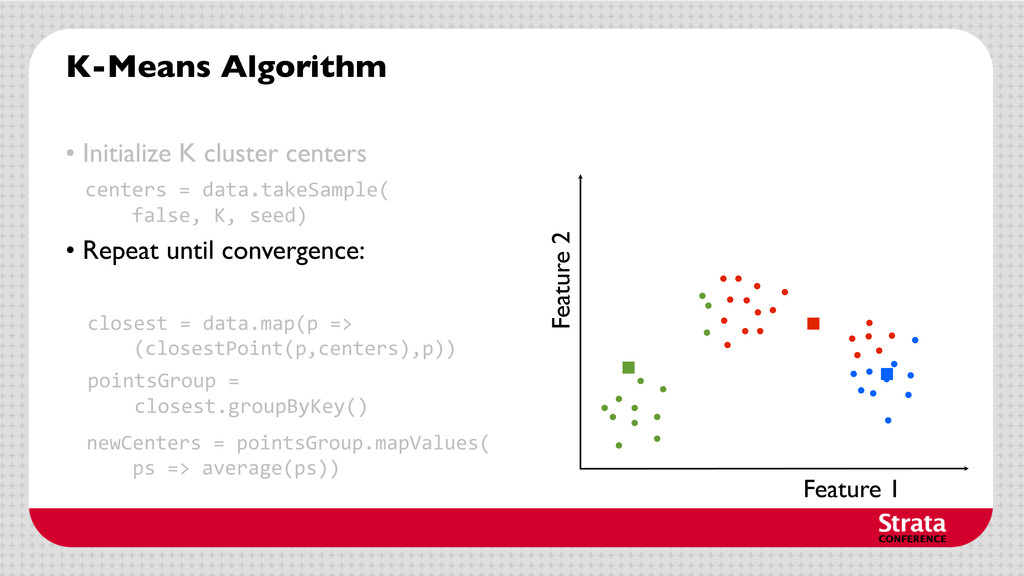
centers • Repeat until convergence: centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) pointsGroup = closest.groupByKey() newCenters = pointsGroup.mapValues( ps => average(ps)) -
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) pointsGroup = closest.groupByKey() newCenters = pointsGroup.mapValues( ps => average(ps)) -
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
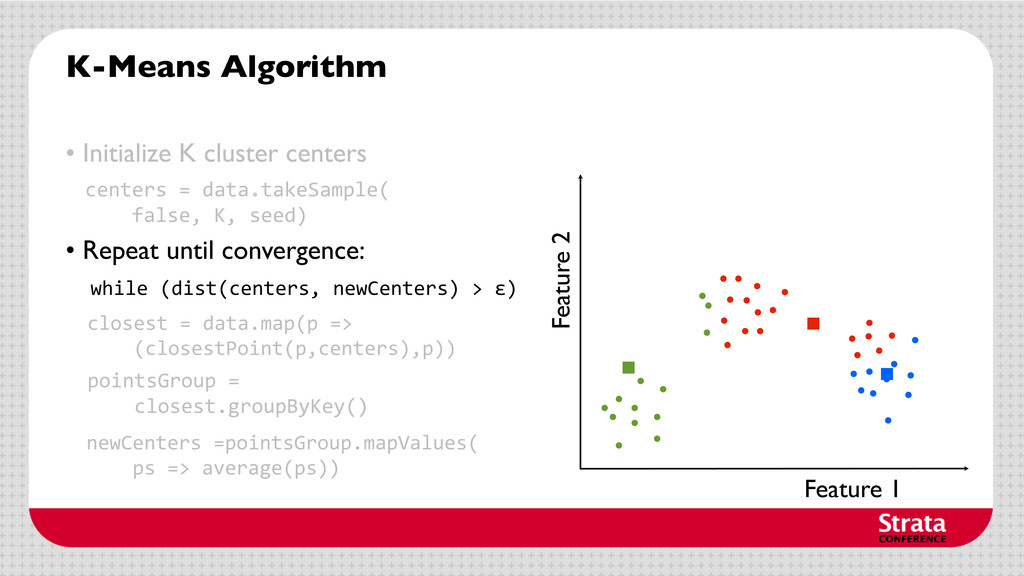
centers • Repeat until convergence: centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) pointsGroup = closest.groupByKey() newCenters =pointsGroup.mapValues( ps => average(ps)) while (dist(centers, newCenters) > ɛ) -
K-Means Algorithm Feature 1 Feature 2 • Initialize K cluster
centers • Repeat until convergence: centers = data.takeSample( false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) pointsGroup = closest.groupByKey() newCenters =pointsGroup.mapValues( ps => average(ps)) while (dist(centers, newCenters) > ɛ) -
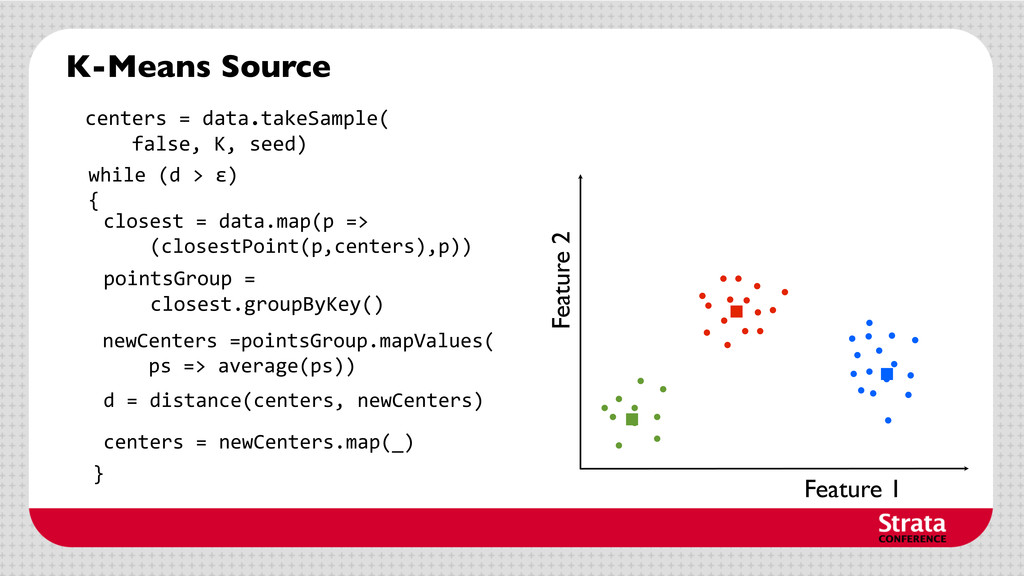
K-Means Source Feature 1 Feature 2 centers = data.takeSample(
false, K, seed) closest = data.map(p => (closestPoint(p,centers),p)) pointsGroup = closest.groupByKey() newCenters =pointsGroup.mapValues( ps => average(ps)) while (d > ɛ) { } d = distance(centers, newCenters) centers = newCenters.map(_) -
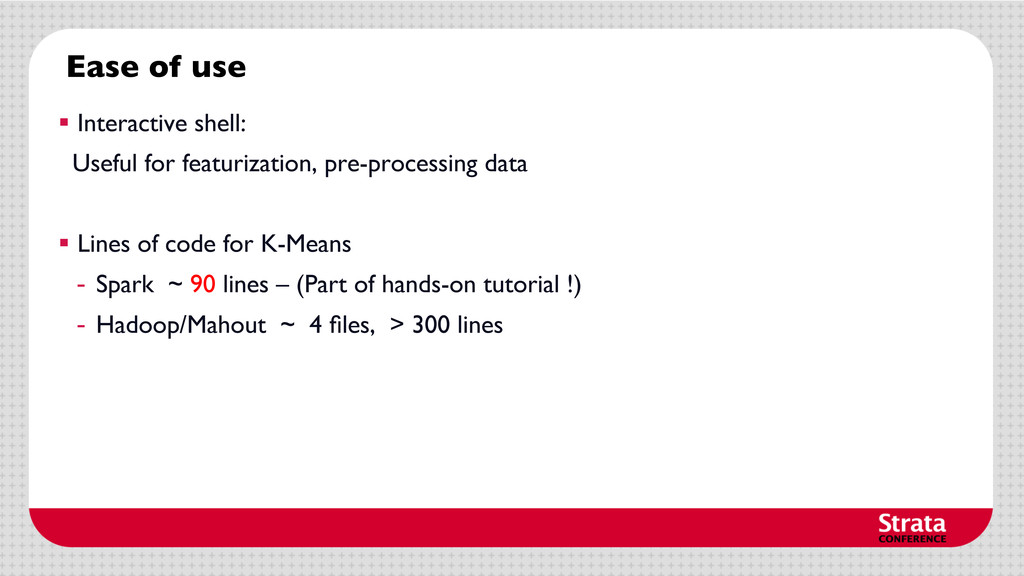
Ease of use § Interactive shell: Useful for featurization, pre-processing
data § Lines of code for K-Means - Spark ~ 90 lines – (Part of hands-on tutorial !) - Hadoop/Mahout ~ 4 files, > 300 lines -
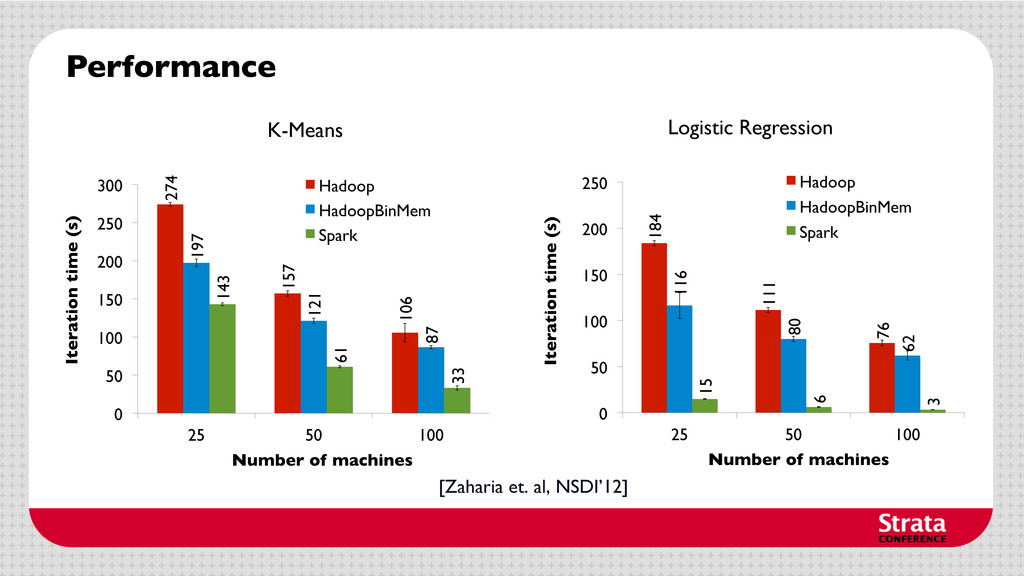
274 157 106 197 121 87 143 61 33 0
50 100 150 200 250 300 25 50 100 Iteration time (s) Number of machines Hadoop HadoopBinMem Spark K-Means 184 111 76 116 80 62 15 6 3 0 50 100 150 200 250 25 50 100 Iteration time (s) Number of machines Hadoop HadoopBinMem Spark Logistic Regression Performance [Zaharia et. al, NSDI’12] -
§ K means clustering using Spark § Hands-on exercise this
afternoon ! Examples and more: www.spark-project.org § Spark: Framework for cluster computing § Fast and easy machine learning programs Conclusion