Share
Embed
Overview of RNA-Sequencing and Its Applications
Literature seminar at the Babraham Institute, Cambridge, UK
Vladimir Kiselev
July 02, 2014
Transcript
21 slides
-
Overview of RNA-‐Sequencing and its applica:ons Vladimir Kiselev
Literature seminar 3rd July 2014 -
Introduc:on to RNA sequencing • Appearance ~2008 (first 5
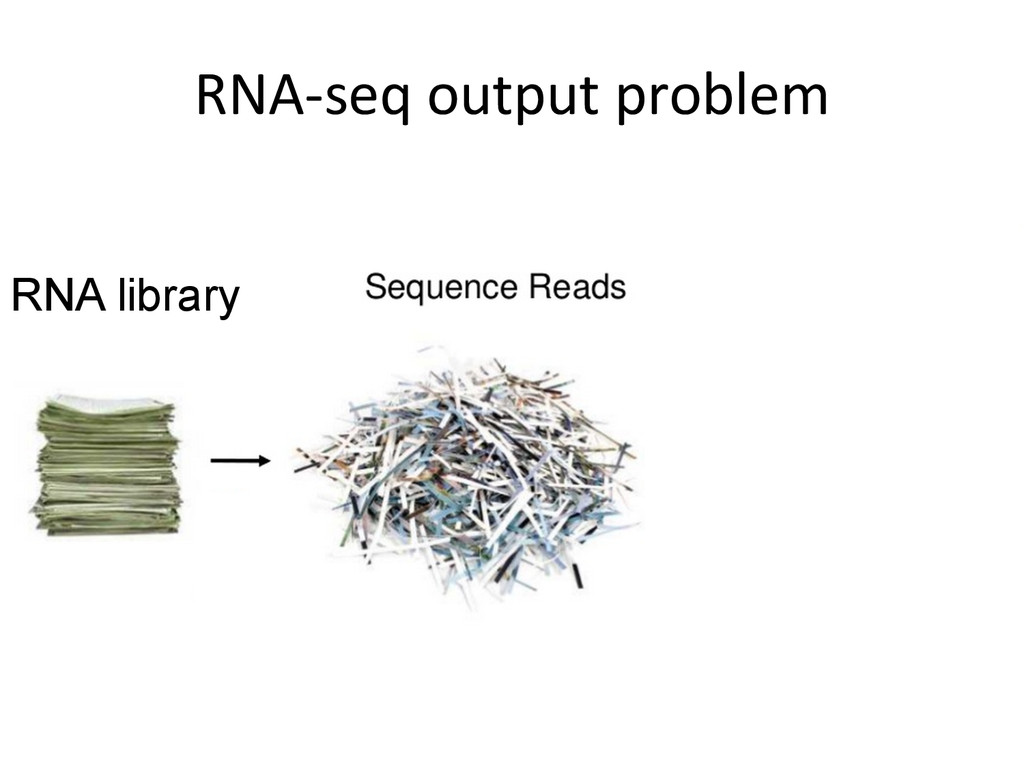
papers) with the introduc:on of next-‐genera:on sequencers • Allowed to analyze en:re gene expression programs • In principle, any high-‐ throughput sequencing technology can be used • Bioinforma:cs tools for RNA-‐seq ~2009 (e.g. TopHat) -
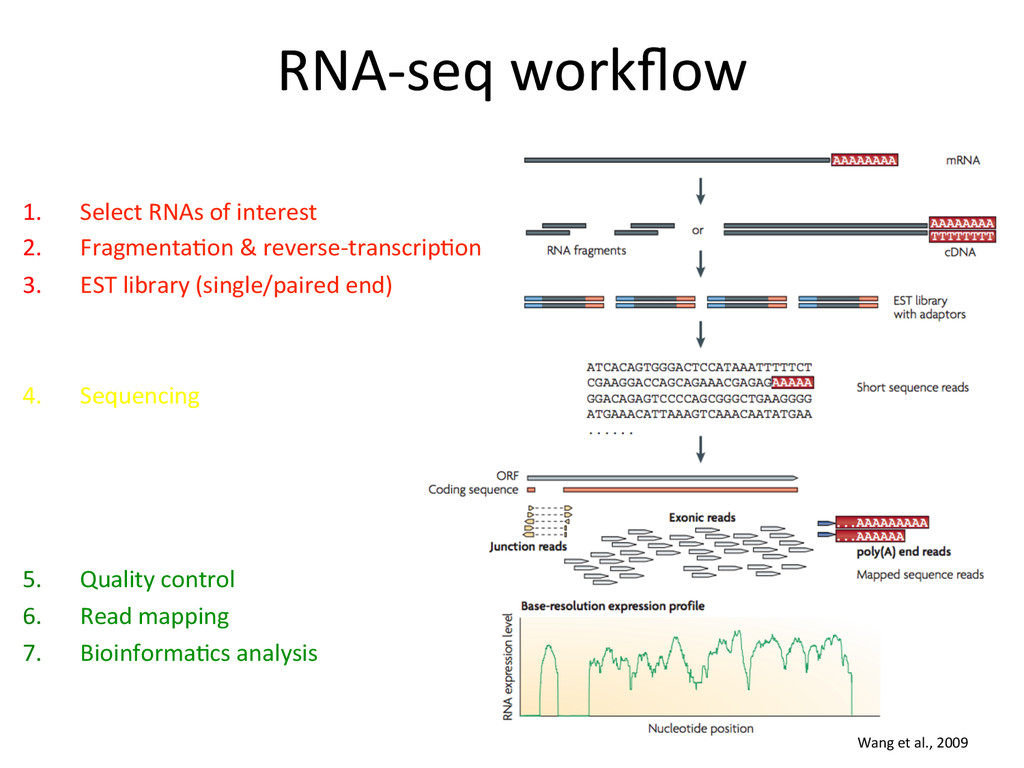
RNA-‐seq workflow 1. Select RNAs of interest 2.
Fragmenta:on & reverse-‐transcrip:on 3. EST library (single/paired end) 4. Sequencing 5. Quality control 6. Read mapping 7. Bioinforma:cs analysis Wang et al., 2009 -
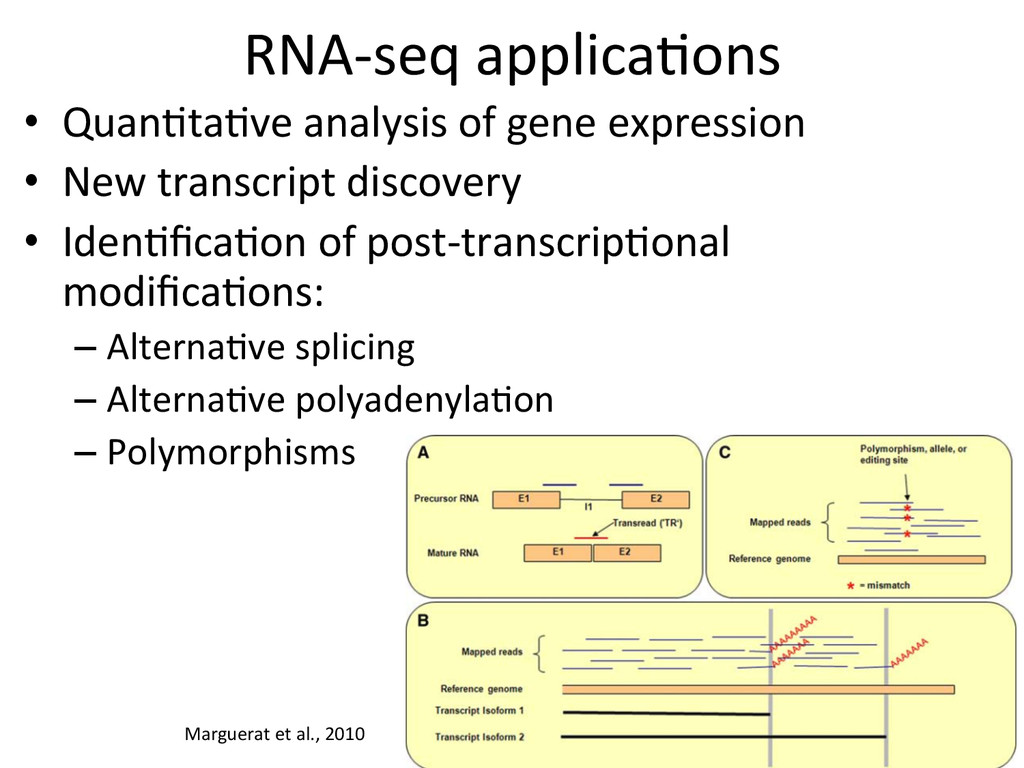
RNA-‐seq applica:ons • Quan:ta:ve analysis of gene expression
• New transcript discovery • Iden:fica:on of post-‐transcrip:onal modifica:ons: – Alterna:ve splicing – Alterna:ve polyadenyla:on – Polymorphisms Marguerat et al., 2010 -
RNA-‐seq: read quality control (QC) • First step of
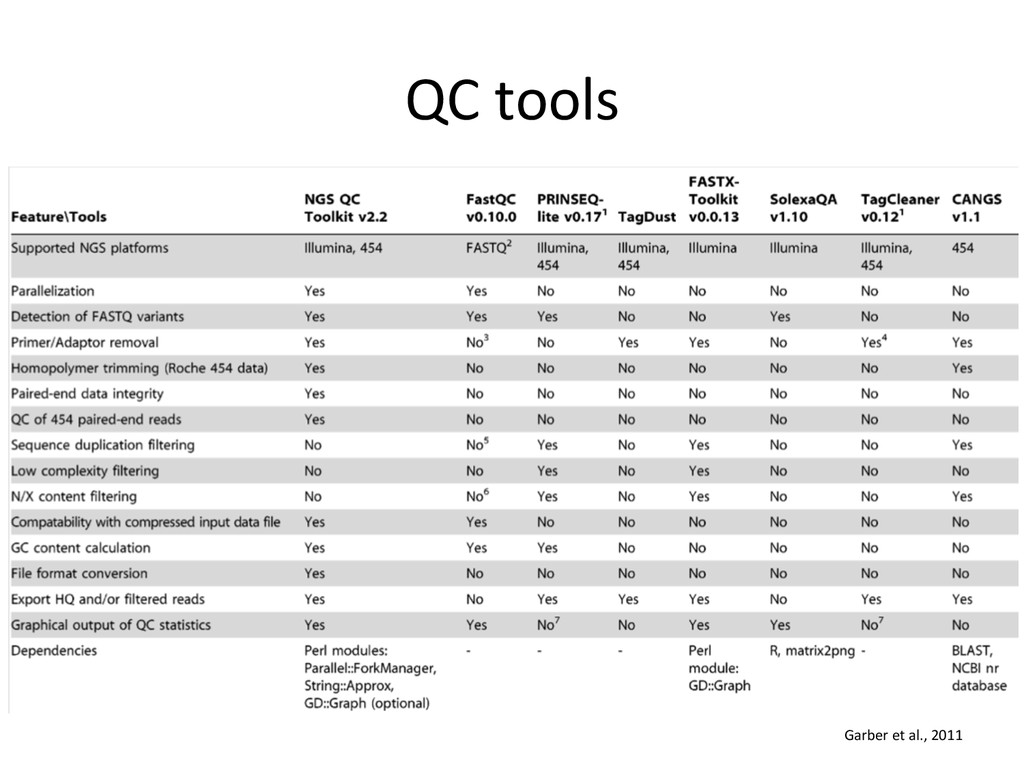
Bioinforma:cs analysis • Data filtering: – low quality sequences/bases – overrepresented sequences – noise • Numerous automa:c tools -
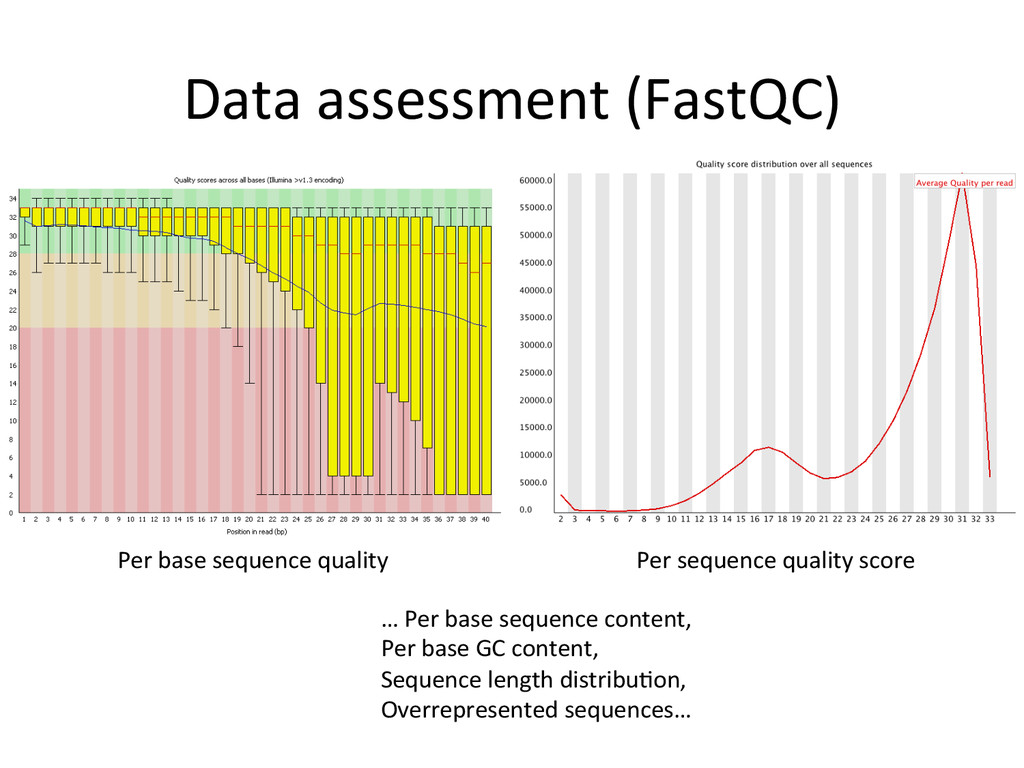
Data assessment (FastQC) Per base sequence quality Per
sequence quality score … Per base sequence content, Per base GC content, Sequence length distribu:on, Overrepresented sequences… -
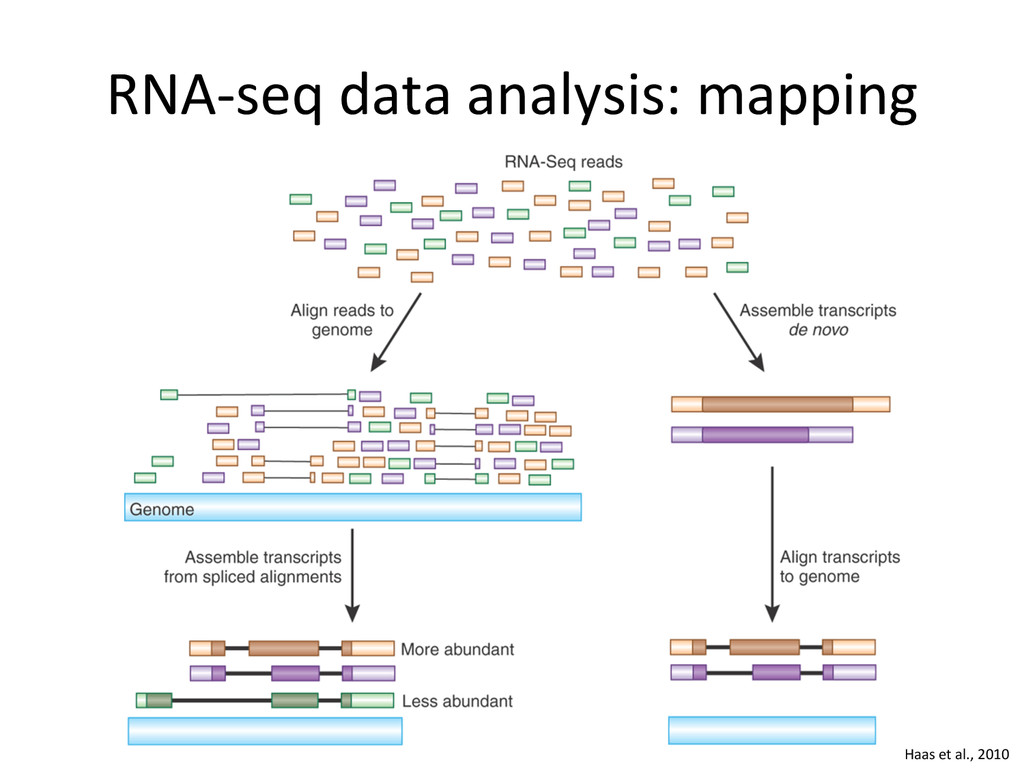
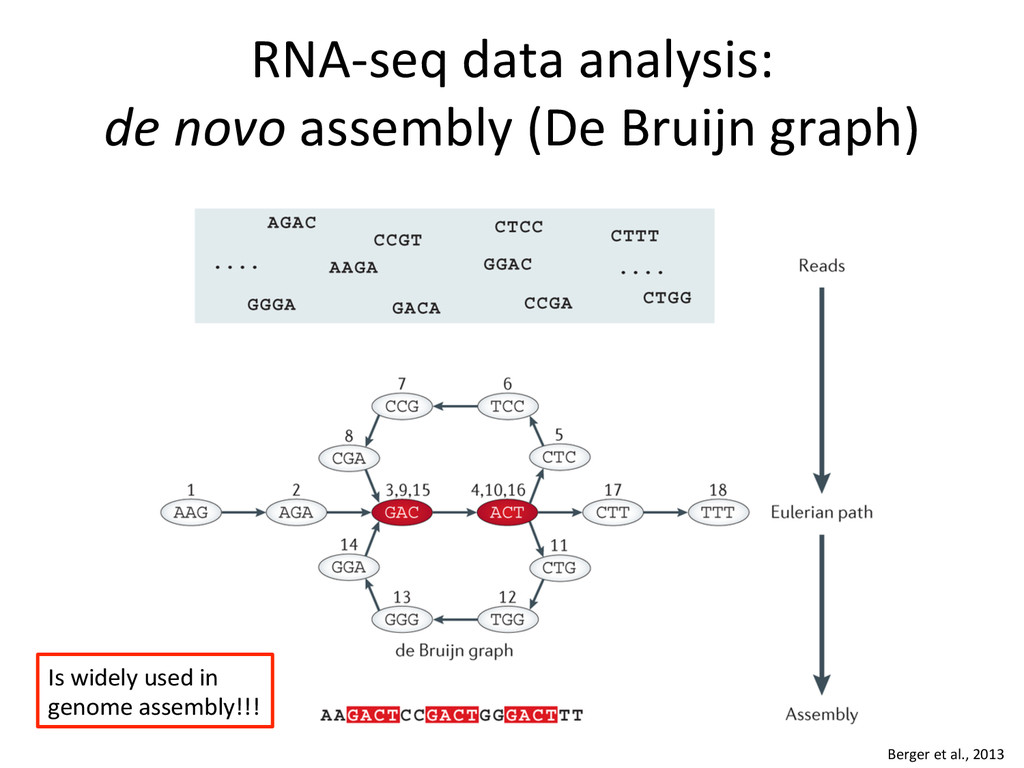
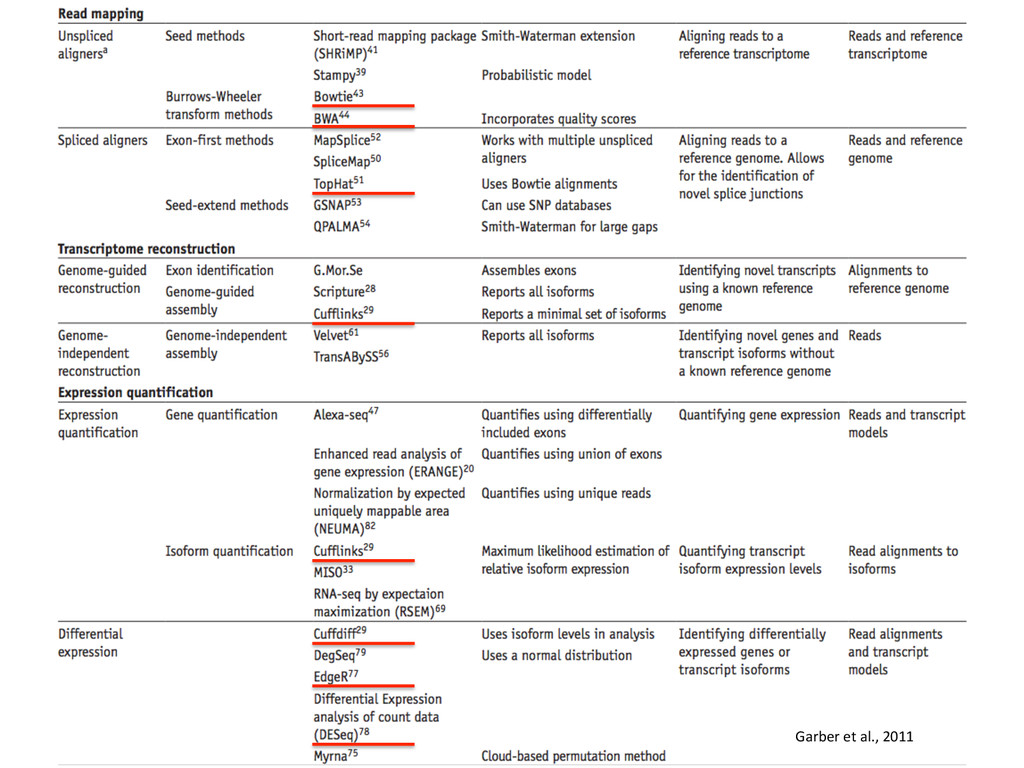
RNA-‐seq data analysis: mapping Three strategies: 1. De
novo assembly (De Bruijn graphs) – Genome unknown or of poor quality 2. Genome alignment – Genome available – Transcriptome unknown or of poor quality – Allows finding new splice junc:ons, polya cleavage sites, etc. 3. Transcriptome alignment – Genome available – Comprehensive transcriptome available -
RNA-‐seq data analysis: de novo assembly (De Bruijn graph)
Berger et al., 2013 Is widely used in genome assembly!!! -
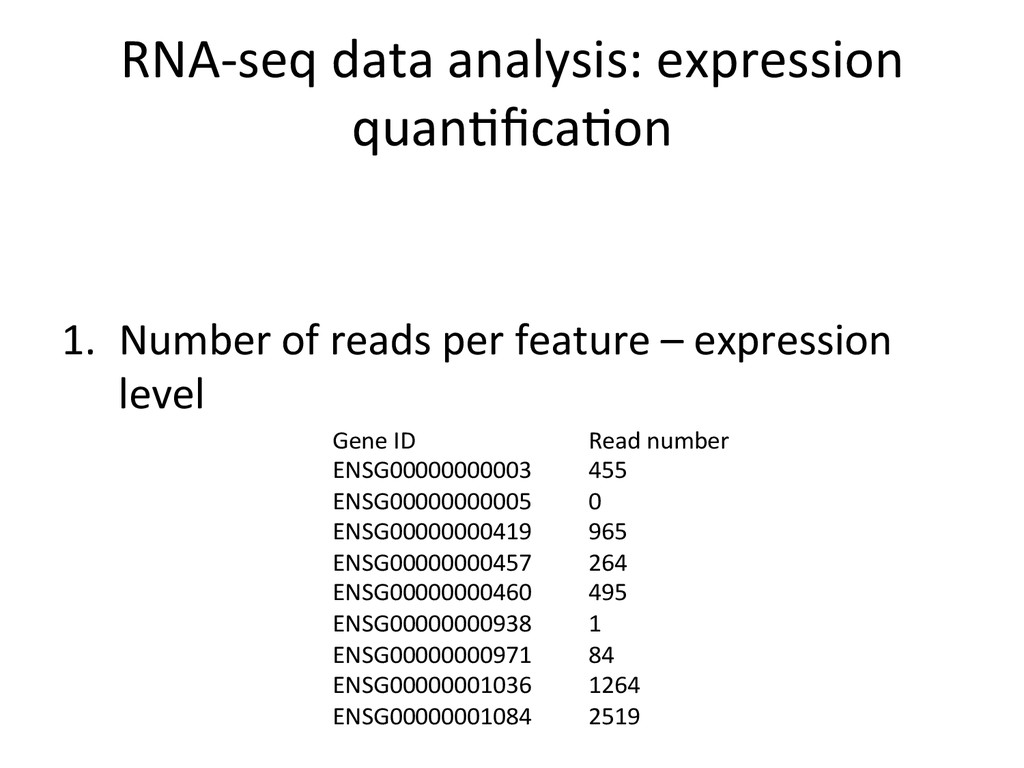
RNA-‐seq data analysis: expression quan:fica:on 1. Number of
reads per feature – expression level Gene ID Read number ENSG00000000003 455 ENSG00000000005 0 ENSG00000000419 965 ENSG00000000457 264 ENSG00000000460 495 ENSG00000000938 1 ENSG00000000971 84 ENSG00000001036 1264 ENSG00000001084 2519 -
RNA-‐seq data analysis: expression quan:fica:on 1. Number of
reads per feature – expression level 2. Comparison of read numbers per feature at different condi:ons – differen:al expression: – Numerous sta:s:cal approaches -
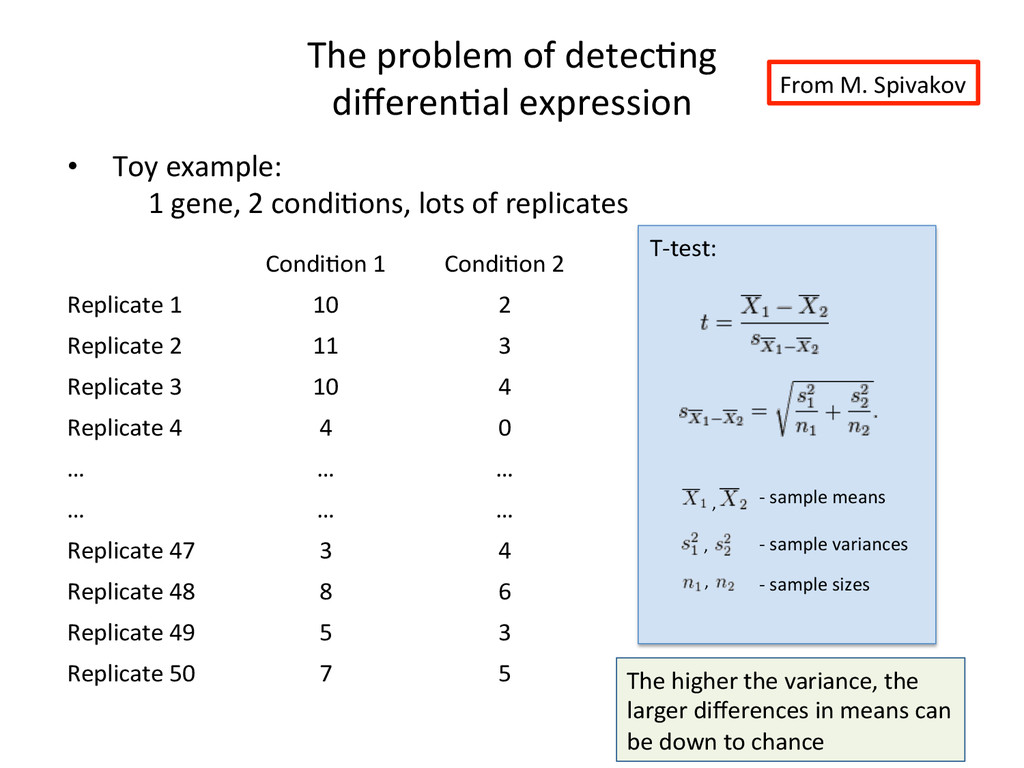
The problem of detec:ng differen:al expression •
Toy example: 1 gene, 2 condi:ons, lots of replicates T-‐test: , , -‐ sample variances -‐ sample means , -‐ sample sizes Condi:on 1 Condi:on 2 Replicate 1 10 2 Replicate 2 11 3 Replicate 3 10 4 Replicate 4 4 0 … … … … … … Replicate 47 3 4 Replicate 48 8 6 Replicate 49 5 3 Replicate 50 7 5 The higher the variance, the larger differences in means can be down to chance From M. Spivakov -
The problem of detec:ng differen:al expression •
Toy example: 1 gene, 2 condi:ons, lots of replicates • When the number of replicates is very small: – Can’t robustly es:mate popula&on variance from sample variance – Can’t assume normal distribu:on for count data T-‐test: , , -‐ sample variances -‐ sample means , -‐ sample sizes The higher the variance, the larger differences in means can be down to chance This is why more sophis:cated tools are needed From M. Spivakov -
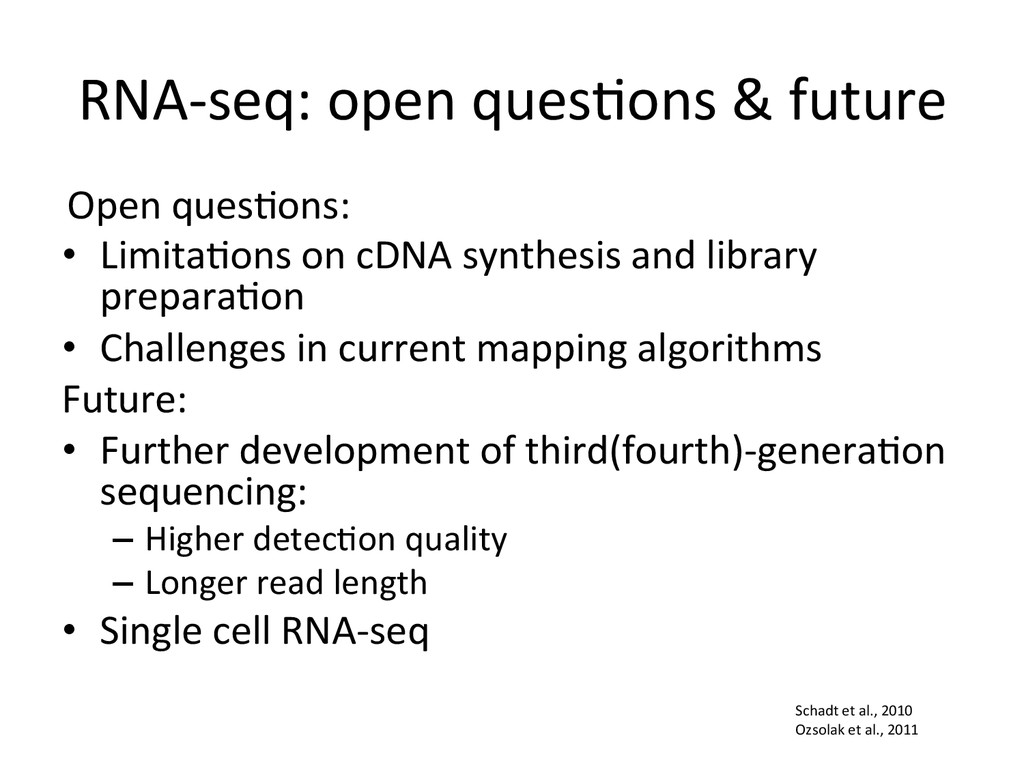
RNA-‐seq: open ques:ons & future Open ques:ons: •
Limita:ons on cDNA synthesis and library prepara:on • Challenges in current mapping algorithms Future: • Further development of third(fourth)-‐genera:on sequencing: – Higher detec:on quality – Longer read length • Single cell RNA-‐seq Schadt et al., 2010 Ozsolak et al., 2011