Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
論文読み会 / Deep Multi-Modal Sets
Search
chck
June 29, 2020
Research
46
0
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
論文読み会 / Deep Multi-Modal Sets
社内論文読み会、PaperFridayでの発表資料です
chck
June 29, 2020
More Decks by chck
See All by chck
Research Engineerという仕事 / Research Engineering: Bridging Research and Business
chck
1
380
CyberAgent AI Lab研修 / Social Implementation Anti-Patterns in AI Lab
chck
7
5.1k
CyberAgent AI Lab研修 / Container for Research
chck
1
2.4k
CyberAgent AI Lab研修 / Code Review in a Team
chck
3
2.6k
論文読み会 / Socio-Technical Anti-Patterns in Building ML-Enabled Software: Insights from Leaders on the Forefront
chck
0
170
CyberAgent AI事業本部MLOps研修Container編 / Container for MLOps
chck
3
6.3k
論文読み会 / GLAZE: Protecting Artists from Style Mimicry by Text-to-Image Models
chck
0
130
論文読み会 / On the Factory Floor: ML Engineering for Industrial-Scale Ads Recommendation Models
chck
0
96
論文読み会 / GUIGAN: Learning to Generate GUI Designs Using Generative Adversarial Networks
chck
0
86
Other Decks in Research
See All in Research
IA for theory
gpeyre
1
500
GeoAgent勉強会 論文紹介と強い推論モデルが与えるインパクト
satai
5
380
生成AIなんでも展示会vol6 LT登壇資料 NexteraBERT
rikkabotan7
0
190
Karkada さんの論文 × 2 の紹介: (1) Closed-Form Training Dynamics Reveal Learned Features and Linear Structure in Word2Vec-like Models, (2) Symmetry in language statistics shapes the geometry of model representations
eumesy
PRO
1
860
【中間報告】国会議員の立法・政策実務を支える環境を巡る現状と課題
polipoli
0
770
Evaluating LLM Reliability Across Facts, Evidence, and Cultures
yukiar
0
210
Développer des solutions de réduction des émissions de méthane entérique : 1ers résultats Méthane 2030
institutdelelevage
PRO
0
260
Vector Map as Language: Toward Unified Remote Sensing Vector Mapping
satai
3
320
[CV勉強会@関東 CVPR2026] PSDesigner: Automated Graphic Design with a Human-Like Creative Workflow / kantocv 67th CVPR 2026
shunk031
0
370
SAM3を用いたコマ・吹き出しの 領域検出と分割構造からの読み順推定
kzmssk
0
190
完全自律LLMエージェントでDIVER OSINT CTF 2026に挑戦してみた
analokmaus
0
780
論文紹介:Doc-to-LoRA: Learning to Instantly Internalize Contexts
yukako_nakano
0
200
Featured
See All Featured
Visualizing Your Data: Incorporating Mongo into Loggly Infrastructure
mongodb
50
10k
Side Projects
sachag
456
43k
Unlocking the hidden potential of vector embeddings in international SEO
frankvandijk
0
1k
The Mindset for Success: Future Career Progression
greggifford
PRO
0
540
Documentation Writing (for coders)
carmenintech
77
5.6k
What’s in a name? Adding method to the madness
productmarketing
PRO
24
4.2k
Chrome DevTools: State of the Union 2024 - Debugging React & Beyond
addyosmani
10
1.4k
How to build a perfect <img>
jonoalderson
1
6.1k
Into the Great Unknown - MozCon
thekraken
41
2.8k
Max Prin - Stacking Signals: How International SEO Comes Together (And Falls Apart)
techseoconnect
PRO
0
490
The untapped power of vector embeddings
frankvandijk
2
1.9k
The Organizational Zoo: Understanding Human Behavior Agility Through Metaphoric Constructive Conversations (based on the works of Arthur Shelley, Ph.D)
kimpetersen
PRO
0
500
Transcript
Deep Multi-Modal Sets 20/06/29 PaperFriday, Yuki Iwazaki@AI Lab
2 Point: 特徴のDown SamplingやScalabilityを考慮した Multi-Modal Encoderを提案 Authors: Austin Reiter, Menglin
Jia, Pu Yang, Ser-Nam Lim - Facebook AI Research, Cornell University 選定理由: - Creative Researchのslackでちょっと話題に出た - 俺より強いマルチモーダル表現に会いに行く
The Multi-Modal Problem 3
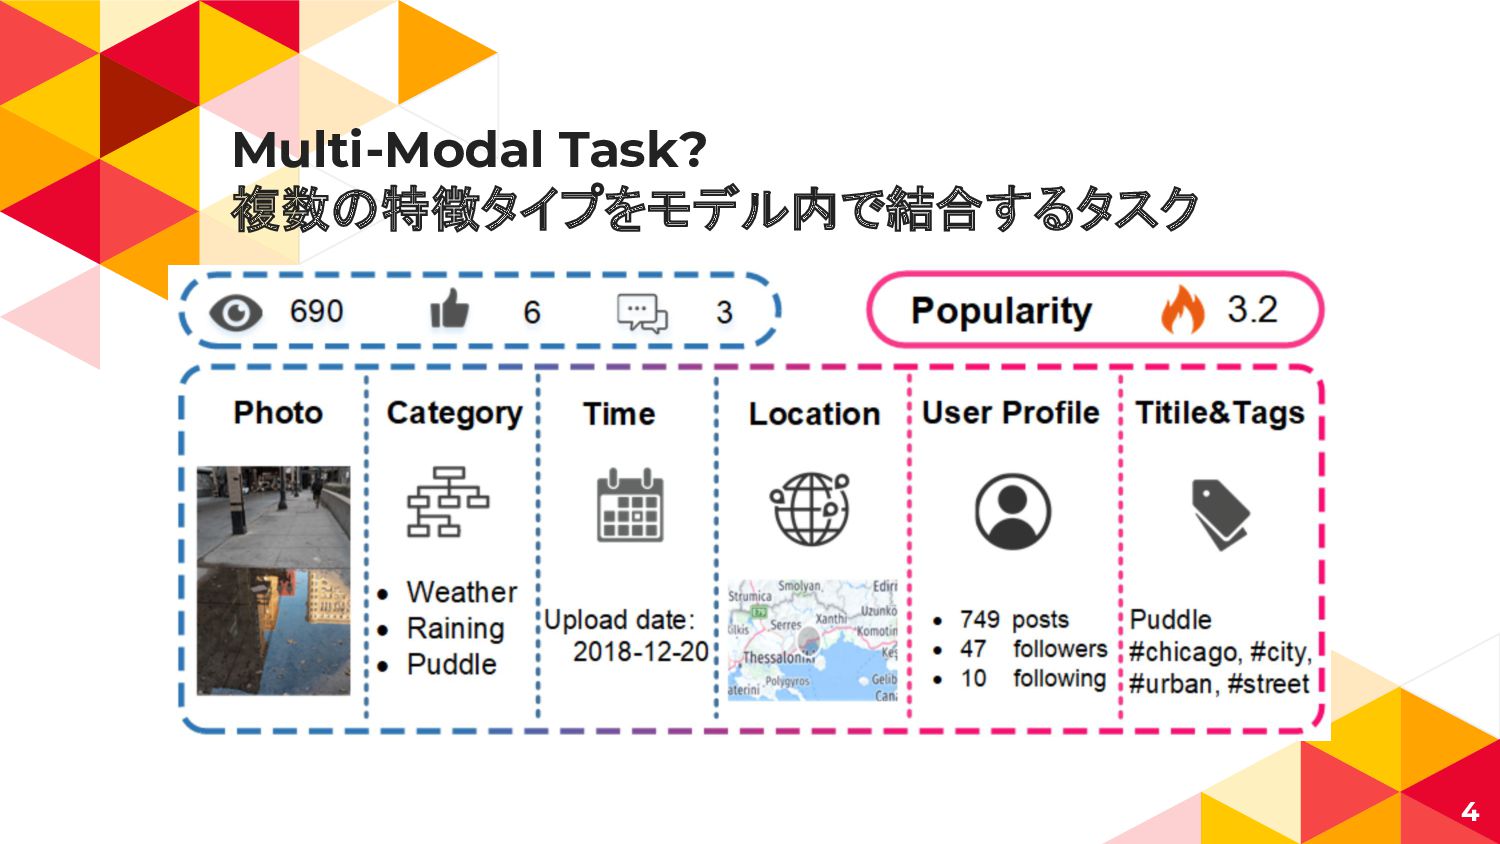
Multi-Modal Task? 複数の特徴タイプをモデル内で結合するタスク 4
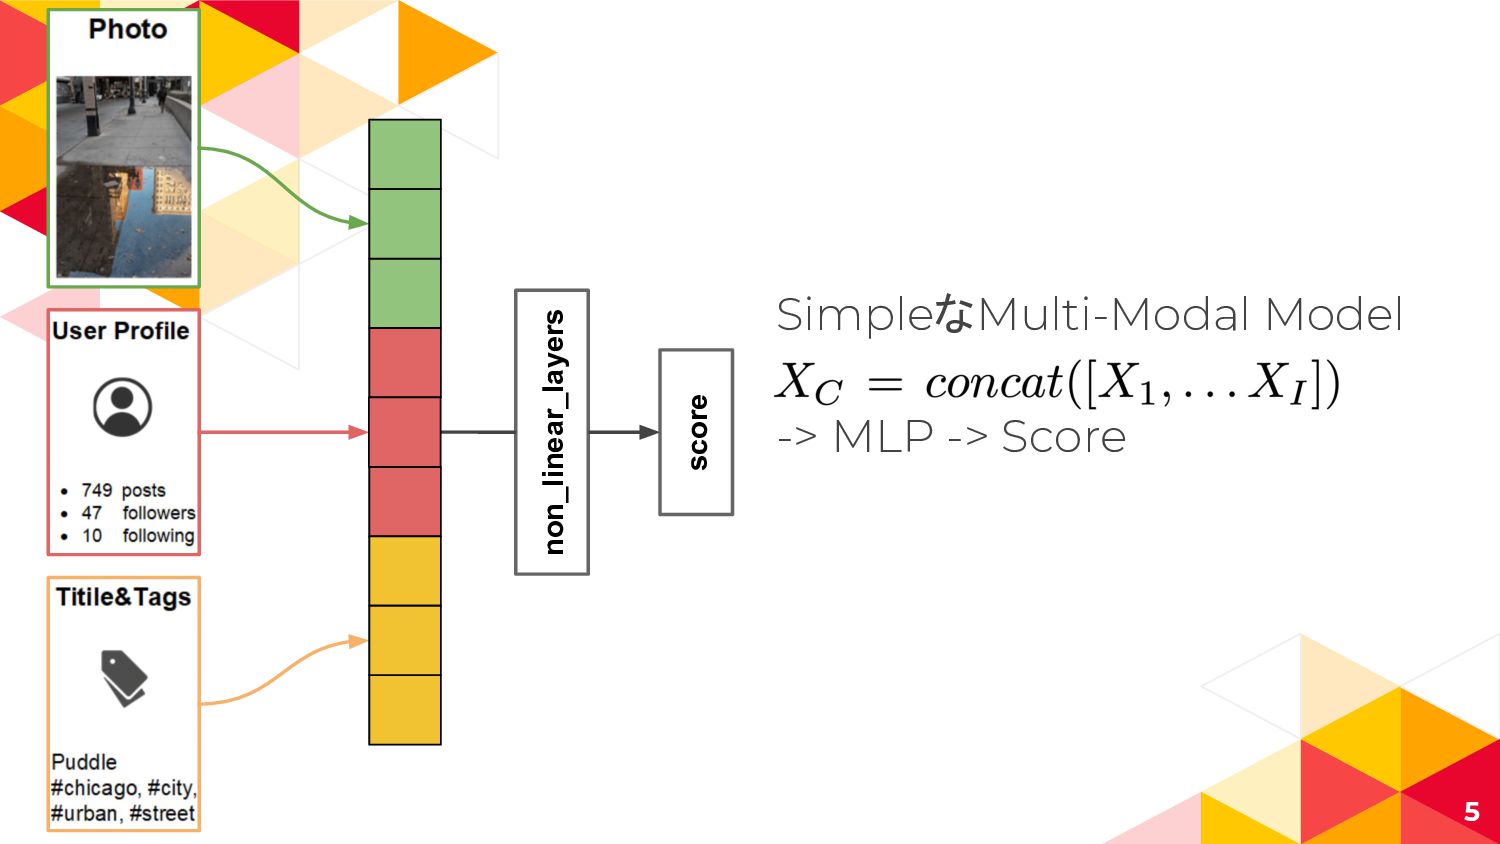
non_linear_layers score 5 SimpleなMulti-Modal Model XC = concat([X1, . .
. XI ]) -> MLP -> Score
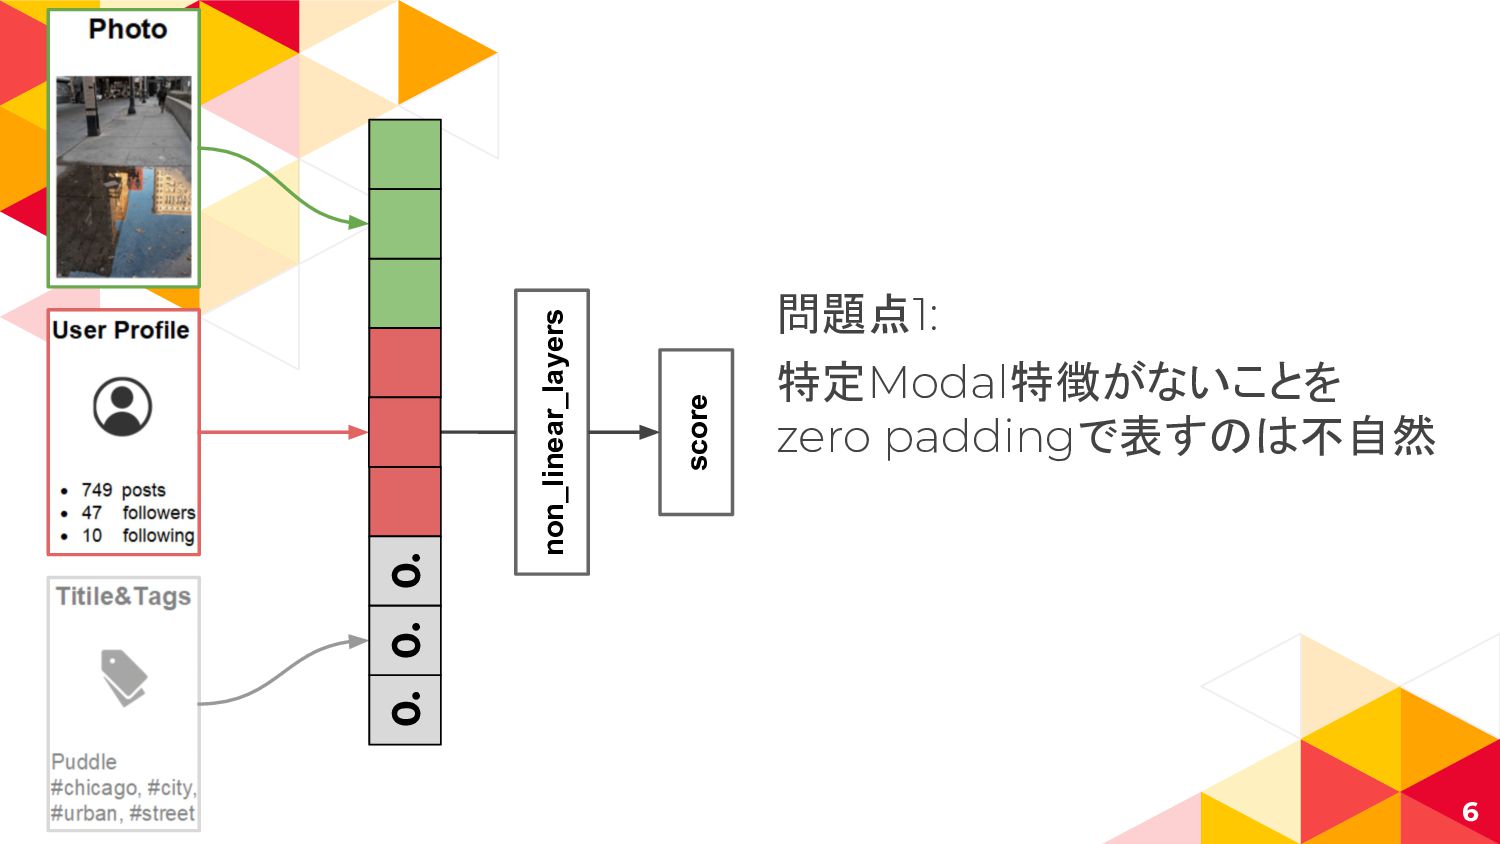
non_linear_layers score 6 問題点1: 特定Modal特徴がないことを zero paddingで表すのは不自然 0. 0. 0.
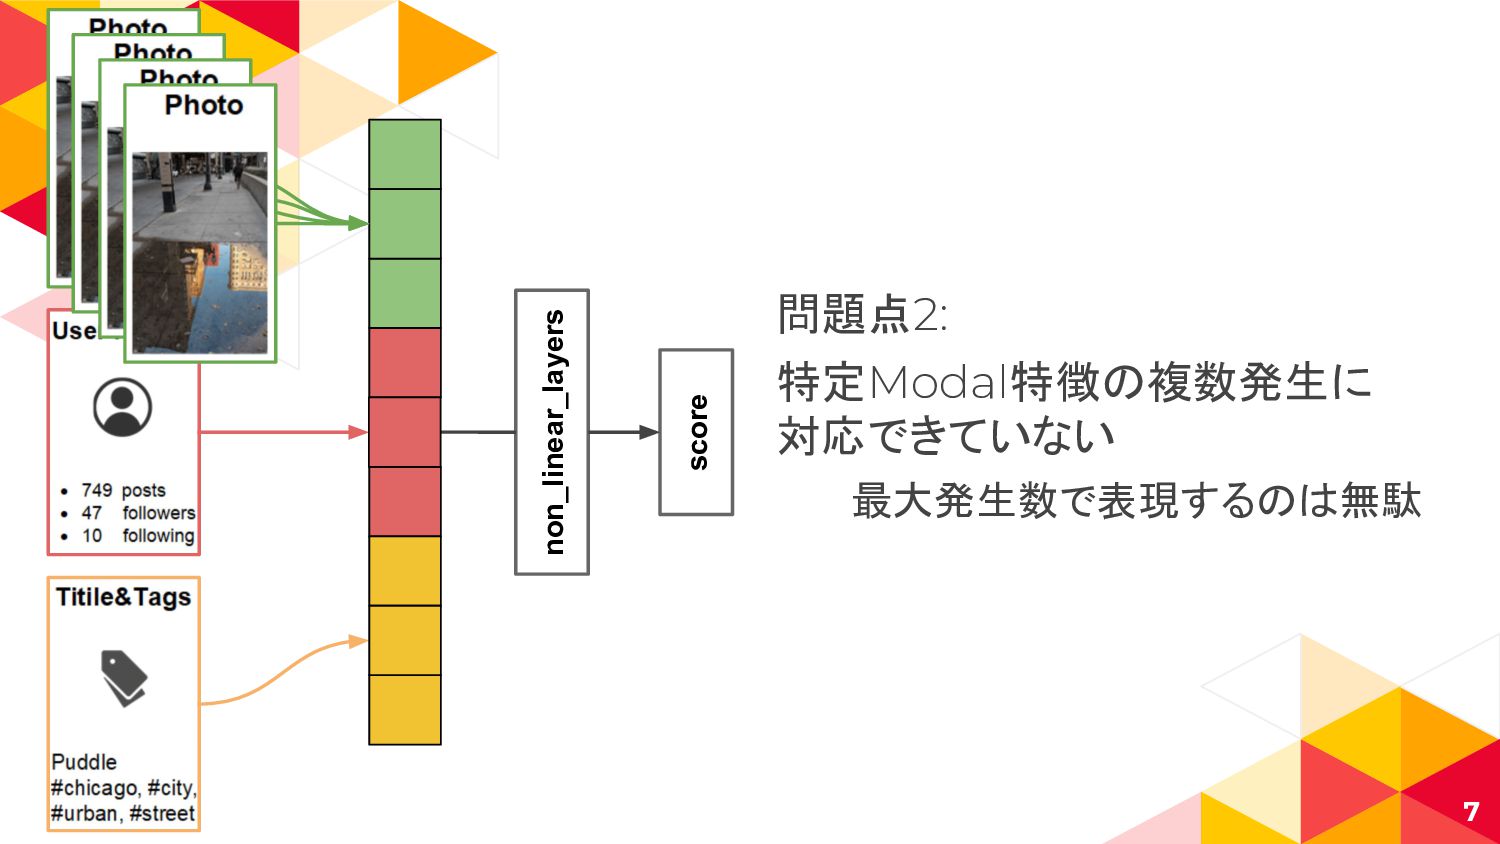
non_linear_layers score 7 問題点2: 特定Modal特徴の複数発生に 対応できていない 最大発生数で表現するのは無駄
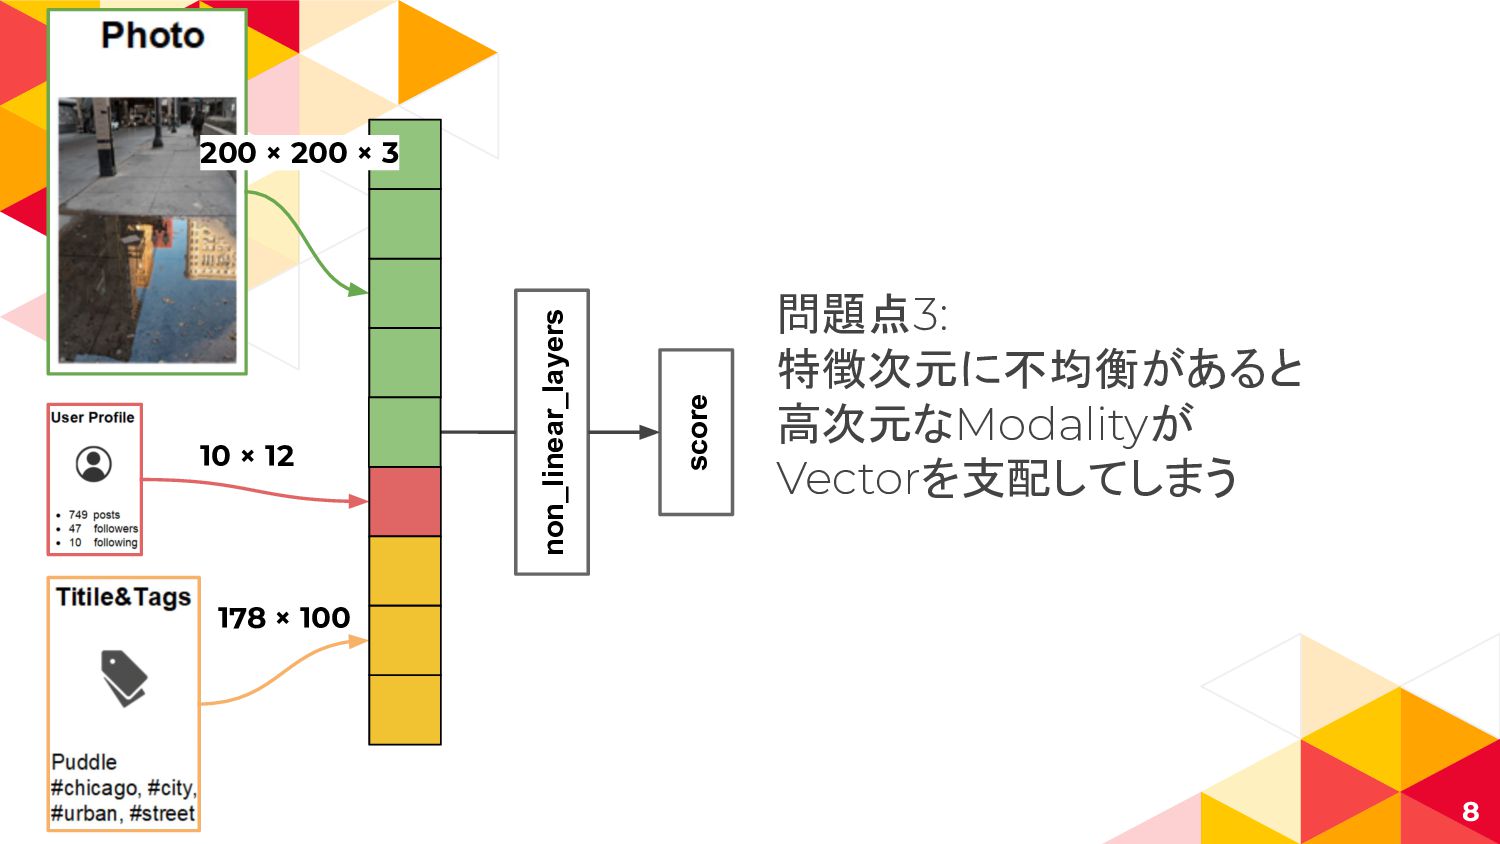
non_linear_layers score 8 問題点3: 特徴次元に不均衡があると 高次元なModalityが Vectorを支配してしまう 10 × 12
178 × 100 200 × 200 × 3
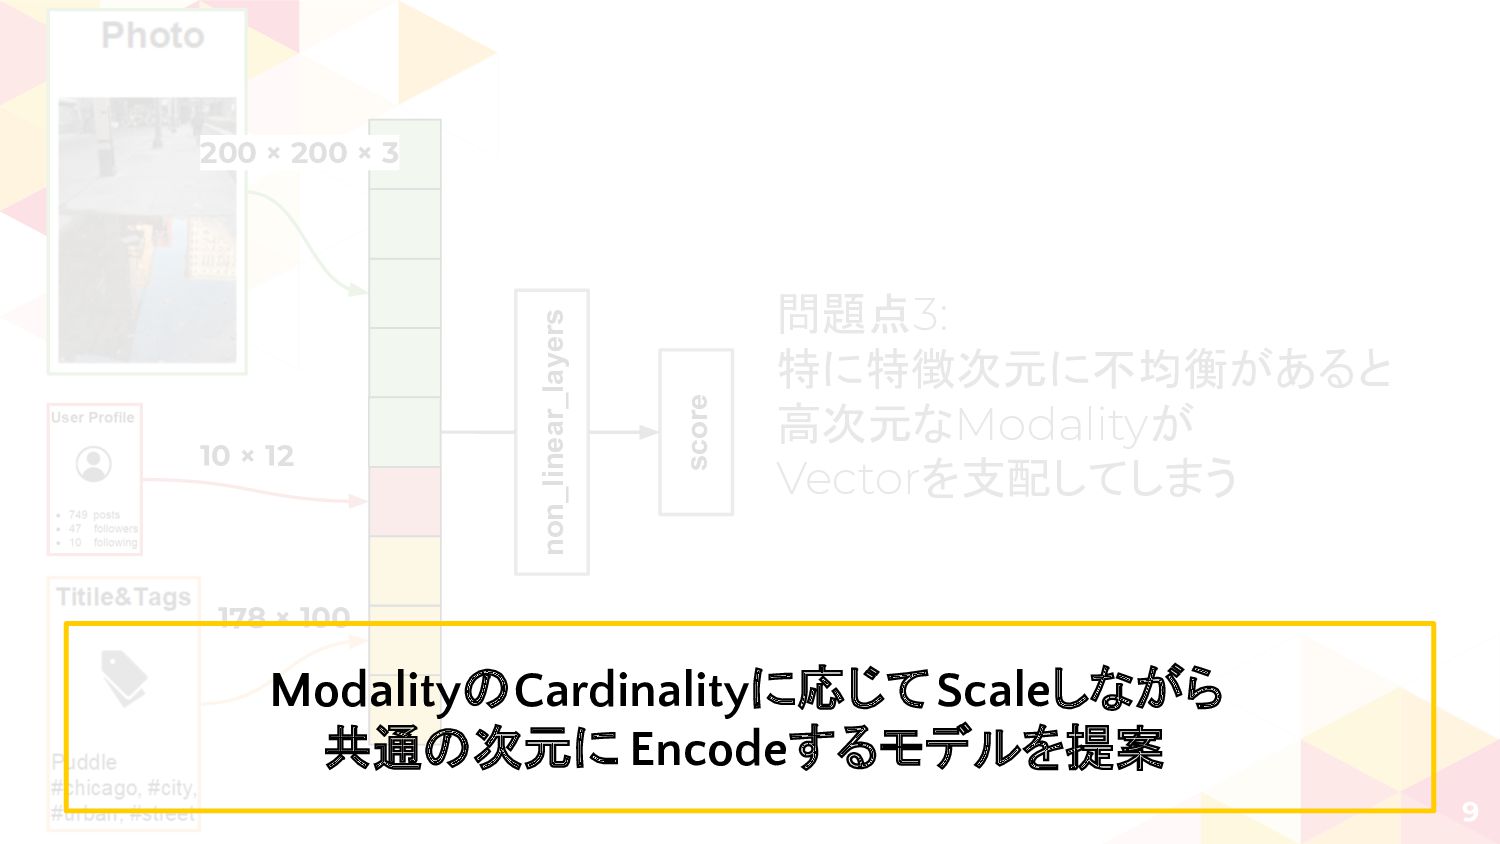
non_linear_layers score 9 問題点3: 特に特徴次元に不均衡があると 高次元なModalityが Vectorを支配してしまう 10 × 12
178 × 100 200 × 200 × 3 ModalityのCardinalityに応じてScaleしながら 共通の次元に Encodeするモデルを提案
Pooling Layer 10
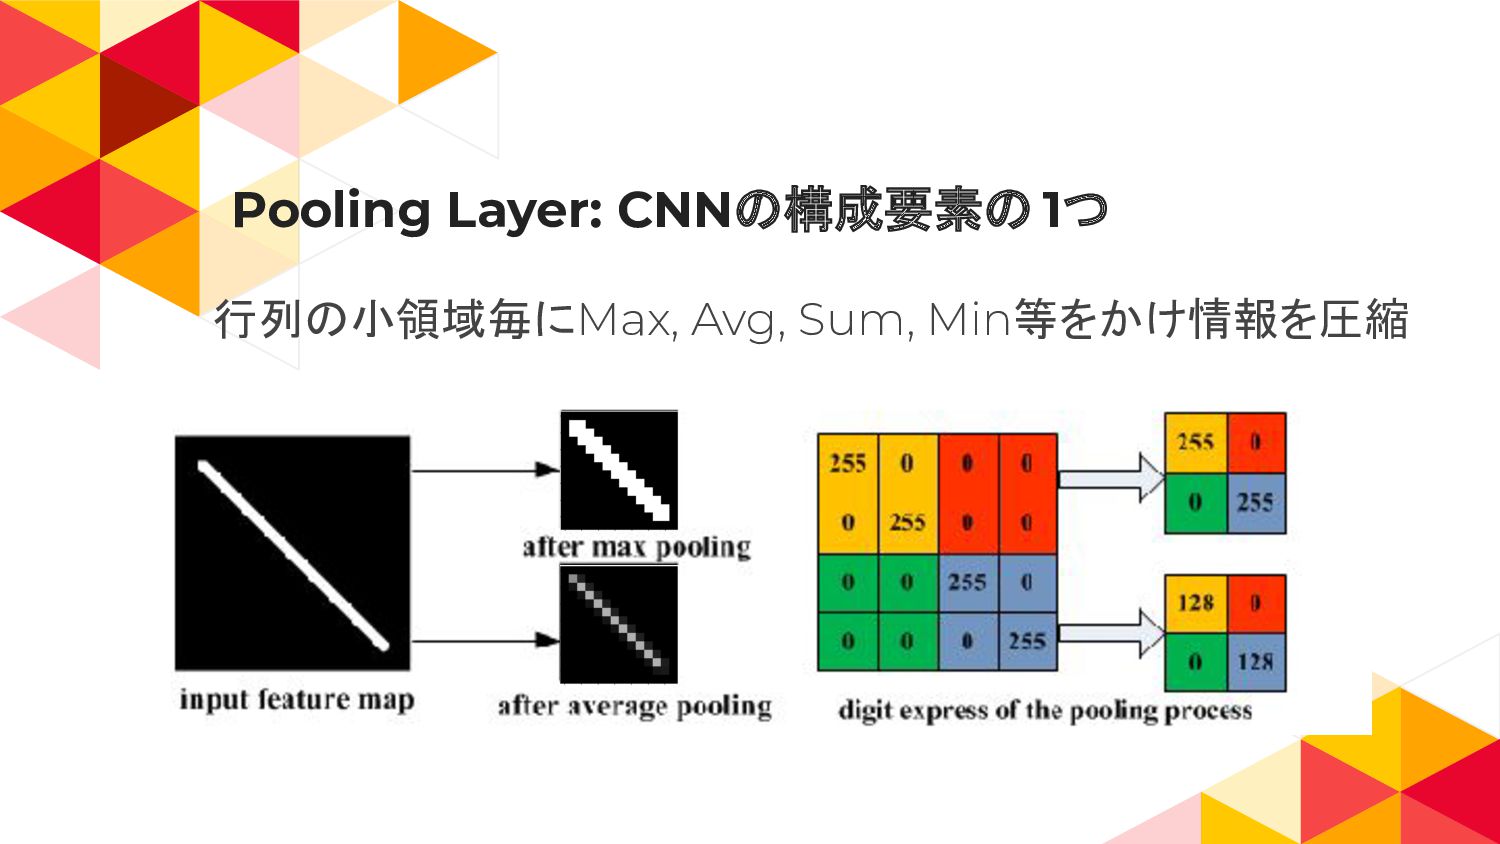
Pooling Layer: CNNの構成要素の 1つ 行列の小領域毎にMax, Avg, Sum, Min等をかけ情報を圧縮
Deep Sets 12
Deep Sets [Zaheer, 17] CNN(Pooling)の位置不変性を利用して Scalableな埋め込み表現を学習するモデル CNNでいう画像サイズが変わろうが、GCNでいうユー ザに対するアイテムの順番が変わろうが、 各要素、特徴自体の位置はPoolingのおかげで 大きく変わらない
15 Graph Convolutional Network
Proposed Method 16
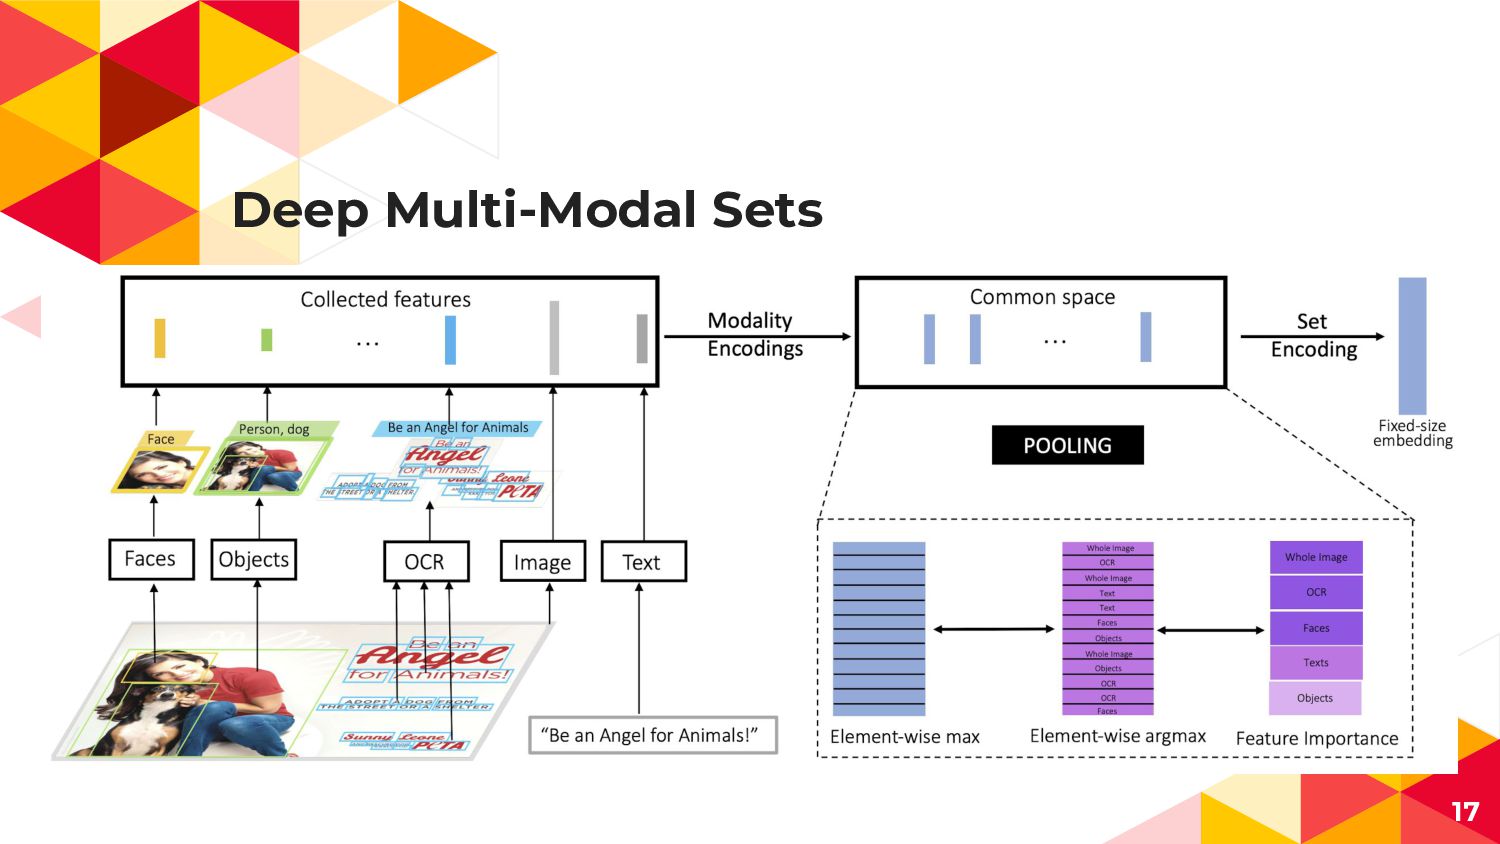
Deep Multi-Modal Sets 17
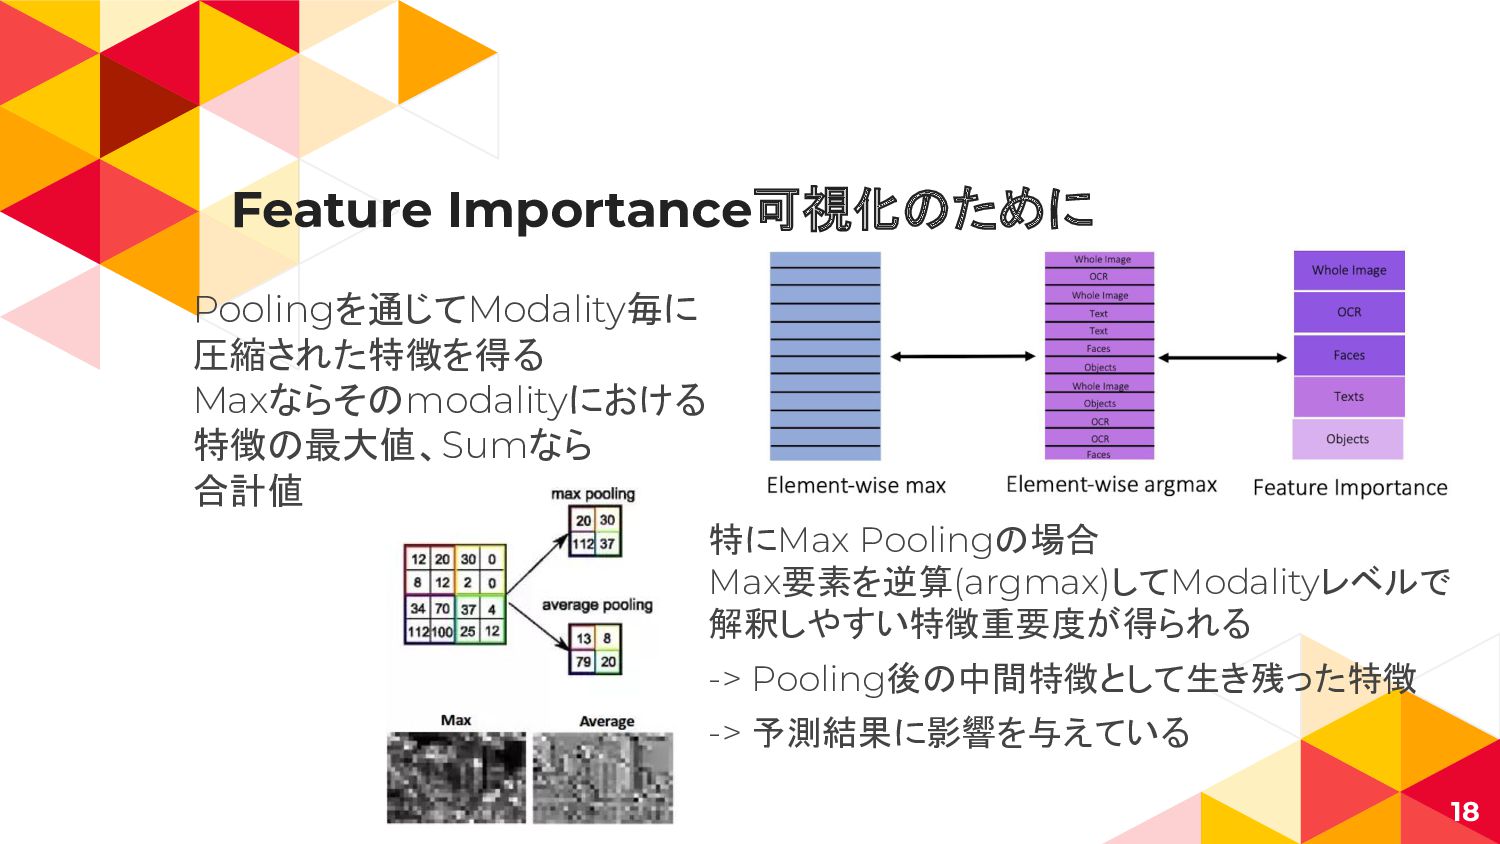
Feature Importance可視化のために Poolingを通じてModality毎に 圧縮された特徴を得る Maxならそのmodalityにおける 特徴の最大値、Sumなら 合計値 18 特にMax Poolingの場合
Max要素を逆算(argmax)してModalityレベルで 解釈しやすい特徴重要度が得られる -> Pooling後の中間特徴として生き残った特徴 -> 予測結果に影響を与えている
Experiments 19
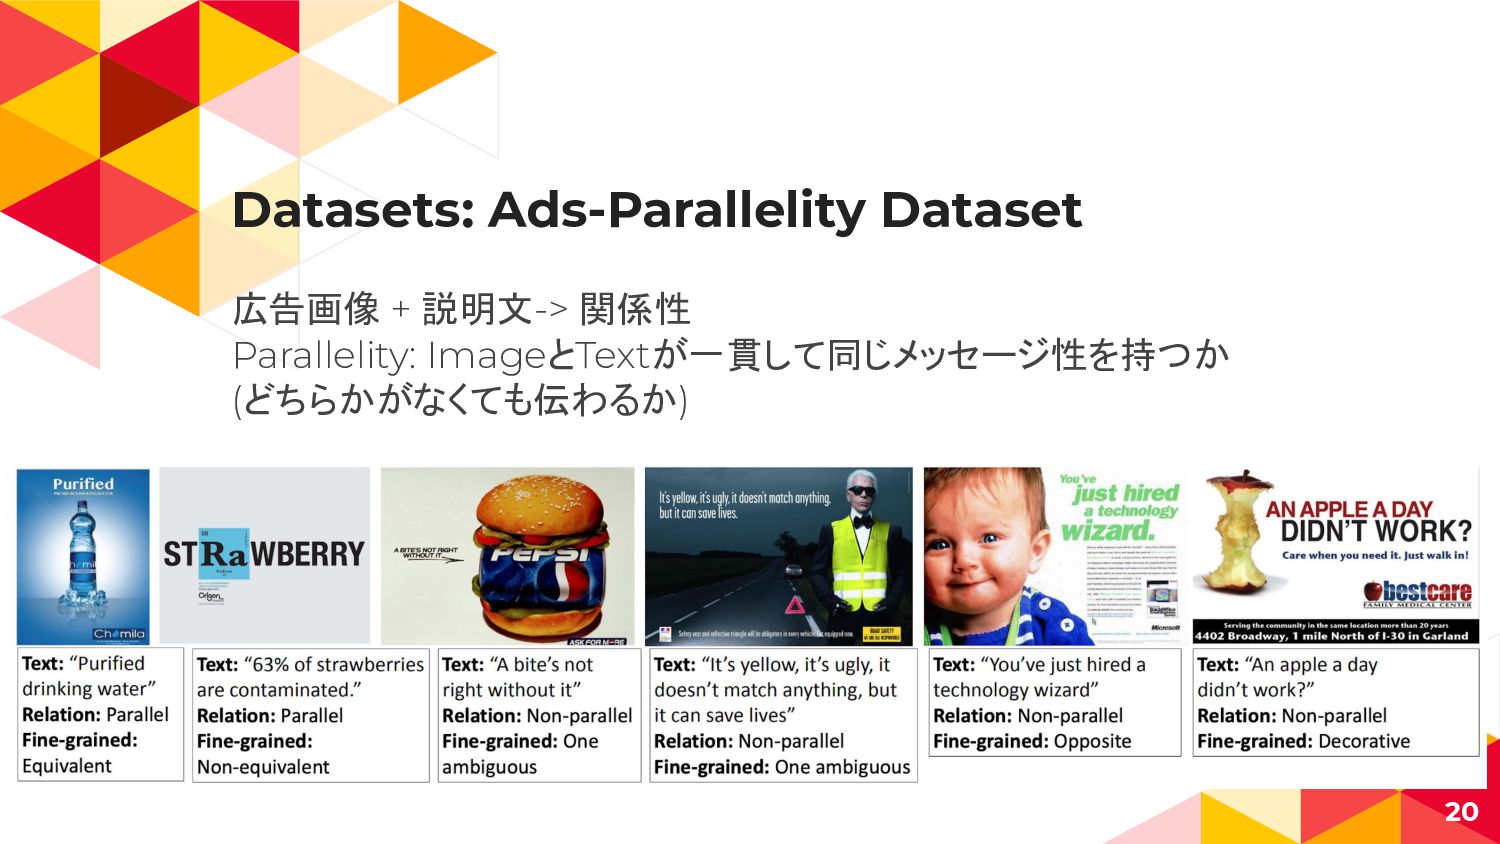
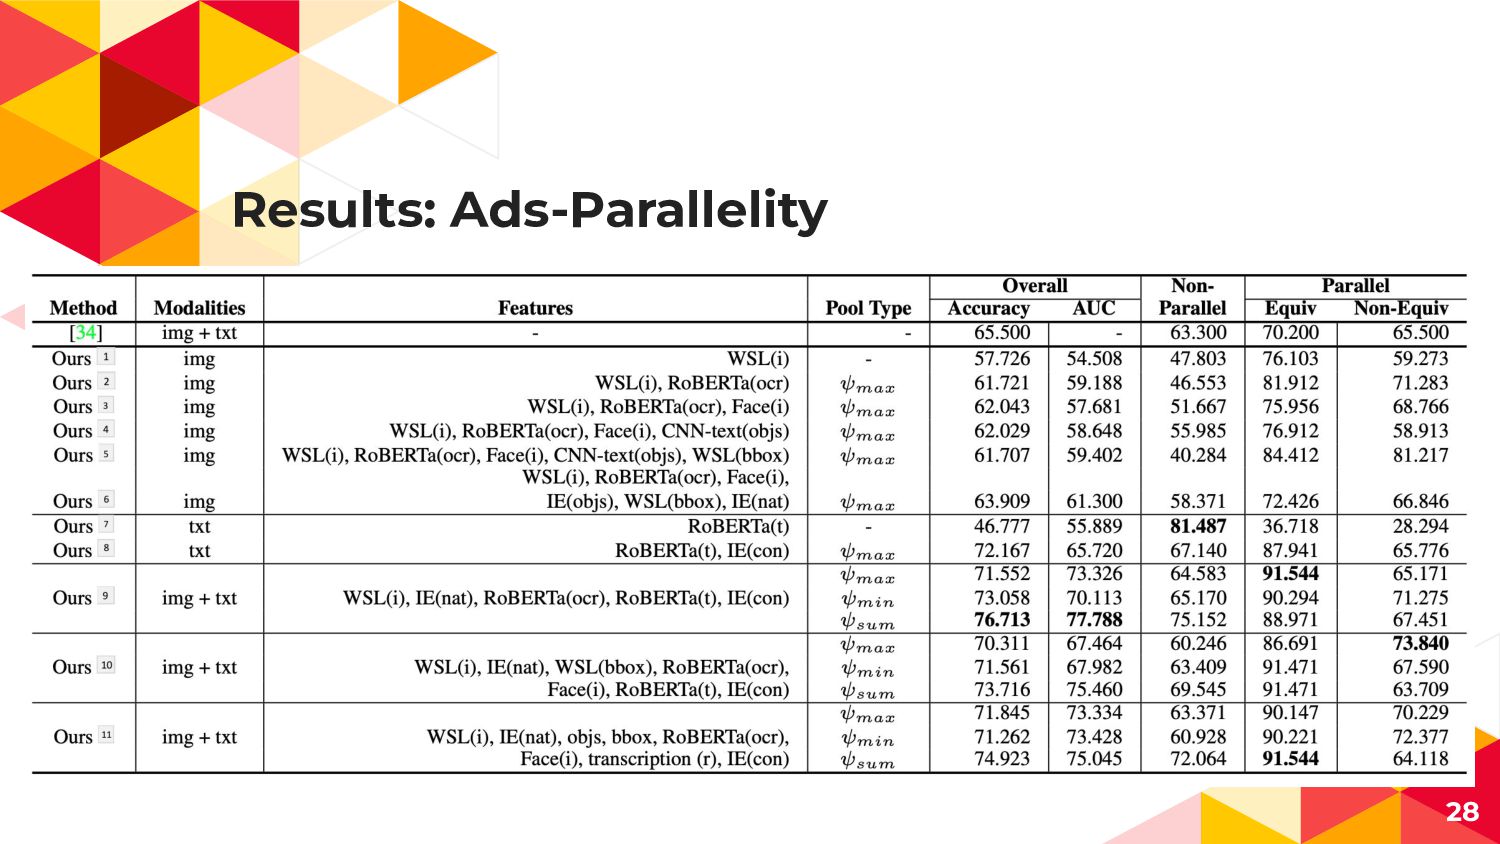
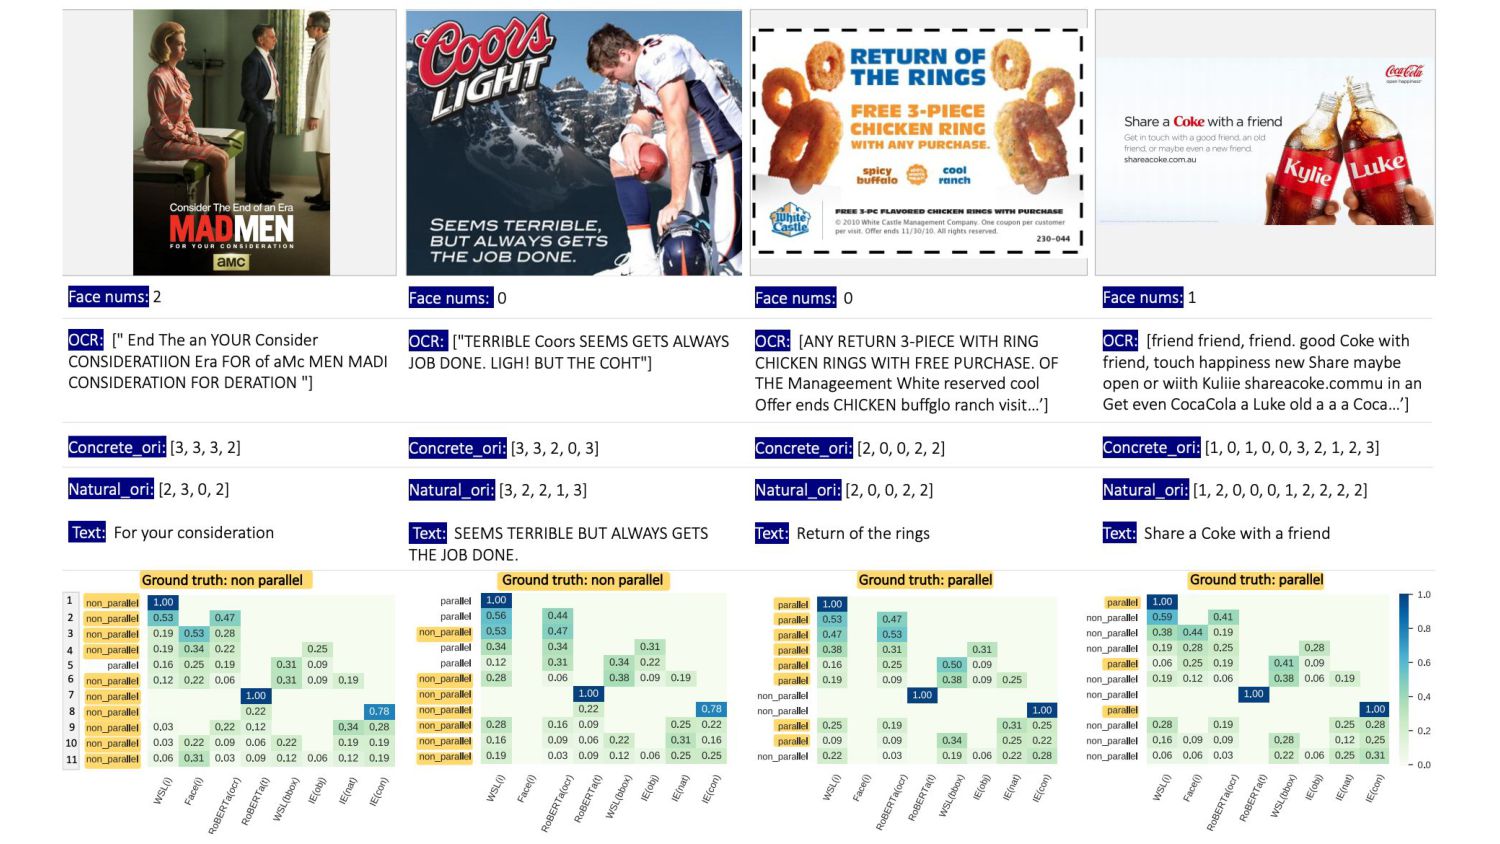
Datasets: Ads-Parallelity Dataset 広告画像 + 説明文-> 関係性 Parallelity: ImageとTextが一貫して同じメッセージ性を持つか (どちらかがなくても伝わるか)
20
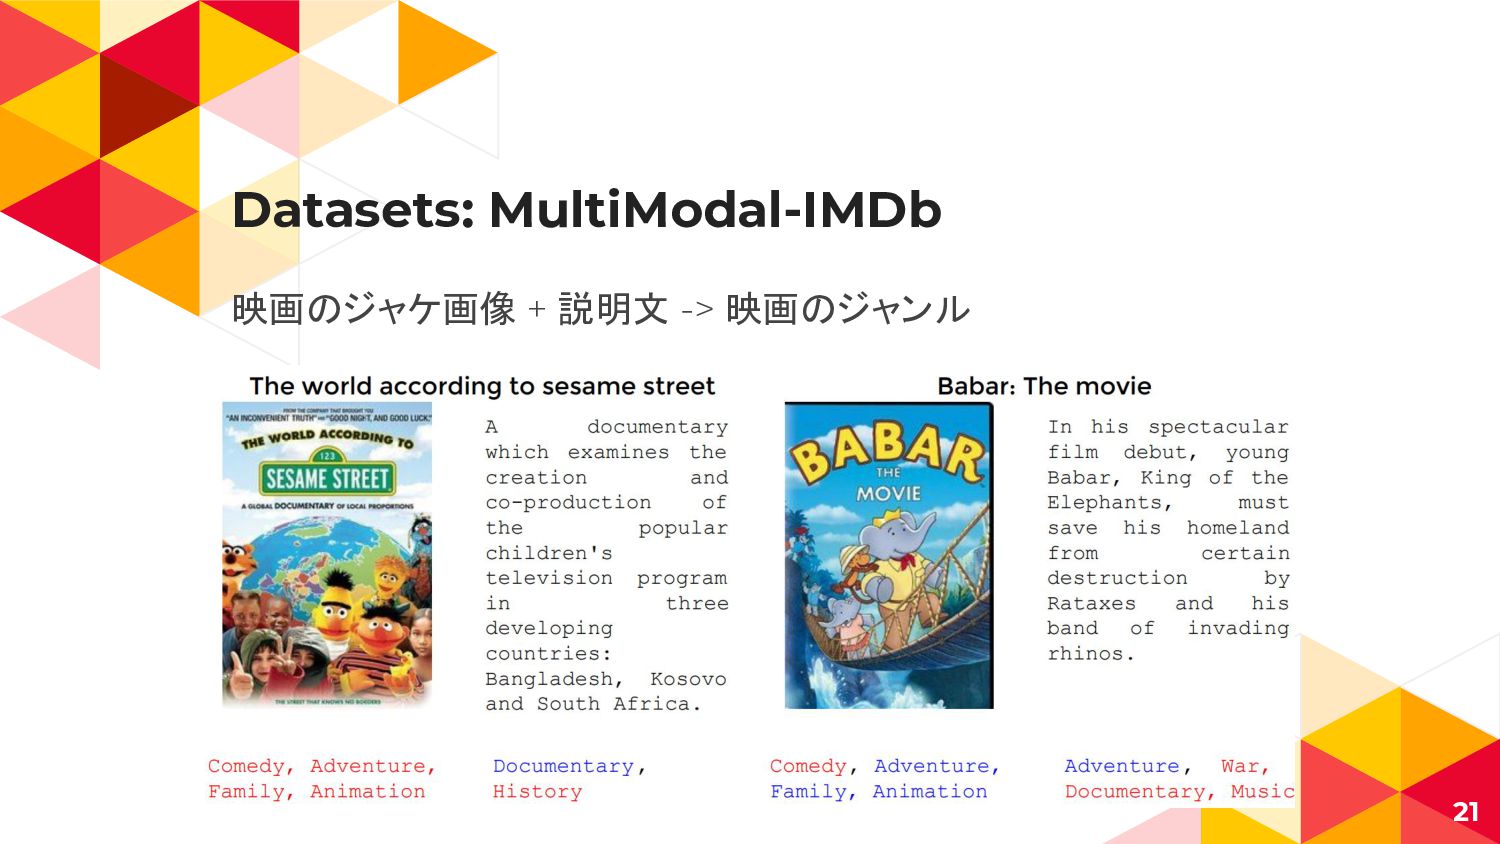
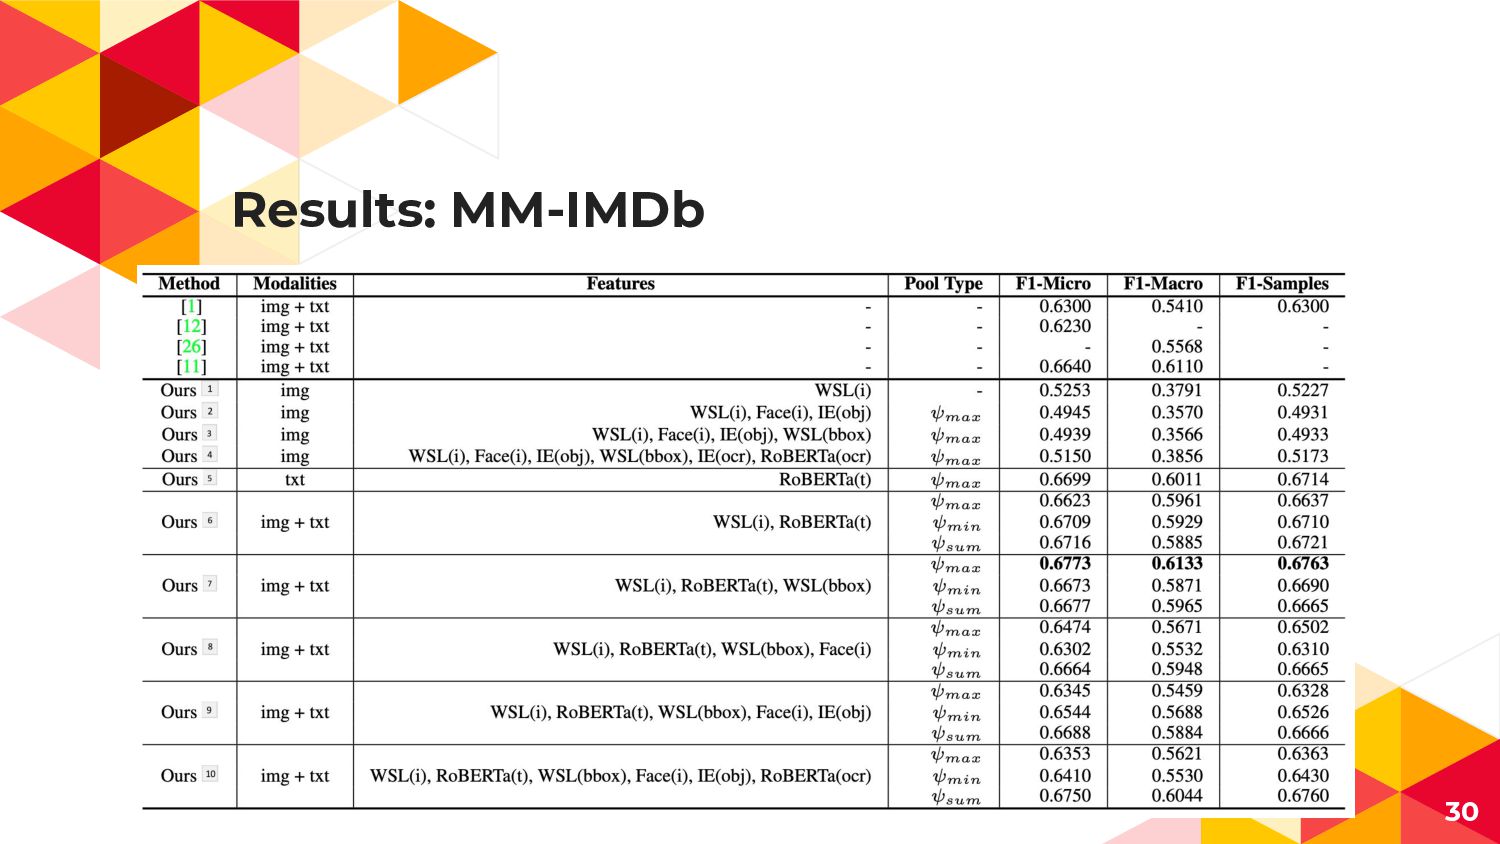
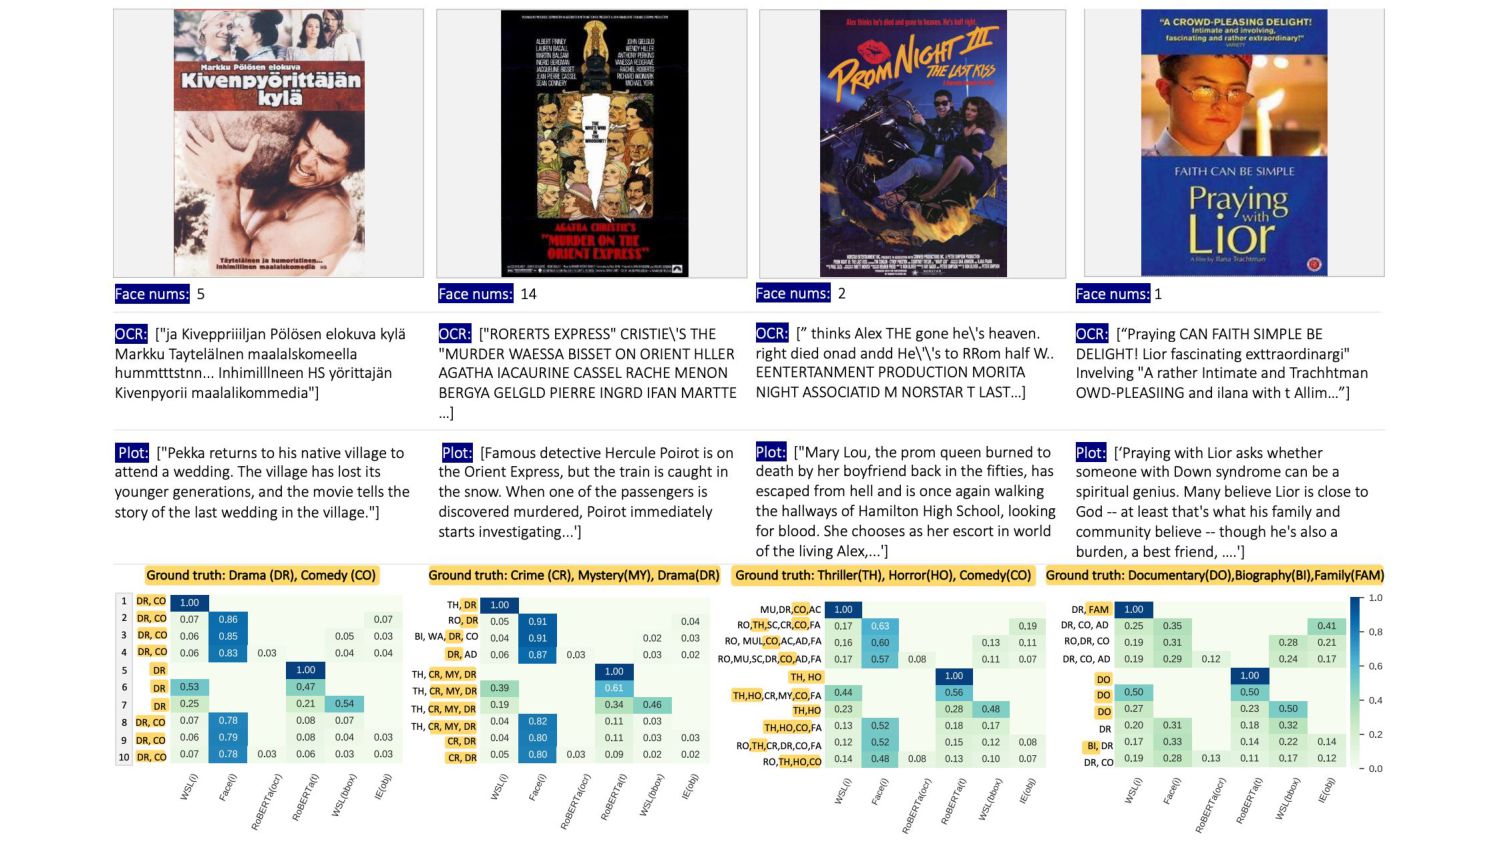
Datasets: MultiModal-IMDb 映画のジャケ画像 + 説明文 -> 映画のジャンル 21
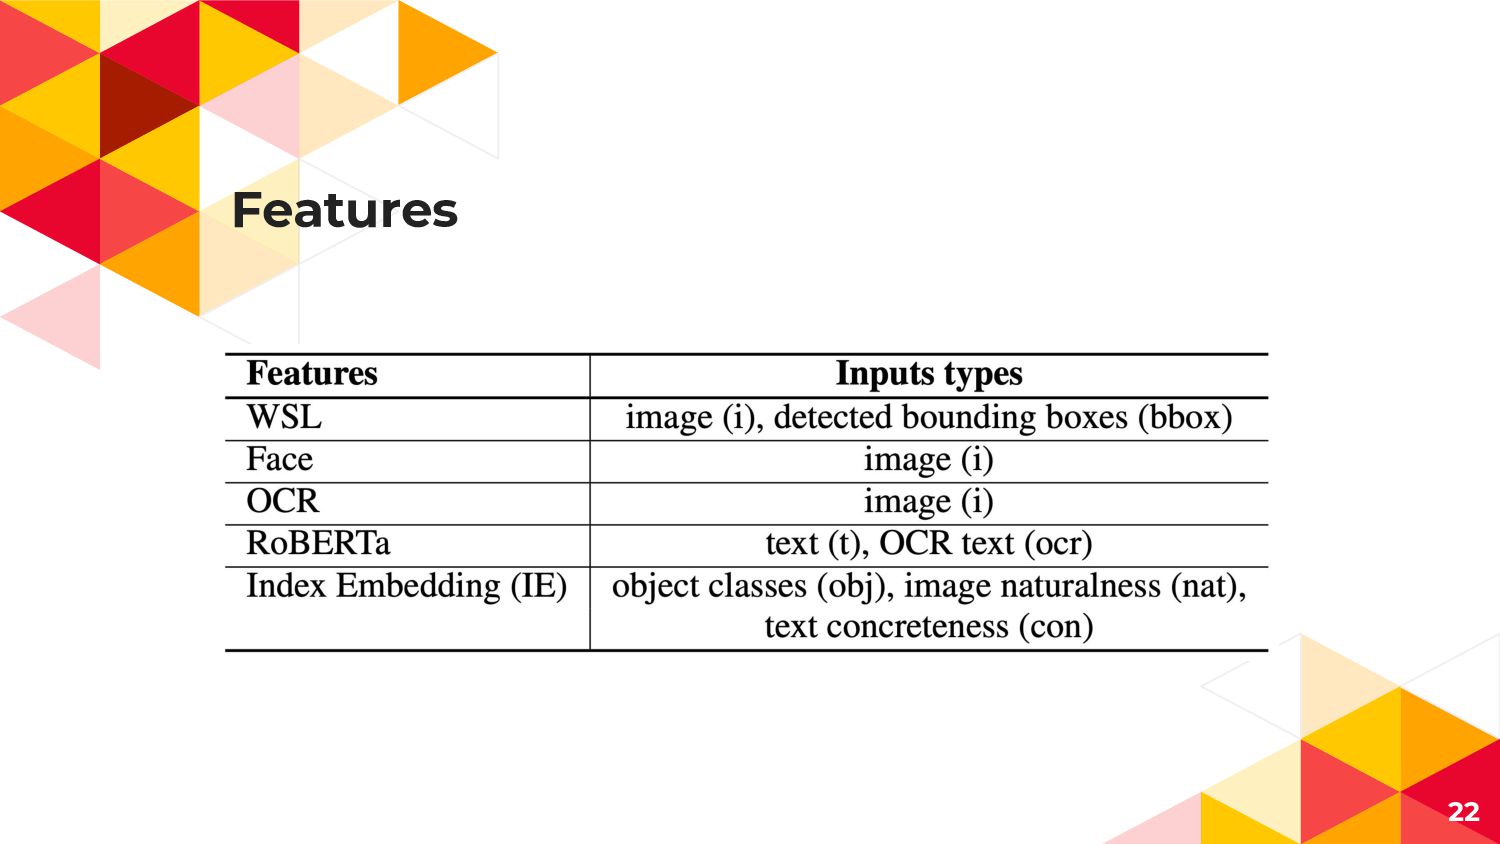
Features 22
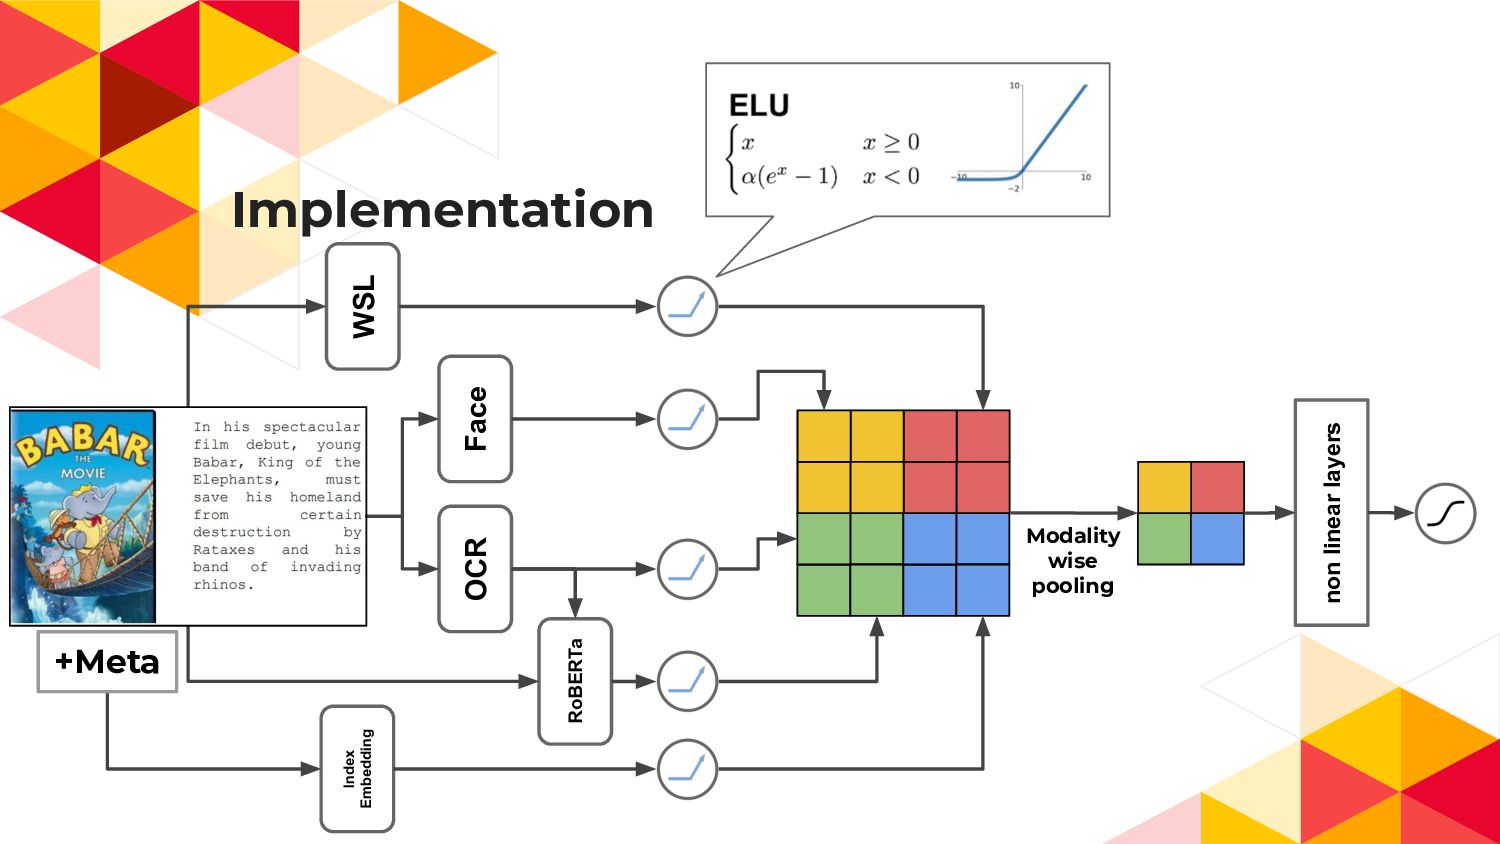
Implementation non linear layers Modality wise pooling WSL Face OCR
RoBERTa Index Embedding +Meta
Results: Ads-Parallelity 28
None
Results: MM-IMDb 30
None
Conclusion 37
Conclusion and Future Work ◂ DynamicなModalityをうまくモデリングできる Multi-Modal Architectureを提案 ◂ PoolingがDown
Samplingのように働く ◂ Max-Poolingを用いた重要度の可視化 ◂ エラー分析が容易に ◂ Videoへの拡張が今後の課題 38
Comment - Pooling自体はシンプルで直感的なので実装しやすい - 特徴抽出器まではfreezeなので計算コストも低そう - Pooling Encoderの出力次元Dがハイパラで肝 - Adsは32次元,
MM-IMDbは1024次元らしい - 説明文(RoBERTa)だけでそこそこ精度が出ている気がする - タスクによるが説明文があればOCRテキストはそこまで要らない? - OCR自体の検出性能が絡んでいそう 39
References - Permutation-equivariant neural networks applied to dynamics prediction -
Graph Neural Networks and Permutation invariance - Connections between Neural Networks and Pure Mathematics - Deep Sets 40
41 Thanks! Any questions? You can find me at ◂
@chck ◂ #times_chck ◂
[email protected]
Feedback - 特徴抽出器もコミコミのe2e? - GPUも1枚なのでおそらく抽出後が入力 - それはそれで実装が重いですね - pooling type結局どれがいいのか
- 精度大差ないのでFeature Importanceとの兼ね合いで Maxでいいのでは


 chck
 gpeyre
 satai
 rikkabotan7
 eumesy
 polipoli
 yukiar
 institutdelelevage
 shunk031
 kzmssk
 analokmaus
 yukako_nakano
 mongodb
 sachag
 frankvandijk
 greggifford
 carmenintech
 productmarketing
 addyosmani
 jonoalderson
 thekraken
 techseoconnect
 kimpetersen