Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
データルーター?Vector/Getting Started with Vector
Search
watawuwu
August 07, 2019
Technology
1.2k
6
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
データルーター?Vector/Getting Started with Vector
watawuwu
August 07, 2019
More Decks by watawuwu
See All by watawuwu
Prometheusでデータの水平分割を試みる/Let's split prometheus data
watawuwu
0
11k
KubernetesでWebアプリケーションをリリースするまでに必要なものは/What you need with Kubernetes
watawuwu
10
1.9k
Thanosってどうですか?/Getting Started with Thanos
watawuwu
1
1.1k
Argo入門/Getting Started with Argo
watawuwu
0
1.1k
Concourse入門 / Concourse Getting Started
watawuwu
3
2.3k
Other Decks in Technology
See All in Technology
ミイダス株式会社 テックチームのご紹介 / MIIDAS Tech Team
miidas
0
160
[2026 Oracle Technical Deep Dive] Apache Iceberg × Oracle AI Database -Oracle Autonomous AI Lakehouseが実現するAI時代のデータ基盤- (2026年9月17日開催)
oracle4engineer
PRO
0
120
Google Cloud Next Tokyo 26登壇時のスクリプト
recruitengineers
PRO
0
200
SREでアラート疲れを 解決しよう!
kairim0
1
210
予測不能な実行エージェントを安全にサクッと試せるサンドボックス環境の話
sansantech
PRO
0
130
形式手法を使って仕様をコーディングしよう
mikanichinose
0
180
事業活動を AI Ready にする攻めと守りのデータエンジニアリング / data-engineering-for-ai-ready-business
pei0804
3
1.5k
子育てエンジニアの可処分時間が減っても成長を諦めない戦い方
sudoakiy
1
1.4k
IR Today: Theory, Practice, and Agents
dtunkelang
0
350
分析AIエージェントを育てる、動く環境を育てる
codatum
0
130
組み立てて楽しむ AWS Blocks 入門
kmiya84377
0
220
MCPゲートウェイを作って運用してわかったこと — Agent時代の権限管理の現在地
mtpooh
10
3.2k
Featured
See All Featured
Navigating Weather and Climate Data
rabernat
0
550
The AI Revolution Will Not Be Monopolized: How open-source beats economies of scale, even for LLMs
inesmontani
PRO
3
3.8k
Exploring the Power of Turbo Streams & Action Cable | RailsConf2023
kevinliebholz
37
6.6k
sira's awesome portfolio website redesign presentation
elsirapls
0
440
10 Git Anti Patterns You Should be Aware of
lemiorhan
PRO
659
62k
JavaScript: Past, Present, and Future - NDC Porto 2020
reverentgeek
52
6.1k
How to Align SEO within the Product Triangle To Get Buy-In & Support - #RIMC
aleyda
2
1.8k
Digital Ethics as a Driver of Design Innovation
axbom
PRO
1
450
What the history of the web can teach us about the future of AI
inesmontani
PRO
1
720
Facilitating Awesome Meetings
lara
57
7.2k
Design in an AI World
tapps
1
350
Bash Introduction
62gerente
615
220k
Transcript
Getting Started with Vector Cloud native meetup tokyo #9 This
document includes the work that is distributed in the Apache License 2.0
profile: name: Wataru Matsui org: [ Z Lab, 3bi.tech ]
twitter: @watawuwu
• What’s Vector? • Usage • VS ... • Roadmap
• Conclusions Agenda
What’s Vector? https://vector.dev
Logs, Metrics & Events Router Is like Fluentd?
Developed by Timber.io https://timber.io
Feature • Log, Metrics, or Events • Agent Or Service
• Fast • Correct • Clear Guarantee • Vendor Neutral • Easy To Deploy • Hot Reload
• Fluentd • Fluent Bit • Filebeat • Logstash Similar
tool
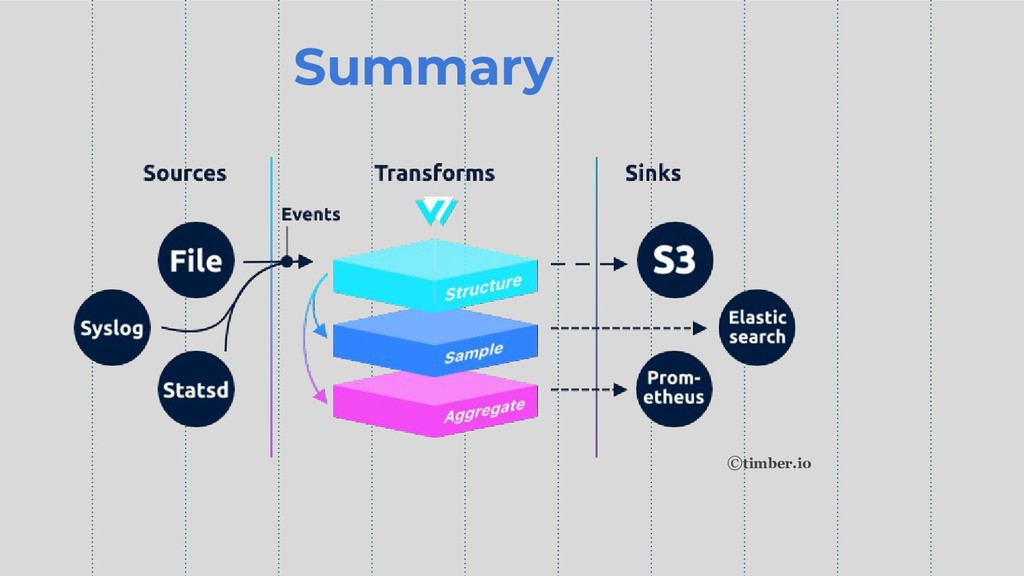
Summary ©timber.io
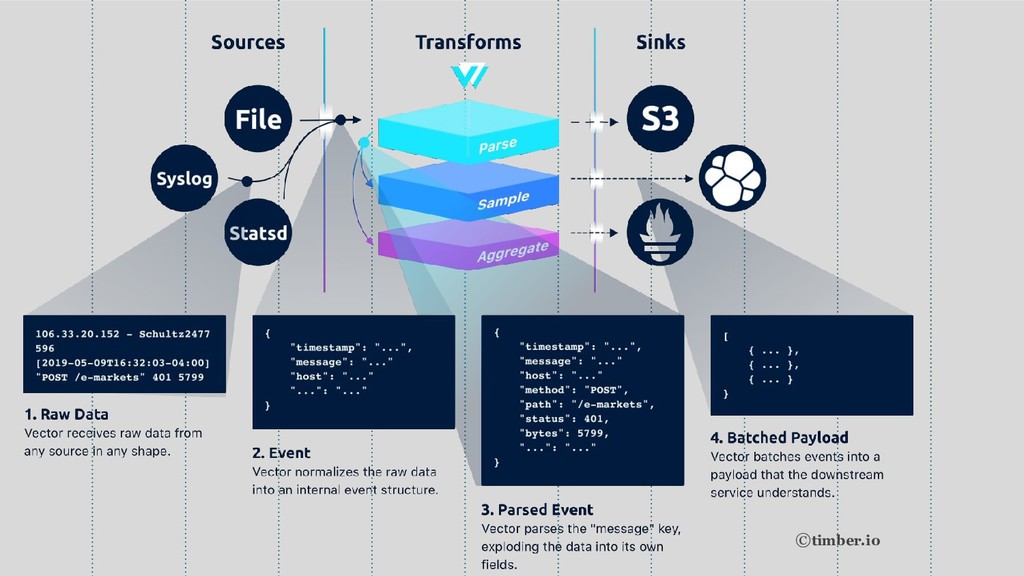
©timber.io
Topologies: Distributed ©timber.io
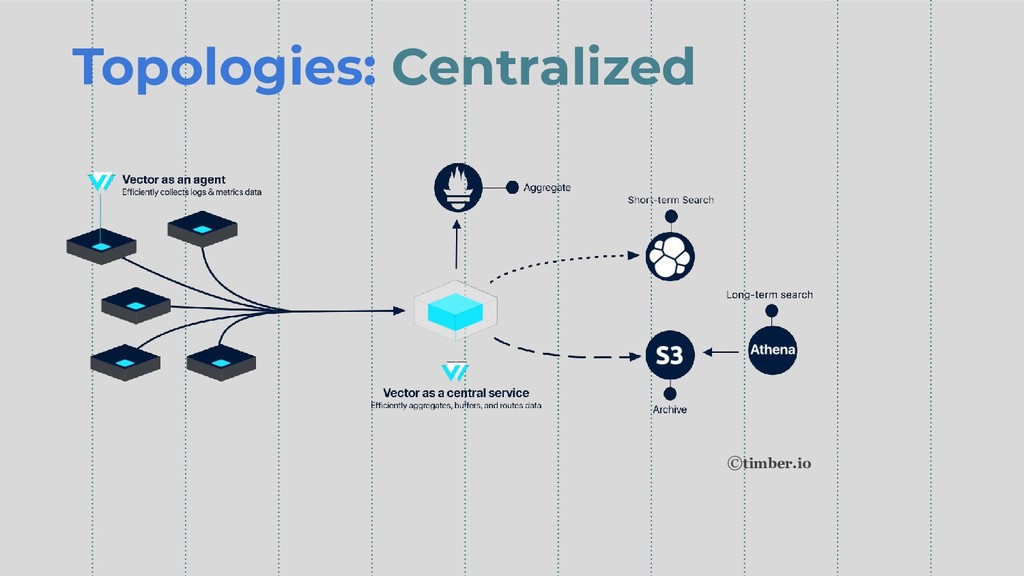
Topologies: Centralized ©timber.io
Topologies: Stream-Based ©timber.io
How to use Vector
Source types • file • statsd • syslog • tcp
• vector • stdin(debug)
[sources.my_file_source_id] # REQUIRED - General type = "file"
# must be: "file" include = ["/var/log/nginx/*.log"] exclude = [""] Source config
[sources.my_tcp_source_id] # REQUIRED - General type = "tcp"
# must be: "tcp" address = ["0.0.0.0:9000"] Source config
Sink types • aws ◦ cloudwatch_logs ◦ kinesis_streams ◦ s3
• elasticsearch • http • kafka • prometheus • splunk_hec • tcp • vector • console • blackhole(/dev/null)
[sinks.my_tcp_sink_id] # REQUIRED - General type = "tcp"
# must be: "tcp" input = ["my_tcp_source_id"] address = ["92.12.333.224:5000"] # OPTIONAL - Requests encoding = "json" # default, enum: "json", "text" Sinks config
[sinks.my_s3_sink_id] # REQUIRED - General type = "s3"
# must be: "s3" input = ["my_file_source_id"] bucket = "my-bucket" region = "ap-northeast-1" encoding = "ndjson" # enum: "ndjson", "text" # OPTIONAL - Requests key_prefix = "date=%F/" # default Sinks config
[sinks.my_prometheus_sink_id] # REQUIRED - General type = "prometheus"
# must be: "prometheus" input = ["my_log2metrics_source_id"] address = "0.0.0.0:9598" Sinks config
Transform types • Fileld ◦ add_fields ◦ remove_filed ◦ filed_filter
• Paser ◦ grok_parser ◦ json_parser ◦ regex_parser ◦ tokenizer • log_to_metric • sampler • lua • vector • console • blackhole(/dev/null)
[transforms.my_regex_trans_id] # REQUIRED - General type = "regex_parser" #
must be: "regex_parser" inputs = ["my_file_source_id"] regex = "^(?P<host>[\\w\\.]+) - (?P<user>[\\w]+) (?P<bytes_in>[\\d]+) \\[(?P<timestamp>.*)\\] \"(? P<method>[\\w]+) (?P<path>.*)\" (?P<status>[\\d]+) (?P<bytes_out>[\\d]+)$" # OPTIONAL - Types [transforms.my_regex_trans_id.types] status = "int" method = "string" bytes_in = "int" bytes_out = "int" Transform config
[transforms.my_prometheus_trans_id] # REQUIRED - General type = "log_to_metric" #
must be: "log_to_metric" inputs = ["my_file_source_id"] # OPTIONAL - Types [[transforms.my_regex_trans_id.metrics]] type = "counter" # enum: "counter", "gauge" field = "duration" increment_by_value = false name = "duration_total" labels = {host = "${HOSTNAME}", region = "us-east-1"} Transform config
[sources.logs] type = 'file' include = ['/var/log/*.log'] [transforms.tokenizer]
inputs = ['logs'] type = 'tokenizer' field_names = ["timestamp", "level", "message"] [transforms.sampler] inputs = ['tokenizer'] type = 'sampler' hash_field = 'request_id' rate = 10 [sinks.search] inputs = ['sampler'] type = 'elasticsearch' host = '123.123.123.123:5000' [sinks.backup] inputs = ['tokenizer'] type = 's3' region = 'ap-northeast-1' bucket = 'log-backup' key_prefix = 'date=%F' Vector config
VS
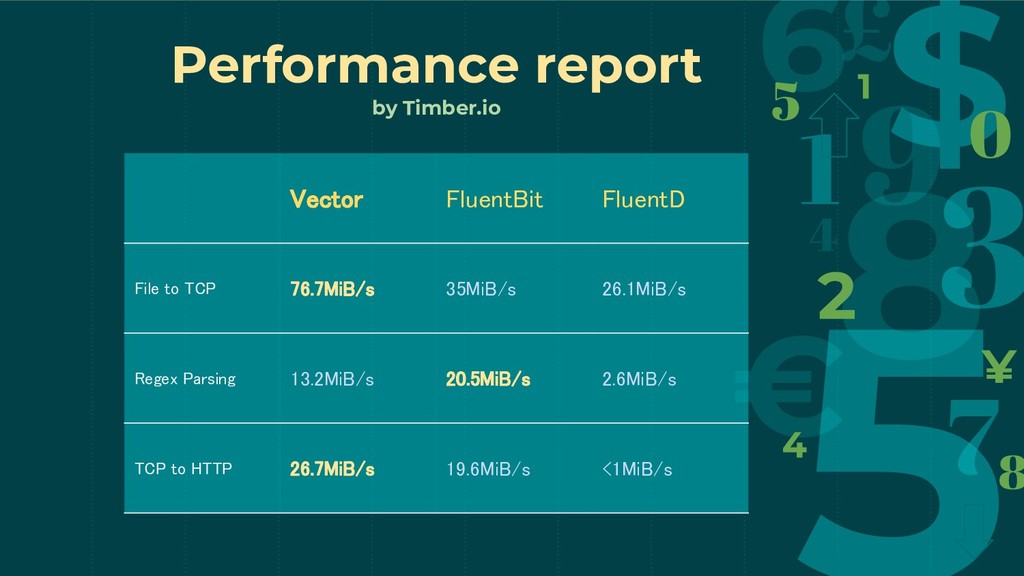
Vector FluentBit FluentD File to TCP 76.7MiB/s 35MiB/s 26.1MiB/s
Regex Parsing 13.2MiB/s 20.5MiB/s 2.6MiB/s TCP to HTTP 26.7MiB/s 19.6MiB/s <1MiB/s Performance report by Timber.io
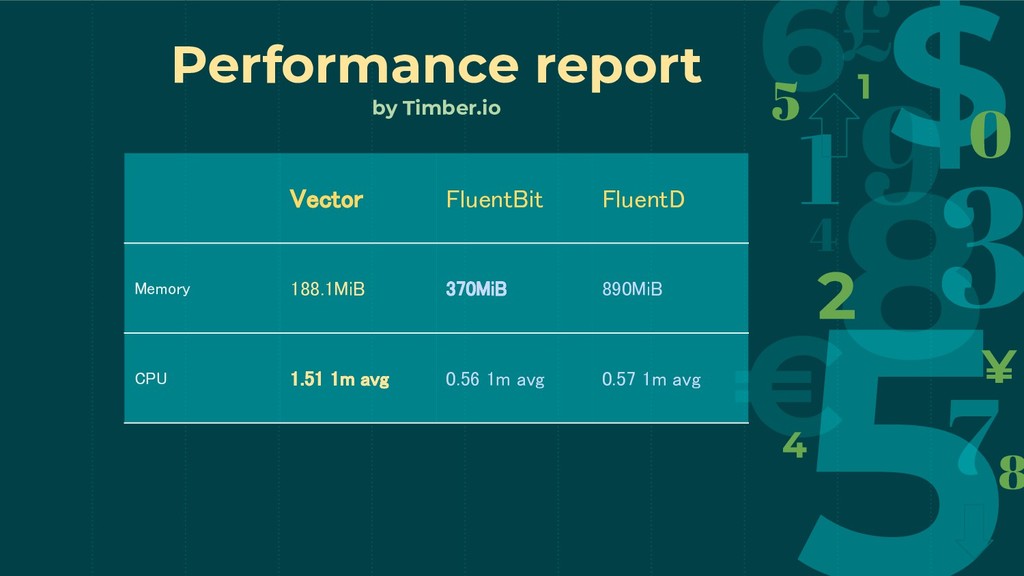
Vector FluentBit FluentD Memory 188.1MiB 370MiB 890MiB CPU 1.51
1m avg 0.56 1m avg 0.57 1m avg Performance report by Timber.io
Don't trust the reports. Measure, Measure, Measure!
Measure using GKE • Kubernetes: v1.13.7 • Node x4 ◦
4 CPU ◦ 3.6 GB Memory ◦ 100 GB Storage(Standard) • Manifests ◦ https://github.com/watawuwu/vector-test
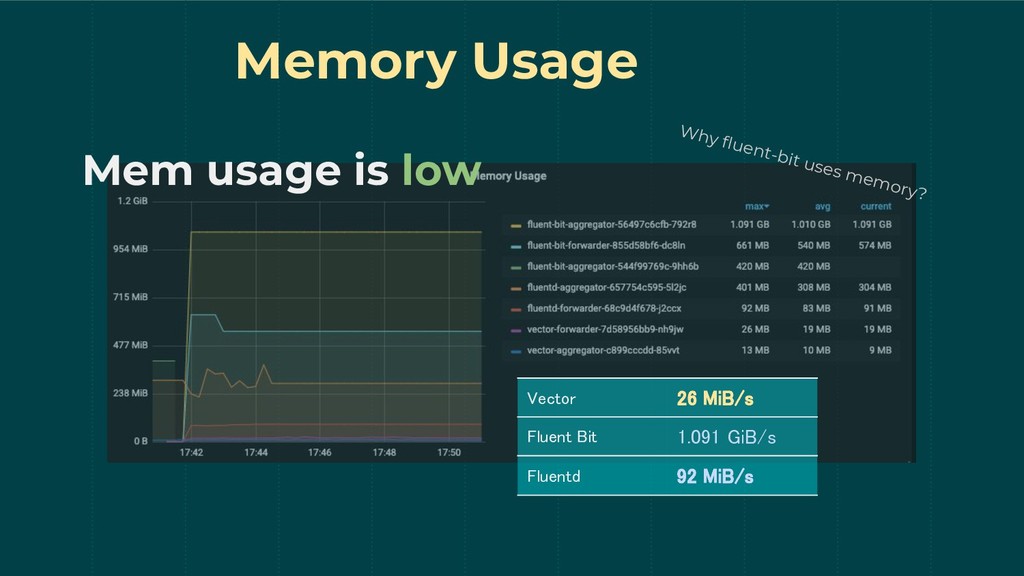
Memory Usage Mem usage is low Why fluent-bit uses memory?
Vector 26 MiB/s Fluent Bit 1.091 GiB/s Fluentd 92 MiB/s
CPU Usage CPU usage is high Vector 1.84 core Fluent
Bit 0.26 core Fluentd 1.25 core
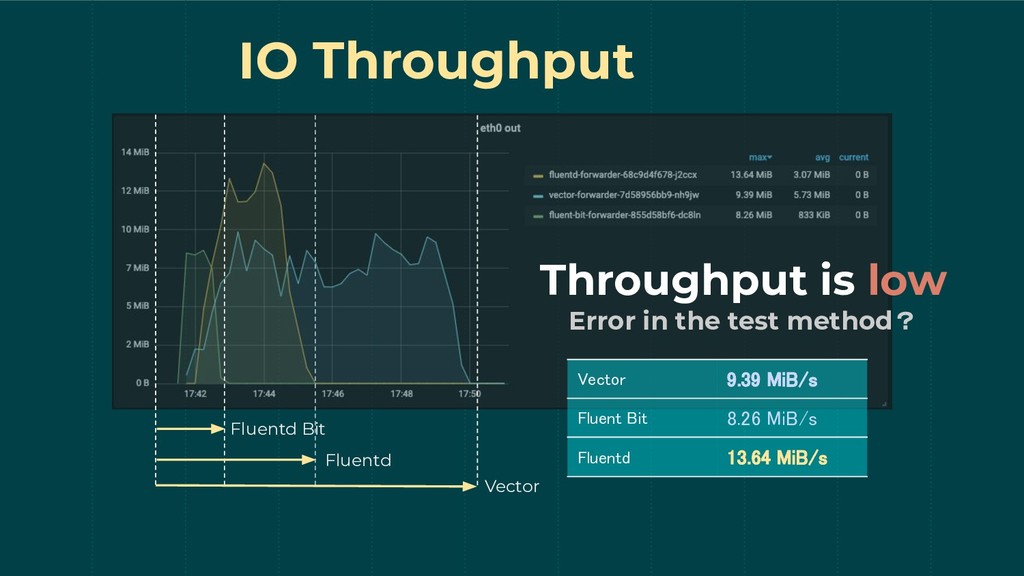
IO Throughput Vector Fluentd Fluentd Bit Throughput is low Error
in the test method? Vector 9.39 MiB/s Fluent Bit 8.26 MiB/s Fluentd 13.64 MiB/s
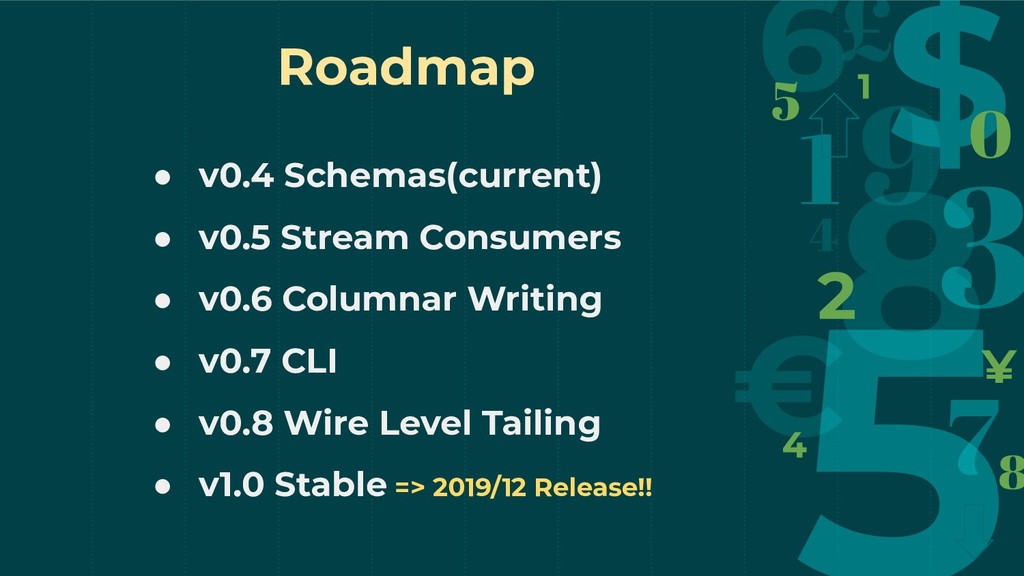
Roadmap
Roadmap • v0.4 Schemas(current) • v0.5 Stream Consumers • v0.6
Columnar Writing • v0.7 CLI • v0.8 Wire Level Tailing • v1.0 Stable => 2019/12 Release!!
Conclusions
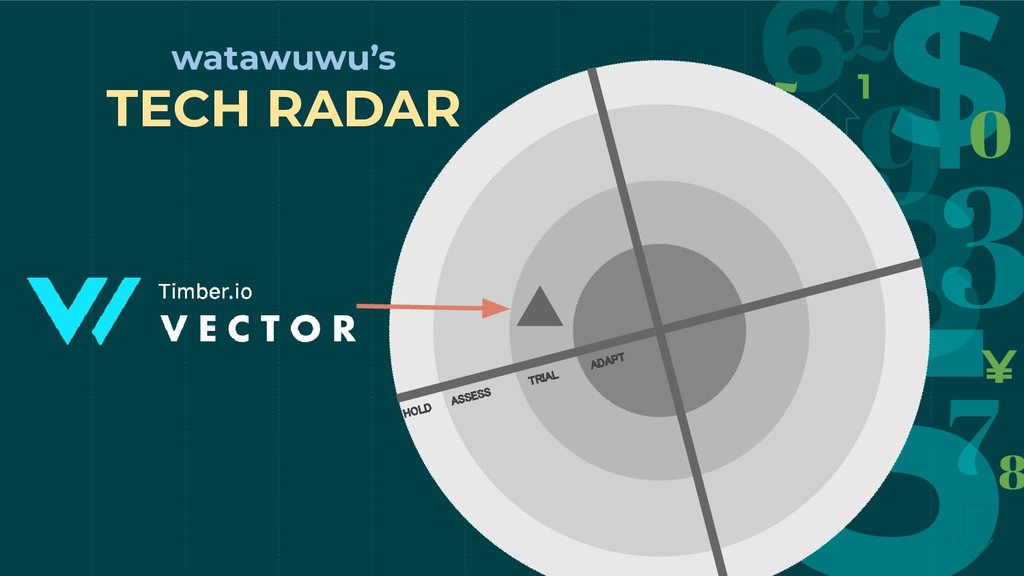
ADAPT TRIAL ASSESS HOLD watawuwu’s TECH RADAR
Thanks! Kubernetes, Cloud Native zlab.co.jp


 watawuwu
 miidas
 oracle4engineer
 recruitengineers
 kairim0
 sansantech
 mikanichinose
 pei0804
 sudoakiy
 dtunkelang
 codatum
 kmiya84377
 mtpooh
 rabernat
 inesmontani
 kevinliebholz
 elsirapls
 lemiorhan
 reverentgeek
 aleyda
 axbom
 lara
 tapps
 62gerente