Upgrade to Pro
— share decks privately, control downloads, hide ads and more …
Speaker Deck
Sign up for free
Menu
Search
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Features
All features
Private URLs
Password Protection
Custom URLS
Scheduled publishing
Remove Branding
Restrict embedding
Deck Collections
Notes
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Explore
Featured decks
Featured speakers
Programming
Technology
Storyboards
Pricing
Search
Sign in
Sign up for free
MixPoet
Search
Sponsored
·
Your Podcast. Everywhere. Effortlessly.
Share. Educate. Inspire. Entertain. You do you. We'll handle the rest.
→
Zhang Yixiao
April 30, 2020
Research
480
4
Share
Embed
Copy iframe code
Copy JS code
Copy link
Start on current slide
MixPoet
Zhang Yixiao
April 30, 2020
More Decks by Zhang Yixiao
See All by Zhang Yixiao
CoCon
ldzhangyx
0
430
vq-cpc
ldzhangyx
0
420
diora
ldzhangyx
0
330
drummernet
ldzhangyx
0
290
ON-LSTM
ldzhangyx
0
250
Other Decks in Research
See All in Research
GLIM とMegaParticles:正規分布近似の限界とタイトカップリング&パーティクルフィルタの進展 / GLIM and MegaParticles : Progress of the distribution representation in SLAM
koide3
0
950
モデル評価を効率的にする方法
ftakahashi
0
210
20260624 NLP colloquium: 単一のhubテキストがCLIPを壊す:hubnessによる埋め込みの脆弱性特定
de9uch1
2
290
PHTalks Bengaluru - SSRF When All Else Fails
dk999
0
1.2k
実例から見るLLMのマンガ理解:実務VQAタスクによる長期的文脈と視覚情報の定性評価
kzmssk
0
190
Physical AIでモデリングはどう変わるか/How Physical AI Will Change Modeling
stktu
0
290
Cross-Media Human-Information Interaction
signer
PRO
0
280
Détecter les vulnérabilités dans un environnement souverain
hellosct1
0
110
Les émissions de méthane entérique en élevage laitier : Enjeux et travaux menés en Afrique de l’Ouest et en France
institutdelelevage
PRO
0
120
JPA2026_NetworkTutorial_JunKashihara
junkashihara
0
230
Fukui Shibiten 39 - AI Art
butchi
0
260
大規模言語モデルは誰を覚えているか / Who Do Large Language Models Memorize?
upura
0
210
Featured
See All Featured
GitHub's CSS Performance
jonrohan
1033
470k
The #1 spot is gone: here's how to win anyway
tamaranovitovic
4
1.2k
Learning to Love Humans: Emotional Interface Design
aarron
275
41k
Site-Speed That Sticks
csswizardry
13
1.6k
実際に使うSQLの書き方 徹底解説 / pgcon21j-tutorial
soudai
PRO
203
77k
Design and Strategy: How to Deal with People Who Don’t "Get" Design
morganepeng
133
20k
SEO in 2025: How to Prepare for the Future of Search
ipullrank
3
3.9k
Ecommerce SEO: The Keys for Success Now & Beyond - #SERPConf2024
aleyda
1
2.2k
Visualizing Your Data: Incorporating Mongo into Loggly Infrastructure
mongodb
50
10k
Design of three-dimensional binary manipulators for pick-and-place task avoiding obstacles (IECON2024)
konakalab
0
610
Templates, Plugins, & Blocks: Oh My! Creating the theme that thinks of everything
marktimemedia
31
2.9k
Art, The Web, and Tiny UX
lynnandtonic
304
22k
Transcript
MixPoet: Diverse Poetry Generation via Learning Controllable Mixed Latent Space
ArXiv: 2003.06094v1 Presenter: Yixiao Zhang
Overview • Idea: 诗人经历、历史背景等 => 诗歌风格多样化 • Methods: • semi-supervised
VAE • disentangling latent space to sub-spaces • each sub-space corresponds to one factor conditioning • adversarial training
Introduction • 近年的研究,主要考虑语义连贯、主题相关 • 存在diversity的困扰 • diversity: • 主题间多样性:给定两个topic words,生成不同的诗歌
• 主题内多样性:给定一个topic word,生成不同的诗歌 • * 现有的模型倾向于记住常见pattern
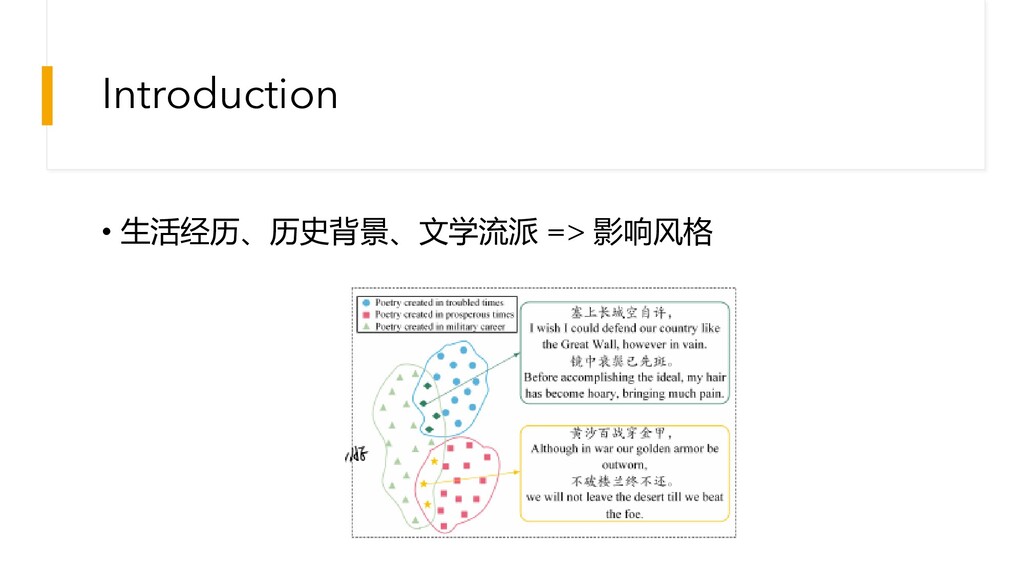
Introduction • 生活经历、历史背景、文学流派 => 影响风格
Introduction • MixPoet: semi-supervised VAE • 将latent space分解为sub-spaces,与影响因子一一对应 • 训练阶段:模型预测无label诗歌的factors
• 测试阶段:指定factor的值,生成风格化的诗歌
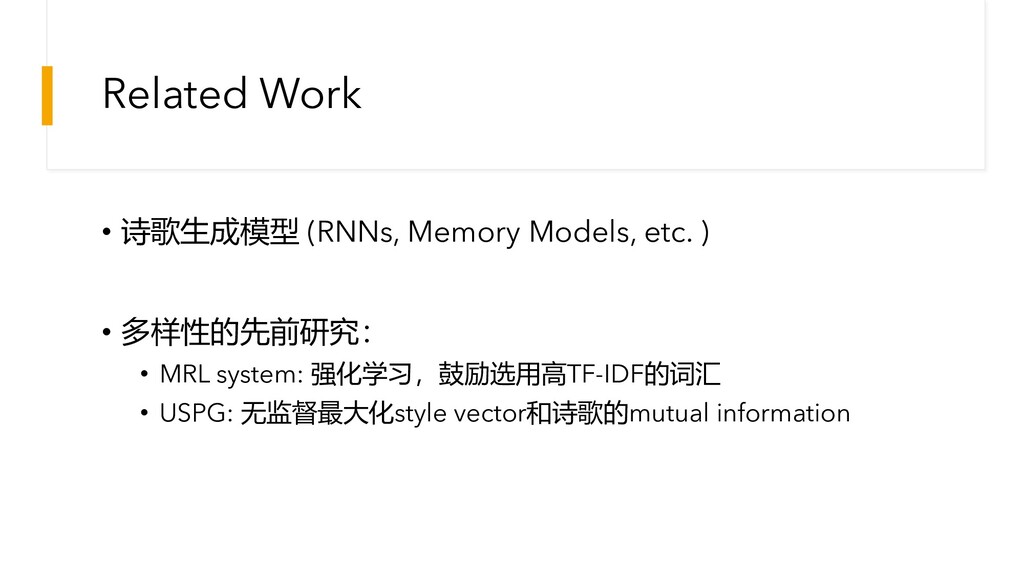
Related Work • 诗歌生成模型 (RNNs, Memory Models, etc. ) •
多样性的先前研究: • MRL system: 强化学习,鼓励选用高TF-IDF的词汇 • USPG: 无监督最大化style vector和诗歌的mutual information
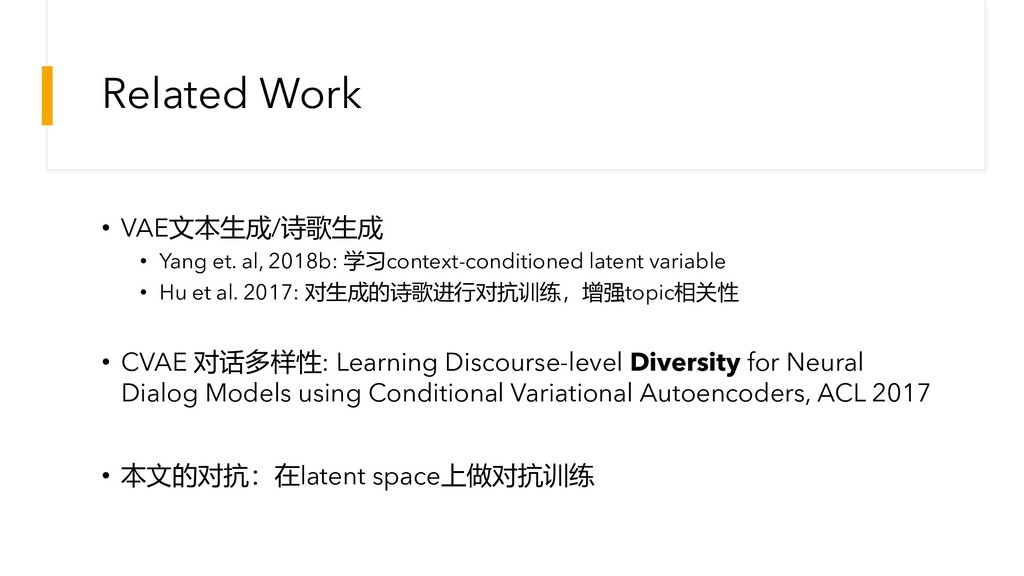
Related Work • VAE文本生成/诗歌生成 • Yang et. al, 2018b: 学习context-conditioned
latent variable • Hu et al. 2017: 对生成的诗歌进行对抗训练,增强topic相关性 • CVAE 对话多样性: Learning Discourse-level Diversity for Neural Dialog Models using Conditional Variational Autoencoders, ACL 2017 • 本文的对抗:在latent space上做对抗训练
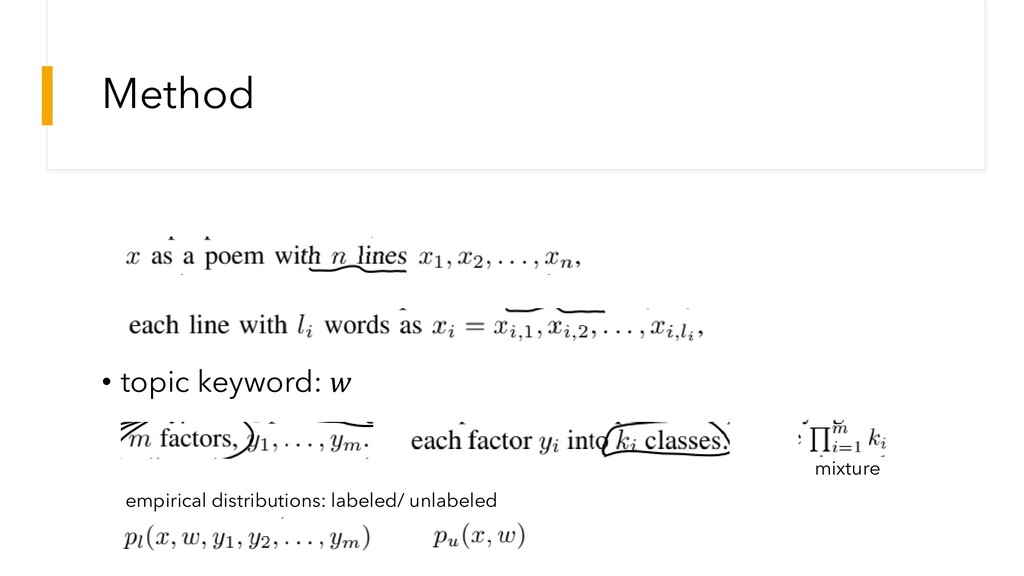
Method • topic keyword: mixture empirical distributions: labeled/ unlabeled
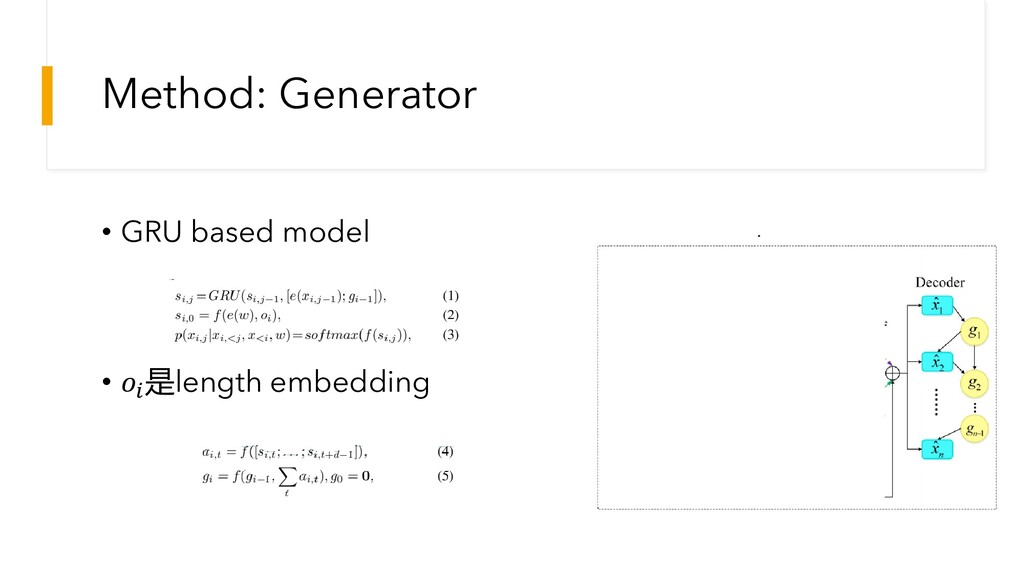
Method: Generator • GRU based model • 是length embedding
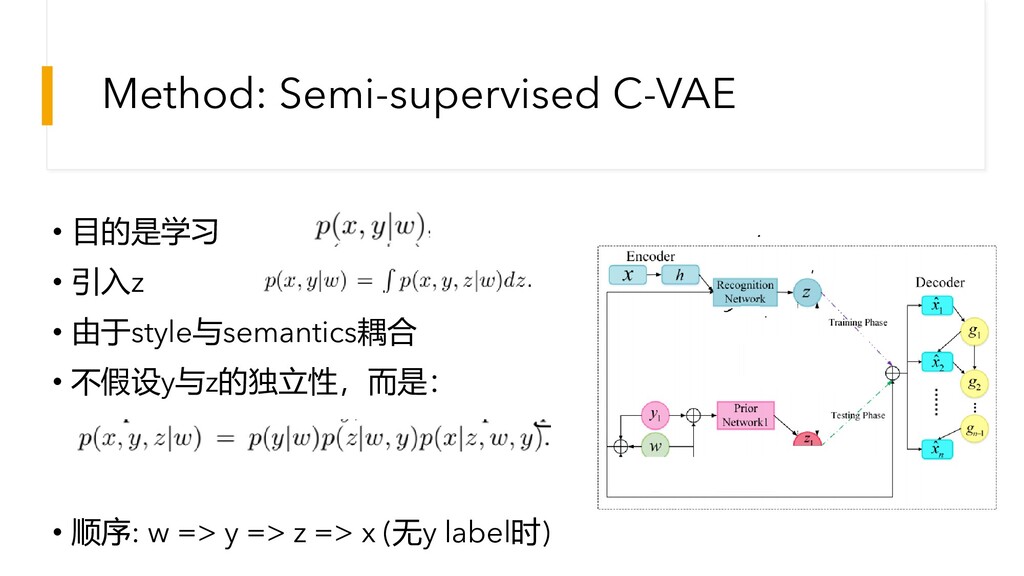
Method: Semi-supervised C-VAE • 目的是学习 • 引入z • 由于style与semantics耦合 •
不假设y与z的独立性,而是: • 顺序: w => y => z => x (无y label时)
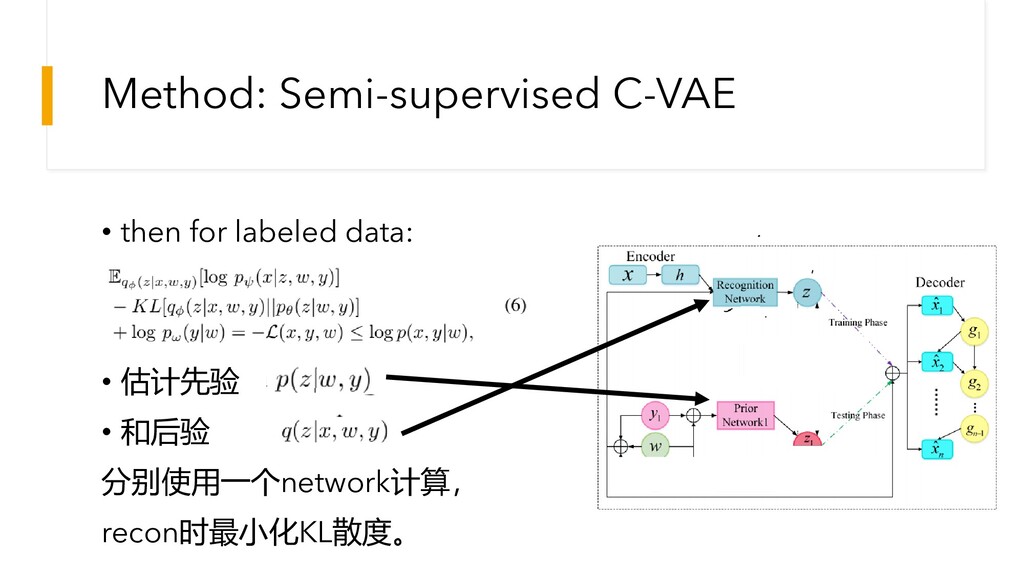
Method: Semi-supervised C-VAE • then for labeled data: • 估计先验
• 和后验 分别使用一个network计算, recon时最小化KL散度。
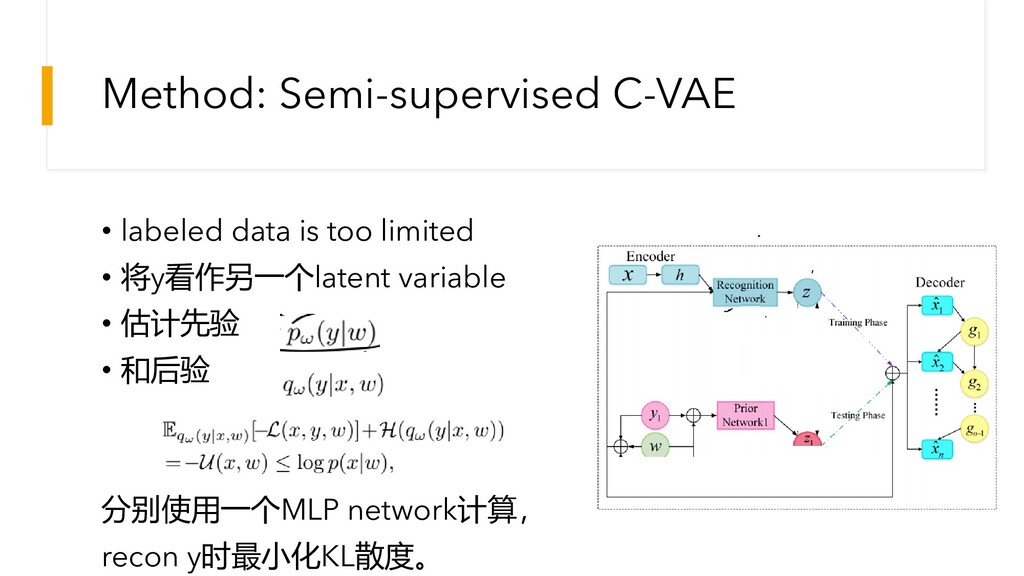
Method: Semi-supervised C-VAE • labeled data is too limited •
将y看作另一个latent variable • 估计先验 • 和后验 分别使用一个MLP network计算, recon y时最小化KL散度。
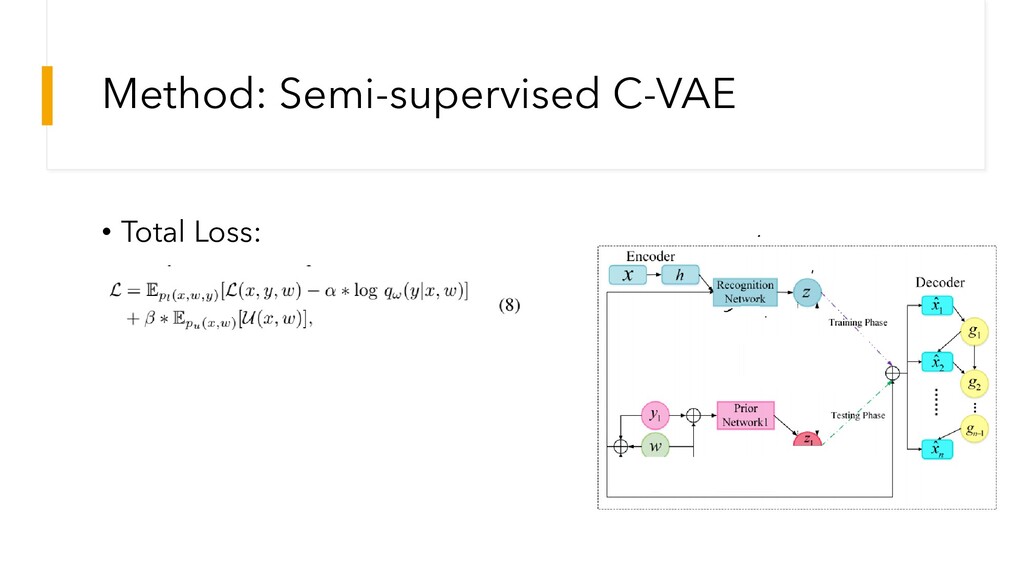
Method: Semi-supervised C-VAE • Total Loss:
Method: Latent Space Mixture • 多个factor时的情形: • 独立性假设:
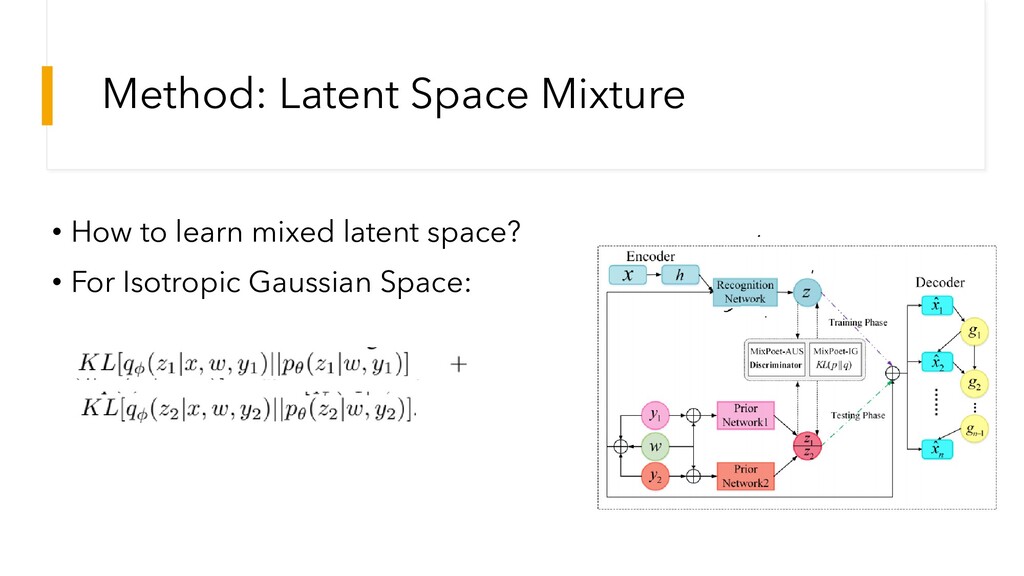
Method: Latent Space Mixture • How to learn mixed latent
space? • For Isotropic Gaussian Space:
Method: Latent Space Mixture • How to learn mixed latent
space? • For Universal Space: 对于condition: ita是噪声,delta是脉冲函数,c是w, y => 从分布中sample出一个值
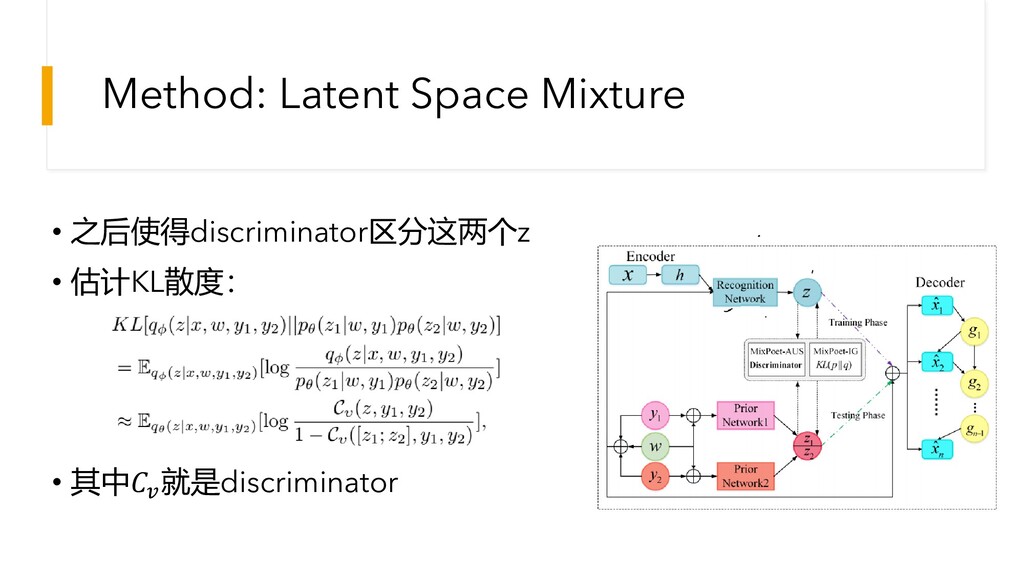
Method: Latent Space Mixture • 之后使得discriminator区分这两个z • 估计KL散度: • 其中
就是discriminator
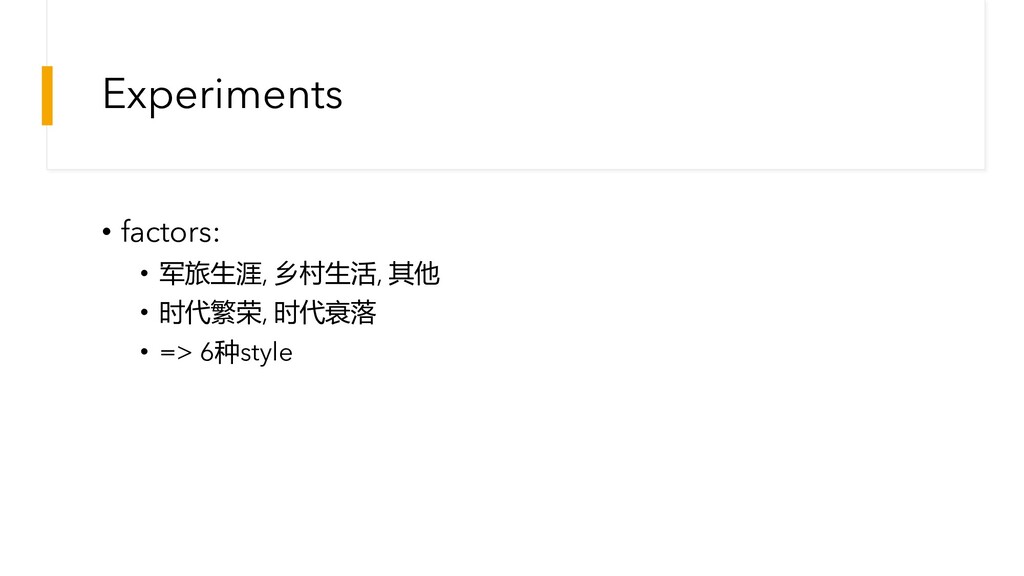
Experiments • factors: • 军旅生涯, 乡村生活, 其他 • 时代繁荣, 时代衰落
• => 6种style
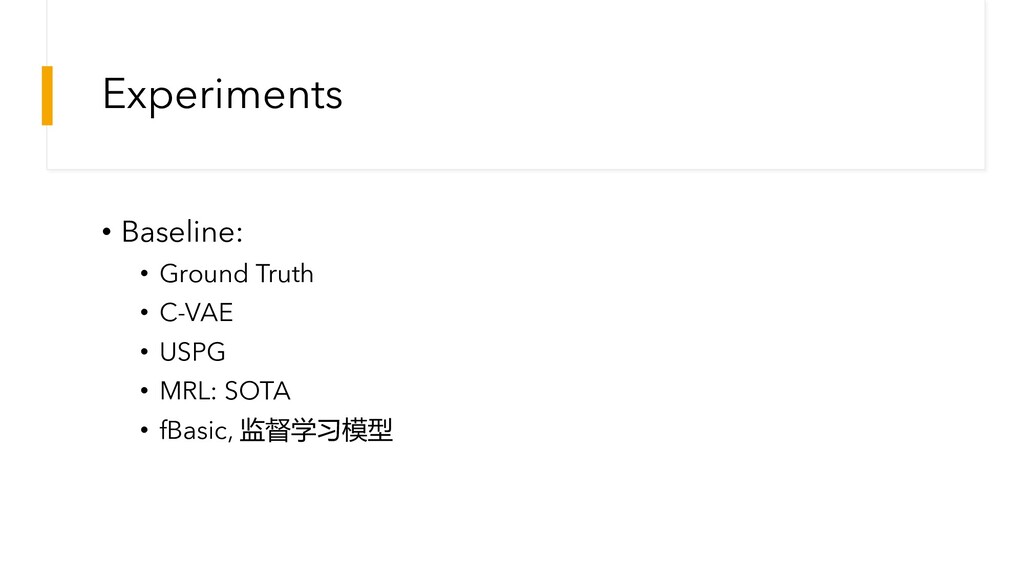
Experiments • Baseline: • Ground Truth • C-VAE • USPG
• MRL: SOTA • fBasic, 监督学习模型
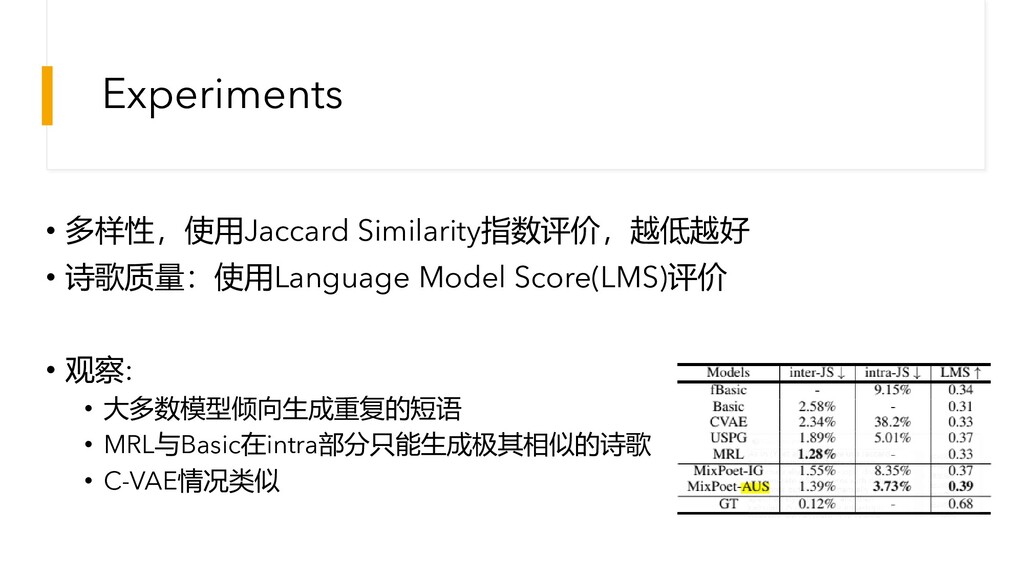
Experiments • 多样性,使用Jaccard Similarity指数评价,越低越好 • 诗歌质量:使用Language Model Score(LMS)评价 • 观察:
• 大多数模型倾向生成重复的短语 • MRL与Basic在intra部分只能生成极其相似的诗歌 • C-VAE情况类似
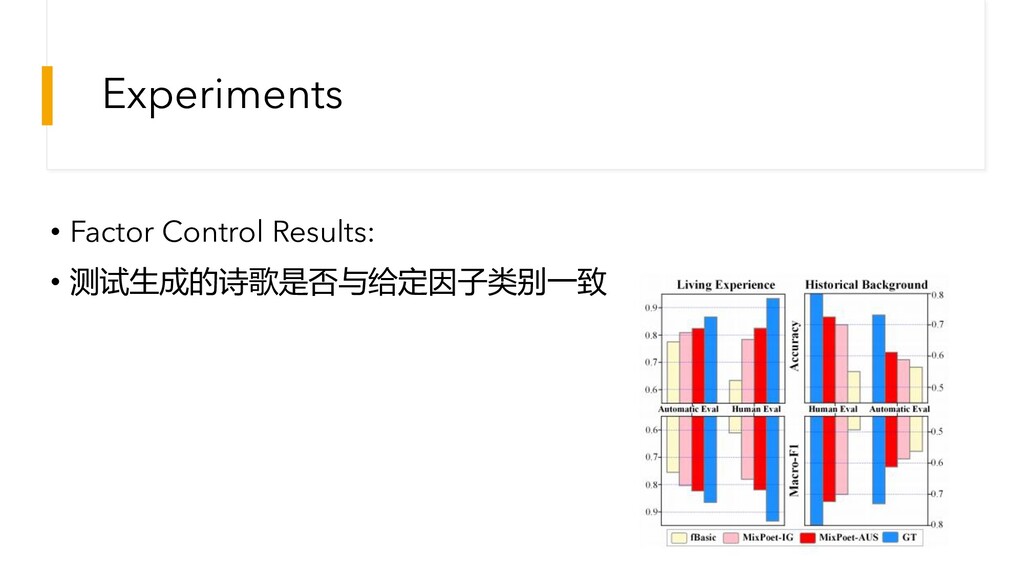
Experiments • Factor Control Results: • 测试生成的诗歌是否与给定因子类别一致
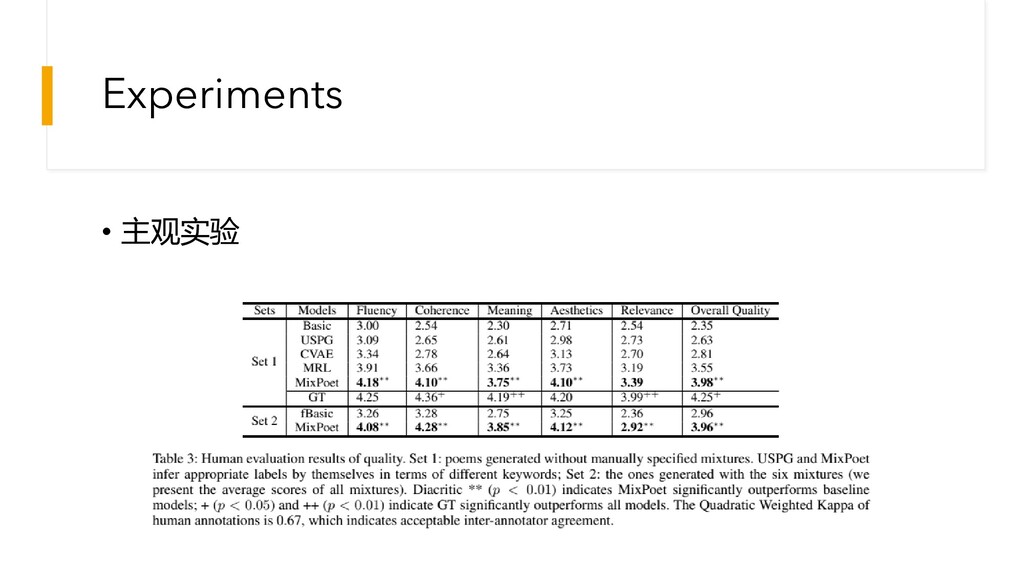
Experiments • 主观实验
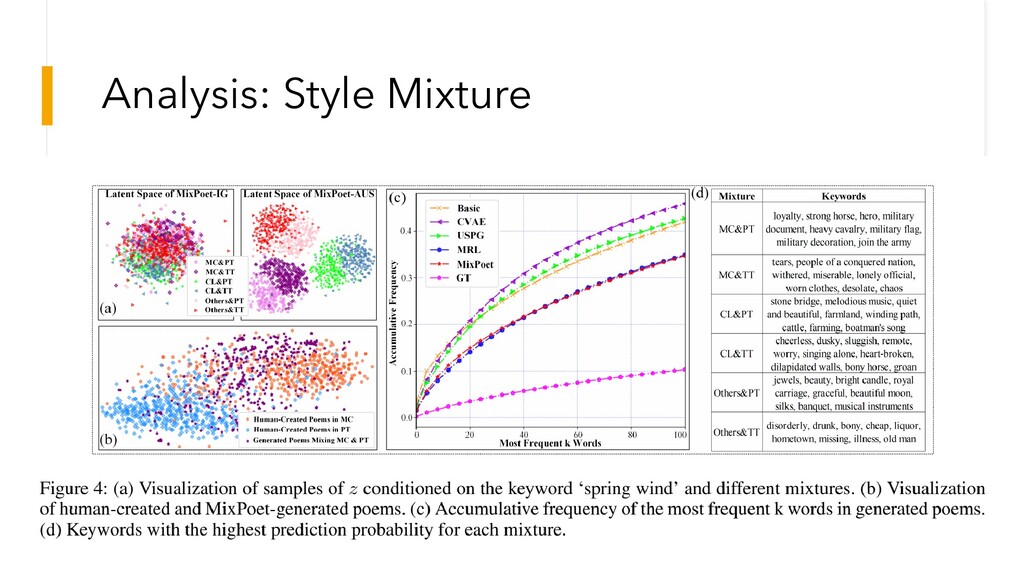
Analysis: Style Mixture
Analysis


 ldzhangyx
 koide3
 ftakahashi
 de9uch1
 dk999
 kzmssk
 stktu
 signer
 hellosct1
 institutdelelevage
 junkashihara
 butchi
 upura
 jonrohan
 tamaranovitovic
 aarron
 csswizardry
 soudai
 morganepeng
 ipullrank
 aleyda
 mongodb
 konakalab
 marktimemedia
 lynnandtonic